Databricks Databricks-Certified-Data-Analyst-Associate Valid Exam Labs: Databricks Certified Data Analyst Associate Exam - Itcertking Easy to Pass

BTW, DOWNLOAD part of Itcertking Databricks-Certified-Data-Analyst-Associate dumps from Cloud Storage: https://drive.google.com/open?id=1qVwPY8xEqny9MfDkuZR4Tzol2Fc17v4H
Some people are not good at operating computers. So you might worry about that the Databricks-Certified-Data-Analyst-Associate certification materials are not suitable for you. Try to believe us. Our experts have taken your worries seriously. They have made it easy to operate for all people. Even if you know little about computers, you can easily begin to do exercises of the Databricks-Certified-Data-Analyst-Associate real exam dumps. Also, we have invited for many volunteers to try our study materials. The results show our products are suitable for them. In addition, the system of our Databricks-Certified-Data-Analyst-Associate test training is powerful. You will never come across system crashes. The system we design has strong compatibility. High speed running completely has no problem at all.
| Topic | Details |
|---|
| Topic 1 | - Data Visualization and Dashboarding: Sub-topics of this topic are about of describing how notifications are sent, how to configure and troubleshoot a basic alert, how to configure a refresh schedule, the pros and cons of sharing dashboards, how query parameters change the output, and how to change the colors of all of the visualizations. It also discusses customized data visualizations, visualization formatting, Query Based Dropdown List, and the method for sharing a dashboard.
|
| Topic 2 | - Databricks SQL: This topic discusses key and side audiences, users, Databricks SQL benefits, complementing a basic Databricks SQL query, schema browser, Databricks SQL dashboards, and the purpose of Databricks SQL endpoints
- warehouses. Furthermore, the delves into Serverless Databricks SQL endpoint
- warehouses, trade-off between cluster size and cost for Databricks SQL endpoints
- warehouses, and Partner Connect. Lastly it discusses small-file upload, connecting Databricks SQL to visualization tools, the medallion architecture, the gold layer, and the benefits of working with streaming data.
|
| Topic 3 | - Data Management: The topic describes Delta Lake as a tool for managing data files, Delta Lake manages table metadata, benefits of Delta Lake within the Lakehouse, tables on Databricks, a table owner’s responsibilities, and the persistence of data. It also identifies management of a table, usage of Data Explorer by a table owner, and organization-specific considerations of PII data. Lastly, the topic it explains how the LOCATION keyword changes, usage of Data Explorer to secure data.
|
| Topic 4 | - SQL in the Lakehouse: It identifies a query that retrieves data from the database, the output of a SELECT query, a benefit of having ANSI SQL, access, and clean silver-level data. It also compares and contrasts MERGE INTO, INSERT TABLE, and COPY INTO. Lastly, this topic focuses on creating and applying UDFs in common scaling scenarios.
|
| Topic 5 | - Analytics applications: It describes key moments of statistical distributions, data enhancement, and the blending of data between two source applications. Moroever, the topic also explains last-mile ETL, a scenario in which data blending would be beneficial, key statistical measures, descriptive statistics, and discrete and continuous statistics.
|
>> Databricks-Certified-Data-Analyst-Associate Valid Exam Labs <<
Databricks Databricks-Certified-Data-Analyst-Associate Valid Exam Labs: Databricks Certified Data Analyst Associate Exam - Itcertking Most Reliable Website
Itcertking is an experienced website with great reputation which offering Databricks dumps torrent and professional explanations. Our Databricks-Certified-Data-Analyst-Associate test questions are created by our IT elites who pay great attention to the IT exam certification so we can ensure you the authority and reliability of our Databricks-Certified-Data-Analyst-Associate Practice Test.
Databricks Certified Data Analyst Associate Exam Sample Questions (Q87-Q92):
NEW QUESTION # 87
In which of the following situations should a data analyst use higher-order functions?
- A. When custom logic needs to be applied to simple, unnested data
- B. When custom logic needs to be applied at scale to array data objects
- C. When built-in functions need to run through the Catalyst Optimizer
- D. When built-in functions are taking too long to perform tasks
- E. When custom logic needs to be converted to Python-native code
Answer: B
Explanation:
Higher-order functions are a simple extension to SQL to manipulate nested data such as arrays. A higher- order function takes an array, implements how the array is processed, and what the result of the computation will be. It delegates to a lambda function how to process each item in the array. This allows you to define functions that manipulate arrays in SQL, without having to unpack and repack them, use UDFs, or rely on limited built-in functions. Higher-order functions provide a performance benefit over user defined functions. References: Higher-order functions | Databricks on AWS, Working with Nested Data Using Higher Order Functions in SQL on Databricks | Databricks Blog, Higher-order functions - Azure Databricks | Microsoft Learn, Optimization recommendations on Databricks | Databricks on AWS
NEW QUESTION # 88
Which of the following SQL keywords can be used to convert a table from a long format to a wide format?
- A. WHERE
- B. SUM
- C. PIVOT
- D. CONVERT
- E. TRANSFORM
Answer: C
Explanation:
Option B is correct. PIVOT rotates unique values from rows into separate columns, which is exactly the process of converting long-format data into wide-format data. UNPIVOT does the reverse. SUM is an aggregate function, WHERE filters rows, and TRANSFORM is not the SQL keyword used for this reshaping task. Official Databricks extract: the PIVOT clause "rotat[es] unique values from a column into separate columns."
NEW QUESTION # 89
Consider the following two statements:
Statement 1:
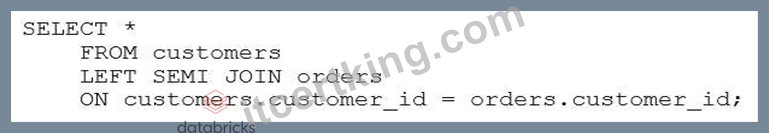
Statement 2:
Which of the following describes how the result sets will differ for each statement when they are run in Databricks SQL?
- A. Both statements will fail because Databricks SQL does not support those join types.
- B. When the first statement is run, only rows from the customers table that have at least one match with the orders table on customer_id will be returned. When the second statement is run, only those rows in the customers table that do not have at least one match with the orders table on customer_id will be returned.
- C. The first statement will return all data from the customers table and matching data from the orders table. The second statement will return all data from the orders table and matching data from the customers table. Any missing data will be filled in with NULL.
- D. There is no difference between the result sets for both statements.
- E. When the first statement is run, all rows from the customers table will be returned and only the customer_id from the orders table will be returned. When the second statement is run, only those rows in the customers table that do not have at least one match with the orders table on customer_id will be returned.
Answer: B
Explanation:
Based on the images you sent, the two statements are SQL queries for different types of joins between the customers and orders tables. A join is a way of combining the rows from two table references based on some criteria. The join type determines how the rows are matched and what kind of result set is returned. The first statement is a query for a LEFT SEMI JOIN, which returns only the rows from the left table reference (customers) that have a match with the right table reference (orders) on the join condition (customer_id). The second statement is a query for a LEFT ANTI JOIN, which returns only the rows from the left table reference (customers) that have no match with the right table reference (orders) on the join condition (customer_id).
Therefore, the result sets for the two statements will differ in the following way:
* The first statement will return a subset of the customers table that contains only the customers who have placed at least one order. The number of rows returned will be less than or equal to the number of rows in the customers table, depending on how many customers have orders. The number of columns returned will be the same as the number of columns in the customers table, as the LEFT SEMI JOIN does not include any columns from the orders table.
* The second statement will return a subset of the customers table that contains only the customers who have not placed any order. The number of rows returned will be less than or equal to the number of rows in the customers table, depending on how many customers have no orders. The number of columns returned will be the same as the number of columns in the customers table, as the LEFT ANTI JOIN does not include any columns from the orders table.
The other options are not correct because:
* A. The first statement will not return all data from the customers table, as it will exclude the customers who have no orders. The second statement will not return all data from the orders table, as it will exclude the orders that have a matching customer. Neither statement will fill in any missing data with NULL, as they do not return any columns from the other table.
* C. There is a difference between the result sets for both statements, as explained above. The LEFT SEMI JOIN and the LEFT ANTI JOIN are not equivalent operations and will produce different outputs.
* D. Both statements will not fail, as Databricks SQL does support those join types. Databricks SQL supports various join types, including INNER, LEFT OUTER, RIGHT OUTER, FULL OUTER, LEFT SEMI, LEFT ANTI, and CROSS. You can also use NATURAL, USING, or LATERAL keywords to specify different join criteria.
* E. The first statement will not return only the customer_id from the orders table, as it will return all columns from the customers table. The second statement is correct, but it is not the only difference between the result sets.
References: JOIN | Databricks on AWS, JOIN - Azure Databricks - Databricks SQL | Microsoft Learn, array_join function | Databricks on AWS, Hints | Databricks on AWS
NEW QUESTION # 90
Which statement about subqueries is correct?
- A. Subqueries can retrieve data without requiring the creation of a table or view.
- B. Subqueries can be used like other built-in functions to transform data into different data types.
- C. Subqueries can be used like other user-defined functions to transform data into different data types.
- D. Subqueries are not available in Databricks SQL
Answer: A
Explanation:
In Databricks SQL, a subquery is a nested query within a larger SQL query that allows for the retrieval of data without the necessity of creating a table or view. This is particularly useful for simplifying complex queries by breaking them down into more manageable parts. Subqueries can be employed in various clauses such as SELECT, FROM, and WHERE to perform operations like filtering, transforming, and aggregating data on- the-fly. This flexibility enhances query efficiency and readability without the overhead of persisting intermediate results as separate tables or views.
Reference: Databricks SQL Query Syntax
NEW QUESTION # 91
A data analysis team is working with the table_bronze SQL table as a source for one of its most complex projects. A stakeholder of the project notices that some of the downstream data is duplicative. The analysis team identifies table_bronze as the source of the duplication.
Which of the following queries can be used to deduplicate the data from table_bronze and write it to a new table table_silver?
A)
CREATE TABLE table_silver AS
SELECT DISTINCT *
FROM table_bronze;
B)
CREATE TABLE table_silver AS
INSERT *
FROM table_bronze;
C)
CREATE TABLE table_silver AS
MERGE DEDUPLICATE *
FROM table_bronze;
D)
INSERT INTO TABLE table_silver
SELECT * FROM table_bronze;
E)
INSERT OVERWRITE TABLE table_silver
SELECT * FROM table_bronze;
- A. Option C
- B. Option E
- C. Option A
- D. Option B
- E. Option D
Answer: C
Explanation:
Option A uses the SELECT DISTINCT statement to remove duplicate rows from the table_bronze and create a new table table_silver with the deduplicated data. This is the correct way to deduplicate data using Spark SQL12. Option B simply inserts all the rows from table_bronze into table_silver, without removing any duplicates. Option C is not a valid syntax for Spark SQL, as there is no MERGE DEDUPLICATE statement. Option D appends all the rows from table_bronze into table_silver, without removing any duplicates. Option E overwrites the existing data in table_silver with the data from table_bronze, without removing any duplicates. Reference: Delete Duplicate using SPARK SQL, Spark SQL - How to Remove Duplicate Rows
NEW QUESTION # 92
......
The study material is available in three easy-to-access formats. The first one is PDF format which is printable and portable. You can access it anywhere with your smart devices like smartphones, tablets, and laptops. In addition, you can even print PDF questions in order to study anywhere and pass Databricks Certified Data Analyst Associate Exam (Databricks-Certified-Data-Analyst-Associate) certification exam.
Databricks-Certified-Data-Analyst-Associate Latest Training: https://www.itcertking.com/Databricks-Certified-Data-Analyst-Associate_exam.html
- Databricks-Certified-Data-Analyst-Associate Standard Answers 🤺 Databricks-Certified-Data-Analyst-Associate Valid Exam Pdf 🦕 Databricks-Certified-Data-Analyst-Associate Latest Test Cram 🗜 ➡ www.testkingpass.com ️⬅️ is best website to obtain ⮆ Databricks-Certified-Data-Analyst-Associate ⮄ for free download 🌰Exam Databricks-Certified-Data-Analyst-Associate Blueprint
- Databricks-Certified-Data-Analyst-Associate Standard Answers 🔟 Databricks-Certified-Data-Analyst-Associate Valid Exam Materials 🐲 Databricks-Certified-Data-Analyst-Associate Trusted Exam Resource 🥌 Easily obtain ⇛ Databricks-Certified-Data-Analyst-Associate ⇚ for free download through ▛ www.pdfvce.com ▟ 🐆Databricks-Certified-Data-Analyst-Associate Valid Exam Pdf
- Databricks-Certified-Data-Analyst-Associate Exam Registration 🤏 Databricks-Certified-Data-Analyst-Associate Valid Study Plan 🧪 Databricks-Certified-Data-Analyst-Associate Reliable Source ➡️ Download ✔ Databricks-Certified-Data-Analyst-Associate ️✔️ for free by simply entering 《 www.pass4test.com 》 website 🍁Databricks-Certified-Data-Analyst-Associate Latest Exam Materials
- Hot Databricks-Certified-Data-Analyst-Associate Valid Exam Labs | Pass-Sure Databricks-Certified-Data-Analyst-Associate Latest Training: Databricks Certified Data Analyst Associate Exam 🌤 Search for 【 Databricks-Certified-Data-Analyst-Associate 】 on ➥ www.pdfvce.com 🡄 immediately to obtain a free download 🐇Valid Databricks-Certified-Data-Analyst-Associate Study Plan
- Test Databricks-Certified-Data-Analyst-Associate Engine 🕌 Valid Databricks-Certified-Data-Analyst-Associate Study Plan 🎎 Databricks-Certified-Data-Analyst-Associate Valid Study Plan 🗯 Open ▷ www.prep4sures.top ◁ and search for { Databricks-Certified-Data-Analyst-Associate } to download exam materials for free ⚪Databricks-Certified-Data-Analyst-Associate Exam Registration
- Databricks-Certified-Data-Analyst-Associate Valid Study Plan 🤥 Unlimited Databricks-Certified-Data-Analyst-Associate Exam Practice 😫 Pass Databricks-Certified-Data-Analyst-Associate Test 🚒 Open ▷ www.pdfvce.com ◁ enter ▛ Databricks-Certified-Data-Analyst-Associate ▟ and obtain a free download 🛫Unlimited Databricks-Certified-Data-Analyst-Associate Exam Practice
- Databricks-Certified-Data-Analyst-Associate Relevant Answers 🔚 Databricks-Certified-Data-Analyst-Associate Exam Registration 🪕 Databricks-Certified-Data-Analyst-Associate Exam Registration 🚋 《 www.troytecdumps.com 》 is best website to obtain ▷ Databricks-Certified-Data-Analyst-Associate ◁ for free download 🗯New Databricks-Certified-Data-Analyst-Associate Braindumps Files
- Databricks Databricks-Certified-Data-Analyst-Associate Valid Exam Labs - Databricks Certified Data Analyst Associate Exam Realistic Latest Training 100% Pass 🛥 Search for ✔ Databricks-Certified-Data-Analyst-Associate ️✔️ and download it for free on ▷ www.pdfvce.com ◁ website ⚛New Databricks-Certified-Data-Analyst-Associate Braindumps Files
- Databricks Databricks-Certified-Data-Analyst-Associate Questions – Reduce Your Chance of Failure [2026] 🤸 Simply search for 【 Databricks-Certified-Data-Analyst-Associate 】 for free download on ✔ www.pass4test.com ️✔️ 🍑Unlimited Databricks-Certified-Data-Analyst-Associate Exam Practice
- 2026 Realistic Databricks-Certified-Data-Analyst-Associate: Databricks Certified Data Analyst Associate Exam Valid Exam Labs 100% Pass Quiz 🆔 Go to website ⏩ www.pdfvce.com ⏪ open and search for ➠ Databricks-Certified-Data-Analyst-Associate 🠰 to download for free 🔳New Databricks-Certified-Data-Analyst-Associate Braindumps Files
- Pass Databricks-Certified-Data-Analyst-Associate Test ✳ Databricks-Certified-Data-Analyst-Associate Valid Exam Camp Pdf 🤰 Databricks-Certified-Data-Analyst-Associate Exam Registration 🖍 Search for ⏩ Databricks-Certified-Data-Analyst-Associate ⏪ and easily obtain a free download on ▷ www.prepawayexam.com ◁ ⚫Exam Databricks-Certified-Data-Analyst-Associate Blueprint
- www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, savee.com, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, mayagriffiths253.blogspot.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
P.S. Free 2026 Databricks Databricks-Certified-Data-Analyst-Associate dumps are available on Google Drive shared by Itcertking: https://drive.google.com/open?id=1qVwPY8xEqny9MfDkuZR4Tzol2Fc17v4H