Fast, Hands-On Databricks-Machine-Learning-Professional Exam-Preparation Questions

What's more, part of that Actualtests4sure Databricks-Machine-Learning-Professional dumps now are free: https://drive.google.com/open?id=1BGVGVu9BAxorBZBI-1gjlFNb1tXo7f1o
For years our team has built a top-ranking brand with mighty and main which bears a high reputation both at home and abroad. The sales volume of the Databricks-Machine-Learning-Professional study materials we sell has far exceeded the same industry and favorable rate about our products is approximate to 100%. Why the clients speak highly of our Databricks-Machine-Learning-Professional Study Materials? Our dedicated service, high quality and passing rate and diversified functions contribute greatly to the high prestige of our products.
Databricks Databricks-Machine-Learning-Professional Exam Overview:
| Certification Vendor: | Databricks |
|---|
| Exam Name: | Databricks Certified Machine Learning Professional |
|---|
| Exam Number: | Databricks-Machine-Learning-Professional |
|---|
| Exam Format: | Multiple choice, Multiple select, Scenario-based questions |
|---|
| Certificate Validity Period: | 2 years |
|---|
| Real Exam Qty: | Approximately 45–60 |
|---|
| Passing Score: | Not publicly disclosed |
|---|
| Related Certifications: | Databricks Certified Machine Learning Associate |
|---|
| Exam Duration: | 120 minutes |
|---|
| Available Languages: | English |
|---|
| Exam Price: | $200 USD |
|---|
| Recommended Training: | Databricks Academy Machine Learning Training |
|---|
| Exam Registration: | Databricks Certification Portal |
|---|
| Sample Questions: | Databricks Databricks-Machine-Learning-Professional Sample Questions |
|---|
| Exam Way: | Online proctored exam (typically delivered via Databricks certification partners such as Certiverse or Pearson VUE depending on region and current program structure) |
|---|
| Pre Condition: | Recommended experience with Databricks platform and machine learning workflows; Databricks Certified Machine Learning Associate certification is often recommended but not strictly required. |
|---|
| Official Syllabus URL: | https://www.databricks.com/learn/certification |
|---|
>> Preparation Databricks-Machine-Learning-Professional Store <<
100% Pass Databricks-Machine-Learning-Professional - Preparation Databricks Certified Machine Learning Professional Store
Once installed Databricks-Machine-Learning-Professional practice exam software onto your computer, you can get started as it does not require an internet connection to run. The Databricks-Machine-Learning-Professional practice exam software is essential for your Databricks Databricks-Machine-Learning-Professional exam preparation as it gives you hands-on experience before the actual Databricks-Machine-Learning-Professional Certification Exam. This kind of exam preparation ensures that a well-prepared and more confident candidate enters the examination arena.
| Topic | Details |
|---|
| Topic 1 | - Identify live serving benefits of querying precomputed batch predictions
- Describe Structured Streaming as a common processing tool for ETL pipelines
|
| Topic 2 | - Create, overwrite, merge, and read Feature Store tables in machine learning workflows
- View Delta table history and load a previous version of a Delta table
|
| Topic 3 | - Describe the advantages of using the pyfunc MLflow flavor
- Manually log parameters, models, and evaluation metrics using MLflow
|
| Topic 4 | - Identify JIT feature values as a need for real-time deployment
- Describe how to list all webhooks and how to delete a webhook
|
| Topic 5 | - Identify the requirements for tracking nested runs
- Describe an MLflow flavor and the benefits of using MLflow flavors
|
| Topic 6 | - Identify which code block will trigger a shown webhook
- Describe the basic purpose and user interactions with Model Registry
|
| Topic 7 | - Describe concept drift and its impact on model efficacy
- Describe summary statistic monitoring as a simple solution for numeric feature drift
|
| Topic 8 | - Identify less performant data storage as a solution for other use cases
- Describe why complex business logic must be handled in streaming deployments
|
| Topic 9 | - Identify a use case for HTTP webhooks and where the Webhook URL needs to come
- Identify advantages of using Job clusters over all-purpose clusters
|
| Topic 10 | - Identify that data can arrive out-of-order with structured streaming
- Identify how model serving uses one all-purpose cluster for a model deployment
|
Databricks Certified Machine Learning Professional Sample Questions (Q182-Q187):
NEW QUESTION # 182
A data scientist has developed a scikit-learn random forest model model, but they have not yet logged model with MLflow. They want to obtain the input schema and the output schema of the model so they can document what type of data is expected as input. Which of the following MLflow operations can be used to perform this task?
- A. mlflow.models.signature.infer_signature
- B. mlflow.models.schema.infer_schema
- C. mlflow.models.Model.get_input_schema
- D. There is no way to obtain the input schema and the output schema of an unlogged model.
- E. mlflow.models.Model.signature
Answer: A
NEW QUESTION # 183
A machine learning engineer is developing a recommendation system for online content. They are using the Databricks Feature Store to store features for training and inference. Which unit test should they create?
- A. Test that Pandas DataFrame operations work as expected
- B. Test Feature Store lookup during inference
- C. Test MLflow Model Registry operations
- D. Test feature transformation functions
Answer: D
Explanation:
When using the Databricks Feature Store, the most important unit tests validate that feature transformation logic produces correct and consistent outputs. Testing feature transformation functions ensures that features written to the Feature Store are accurate and reliable for both training and inference, independent of infrastructure or serving mechanisms.
NEW QUESTION # 184
A Machine Learning Engineer has a real-time fraud detection model deployed that approves or blocks millions of transactions daily. They need to deploy a new version of the model with improved detection accuracy to this high-traffic, business-critical application. Because any model downtime could result in lost revenue or customer dissatisfaction, the engineer must ensure zero downtime and minimal disruption for end users. Leadership also requires that any rollback to the previous version be immediate if issues are detected with the new model in production. Which deployment strategy meets these requirements?
- A. Replace the current production model with the new version during a scheduled maintenance window, notify affected users of potential brief disruptions, and prepare to reroute requests to a backup if failures occur after deployment.
- B. Deploy the new model in parallel with the old version, monitor both for a set period, and then notify all stakeholders to manually switch over to the new version at a coordinated time.
- C. Use a blue-green deployment for the new model, maintaining two separate production environments (one "blue," one "green") and switching user traffic to the new version only after confirming it is healthy, enabling instant rollback if needed.
- D. Use a canary deployment by initially routing a small percentage of user traffic to the new model version, monitoring results, and gradually increasing exposure until all traffic uses the new version if no problems are detected.
Answer: C
Explanation:
A blue-green deployment maintains two fully operational production environments and shifts traffic between them instantly. This approach provides zero downtime during deployment and allows immediate rollback to the previous model version if issues arise, which is critical for high- traffic, business-critical real-time systems.
NEW QUESTION # 185
A Machine Learning Engineer has trained a credit scoring model and needs to evaluate fairness metrics across different customer segments while maintaining different levels of granularity for business reporting. They need to compute metrics like precision, recall, and demographic parity at the individual feature level (credit_score_range, income_bracket) as well as intersectional slices (combinations of features). The model outputs are stored in a Delta table with prediction probabilities and actual default labels. The engineer wants to systematically evaluate model performance across these various feature slices and granularities. Which approach will do this?
- A. Create Lakehouse Monitoring with slicing expressions for individual features and intersection conditions.
- B. Use Unity Catalog metric views with dimensions defined for each feature and measures for the fairness metrics.
- C. Implement custom MLflow evaluation functions that iterate through all possible feature combinations.
- D. Build separate Spark DataFrames for each slice and compute metrics using standard DataFrame operations.
Answer: A
Explanation:
Lakehouse Monitoring supports defining slicing expressions on one or more columns, allowing metrics such as precision, recall, and fairness indicators to be computed at both individual feature levels and intersectional combinations. This provides a systematic, scalable, and governed way to evaluate model performance and fairness across multiple granularities directly from Delta tables without custom metric pipelines.
NEW QUESTION # 186
A data scientist would like to switch from manually using MLflow logging to MLflow Autologging for all machine learning libraries used in a notebook.
They begin by adding mlflow.autolog()to the top of the below code block:
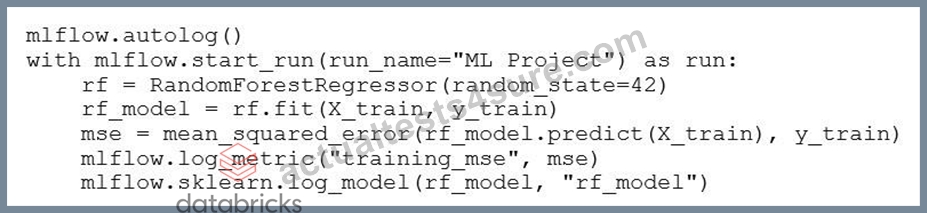
The data scientist is now trying to determine which line of code will kick off the MLflow Autologging process.
Which line of code within the above code block will start the MLflow Autologging process?
- A. with mlflow.start_run(run_name="ML Project") as run:
- B. mlflow.log_metric("training_mse", mse)
- C. rf_model = rf.fit(X_train, y_train)
- D. mlflow.sklearn.log_model(rf_model, "rf_model")
Answer: C
Explanation:
The MLflow Autologging process is triggered when a model's training function is called. In this case, rf.fit(X_train, y_train) starts the autologging process because mlflow.autolog() automatically tracks parameters, metrics, and the model when a supported estimator (like RandomForestRegressor) is fitted. The context manager mlflow.start_run() only initiates an MLflow run, but the actual autologging begins during the .fit() execution.
NEW QUESTION # 187
......
Databricks-Machine-Learning-Professional Latest Version: https://www.actualtests4sure.com/Databricks-Machine-Learning-Professional-test-questions.html
- Prep Databricks-Machine-Learning-Professional Guide 🔳 New Databricks-Machine-Learning-Professional Exam Price 🕶 Exam Databricks-Machine-Learning-Professional Online 🏩 Search for ⇛ Databricks-Machine-Learning-Professional ⇚ and download exam materials for free through ⏩ www.dumpsmaterials.com ⏪ 👙Databricks-Machine-Learning-Professional New Braindumps Pdf
- Free PDF Databricks Databricks-Machine-Learning-Professional - Preparation Databricks Certified Machine Learning Professional Store ⚡ Open website 《 www.pdfvce.com 》 and search for “ Databricks-Machine-Learning-Professional ” for free download 🌺Databricks-Machine-Learning-Professional Exam Lab Questions
- Free PDF Databricks Databricks-Machine-Learning-Professional - Preparation Databricks Certified Machine Learning Professional Store 📐 Immediately open ➤ www.troytecdumps.com ⮘ and search for { Databricks-Machine-Learning-Professional } to obtain a free download 👲Databricks-Machine-Learning-Professional Latest Exam Online
- Databricks-Machine-Learning-Professional Valid Exam Cost ⏮ Databricks-Machine-Learning-Professional Certificate Exam 📸 New Databricks-Machine-Learning-Professional Test Sample 🦉 Download ➤ Databricks-Machine-Learning-Professional ⮘ for free by simply searching on ✔ www.pdfvce.com ️✔️ 🗾Databricks-Machine-Learning-Professional Latest Test Practice
- Databricks-Machine-Learning-Professional Valid Exam Cost 🧍 Databricks-Machine-Learning-Professional Valid Exam Cost ⛰ Databricks-Machine-Learning-Professional Valid Exam Cost 🎧 Open [ www.prep4away.com ] enter 「 Databricks-Machine-Learning-Professional 」 and obtain a free download ❓Valid Exam Databricks-Machine-Learning-Professional Practice
- Databricks-Machine-Learning-Professional Latest Test Practice 😠 Training Databricks-Machine-Learning-Professional Tools 🚪 Databricks-Machine-Learning-Professional Reliable Dumps 🕌 The page for free download of 《 Databricks-Machine-Learning-Professional 》 on ( www.pdfvce.com ) will open immediately ⏳Databricks-Machine-Learning-Professional New Braindumps Pdf
- Databricks-Machine-Learning-Professional Test Dumps Demo 🐣 Databricks-Machine-Learning-Professional Reliable Dumps ↩ Databricks-Machine-Learning-Professional Reliable Dumps 🏎 Simply search for ➤ Databricks-Machine-Learning-Professional ⮘ for free download on 《 www.testkingpass.com 》 🍱Databricks-Machine-Learning-Professional Valid Exam Cost
- Databricks-Machine-Learning-Professional Latest Exam Notes 🤝 Databricks-Machine-Learning-Professional Certificate Exam 🧫 Prep Databricks-Machine-Learning-Professional Guide 🕚 Search for ▷ Databricks-Machine-Learning-Professional ◁ and download it for free on 「 www.pdfvce.com 」 website 🚟Databricks-Machine-Learning-Professional Reliable Dumps
- Databricks-Machine-Learning-Professional Exam Topics Pdf 🕗 Databricks-Machine-Learning-Professional Certification Sample Questions 🥚 New Databricks-Machine-Learning-Professional Test Sample 😫 Open ➥ www.vce4dumps.com 🡄 and search for ➠ Databricks-Machine-Learning-Professional 🠰 to download exam materials for free ☃Databricks-Machine-Learning-Professional Reliable Dumps
- Databricks-Machine-Learning-Professional Latest Exam Online 📳 New Databricks-Machine-Learning-Professional Exam Bootcamp 🟠 Databricks-Machine-Learning-Professional Valid Exam Cost 🧝 The page for free download of ➡ Databricks-Machine-Learning-Professional ️⬅️ on ▷ www.pdfvce.com ◁ will open immediately 🕵Databricks-Machine-Learning-Professional Latest Test Practice
- New Databricks-Machine-Learning-Professional Exam Bootcamp 🦱 Training Databricks-Machine-Learning-Professional Tools 🟧 Databricks-Machine-Learning-Professional Exam Topics Pdf ⚾ Download ✔ Databricks-Machine-Learning-Professional ️✔️ for free by simply searching on ▷ www.prep4sures.top ◁ 💥Training Databricks-Machine-Learning-Professional Tools
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
2026 Latest Actualtests4sure Databricks-Machine-Learning-Professional PDF Dumps and Databricks-Machine-Learning-Professional Exam Engine Free Share: https://drive.google.com/open?id=1BGVGVu9BAxorBZBI-1gjlFNb1tXo7f1o