DOWNLOAD the newest RealVCE Databricks-Certified-Professional-Data-Engineer PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1_HQVvL4slbwcI5FDwgMaBajYmwby46iE
May be you will meet some difficult or problems when you prepare for your Databricks-Certified-Professional-Data-Engineer exam, you even want to give it up. That is why I suggest that you must try our study materials. Because Databricks-Certified-Professional-Data-Engineer guide torrent can help you to solve all the problems encountered in the learning process, Databricks-Certified-Professional-Data-Engineer study tool will provide you with very flexible learning time so that you can easily pass the exam. Even if you fail to pass the exam, as long as you are willing to continue to use our Databricks-Certified-Professional-Data-Engineer Study Tool, we will still provide you with the benefits of free updates within a year.
| Section | Objectives |
|---|---|
| Topic 1: Production Pipelines and Orchestration | - Pipeline reliability and fault tolerance - Automate ETL pipelines and scheduling - Build and manage workflows using Databricks Jobs |
| Topic 2: Security, Governance, Monitoring, and Optimization | - Monitor and optimize Spark workloads - Cost optimization and performance tuning - Implement Unity Catalog governance and access control |
| Topic 3: Data Modeling and Storage | - Delta Lake table design and optimization - Schema evolution and data partitioning strategies - Design scalable data lakehouse architectures |
| Topic 4: Data Ingestion and Transformation | - Ingest data using Apache Spark and Databricks - Transform and clean datasets using Spark SQL and DataFrame APIs - Handle batch and streaming data pipelines |
>> New Databricks-Certified-Professional-Data-Engineer Test Format <<
We have special online worker to solve all your problems. Once you have questions about our Databricks-Certified-Professional-Data-Engineer latest exam guide, you can directly contact with them through email. We are 7*24*365 online service. We are welcome you to contact us any time via email or online service. We have issued numerous products, so you might feel confused about which Databricks-Certified-Professional-Data-Engineer Study Dumps suit you best. You will get satisfied answers after consultation.
NEW QUESTION # 45
A member of the data engineering team has submitted a short notebook that they wish to schedule as part of a larger data pipeline. Assume that the commands provided below produce the logically correct results when run as presented.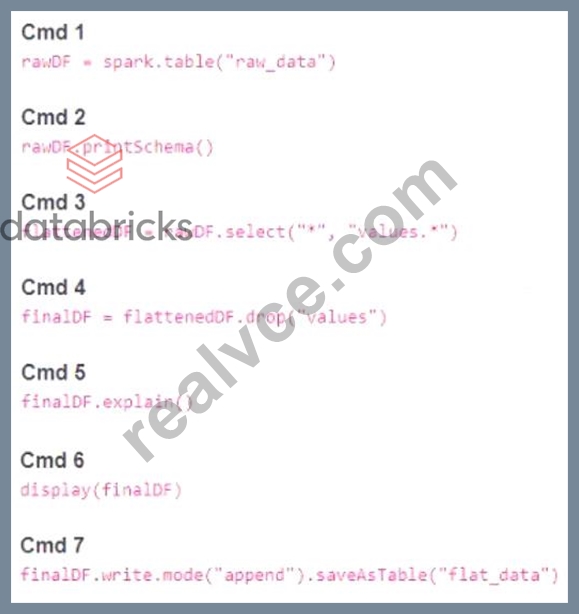
Which command should be removed from the notebook before scheduling it as a job?
Answer: D
Explanation:
Cmd 6 is the command that should be removed from the notebook before scheduling it as a job. This command is selecting all the columns from the finalDF dataframe and displaying them in the notebook. This is not necessary for the job, as the finalDF dataframe is already written to a table in Cmd 7. Displaying the dataframe in the notebook will only consume resources and time, and it will not affect the output of the job.
Therefore, Cmd 6 is redundant and should be removed.
The other commands are essential for the job, as they perform the following tasks:
* Cmd 1: Reads the raw_data table into a Spark dataframe called rawDF.
* Cmd 2: Prints the schema of the rawDF dataframe, which is useful for debugging and understanding the data structure.
* Cmd 3: Selects all the columns from the rawDF dataframe, as well as the nested columns from the values struct column, and creates a new dataframe called flattenedDF.
* Cmd 4: Drops the values column from the flattenedDF dataframe, as it is no longer needed after flattening, and creates a new dataframe called finalDF.
* Cmd 5: Explains the physical plan of the finalDF dataframe, which is useful for optimizing and tuning the performance of the job.
* Cmd 7: Writes the finalDF dataframe to a table called flat_data, using the append mode to add new data to the existing table.
NEW QUESTION # 46
A data engineer has three notebooks in an ELT pipeline. The notebooks need to be executed in a specific order
for the pipeline to complete successfully. The data engineer would like to use Delta Live Tables to manage this
process.
Which of the following steps must the data engineer take as part of implementing this pipeline using Delta
Live Tables?
Answer: A
NEW QUESTION # 47
Which of the following is true of Delta Lake and the Lakehouse?
Answer: C
Explanation:
https://docs.delta.io/2.0.0/table-properties.html
Delta Lake automatically collects statistics on the first 32 columns of each table, which are leveraged in data skipping based on query filters 1 . Data skipping is a performance optimization technique that aims to avoid reading irrelevant data from the storage layer 1 . By collecting statistics such as min/max values, null counts, and bloom filters, Delta Lake can efficiently prune unnecessary files or partitions from the query plan 1 . This can significantly improve the query performance and reduce the I/O cost.
The other options are false because:
* Parquet compresses data column by column, not row by row 2 . This allows for better compression ratios, especially for repeated or similar values within a column 2 .
* Views in the Lakehouse do not maintain a valid cache of the most recent versions of source tables at all times 3 . Views are logical constructs that are defined by a SQL query on one or more base tables 3
. Views are not materialized by default, which means they do not store any data, but only the query definition 3 . Therefore, views always reflect the latest state of the source tables when queried 3 .
However, views can be cached manually using the CACHE TABLE or CREATE TABLE AS SELECT commands.
* Primary and foreign key constraints can not be leveraged to ensure duplicate values are never entered into a dimension table. Delta Lake does not support enforcing primary and foreign key constraints on tables. Constraints are logical rules that define the integrity and validity of the data in a table. Delta Lake relies on the application logic or the user to ensure the data quality and consistency.
* Z-order can be applied to any values stored in Delta Lake tables, not only numeric values. Z-order is a technique to optimize the layout of the data files by sorting them on one or more columns. Z-order can improve the query performance by clustering related values together and enabling more efficient data skipping. Z-order can be applied to any column that has a defined ordering, such as numeric, string, date, or boolean values.
References: Data Skipping , Parquet Format , Views , [Caching], [Constraints] , [Z-Ordering]
NEW QUESTION # 48
The security team is exploring whether or not the Databricks secrets module can be leveraged for connecting to an external database.
After testing the code with all Python variables being defined with strings, they upload the password to the secrets module and configure the correct permissions for the currently active user. They then modify their code to the following (leaving all other variables unchanged).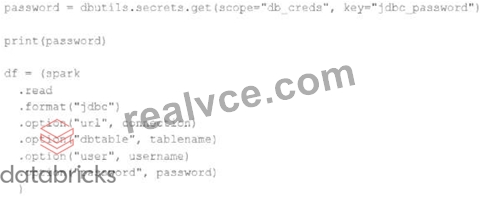
Which statement describes what will happen when the above code is executed?
Answer: A
Explanation:
This is the correct answer because the code is using the dbutils.secrets.get method to retrieve the password from the secrets module and store it in a variable. The secrets module allows users to securely store and access sensitive information such as passwords, tokens, or API keys. The connection to the external table will succeed because the password variable will contain the actual password value. However, when printing the password variable, the string "redacted" will be displayed instead of the plain text password, as a security measure to prevent exposing sensitive information in notebooks. Verified References: [Databricks Certified Data Engineer Professional], under "Security & Governance" section; Databricks Documentation, under
"Secrets" section.
NEW QUESTION # 49
Which of the following are stored in the control pane of Databricks Architecture?
Answer: C
Explanation:
Explanation
The answer is Databricks Web Application
Azure Databricks architecture overview - Azure Databricks | Microsoft Docs Databricks operates most of its services out of a control plane and a data plane, please note serverless features like SQL Endpoint and DLT compute use shared compute in Control pane.
Control Plane: Stored in Databricks Cloud Account
* The control plane includes the backend services that Databricks manages in its own Azure account.
Notebook commands and many other workspace configurations are stored in the control plane and encrypted at rest.
Data Plane: Stored in Customer Cloud Account
* The data plane is managed by your Azure account and is where your data resides. This is also where data is processed. You can use Azure Databricks connectors so that your clusters can connect to external data sources outside of your Azure account to ingest data or for storage.
Timeline Description automatically generated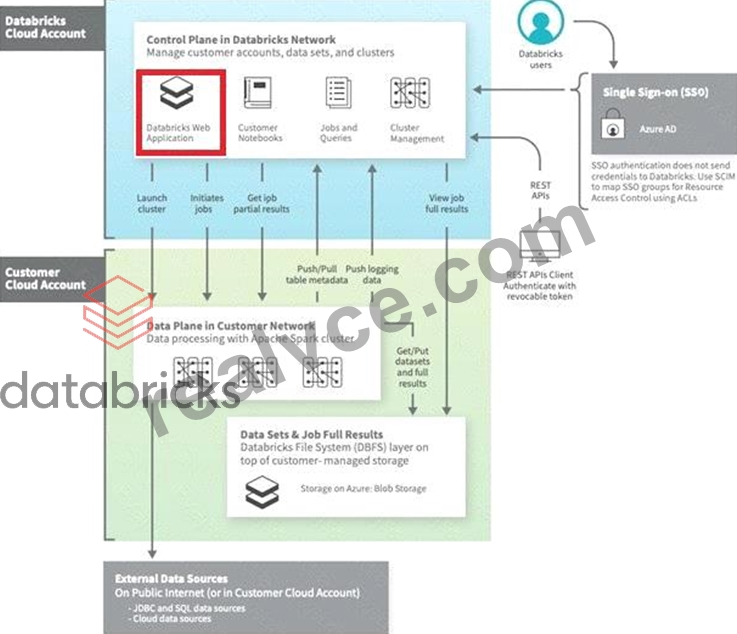
Bottom of Form
Top of Form
NEW QUESTION # 50
......
Our Databricks-Certified-Professional-Data-Engineer exam dumps are compiled by our veteran professionals who have been doing research in this field for years. There is no question to doubt that no body can know better than them. The content and displays of the Databricks-Certified-Professional-Data-Engineer pass guide Which they have tailor-designed are absolutely more superior than the other providers'. Besides, they update our Databricks-Certified-Professional-Data-Engineer Real Exam every day to make sure that our customer can receive the latest Databricks-Certified-Professional-Data-Engineer preparation brain dumps.
Test Databricks-Certified-Professional-Data-Engineer Online: https://www.realvce.com/Databricks-Certified-Professional-Data-Engineer_free-dumps.html
DOWNLOAD the newest RealVCE Databricks-Certified-Professional-Data-Engineer PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1_HQVvL4slbwcI5FDwgMaBajYmwby46iE