Many candidates find the Databricks Databricks-Certified-Professional-Data-Engineer exam preparation difficult. They often buy expensive study courses to start their Databricks Databricks-Certified-Professional-Data-Engineer certification exam preparation. However, spending a huge amount on such resources is difficult for many Databricks Certified Professional Data Engineer Exam exam applicants. The latest Databricks Databricks-Certified-Professional-Data-Engineer Exam Dumps are the right option for you to prepare for the Databricks Databricks-Certified-Professional-Data-Engineer certification test at home.
The Databricks Databricks-Certified-Professional-Data-Engineer Exam is intended for data engineers with experience in designing and implementing data solutions using Databricks. Candidates for this certification should have a good understanding of data engineering concepts, data processing frameworks, and programming languages such as Python and SQL. They should also be familiar with cloud platforms such as AWS, Azure, and Google Cloud Platform.
Passing the Databricks Certified Professional Data Engineer exam is a valuable achievement for data professionals who work with the Databricks platform. Databricks Certified Professional Data Engineer Exam certification demonstrates that candidates have the skills and knowledge needed to perform data engineering tasks effectively using Databricks. It also provides a competitive advantage in the job market, as employers are increasingly looking for candidates with data engineering certifications.
>> Valid Databricks-Certified-Professional-Data-Engineer Test Blueprint <<
Whatever may be the reason to leave your job, if you have made up your mind, there is no going back. By getting the Databricks Databricks-Certified-Professional-Data-Engineer Certification, you can avoid thinking about negative things, instead, you can focus on the positive and bright side of taking this step and find a new skill set to improve your chances of getting your dream job.
To take the Databricks Certified Professional Data Engineer certification exam, candidates must have a strong background in data engineering and experience working with Databricks. Databricks-Certified-Professional-Data-Engineer exam consists of multiple-choice questions and hands-on tasks that require candidates to demonstrate their ability to design, build, and manage data processing systems using Databricks. Databricks-Certified-Professional-Data-Engineer Exam covers a wide range of topics, including data ingestion, data transformation, data storage, data processing, and data visualization. Upon successful completion of the exam, candidates will receive a Databricks Certified Professional Data Engineer certification, which demonstrates their expertise in using Databricks to build and maintain data processing systems.
NEW QUESTION # 202
A table named user_ltv is being used to create a view that will be used by data analysis on various teams. Users in the workspace are configured into groups, which are used for setting up data access using ACLs.
The user_ltv table has the following schema: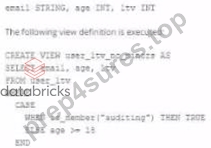
An analyze who is not a member of the auditing group executing the following query: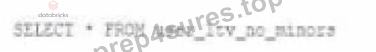
Which result will be returned by this query?
Answer: B
Explanation:
Given the CASE statement in the view definition, the result set for a user not in the auditing group would be constrained by the ELSE condition, which filters out records based on age. Therefore, the view will return all columns normally for records with an age greater than 18, as users who are not in the auditing group will not satisfy the is_member('auditing') condition. Records not meeting the age > 18 condition will not be displayed.
NEW QUESTION # 203
The business reporting team requires that data for their dashboards be updated every hour. The total processing time for the pipeline that extracts, transforms, and loads the data for their pipeline runs in 10 minutes. Assuming normal operating conditions, which configuration will meet their service-level agreement requirements with the lowest cost?
Answer: A
Explanation:
Comprehensive and Detailed Explanation From Exact Extract:
* Exact extract: "Job clusters are created for a job run and terminate when the job completes." References: Cluster types (job vs all-purpose); Databricks Jobs scheduling.
NEW QUESTION # 204
The data governance team is reviewing user for deleting records for compliance with GDPR. The following logic has been implemented to propagate deleted requests from the user_lookup table to the user aggregate table.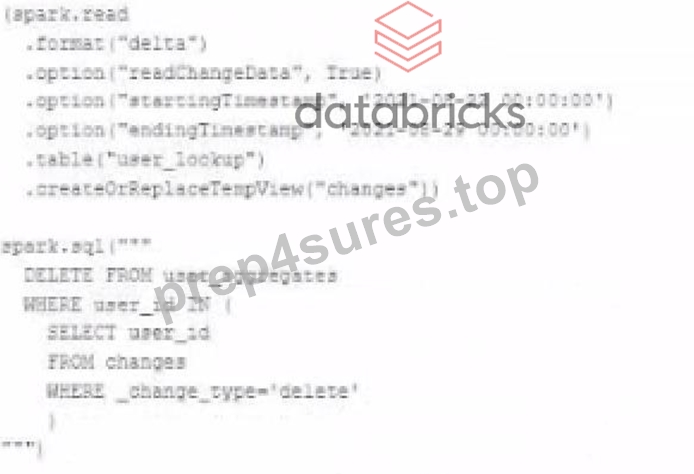
Assuming that user_id is a unique identifying key and that all users have requested deletion have been removed from the user_lookup table, which statement describes whether successfully executing the above logic guarantees that the records to be deleted from the user_aggregates table are no longer accessible and why?
Answer: C
Explanation:
The DELETE operation in Delta Lake is ACID compliant, which means that once the operation is successful, the records are logically removed from the table. However, the underlying files that contained these records may still exist and be accessible via time travel to older versions of the table. To ensure that these records are physically removed and compliance with GDPR is maintained, a VACUUM command should be used to clean up these data files after a certain retention period. The VACUUM command will remove the files from the storage layer, and after this, the records will no longer be accessible.
NEW QUESTION # 205
A junior data engineer seeks to leverage Delta Lake's Change Data Feed functionality to create a Type 1 table representing all of the values that have ever been valid for all rows in a bronze table created with the property delta.enableChangeDataFeed = true. They plan to execute the following code as a daily job:
Which statement describes the execution and results of running the above query multiple times?
Answer: A
Explanation:
Reading table's changes, captured by CDF, using spark.read means that you are reading them as a static source. So, each time you run the query, all table's changes (starting from the specified startingVersion) will be read.
NEW QUESTION # 206
Which of the following scenarios is the best fit for AUTO LOADER?
Answer: E
Explanation:
Explanation
The answer is, Efficiently process new data incrementally from cloud object storage, AU-TO LOADER only supports ingesting files stored in a cloud object storage. Auto Loader cannot process streaming data sources like Kafka or Delta streams, use Structured streaming for these data sources.
Diagram Description automatically generated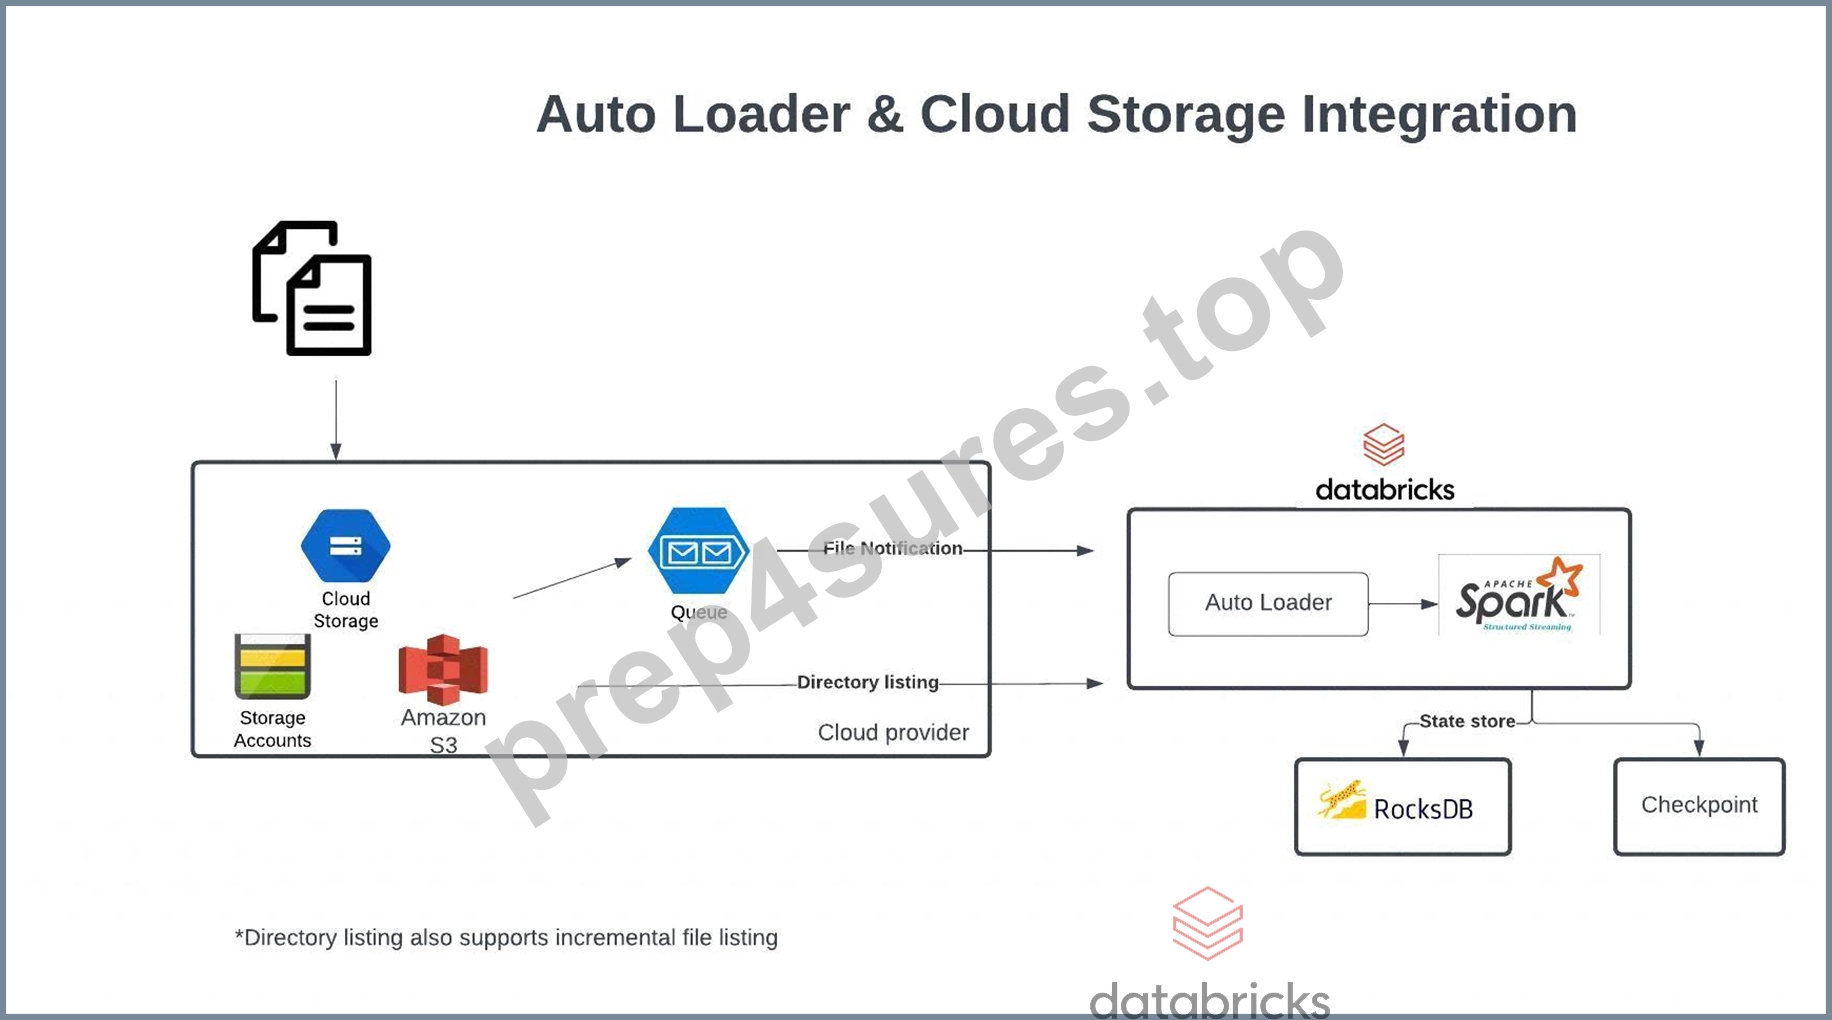
Auto Loader and Cloud Storage Integration
Auto Loader supports a couple of ways to ingest data incrementally
1.Directory listing - List Directory and maintain the state in RocksDB, supports incremental file listing
2.File notification - Uses a trigger+queue to store the file notification which can be later used to retrieve the file, unlike Directory listing File notification can scale up to millions of files per day.
[OPTIONAL]
Auto Loader vs COPY INTO?
Auto Loader
Auto Loader incrementally and efficiently processes new data files as they arrive in cloud storage without any additional setup. Auto Loader provides a new Structured Streaming source called cloudFiles. Given an input directory path on the cloud file storage, the cloudFiles source automatically processes new files as they arrive, with the option of also processing existing files in that directory.
When to use Auto Loader instead of the COPY INTO?
*You want to load data from a file location that contains files in the order of millions or higher. Auto Loader can discover files more efficiently than the COPY INTO SQL command and can split file processing into multiple batches.
*You do not plan to load subsets of previously uploaded files. With Auto Loader, it can be more difficult to reprocess subsets of files. However, you can use the COPY INTO SQL command to reload subsets of files while an Auto Loader stream is simultaneously running.
NEW QUESTION # 207
......
Databricks-Certified-Professional-Data-Engineer Test Questions Vce: https://www.prep4sures.top/Databricks-Certified-Professional-Data-Engineer-exam-dumps-torrent.html