2026 Latest Getcertkey Professional-Machine-Learning-Engineer PDF Dumps and Professional-Machine-Learning-Engineer Exam Engine Free Share: https://drive.google.com/open?id=1WWyRJrW-CInPc67HbR1yHn60uPg3nje4
After clients pay successfully for our Professional-Machine-Learning-Engineer guide torrent, they will receive our mails sent by our system in 5-10 minutes. Then they can dick the mail and log in to use our software to learn immediately. For that time is extremely important for the learners, everybody hope that they can get the efficient learning. So clients can use our Professional-Machine-Learning-Engineer Test Torrent immediately is the great merit of our Professional-Machine-Learning-Engineer exam questions. When you begin to use, you can enjoy the various functions and benefits of our Professional-Machine-Learning-Engineer practice guide such as it can simulate the exam and boosts the timing function.
Google Professional Machine Learning Engineer certification exam is intended for professionals who have experience in the field of machine learning, including data scientists, machine learning engineers, and software developers. Google Professional Machine Learning Engineer certification exam is designed to test the candidate's knowledge of advanced machine learning concepts, including deep learning, natural language processing, and computer vision.
>> New Professional-Machine-Learning-Engineer Exam Notes <<
You can be a part of this wonderful community. To do this you just need to pass the Google Professional-Machine-Learning-Engineer certification exam. Are you ready to accept this challenge? Looking for the proven and easiest way to crack the Google Professional-Machine-Learning-Engineer certification exam? If your answer is yes then you do not need to go anywhere. Just download Getcertkey Professional-Machine-Learning-Engineer exam practice questions and start Google Professional Machine Learning Engineer (Professional-Machine-Learning-Engineer) exam preparation without wasting further time. The Getcertkey Professional-Machine-Learning-Engineer Dumps will provide you with everything that you need to learn, prepare and pass the challenging Getcertkey Google Professional-Machine-Learning-Engineer exam with flying colors. You must try Getcertkey Professional-Machine-Learning-Engineer exam questions today.
The associate level certification is focused on the fundamental skills of deploying, monitoring, and maintaining projects on Google Cloud. This certification is a good starting point for those new to cloud and can be used as a path to professional level certifications.
Professional certifications span key technical job functions and assess advanced skills in design, implementation, and management. These certifications are recommended for individuals with industry experience and familiarity with Google Cloud products and solutions.
NEW QUESTION # 220
You work for a company that captures live video footage of checkout areas in their retail stores You need to use the live video footage to build a mode! to detect the number of customers waiting for service in near real time You want to implement a solution quickly and with minimal effort How should you build the model?
Answer: B
Explanation:
According to the official exam guide1, one of the skills assessed in the exam is to "design, build, and productionalize ML models to solve business challenges using Google Cloud technologies". The Vertex AI Vision Occupancy Analytics model2 is a specialized pre-built vision model that lets you count people or vehicles given specific inputs you add in video frames. It provides advanced features such as active zones counting, line crossing counting, and dwelling detection. This model is suitable for the use case of detecting the number of customers waiting for service in near real time. You can easily create and deploy an occupancy analytics application using Vertex AI Vision3. The other options are not relevant or optimal for this scenario. Reference:
Professional ML Engineer Exam Guide
Occupancy analytics guide
Create an occupancy analytics app with BigQuery forecasting
Google Professional Machine Learning Certification Exam 2023
Latest Google Professional Machine Learning Engineer Actual Free Exam Questions
NEW QUESTION # 221
You need to train a natural language model to perform text classification on product descriptions that contain millions of examples and 100,000 unique words. You want to preprocess the words individually so that they can be fed into a recurrent neural network. What should you do?
Answer: B
Explanation:
* Option A is incorrect because creating a one-hot encoding of words, and feeding the encodings into your model is not an efficient way to preprocess the words individually for a natural language model. One-hot encoding is a method of representing categorical variables as binary vectors, where each element corresponds to a category and only one element is 1 andthe rest are 01. However, this method is not suitable for high-dimensional and sparse data, such as words in a large vocabulary, because it requires a lot of memory and computation, and does not capture the semantic similarity or relationship between words2.
* Option B is correct because identifying word embeddings from a pre-trained model, and using the embeddings in your model is a good way to preprocess the words individually for a natural language model. Word embeddings are low-dimensional and dense vectors that represent the meaning and usage of words in a continuous space3. Word embeddings can be learned from a large corpus of text using neural networks, such as word2vec, GloVe, or BERT4. Using pre-trained word embeddings can save time and resources, and improve the performance of the natural language model, especially when the training data is limited or noisy5.
* Option C is incorrect because sorting the words by frequency of occurrence, and using the frequencies as the encodings in your model is not a meaningful way to preprocess the words individually for a natural language model. This method implies that the frequency of a wordis a good indicator of its importance or relevance, which may not be true. For example, the word "the" is very frequent but not very informative, while the word "unicorn" is rare but more distinctive. Moreover, this method does not capture the semantic similarity or relationship between words, and may introduce noise or bias into the model.
* Option D is incorrect because assigning a numerical value to each word from 1 to 100,000 and feeding the values as inputs in your model is not a valid way to preprocess the words individually for a natural language model. This method implies an ordinal relationship between the words, which may not be true.
For example, assigning the values 1, 2, and 3 to the words "apple", "banana", and "orange" does not make sense, as there is no inherent order among these fruits. Moreover, this method does not capture the semantic similarity or relationship between words, and may confuse the model with irrelevant or misleading information.
References:
* One-hot encoding
* Word embeddings
* Word embedding
* Pre-trained word embeddings
* Using pre-trained word embeddings in a Keras model
* [Term frequency]
* [Term frequency-inverse document frequency]
* [Ordinal variable]
* [Encoding categorical features]
NEW QUESTION # 222
A Machine Learning Specialist deployed a model that provides product recommendations on a company's website. Initially, the model was performing very well and resulted in customers buying more products on average. However, within the past few months, the Specialist has noticed that the effect of product recommendations has diminished and customers are starting to return to their original habits of spending less.
The Specialist is unsure of what happened, as the model has not changed from its initial deployment over a year ago.
Which method should the Specialist try to improve model performance?
Answer: A
NEW QUESTION # 223
You work for a company that is developing a new video streaming platform. You have been asked to create a recommendation system that will suggest the next video for a user to watch.
After a review by an AI Ethics team, you are approved to start development. Each video asset in your company's catalog has useful metadata (e.g., content type, release date, country), but you do not have any historical user event data. How should you build the recommendation system for the first version of the product?
Answer: B
Explanation:
https://developers.google.com/machine-learning/guides/rules-of-ml
NEW QUESTION # 224
You are designing an architecture with a serverless ML system to enrich customer support tickets with informative metadata before they are routed to a support agent. You need a set of models to predict ticket priority, predict ticket resolution time, and perform sentiment analysis to help agents make strategic decisions when they process support requests. Tickets are not expected to have any domain-specific terms or jargon.
The proposed architecture has the following flow: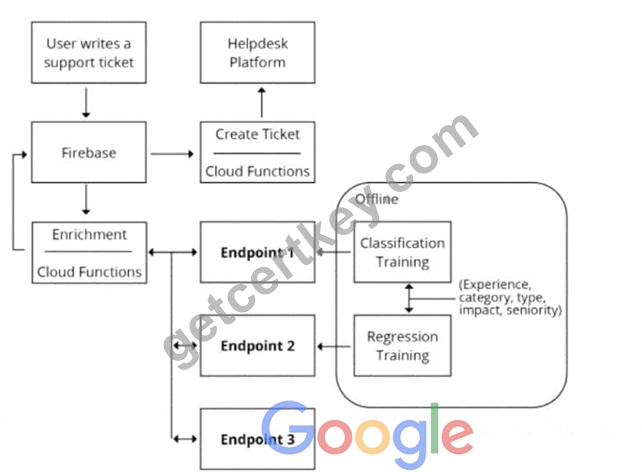
Which endpoints should the Enrichment Cloud Functions call?
Answer: C
Explanation:
Vertex AI is a unified platform for building and deploying ML models on Google Cloud. It supports both custom and AutoML models, and provides various tools and services for ML development, such as Vertex Pipelines, Vertex Vizier, Vertex Explainable AI, and Vertex Feature Store. Vertex AI can be used to create models for predicting ticket priority and resolution time, as these are domain-specific tasks that require custom training data and evaluation metrics. Cloud Natural Language API is a pre-trained service that provides natural language understanding capabilities, such as sentiment analysis, entity analysis, syntax analysis, and content classification. Cloud Natural Language API can be used toperform sentiment analysis on the support tickets, as this is a general task that does not require domain-specific knowledge or jargon. The other options are not suitable for the given architecture. AutoML Natural Language and AutoML Vision are services that allow users to create custom natural language and vision models using their own data and labels. They are not needed for sentiment analysis, as Cloud Natural Language API already provides this functionality. Cloud Vision API is a pre-trained service that provides image analysis capabilities, such as object detection, face detection, text detection, and image labeling. It is not relevant for the support tickets, as they are not expected to have any images. References:
* Vertex AI documentation
* Cloud Natural Language API documentation
NEW QUESTION # 225
......
Professional-Machine-Learning-Engineer Brain Dump Free: https://www.getcertkey.com/Professional-Machine-Learning-Engineer_braindumps.html
P.S. Free & New Professional-Machine-Learning-Engineer dumps are available on Google Drive shared by Getcertkey: https://drive.google.com/open?id=1WWyRJrW-CInPc67HbR1yHn60uPg3nje4