Magnificent Certified-Data-Engineer-Professional Preparation Dumps: Databricks Certified Data Engineer Professional Represent the Most Popular Simulating Exam - ActualTestsIT

The PDF version of our Certified-Data-Engineer-Professional guide exam is prepared for you to print it and read it everywhere. It is convenient for you to see the answers to the questions and remember them. After you buy the PDF version of our study material, you will get an E-mail form us in 5 to 10 minutes after payment. Then you can click the link in the E-mail and download your Certified-Data-Engineer-Professional study engine. You can download it as many times as you need.
| Section | Objectives |
|---|
| Topic 1: Debugging and Deploying | - Debugging and Troubleshooting
- 1. Use Lakeflow Declarative Pipelines event logs and Spark UI to debug Lakeflow Declarative Pipelines and Spark pipelines
- 2. Analyze errors and remediate failed job runs using job repairs and parameter overrides
- 3. Identify diagnostic information using Spark UI, cluster logs, system tables, and query profiles to troubleshoot errors
- Deploying CI/CD
- 1. Build and deploy Databricks resources using Databricks Asset Bundles
- 2. Configure and integrate Git-based CI/CD workflows using Databricks Git folders for notebook and code deployment
|
| Topic 2: Data Modeling | - Design and optimize data models
- 1. Design and implement scalable data models using Delta Lake to manage large datasets
- 2. Design dimensional models for analytical workloads with efficient querying and aggregation
- 3. Simplify data layout decisions and optimize query performance using liquid clustering
- 4. Identify the benefits of liquid clustering over partitioning and Z-Ordering
|
| Topic 3: Data Transformation, Cleansing, and Quality | - Transform and validate data
- 1. Develop a quarantining process for bad data with Lakeflow Declarative Pipelines or Auto Loader in classic jobs
- 2. Write efficient Spark SQL and PySpark code for advanced transformations including window functions, joins, and aggregations
|
| Topic 4: Cost & Performance Optimization | - Optimize cost and performance
- 1. Understand how and why Unity Catalog managed tables reduce operational overhead and maintenance burden
- 2. Understand Databricks query optimization techniques for large datasets, including data skipping and file pruning
- 3. Apply Change Data Feed to address streaming table limitations and improve latency
- 4. Use query profiling to identify bottlenecks such as inefficient joins and data shuffling
- 5. Understand Delta optimization techniques such as deletion vectors and liquid clustering
|
| Topic 5: Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Create an append-only data pipeline capable of handling both batch and streaming data using Delta
- 2. Ingest formats including Delta Lake, Parquet, ORC, AVRO, JSON, CSV, XML, text, and binary data from sources such as message buses and cloud storage
|
| Topic 6: Monitoring and Alerting | - Monitoring
- 1. Use Query Profile and Spark UI to monitor workloads
- 2. Use Databricks REST APIs and Databricks CLI to monitor jobs and pipelines
- 3. Use Lakeflow Declarative Pipelines event logs to monitor pipelines
- 4. Use system tables for observability of resource utilization, cost, auditing, and workloads
- Alerting
- 1. Use SQL Alerts to monitor data quality
- 2. Use the Workflows UI and Jobs API to configure notifications for job status and performance issues
|
| Topic 7: Data Governance | - Govern enterprise data
- 1. Demonstrate understanding of the Unity Catalog permission inheritance model
- 2. Create and add descriptions and metadata to enterprise data to improve discoverability
|
| Topic 8: Data Sharing and Federation | - Share and federate data
- 1. Use Delta Sharing to share live data from the Lakehouse with any computing platform
- 2. Demonstrate secure Delta Sharing between Databricks deployments using Databricks-to-Databricks sharing or with external platforms using the open sharing protocol
- 3. Configure Lakehouse Federation with appropriate governance across supported source systems
|
| Topic 9: Developing Code for Data Processing using Python and SQL | - Using Python and Tools for Development
- 1. Develop User-Defined Functions using Pandas/Python UDF
- 2. Design and implement a scalable Python project structure optimized for Databricks Asset Bundles, enabling modular development, deployment automation, and CI/CD integration
- 3. Manage and troubleshoot external third-party library installations and dependencies, including PyPI packages, local wheels, and source archives
- Building and Testing an ETL Pipeline with Lakeflow Declarative Pipelines, SQL, and Apache Spark
- 1. Develop unit and integration tests using assertDataFrameEqual, assertSchemaEqual, DataFrame.transform, testing frameworks, and debugging tools
- 2. Compare Spark Structured Streaming and Lakeflow Declarative Pipelines to determine the optimal approach for scalable ETL pipelines
- 3. Create pipeline components using control flow operators such as if/else and foreach
- 4. Create and automate ETL workloads using Jobs through the UI, APIs, or CLI
- 5. Choose appropriate configurations for environments, dependencies, high-memory notebook tasks, and retry behavior
- 6. Use APPLY CHANGES APIs to simplify CDC in Lakeflow Declarative Pipelines
- 7. Build and manage reliable, production-ready batch and streaming data pipelines using Lakeflow Declarative Pipelines and Auto Loader
- 8. Explain the advantages and disadvantages of streaming tables compared to materialized views
|
| Topic 10: Ensuring Data Security and Compliance | - Ensuring Compliance
- 1. Implement compliant batch and streaming pipelines that detect and mask PII
- 2. Develop data purging solutions that comply with data retention policies
- Applying Data Security Mechanisms
- 1. Use row filters and column masks to protect sensitive table data
- 2. Use ACLs to secure workspace objects and enforce the principle of least privilege
- 3. Apply anonymization and pseudonymization methods including hashing, tokenization, suppression, and generalization
|
>> Reliable Certified-Data-Engineer-Professional Test Duration <<
Certified-Data-Engineer-Professional Reliable Dumps Ppt | Certified-Data-Engineer-Professional PDF Questions
Maybe you have desired the Certified-Data-Engineer-Professional certification for a long time but don't have time or good methods to study. Maybe you always thought study was too boring for you. Our Certified-Data-Engineer-Professional study materials will change your mind. With our Certified-Data-Engineer-Professional exam questions, you will soon feel the happiness of study. Just look at the three different versions of our Certified-Data-Engineer-Professional learning quiz: the PDF, Software and APP online which can apply to study not only on the paper, but also can apply to study on IPAD, phone or laptop.
Databricks Certified Data Engineer Professional Sample Questions (Q69-Q74):
NEW QUESTION # 69
The data architect has mandated that all tables in the Lakehouse should be configured as external (also known as "unmanaged") Delta Lake tables.
Which approach will ensure that this requirement is met?
- A. When data is saved to a table, make sure that a full file path is specified alongside the Delta format.
- B. When a database is being created, make sure that the LOCATION keyword is used.
- C. When the workspace is being configured, make sure that external cloud object storage has been mounted.
- D. When configuring an external data warehouse for all table storage, leverage Databricks for all ELT.
- E. When tables are created, make sure that the EXTERNAL keyword is used in the CREATE TABLE statement.
Answer: E
Explanation:
To create an external or unmanaged Delta Lake table, you need to use the EXTERNAL keyword in the CREATE TABLE statement. This indicates that the table is not managed by the catalog and the data files are not deleted when the table is dropped. You also need to provide a LOCATION clause to specify the path where the data files are stored.
For example:
CREATE EXTERNAL TABLE events ( date DATE, eventId STRING, eventType STRING, data STRING) USING DELTA LOCATION `/mnt/delta/events'; This creates an external Delta Lake table named events that references the data files in the
`/mnt/delta/events' path. If you drop this table, the data files will remain intact and you can recreate the table with the same statement.
NEW QUESTION # 70
A data engineer is using Auto Loader to read incoming JSON data as it arrives. They have configured Auto Loader to quarantine invalid JSON records but notice that over time, some records are being quarantined even though they are well-formed JSON.
The code snippet is:
df = (spark.readStream
.format("cloudFiles")
.option("cloudFiles.format", "json")
.option("badRecordsPath", "/tmp/somewhere/badRecordsPath")
.schema("a int, b int")
.load("/Volumes/catalog/schema/raw_data/"))
What is the cause of the missing data?
- A. At some point, the upstream data provider switched everything to multi-line JSON.
- B. The engineer forgot to set the option "cloudFiles.quarantineMode" = "rescue".
- C. The badRecordsPath location is accumulating many small files.
- D. The source data is valid JSON but does not conform to the defined schema in some way.
Answer: D
Explanation:
Auto Loader quarantines records that cannot be parsed according to the specified schema, even if the JSON itself is well formed. If incoming records contain additional fields, missing fields, or incompatible data types compared to the declared schema, they are treated as invalid and routed to the bad records path.
NEW QUESTION # 71
The data governance team has instituted a requirement that all tables containing Personal Identifiable Information (PH) must be clearly annotated. This includes adding column comments, table comments, and setting the custom table property "contains_pii" = true.
The following SQL DDL statement is executed to create a new table:
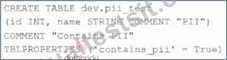
Which command allows manual confirmation that these three requirements have been met?
- A. DESCRIBE HISTORY dev.pii test
- B. DESCRIBE DETAIL dev.pii test
- C. SHOW TABLES dev
- D. DESCRIBE EXTENDED dev.pii test
- E. SHOW TBLPROPERTIES dev.pii test
Answer: D
Explanation:
This is the correct answer because it allows manual confirmation that these three requirements have been met. The requirements are that all tables containing Personal Identifiable Information (PII) must be clearly annotated, which includes adding column comments, table comments, and setting the custom table property "contains_pii" = true. The DESCRIBE EXTENDED command is used to display detailed information about a table, such as its schema, location, properties, and comments. By using this command on the dev.pii_test table, one can verify that the table has been created with the correct column comments, table comment, and custom table property as specified in the SQL DDL statement.
NEW QUESTION # 72
The data engineering team maintains the following code:
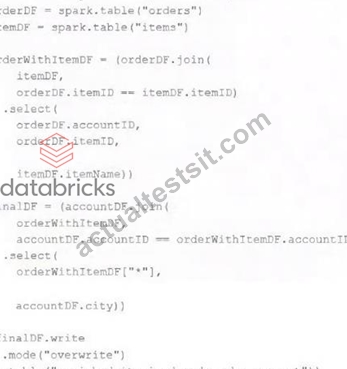
Assuming that this code produces logically correct results and the data in the source tables has been de-duplicated and validated, which statement describes what will occur when this code is executed?
- A. A batch job will update the enriched_itemized_orders_by_account table, replacing only those rows that have different values than the current version of the table, using accountID as the primary key.
- B. An incremental job will leverage information in the state store to identify unjoined rows in the source tables and write these rows to the enriched_iteinized_orders_by_account table.
- C. An incremental job will detect if new rows have been written to any of the source tables; if new rows are detected, all results will be recalculated and used to overwrite the enriched_itemized_orders_by_account table.
- D. The enriched_itemized_orders_by_account table will be overwritten using the current valid version of data in each of the three tables referenced in the join logic.
- E. No computation will occur until enriched_itemized_orders_by_account is queried; upon query materialization, results will be calculated using the current valid version of data in each of the three tables referenced in the join logic.
Answer: D
Explanation:
This is the correct answer because it describes what will occur when this code is executed. The code uses three Delta Lake tables as input sources: accounts, orders, and order_items. These tables are joined together using SQL queries to create a view called new_enriched_itemized_orders_by_account, which contains information about each order item and its associated account details. Then, the code uses write.format("delta").mode("overwrite") to overwrite a target table called enriched_itemized_orders_by_account using the data from the view. This means that every time this code is executed, it will replace all existing data in the target table with new data based on the current valid version of data in each of the three input tables.
NEW QUESTION # 73
When monitoring a complex workload, being able to see the query plan is critical to understanding what the workload is doing. Where can the visualization of the query plan be found?
- A. In the Spart UI, under the Jobs tab
- B. In the Query Profiler, under Query Source
- C. In the Query Profiler, under the Stages tab
- D. In the Spark UI, under the SQL/DataFrame tab
Answer: D
Explanation:
The Spark UI provides detailed visibility into how queries are executed. The SQL/DataFrame tab displays the logical and physical query plans, allowing engineers to visualize execution details and understand how the workload is processed across stages and operators.
NEW QUESTION # 74
......
ActualTestsIT's Databricks Certified-Data-Engineer-Professional exam training materials are the best training materials of all the Internet training resources. Our visibility is very high, which are results that obtained through many candidates who have used the ActualTestsIT's Databricks Certified-Data-Engineer-Professional exam training materials. If you also use ActualTestsIT's Databricks Certified-Data-Engineer-Professional Exam Training materials, we can give you 100% guarantee of success. If you do not pass the exam, we will refund the full purchase cost to you. For the vital interests of the majority of candidates, ActualTestsIT is absolutely trustworthy.
Certified-Data-Engineer-Professional Reliable Dumps Ppt: https://www.actualtestsit.com/Databricks/Certified-Data-Engineer-Professional-exam-prep-dumps.html
- Latest Certified-Data-Engineer-Professional Dumps 🥶 Certified-Data-Engineer-Professional Exam Cram Pdf 🎓 Exam Certified-Data-Engineer-Professional Questions Pdf 🙌 Immediately open ⏩ www.examcollectionpass.com ⏪ and search for ⇛ Certified-Data-Engineer-Professional ⇚ to obtain a free download 💔Updated Certified-Data-Engineer-Professional Dumps
- Get Success in Databricks Certified-Data-Engineer-Professional Exam with Flying Colors 🍊 Immediately open ➥ www.pdfvce.com 🡄 and search for 【 Certified-Data-Engineer-Professional 】 to obtain a free download 🍕Certified-Data-Engineer-Professional Exam Cram Pdf
- Certified-Data-Engineer-Professional Hottest Certification 🖐 Certified-Data-Engineer-Professional Valid Exam Book 🍨 Certified-Data-Engineer-Professional Valid Test Cram 🍽 Search for ▛ Certified-Data-Engineer-Professional ▟ on 《 www.prepawayexam.com 》 immediately to obtain a free download 🥘Exam Certified-Data-Engineer-Professional Questions Pdf
- Valid Certified-Data-Engineer-Professional Exam Duration 🧇 Certified-Data-Engineer-Professional Valid Test Cram 🕺 Certified-Data-Engineer-Professional Valid Exam Tutorial 🏬 Search on 【 www.pdfvce.com 】 for ☀ Certified-Data-Engineer-Professional ️☀️ to obtain exam materials for free download 🙎Certified-Data-Engineer-Professional Valid Test Test
- Reliable Certified-Data-Engineer-Professional Study Notes 🌭 Exam Certified-Data-Engineer-Professional Questions Pdf ✌ Certified-Data-Engineer-Professional Simulations Pdf ⚪ Enter ( www.troytecdumps.com ) and search for ( Certified-Data-Engineer-Professional ) to download for free 📉Certified-Data-Engineer-Professional Reliable Exam Papers
- Latest Certified-Data-Engineer-Professional Dumps 🤙 Certified-Data-Engineer-Professional Valid Exam Tutorial 🥮 Certified-Data-Engineer-Professional Valid Exam Book 🌎 Enter ➽ www.pdfvce.com 🢪 and search for ➤ Certified-Data-Engineer-Professional ⮘ to download for free 🕢Certified-Data-Engineer-Professional Hottest Certification
- Free PDF 2026 Certified-Data-Engineer-Professional: Accurate Reliable Databricks Certified Data Engineer Professional Test Duration 🕳 Copy URL ⇛ www.prepawaypdf.com ⇚ open and search for 【 Certified-Data-Engineer-Professional 】 to download for free 🧤Latest Certified-Data-Engineer-Professional Dumps
- Free PDF Quiz 2026 Databricks Certified-Data-Engineer-Professional – The Best Reliable Test Duration 🦋 Open 「 www.pdfvce.com 」 and search for ✔ Certified-Data-Engineer-Professional ️✔️ to download exam materials for free ☮Certified-Data-Engineer-Professional Reliable Exam Papers
- Free PDF 2026 Certified-Data-Engineer-Professional: Accurate Reliable Databricks Certified Data Engineer Professional Test Duration 📶 Search for 【 Certified-Data-Engineer-Professional 】 and obtain a free download on ▛ www.examcollectionpass.com ▟ 🟣Certified-Data-Engineer-Professional Hottest Certification
- Certified-Data-Engineer-Professional Valid Exam Tutorial 🍃 Certified-Data-Engineer-Professional Simulations Pdf 🕧 New Certified-Data-Engineer-Professional Exam Fee 🔋 Easily obtain ⏩ Certified-Data-Engineer-Professional ⏪ for free download through 【 www.pdfvce.com 】 🛹New Certified-Data-Engineer-Professional Exam Fee
- Free PDF 2026 Certified-Data-Engineer-Professional: Accurate Reliable Databricks Certified Data Engineer Professional Test Duration 🍚 Search for ⏩ Certified-Data-Engineer-Professional ⏪ on ➡ www.practicevce.com ️⬅️ immediately to obtain a free download 🏠Exam Certified-Data-Engineer-Professional Questions Pdf
- www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, Disposable vapes