AI-300認定はこの分野で大きな効果があり、将来的にもあなたのキャリアに影響を与える可能性があります。 AI-300実際の質問ファイルはプロフェッショナルで高い合格率であるため、ユーザーは最初の試行で試験に合格できます。高品質と合格率により、私たちは有名になり、より速く成長しています。多くの受験者は、AI-300学習ガイド資料が資格試験に最適なアシスタントであり、学習するために他のトレーニングコースや書籍を購入する必要がなく、試験の前にAI-300 Microsoft Certified試験ブレーンダンプを実践する、彼らは簡単に短時間で試験に合格することができます。
| Section | Objectives |
|---|---|
| Design and implement generative AI solutions | - Large language model integration
|
| Operationalizing machine learning solutions | - ML lifecycle management
|
| Plan and design AI solutions using Azure AI services | - Responsible AI design
|
| Implement secure and scalable AI systems | - Security and governance
|
AI-300練習資料は、AI-300試験に簡単に合格するのに役立ちます。 AI-300の学習資料に雇われたJapancert業界の専門家は、理解しにくいすべての専門用語を例、図などで説明しています。AI-300の実際のテストで使用されるすべての言語は非常にシンプルで理解しやすいものでした。 AI-300学習教材を使用すると、プロの本の内容を理解していないことを心配する必要はありません。 また、家庭教師のクラスに行くために高価な授業料を費やす必要はありません。Operationalizing Machine Learning and Generative AI SolutionsのAI-300テストエンジンは、研究のすべての問題を解決するのに役立ちます。
質問 # 114
-
A customer-facing web application uses a foundational model deployed through Microsoft Foundry.
A new model version must be introduced and validated without disrupting production traffic.
You need to deploy the new version by using a safe promotion strategy.
Which three actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.
正解:
解説: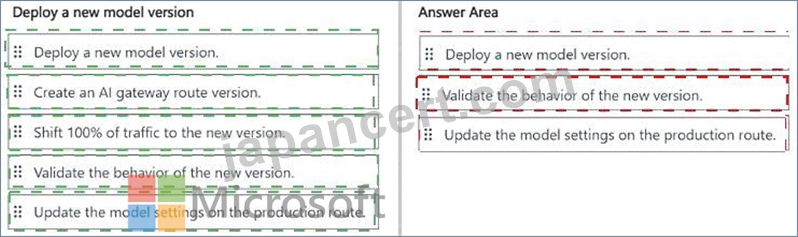
Explanation:
Correct sequence:
* Deploy a new model version.
* Validate the behavior of the new version.
* Update the model settings on the production route.
The safe approach is to deploy the new model side by side with the existing production deployment rather than modifying the currently serving model immediately. Microsoft Foundry documentation explains that a newly available model version can be tested through a separate deployment, allowing teams to evaluate behavioral differences without affecting existing production requests.
After deployment, validate the behavior of the new version against representative production workloads.
Validation should cover response quality, latency, errors, structured-output compatibility, tool-calling behavior, safety characteristics, and application-specific acceptance criteria. Microsoft ' s model-migration guidance explicitly places validation before production rollout and recommends proving that the new configuration meets defined quality requirements before broad exposure.
Once validation succeeds, update the model settings on the production route so that the application ' s existing production entry point directs requests to the validated deployment. This preserves the stable application-facing endpoint while changing the backend model in a controlled manner.
Shift 100% of traffic to the new version is not the appropriate intermediate safe-promotion action because immediately transferring all production traffic removes the staged validation safeguard. Creating another AI gateway route version is also unnecessary for the required three-step promotion sequence.
Study Guide Reference: Implement machine learning model lifecycle and operations - model versioning, side-by-side deployments, pre-production validation, controlled promotion, production routing, and rollback- safe model lifecycle management.
質問 # 115
You manage an Azure Machine Learning workspace named workspace1 by using the Python SDK v2. You create a General Purpose v2 Azure storage account named mlstorage 1. The storage account includes a publicly accessible container named mlcontainer 1. The container stores 10 blobs with files in the CSV format.
You must develop Python SDK v2 code to create a data asset referencing all blobs in the container named mlcontainer 1.
You need to complete the Python SDK v2 code.
How should you complete the code? To answer, select the appropriate options in the answer area . NOTE:
Each correct selection is worth one point.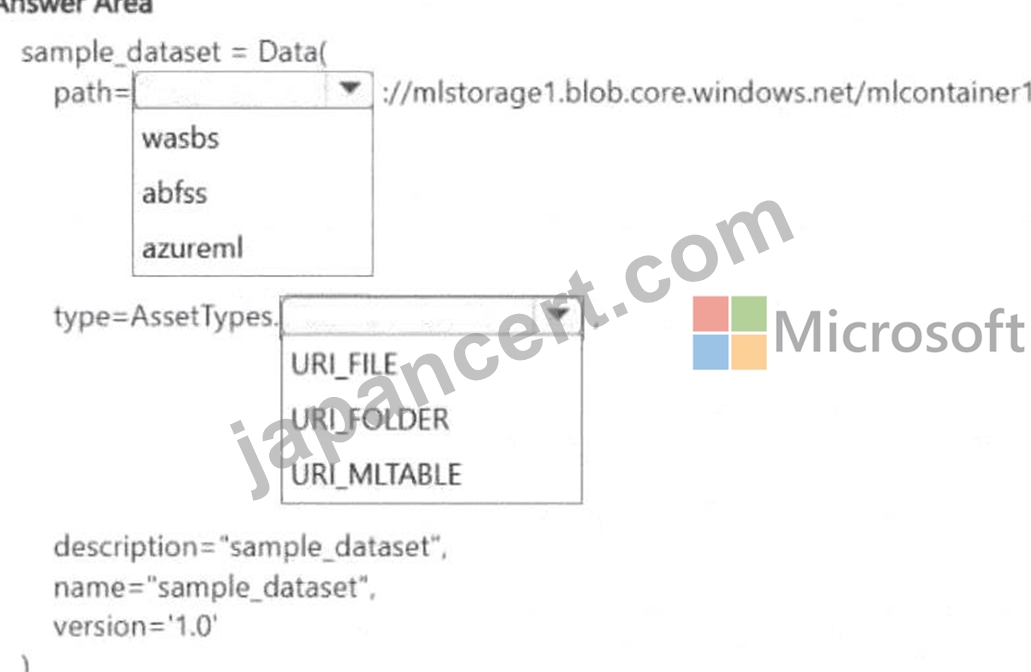
正解:
解説:
Explanation:
Because you want to reference all blobs in a container rather than a single file, the correct asset type is AssetTypes.URI_FOLDER. This type points to a directory-level URI, allowing Azure ML to traverse all files within it. For a publicly accessible Azure Blob Storage container, the URI follows the pattern
https://storage_account.blob.core.windows.net/container_name/. You then create the Data object with the correct type, path, name, and version parameters, and register it in the workspace using ml_client.data.
create_or_update. Do not use AssetTypes.URI_FILE, which references a single file. Do not use AssetTypes.
MLTABLE unless you have an MLTable YAML descriptor. URI_FOLDER is the correct choice for referencing a collection of CSV blobs in an Azure Blob Storage container, allowing Azure ML to discover and process all files within the specified path.
Microsoft Learn Reference Topic: Create and manage data assets in Azure Machine Learning Python SDK v2 - URI_FOLDER
質問 # 116
A team develops and manages a conversational assistant by using Microsoft Foundry.
The team requires generative AI to automatically evaluate every pull request of an agentic application and fail the build if safety thresholds are exceeded.
You need to automate evaluations as part of CI.
What should you configure?
正解:A
解説:
The correct solution is a GitHub Actions workflow that executes Microsoft Foundry evaluations as part of the CI process . Microsoft provides an AI agent evaluation GitHub Action specifically for incorporating Foundry agent evaluations into CI/CD workflows. The action can invoke the agent against an evaluation dataset, execute configured evaluators-including safety evaluators-and publish evaluation results before a change reaches production.
For pull-request gating, the workflow can be configured to run whenever relevant application files change.
Evaluation commands can also enforce explicit thresholds and return a non-zero exit code when those thresholds are not satisfied. Microsoft documents evaluation gating through options such as --fail-on pass- rate= < threshold > or --fail-on any-failure; a non-zero result causes the CI job to fail, preventing unsafe changes from being promoted.
A blocklist or content filter provides runtime content protection but does not automate pull-request evaluation.
A retrieval chunking strategy affects RAG retrieval quality, not CI safety gates.
Therefore, the required mechanism is GitHub Actions integrated with Foundry evaluation runs and safety thresholds .
Study Guide Reference: Implement generative AI quality assurance and observability - automated evaluations, CI/CD quality gates, safety evaluators, GitHub Actions, and pre-production validation.
質問 # 117
Drag and Drop Question
A team is developing a Retrieval-Augmented Generation (RAG) system.
The team requires improvements to the system's retrieval quality to ensure accurate, grounded responses.
You need to assess RAG performance before you can suggest an improvement strategy.
Which four actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.
正解:
解説:
Explanation:
To properly assess your Azure Retrieval-Augmented Generation (RAG) system's performance before implementing an improvement strategy, you should include the following four steps: Run RAG evaluators, Collect retrieval logs, Modify model temperature, and Regenerate the prompt template.
Step 1: Run RAG evaluators
Run RAG evaluators is the primary method to objectively measure system performance.
Evaluators calculate data-driven metrics like groundedness, relevance, and retrieval precision using tools like Azure AI Studio Evaluators.
Step 2: Collect retrieval logs
Collect retrieval logs provides the raw operational data needed for assessment. Analyzing these logs helps you identify exactly which documents were retrieved, their relevance scores, and where the retrieval pipeline failed to fetch the correct context.
Step 3: Modify model temperature
Modify model temperature: Adjusting the temperature during assessment helps isolate whether poor responses are caused by bad retrieval or by the LLM being too creative (high temperature) or too rigid (low temperature). Testing variations helps establish a performance baseline.
Step 4: Regenerate the prompt template
Regenerate the prompt template: Evaluating how different prompt variations alter the output allows you to assess if the current template is effectively forcing the model to rely only on the retrieved context, which is critical for identifying grounding issues.
Incorrect:
Adjust the chunking strategy
This is an improvement action, not an assessment step. You would perform this optimization strategy after your assessment reveals that information is being cut off or poorly contextualized.
Re-index documents: This is a heavy remediation step. Re-indexing is a time- and resource- consuming strategy used to fix issues once the assessment phase has already proven that the current index or embedding model is faulty.
Reference:
https://flytoleisure.medium.com/guideline-for-building-a-practical-and-effective-rag-retrieval-augmented-generation-application-f6cf50676e37
質問 # 118
You need to recommend an experiment-tracking strategy that ensures consistent experiment results.
What should you recommend?
正解:B
解説:
MLflow is the industry-standard open-source platform for experiment tracking, and Azure Machine Learning has first-class native integration with it. When you use MLflow within an Azure ML job, parameters, metrics, and artifacts are automatically logged to the run history of the AML workspace, making every run reproducible and comparable. Option A (AML job output logs) only captures console output and lacks structured parameter and metric logging. Option C (Application Insights logs) is designed for application- level telemetry, not ML experiment metadata. Option D (Azure Monitor alerts) is a reactive notification tool, not a tracking system. MLflow ' s autologging capability means that for common frameworks such as scikit- learn, XGBoost, and PyTorch, parameters and metrics are captured without a single line of custom code, directly answering Fabrikam ' s requirement for consistent experiment tracking.
Microsoft Learn Reference Topic: Track ML experiments with MLflow - Azure Machine Learning MLflow integration
質問 # 119
......
もしJapancertのAI-300問題集を利用してからやはりAI-300認定試験に失敗すれば、あなたは問題集を購入する費用を全部取り返すことができます。これはまさにJapancertが受験生の皆さんに与えるコミットメントです。優秀な試験参考書は話すことに依頼することでなく、受験生の皆さんに検証されることに依頼するのです。 Japancertの参考資料は時間の試練に耐えることができます。Japancertは現在の実績を持っているのは受験生の皆さんによって実践を通して得られた結果です。真実かつ信頼性の高いものだからこそ、Japancertの試験参考書は長い時間にわたってますます人気があるようになっています。
AI-300認証試験: https://www.japancert.com/AI-300.html