さらに、Fast2test MLA-C01ダンプの一部が現在無料で提供されています:https://drive.google.com/open?id=1GcjmkE3Ekpc73y4TOj37AjVX_cj3thUn
最近Amazon試験はますます重要になっています。受験生たちはたいへん悩んでいるんでしょう。受験生としてのあなたを助けるために、我々は質量高いMLA-C01問題集を提供して、あなたは我々の商品を利用して、試験に合格することができます。我々の提供するMLA-C01問題集を信じてください。
| Certification Vendor: | Amazon Web Services (AWS) |
|---|---|
| Exam Name: | AWS Certified Machine Learning Engineer - Associate |
| Exam Number: | MLA-C01 |
| Certificate Validity Period: | 3 years |
| Available Languages: | Simplified Chinese, Traditional Chinese, Korean, Japanese, English |
| Exam Duration: | 170 minutes |
| Passing Score: | 1000-2000 scaled score (passing score approximately 720) |
| Exam Price: | 150 USD |
| Exam Format: | Multiple response, Multiple choice |
| Real Exam Qty: | 85 |
| Related Certifications: | AWS Certified Solutions Architect - Associate AWS Certified Data Engineer - Associate AWS Certified Developer - Associate |
| Sample Questions: | Amazon MLA-C01 Sample Questions |
| Exam Way: | Online proctored (Pearson VUE) or in-person testing center |
| Pre Condition: | Recommended: 2+ years of ML engineering experience, familiarity with AWS ML services |
| Official Syllabus URL: | https://aws.amazon.com/certification/certified-machine-learning-engineer-associate/ |
MLA-C01試験はあなたのキャリアのマイルストーンで、競争が激しいこの時代で、これまで以上に重要になりました。あなたは一回で気楽にMLA-C01試験に合格することを保証します。将来で新しいチャンスを作って、仕事が楽しげにやらせます。Fast2testの値段よりそれが創造する価値ははるかに大きいです。我々は弊社の商品とあなたの努力を通してあなたはMLA-C01試験に合格することができると信じています。
| トピック | 出題範囲 |
|---|---|
| トピック 1 |
|
| トピック 2 |
|
| トピック 3 |
|
| トピック 4 |
|
質問 # 188
A company uses 10 Reserved Instances of accelerated instance types to serve the current version of an ML model. An ML engineer needs to deploy a new version of the model to an Amazon SageMaker real-time inference endpoint.
The solution must use the original 10 instances to serve both versions of the model. The solution also must include one additional Reserved Instance that is available to use in the deployment process. The transition between versions must occur with no downtime or service interruptions.
Which solution will meet these requirements?
正解:A
質問 # 189
Hotspot Question
An ML engineer must choose the appropriate Amazon SageMaker algorithm to solve specific AI problems.
Select the correct SageMaker built-in algorithm from the following list for each use case. Each algorithm should be selected one time.
- Random Cut Forest (RCF) algorithm
- Semantic segmentation algorithm
- Sequence-to-Sequence (seq2seq) algorithm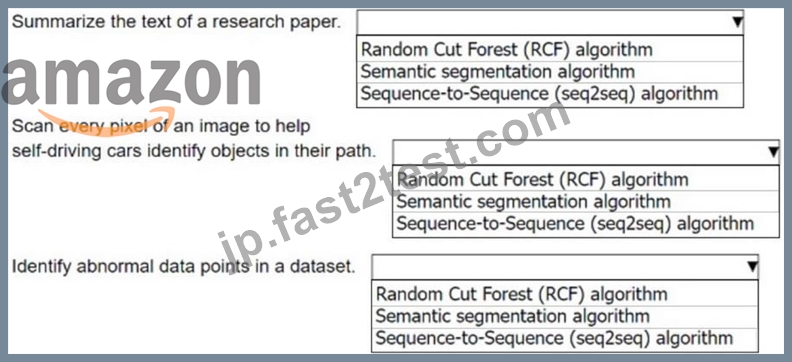
正解:
解説: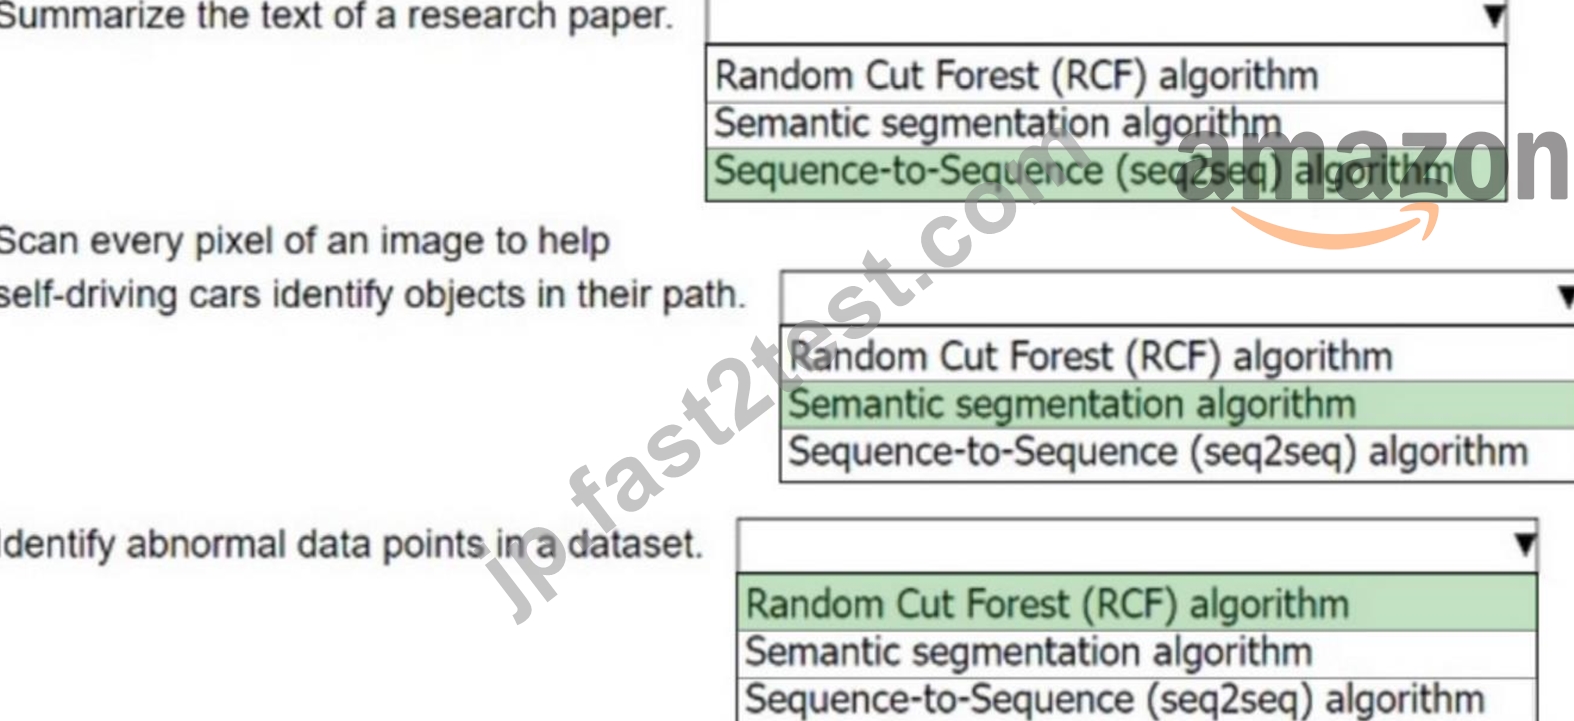
質問 # 190
A company launches a feature that predicts home prices. An ML engineer trained a regression model using the SageMaker AI XGBoost algorithm. The model performs well on training data but underperforms on real- world validation data.
Which solution will improve the validation score with the LEAST implementation effort?
正解:B
解説:
This scenario indicates overfitting. AWS documentation for XGBoost recommends increasing the L2 regularization parameter (lambda) to reduce overfitting and improve generalization.
Increasing num_round worsens overfitting. Changing evaluation metrics does not change model behavior.
Collecting more data is effective but requires significant effort.
Regularization is a low-effort, high-impact fix.
Therefore, Option D is correct.
質問 # 191
An ML engineer needs to use Amazon SageMaker Feature Store to create and manage features to train a model.
Select and order the steps from the following list to create and use the features in Feature Store. Each step should be selected one time. (Select and order three.)
* Access the store to build datasets for training.
* Create a feature group.
* Ingest the records.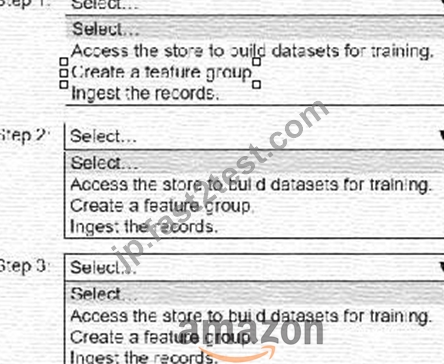
正解:
解説: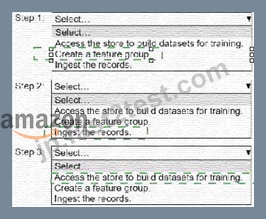
Explanation: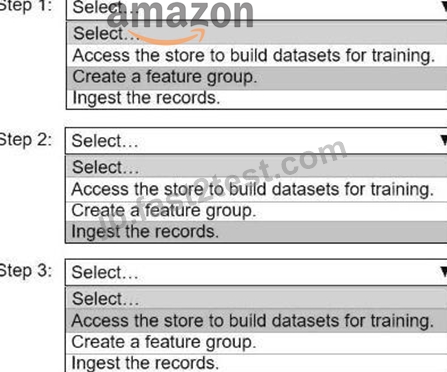
Step 1: Create a feature group.
Step 2: Ingest the records.
Step 3: Access the store to build datasets for training.
* Step 1: Create a Feature Group
* Why? A feature group is the foundational unit in SageMaker Feature Store, where features are defined, stored, and organized. Creating a feature group specifies the schema (name, data type) for the features and the primary keys for data identification.
* How? Use the SageMaker Python SDK or AWS CLI to define the feature group by specifying its name, schema, and S3 storage location for offline access.
* Step 2: Ingest the Records
* Why? After creating the feature group, the raw data must be ingested into the Feature Store. This step populates the feature group with data, making it available for both real-time and offline use.
* How? Use the SageMaker SDK or AWS CLI to batch-ingest historical data or stream new records into the feature group. Ensure the records conform to the feature group schema.
* Step 3: Access the Store to Build Datasets for Training
* Why? Once the features are stored, they can be accessed to create training datasets. These datasets combine relevant features into a single format for machine learning model training.
* How? Use the SageMaker Python SDK to query the offline store or retrieve real-time features using the online store API. The offline store is typically used for batch training, while the online store is used for inference.
Order Summary:
* Create a feature group.
* Ingest the records.
* Access the store to build datasets for training.
This process ensures the features are properly managed, ingested, and accessible for model training using Amazon SageMaker Feature Store.
質問 # 192
A music streaming company constantly streams song ratings from an application to an Amazon S3 bucket.
The company wants to use the ratings as an input for training and inference of an Amazon SageMaker AI model.
The company has an AWS Glue Data Catalog that is configured with the S3 bucket as the source. An ML engineer needs to implement a solution to create a repository for this data. The solution must ensure that the data stays synchronized during batch training and real-time inference.
Which solution will meet these requirements?
正解:A
質問 # 193
......
MLA-C01資料勉強: https://jp.fast2test.com/MLA-C01-premium-file.html
P.S. Fast2testがGoogle Driveで共有している無料かつ新しいMLA-C01ダンプ:https://drive.google.com/open?id=1GcjmkE3Ekpc73y4TOj37AjVX_cj3thUn