Braindumps Databricks-Certified-Data-Engineer-Associate Pdf & Real Databricks-Certified-Data-Engineer-Associate Dumps

DOWNLOAD the newest ExamCost Databricks-Certified-Data-Engineer-Associate PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1ydCFgnUngdLUhCSKGYT1-JO7xj7Rlzff
We committed to providing you with the best possible Databricks Certified Data Engineer Associate Exam (Databricks-Certified-Data-Engineer-Associate) practice test material to succeed in the Databricks Databricks-Certified-Data-Engineer-Associate exam. With real Databricks-Certified-Data-Engineer-Associate exam questions in PDF, customizable Databricks Databricks-Certified-Data-Engineer-Associate practice exams, free demos, and 24/7 support, you can be confident that you are getting the best possible Databricks-Certified-Data-Engineer-Associate Exam Material for the test. Buy today and start your journey to Databricks Certified Data Engineer Associate Exam (Databricks-Certified-Data-Engineer-Associate) exam success with ExamCost!
| Section | Weight | Objectives |
|---|
| Delta Lake Fundamentals | 20-25% | - Explain Delta Lake features and benefits
- Create and manage Delta tables
- Understand ACID transactions and time travel
- Write to and read from Delta tables
|
| Spark SQL and DataFrames | 15-20% | - Aggregate and group data
- Handle null values and data quality
- Write and execute Spark SQL queries
- Join and union DataFrames
|
| Lakehouse Platform Concepts | 10-15% | - Understand the Lakehouse architecture and its benefits
- Explain data governance and security concepts
- Describe key Databricks Lakehouse platform components
|
| Python for Data Engineering | 10-15% | - Work with Spark APIs in Python
- Use PySpark for data processing
- Implement user-defined functions (UDFs)
|
| Apache Spark Data Processing Fundamentals | 20-25% | - Use Spark SQL for data processing
- Apply transformations and actions on DataFrames
- Work with structured data types (arrays, maps, structs)
- Create and use Spark DataFrames
|
| Data Pipeline Architecture | 15-20% | - Monitor and optimize pipeline performance
- Design data pipelines for batch and streaming
- Implement incremental data processing
- Understand ELT vs ETL patterns
|
>> Braindumps Databricks-Certified-Data-Engineer-Associate Pdf <<
Real Databricks Databricks-Certified-Data-Engineer-Associate Dumps - Databricks-Certified-Data-Engineer-Associate Reliable Exam Simulations
We believe that if you trust our Databricks-Certified-Data-Engineer-Associate exam simulator and we will help you obtain Databricks-Certified-Data-Engineer-Associate certification easily. After purchasing, you can receive our Databricks-Certified-Data-Engineer-Associate training material and download within 10 minutes. Besides, we provide one year free updates of our Databricks-Certified-Data-Engineer-Associate learning guide for you and money back guaranteed policy so that we are sure that it will give you free-shopping experience. Now choose our Databricks-Certified-Data-Engineer-Associate practic braindump, you will not regret.
Databricks Certified Data Engineer Associate Exam Sample Questions (Q181-Q186):
NEW QUESTION # 181
A data engineer is deploying a dashboard through a Declarative Automation Bundle. The dashboard resource references ${var.dataset_catalog}, and the bundle contains the following configuration:
bundle:
name: workspace_assets
variables:
dataset_catalog:
default: catalog_dev
targets:
dev:
variables:
dataset_catalog: catalog_dev
prod:
variables:
dataset_catalog: catalog_prod
Which action deploys the dashboard to the production target using catalog_prod without changing the resource definition?
- A. Run databricks bundle execute --profile prod so that the CLI selects targets.prod and applies catalog_prod.
- B. Run databricks bundle deploy --profile prod so that the CLI selects targets.prod and applies catalog_prod.
- C. Run databricks bundle deploy --target prod so that the deployment uses targets.prod and its dataset_catalog override.
- D. Run databricks bundle deploy --var dataset_catalog=catalog_prod so that the CLI automatically selects targets.prod.
Answer: C
NEW QUESTION # 182
A data engineer has developed a data pipeline to ingest data from a JSON source using Auto Loader, but the engineer has not provided any type inference or schema hints in their pipeline. Upon reviewing the data, the data engineer has noticed that all of the columns in the target table are of the string type despite some of the fields only including float or boolean values.
Which of the following describes why Auto Loader inferred all of the columns to be of the string type?
- A. JSON data is a text-based format
- B. Auto Loader only works with string data
- C. All of the fields had at least one null value
- D. There was a type mismatch between the specific schema and the inferred schema
- E. Auto Loader cannot infer the schema of ingested data
Answer: A
Explanation:
JSON data is a text-based format that represents data as a collection of name-value pairs. By default, when Auto Loader infers the schema of JSON data, it treats all columns as strings. This is because JSON data can have varying data types for the same column across different files or records, and Auto Loader does not attempt to reconcile these differences. For example, a column named "age" may have integer values in some files, but string values in others. To avoid data loss or errors, Auto Loader infers the column as a string type.
However, Auto Loader also provides an option to infer more precise column types based on the sample data.
This option is called cloudFiles.inferColumnTypes and it can be set to true or false. When set to true, Auto Loader tries to infer the exact data types of the columns, such as integers, floats, booleans, or nested structures. When set to false, Auto Loader infers all columns as strings. The default value of this option is false. References: Configure schema inference and evolution in Auto Loader, Schema inference with auto loader (non-DLT and DLT), Using and Abusing Auto Loader's Inferred Schema, Explicit path to data or a defined schema required for Auto loader.
NEW QUESTION # 183
Which of the following describes a benefit of creating an external table from Parquet rather than CSV when using a CREATE TABLE AS SELECT statement?
- A. Parquet files have the ability to be optimized
- B. CREATE TABLE AS SELECT statements cannot be used on files
- C. Parquet files will become Delta tables
- D. Parquet files have a well-defined schema
- E. Parquet files can be partitioned
Answer: D
Explanation:
Option C is the correct answer because Parquet files have a well-defined schema that is embedded within the data itself. This means that the data types and column names of the Parquet files are automatically detected and preserved when creating an external table from them. This also enables the use of SQL and other structured query languages to access and analyze the data. CSV files, on the other hand, do not have a schema embedded in them, and require specifying the schema explicitly or inferring it from the data when creating an external table from them. This can lead to errors or inconsistencies in the data types and column names, and also increase the processing time and complexity CREATE TABLE AS SELECT, Parquet Files, CSV Files, Parquet vs. CSV
NEW QUESTION # 184
A data engineer has configured a Structured Streaming job to read from a table, manipulate the data, and then perform a streaming write into a new table.
The code block used by the data engineer is below:
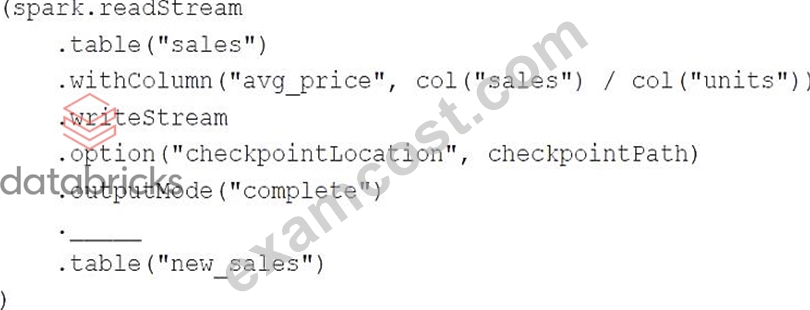
If the data engineer only wants the query to process all of the available data in as many batches as required, which of the following lines of code should the data engineer use to fill in the blank?
- A. processingTime(1)
- B. trigger(continuous="once")
- C. trigger(processingTime="once")
- D. trigger(availableNow=True)
- E. trigger(parallelBatch=True)
Answer: D
Explanation:
https://spark.apache.org/docs/latest/api/python/reference/pyspark.ss/api/pyspark.sql.streaming.DataStreamWriter.trigger.html
NEW QUESTION # 185
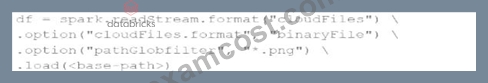
A data engineer needs to parse only png files in a directory that contains files with different suffixes. Which code should the data engineer use to achieve this task?
Answer: D
NEW QUESTION # 186
......
How can our Databricks-Certified-Data-Engineer-Associate practice materials become salable products? Their quality with low prices is unquestionable. There are no better or cheaper practice materials can replace our Databricks-Certified-Data-Engineer-Associate exam questions as alternatives while can provide the same functions. The accomplished Databricks-Certified-Data-Engineer-Associate Guide exam is available in the different countries around the world and being testified over the customers around the different countries. They are valuable acquisitions to the filed.
Real Databricks-Certified-Data-Engineer-Associate Dumps: https://www.examcost.com/Databricks-Certified-Data-Engineer-Associate-practice-exam.html
- Free Databricks-Certified-Data-Engineer-Associate Practice 🥪 Frenquent Databricks-Certified-Data-Engineer-Associate Update 💻 Free Databricks-Certified-Data-Engineer-Associate Practice 🧙 Download ➠ Databricks-Certified-Data-Engineer-Associate 🠰 for free by simply searching on 《 www.pass4test.com 》 ⚓Test Databricks-Certified-Data-Engineer-Associate Simulator Free
- Databricks-Certified-Data-Engineer-Associate Valid Test Preparation 😩 Valid Databricks-Certified-Data-Engineer-Associate Test Question 🖌 Databricks-Certified-Data-Engineer-Associate Practice Online 🏋 Search for “ Databricks-Certified-Data-Engineer-Associate ” and easily obtain a free download on ⏩ www.pdfvce.com ⏪ 🧏Databricks-Certified-Data-Engineer-Associate Valid Exam Registration
- Achieve Success 100% With Databricks Databricks-Certified-Data-Engineer-Associate Exam Questions In The First Attempt ✔ Search for “ Databricks-Certified-Data-Engineer-Associate ” and download it for free immediately on “ www.troytecdumps.com ” 🚚Databricks-Certified-Data-Engineer-Associate Valid Exam Format
- Databricks-Certified-Data-Engineer-Associate Test Sample Questions - Databricks-Certified-Data-Engineer-Associate Vce Pdf Training - Databricks-Certified-Data-Engineer-Associate Valid Test Simulator 🌖 Open “ www.pdfvce.com ” enter ➥ Databricks-Certified-Data-Engineer-Associate 🡄 and obtain a free download 🏢Databricks-Certified-Data-Engineer-Associate Valid Exam Format
- Test Databricks-Certified-Data-Engineer-Associate Online 🕓 Databricks-Certified-Data-Engineer-Associate Authentic Exam Questions 🔢 Free Sample Databricks-Certified-Data-Engineer-Associate Questions ➖ Search on ▷ www.troytecdumps.com ◁ for 【 Databricks-Certified-Data-Engineer-Associate 】 to obtain exam materials for free download 🤴Databricks-Certified-Data-Engineer-Associate Authentic Exam Questions
- 100% Pass 2026 Databricks Databricks-Certified-Data-Engineer-Associate: Databricks Certified Data Engineer Associate Exam Authoritative Braindumps Pdf 🐱 Search for ▷ Databricks-Certified-Data-Engineer-Associate ◁ and easily obtain a free download on ➽ www.pdfvce.com 🢪 🍏Latest Databricks-Certified-Data-Engineer-Associate Dumps Ebook
- Download Databricks-Certified-Data-Engineer-Associate Demo 🥘 Valid Databricks-Certified-Data-Engineer-Associate Test Question 🔖 Databricks-Certified-Data-Engineer-Associate Valid Exam Registration 🗨 Download ⇛ Databricks-Certified-Data-Engineer-Associate ⇚ for free by simply entering ▷ www.exam4labs.com ◁ website 🗨Testing Databricks-Certified-Data-Engineer-Associate Center
- Free Databricks-Certified-Data-Engineer-Associate Practice 🍒 Free Databricks-Certified-Data-Engineer-Associate Practice 🧽 Free Sample Databricks-Certified-Data-Engineer-Associate Questions 👞 Go to website 【 www.pdfvce.com 】 open and search for ➽ Databricks-Certified-Data-Engineer-Associate 🢪 to download for free 👄Databricks-Certified-Data-Engineer-Associate Valid Test Preparation
- 2026 Unparalleled Databricks Braindumps Databricks-Certified-Data-Engineer-Associate Pdf Pass Guaranteed Quiz 😱 Search on ✔ www.exam4labs.com ️✔️ for 《 Databricks-Certified-Data-Engineer-Associate 》 to obtain exam materials for free download 🤺Databricks-Certified-Data-Engineer-Associate Valid Exam Registration
- Databricks-Certified-Data-Engineer-Associate Valid Test Preparation 🍽 Reliable Databricks-Certified-Data-Engineer-Associate Braindumps Free 🙌 Frenquent Databricks-Certified-Data-Engineer-Associate Update 🪐 Go to website ➽ www.pdfvce.com 🢪 open and search for ▶ Databricks-Certified-Data-Engineer-Associate ◀ to download for free 🕛Databricks-Certified-Data-Engineer-Associate Practice Online
- 2026 Braindumps Databricks-Certified-Data-Engineer-Associate Pdf - Unparalleled Real Databricks Certified Data Engineer Associate Exam Dumps 🧺 Download ⇛ Databricks-Certified-Data-Engineer-Associate ⇚ for free by simply entering ▛ www.examcollectionpass.com ▟ website 🥕Databricks-Certified-Data-Engineer-Associate Valid Test Preparation
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, app.parler.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, findaspring.org, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
2026 Latest ExamCost Databricks-Certified-Data-Engineer-Associate PDF Dumps and Databricks-Certified-Data-Engineer-Associate Exam Engine Free Share: https://drive.google.com/open?id=1ydCFgnUngdLUhCSKGYT1-JO7xj7Rlzff