If you want to sharpen your skills, and get the Developing AI Cloud Solutions on Azure (AI-200) certification done within the target period, it is important to get the best Developing AI Cloud Solutions on Azure (AI-200) exam questions. You must try the Free4Dump Developing AI Cloud Solutions on Azure (AI-200) practice exam that will help you get the Microsoft AI-200 Certification. Free4Dump hires the top industry experts to draft the Developing AI Cloud Solutions on Azure (AI-200) exam dumps and help the candidates to clear their Developing AI Cloud Solutions on Azure (AI-200) exam easily. Free4Dump plays a vital role in their journey to get the AI-200 certification.
| Section | Objectives |
|---|---|
| Topic 1: Secure, monitor, troubleshoot Azure solutions | - Operate AI cloud solutions
|
| Topic 2: Connect to and consume Azure services | - Integrate Azure services
|
| Topic 3: Develop AI solutions by using Azure data management services | - Work with Azure data platforms for AI workloads
|
| Topic 4: Develop containerized solutions on Azure | - Implement containerized applications
|
>> AI-200 Reliable Test Vce <<
Once you ensure your grasp on the AI-200 Questions and answers, evaluate your learning solving the AI-200 practice tests provided by our testing engine. This innovative facility provides you a number of practice questions and answers and highlights the weak points in your learning. You can improve the weak areas before taking the actual test and thus brighten your chances of passing the exam with an excellent score. Moreover, doing these practice tests will impart you knowledge of the actual exam format and develop your command over it.
NEW QUESTION # 21
Case Study 2 - Proseware Inc.
Background
Proseware Inc. develops AI-powered knowledge management solutions for enterprise customers.
The company is modernizing its platform to support semantic search, intelligent document retrieval, and real-time partner integrations.
The engineering team uses Python and Azure SDKs. The architecture is being redesigned to support containerized microservices, vector search workloads, and serverless backend processing.
Planned Application Architecture
Microservices are containerized by using Docker.
Code for containerized microservices and Azure Function apps is developed locally but stored in a GitHub repository.
Custom images for containerized microservices are stored in Azure Container Registry (ACR).
Base images are stored in Docker Hub. Custom images must be rebuilt automatically whenever their base images are updated.
Azure Cosmos DB for NoSQL stores documents, metadata, and vector embeddings.
Azure Functions generate vector embeddings of Azure Cosmos DB for NoSQL-hosted documents and send messages to Service Bus to trigger search index updates.
Azure Container Apps (ACA) apps host backend API services that provide semantic search across Azure Cosmos DB for NoSQL documents. API services process Service Bus messages and update search indexes.
Azure Kubernetes Service (AKS) processes batch vector embedding regeneration for existing Azure Cosmos DB for NoSQL documents (whenever the embedding model is changed).
An extranet-facing containerized webhook allows business partners to submit documents to be processed by internal AI workflows for semantic search and retrieval.
Monitoring
Telemetry generated by Azure resources is sent to Azure Monitor.
A Log Analytics workspace is used to collect ACA apps logs, AKS container logs, and Azure Functions apps logs.
Monitoring of Azure Functions is currently implemented by using Azure Application Insights SDK instrumentation.
Business Requirements
Embeddings for new or updated Azure Cosmos DB for NoSQL-hosted documents must be automatically generated.
Backend API services must scale automatically during business hours.
Cold start delay of backend APIs must be minimized.
Secrets must be stored outside of container images.
Developers must be able to correlate telemetry across Azure Functions hosts and apps.
All tracing must be implemented by using OpenTelemetry SDK instrumentation.
Development efforts must be minimized.
Technical Requirements
Container images must be built automatically and validated before code updates are merged into the main branch.
Image build automation must run inside the Azure Container Registry, eliminating dependency on local developer machines and external build services.
Dependency of image builds on local developer machines must be eliminated.
Event-driven scaling in ACA must occur based on the number of pending messages in the Azure Service Bus queue.
Azure Cosmos DB for NoSQL RU consumption must be minimized.
Vector similarity search must use embeddings stored in Azure Cosmos DB for NoSQL.
The partner-facing containerized webhook service must run on Azure App Service.
Secrets must NOT be stored in container images, source control, or application configuration directly. They must be accessed securely at runtime.
All secrets must be stored centrally in Azure Key Vault and accessed at runtime through a managed identity.
Azure App Service must supply secrets at runtime without relying on external services.
Resources and workloads must be deployed by using Bicep templates through an automated, version-controlled pipeline. Local and command-line deployments must be eliminated to ensure repeatable, auditable deployments.
Known Issues
RU consumption spikes during vector similarity queries.
Drag and Drop Question
You need to configure event-driven scaling for the backend API services to meet the technical requirements.
Which settings should you use for each element? To answer, move the appropriate settings to the correct elements. You may use each setting once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.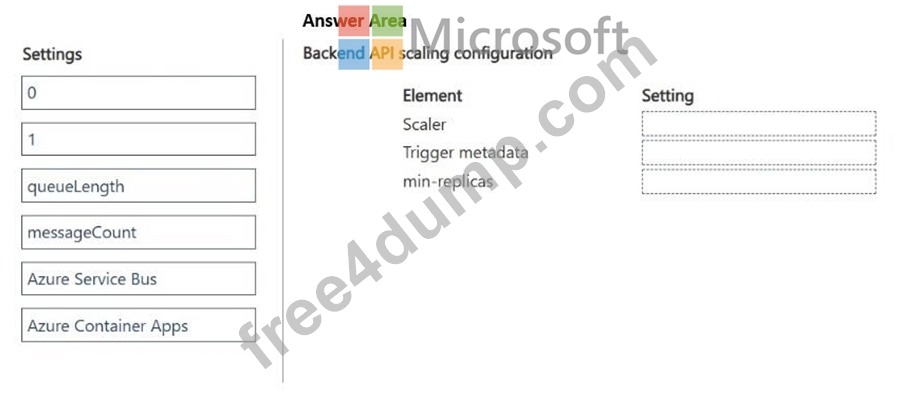
Answer:
Explanation: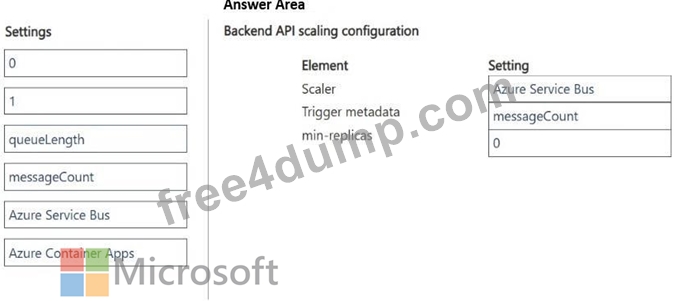
Explanation:
Scenario, technical requirements.
Event-driven scaling in ACA must occur based on the number of pending messages in the Azure Service Bus queue.
Box 1: Azure Service Bus
Scaler TypeType
Set the scale rule type to custom.
KEDA Scaler Name: Set the type inside the custom specification block to azure-service-bus.
Box 2: messageCount
Trigger Metadata Values
The metadata block dictates how KEDA calculates the required replica count.
Configure the following core metadata parameters:
queueName: The explicit string name of your targeted Azure Service Bus
*-> queue.messageCount: The target integer threshold of concurrent pending messages assigned per replica (e.g., 5 or 10). KEDA uses this value to scale out systematically.
activationMessageCount: Set to 1 or 0. This defines the exact metric floor required to transition the container app out of a dormant state.
namespace: The canonical name of your Service Bus namespace
Box 3: 0
Min-Replicas ConfigurationValue
Set --min-replicas to 0.
Setting this value to zero enables full serverless cost efficiency. KEDA actively handles the background polling, allowing your backend API containers to scale down completely and run zero active replicas when the Service Bus queue contains zero pending messages.
Reference:
https://oneuptime.com/blog/post/2026-02-16-how-to-set-up-keda-based-auto-scaling-with-queue-triggers-in-azure-container-apps/view
NEW QUESTION # 22
You process Azure Service Bus messages that require a dependent external API call.
If the API is temporarily unavailable, you must delay processing of the message without incrementing the delivery count. You need to find a way to process the message when the API is available while keeping the message accessible. Which message action should you perform?
Answer: B
Explanation:
Detailed Explanation: Deferral is intended for a message that cannot be processed now because a particular dependency is temporarily unavailable, while the application wants to keep the message in the main queue for later retrieval by sequence number. Complete would permanently remove it, dead-letter would move it aside as a failed message, and abandon immediately releases the lock for redelivery. Deferral therefore best matches the requirement to postpone the individual message while keeping it available for deliberate later processing.
Study Guide Alignment: Azure service integration: Service Bus, Event Grid, Azure Functions triggers
/bindings, and event-driven processing.
Official Microsoft Learn References: AI-200 Study Guide | Service Bus message deferral | Service Bus message transfers, locks, and settlement
NEW QUESTION # 23
You need to deploy Azure function resources and apps by using an automated, version-controlled CI/CD pipeline that supports declarative infrastructure deployment. What should you use?
Answer: C
NEW QUESTION # 24
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear on the review screen.
You are preparing a production deployment for an Azure Function app. The app will run across multiple environments.
The solution must support environment-specific configuration and prevent secrets from being stored in source control.
You need to develop the solution.
Solution: Store connection strings in the Function app application settings configured in the Azure Portal.
Does the solution meet the goal?
Answer: A
Explanation:
Correct:
* Use App Configuration with Key Vault references to store environment-specific settings and secrets, accessed from the function app by using a managed identity.
This is an industry-standard best practice architectural pattern.
Using Azure App Configuration combined with Azure Key Vault references completely satisfies your compliance requirements. It centralizes feature flags and non-sensitive configurations, keeps sensitive data safely out of source control, handles multi-environment deployments cleanly, and eliminates credentials via a passwordless Managed Identity.
Incorrect:
* Store connection strings in the Function app application settings configured in the Azure Portal.
* Store production secrets in environment variables set by the Dockerfile.
Reference:
https://learn.microsoft.com/en-us/azure/app-service/app-service-key-vault-references
NEW QUESTION # 25
An AI application uses a database. The database credential rotates every 30 days.
The application currently requires a manual update each time the credential rotates.
You need to ensure that the application always uses the latest secret version without manual updates.
Which two actions should you perform? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
Answer: A,C
Explanation:
Configure a Key Vault rotation policy to automate periodic credential generation and updates.
Retrieve secrets without a version identifier (versionless reference) so the app automatically resolves the newest active version.
Incorrect:
[Not B]
To stop manual updates, you should not retrieve secrets by specifying a version identifier, because locking in a version stops the application from seeing newer updates.
Reference:
https://learn.microsoft.com/en-us/azure/key-vault/secrets/secure-secrets
NEW QUESTION # 26
......
We believe that the best brands are those that go beyond expectations. They don't just do the job – they go deeper and become the fabric of our lives. Therefore, our company as the famous brand, even though we have been very successful we have never satisfied with the status quo, and always be willing to constantly update the contents of our AI-200 Exam Torrent in order to keeps latest information about AI-200 exam.
Printable AI-200 PDF: https://www.free4dump.com/AI-200-braindumps-torrent.html