I know that you are already determined to make a change, and our AI-200 exam materials will spare no effort to help you. After you purchase our AI-200 practice engine, I hope you can stick with it. We can promise that you really don't need to spend a long time and you can definitely pass the AI-200 Exam. As we have so many customers passed the AI-200 study questions, the pass rate is high as 98% to 100%. And this data is tested. With our AI-200 learning guide, you won't regret!
| Section | Objectives |
|---|---|
| Plan and manage Azure AI solutions | - Monitor and optimize AI solutions - Plan security and compliance requirements - Select appropriate Azure AI services |
| Implement and monitor AI workloads | - Deploy AI models and services - Monitor performance and troubleshoot issues |
| Implement Azure AI solutions | - Implement natural language processing solutions - Implement computer vision solutions - Implement generative AI solutions using Azure OpenAI - Implement knowledge mining with Azure AI Search |
In today's society, the number of college students has grown rapidly. Everyone has their own characteristics. How do you stand out? Obtaining AI-200 certification is a very good choice. Our AI-200 study materials can help you pass test faster. You can take advantage of the certification. Many people improve their ability to perform more efficiently in their daily work with the help of our AI-200 Exam Questions and you can be as good as they are.
NEW QUESTION # 137
You are building a semantic search feature for a chatbot. You store document embeddings in Redis.
You review the following Python code that connects to Redis and stores an embedding value: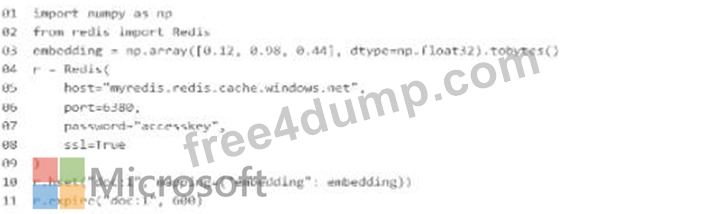
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.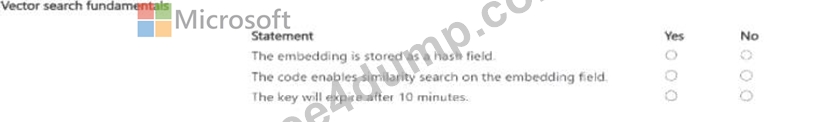
Answer:
Explanation: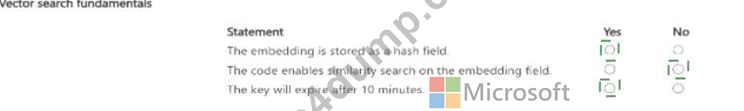
Explanation:
Verified Answer: Yes; No; Yes.
Detailed Explanation: `HSET` stores the binary embedding as a field in the Redis hash keyed by `doc:1`, so the first statement is true. The code does not create a RediSearch/Redis Query Engine vector index or define a vector field schema; merely storing bytes does not enable similarity search, so the second statement is false.
`EXPIRE doc:1 600` sets a 600-second lifetime, which is ten minutes, making the third statement true.
Study Guide Alignment: AI data-management workloads: Cosmos DB, PostgreSQL, caching, vector storage, vector retrieval, consistency, and connection optimization.
Official Microsoft Learn References: AI-200 Study Guide | Vector search in Azure Managed Redis
NEW QUESTION # 138
A company is implementing a publish-subscribe (Pub/Sub) messaging component by using Azure Service Bus. You are developing the first subscription application.
In the Azure portal you see that messages are being sent to the subscription for each topic. You create and initialize a subscription client object by supplying the correct details, but the subscription application is still not consuming the messages.
You need to ensure that the subscription client processes all messages.
Which code segment should you use?
Answer: C
Explanation:
Detailed Explanation: Creating a subscription client establishes the client object but does not start application-level message processing. The message handler must be registered so received subscription messages are delivered to the application callback. Adding a default TrueFilter is only necessary when subscription rules require adjustment and does not start the receiver; the default subscription rule already accepts messages in a normal subscription. Closing the client would stop processing rather than enable it.
Study Guide Alignment: Azure service integration: Service Bus, Event Grid, Azure Functions triggers
/bindings, and event-driven processing.
Official Microsoft Learn References: AI-200 Study Guide | Service Bus message transfers, locks, and settlement
NEW QUESTION # 139
You are designing a solution that will use two Azure Functions apps: App1 and App2. App1 is Windows based and will be deployed as code. App2 is Linux based and will be deployed as a container image.
Estimates show that the duration of the request processing for both apps will range from 1 to 10 minutes.
You plan to implement App1 and App2 by using the hosting plan to satisfy the following requirements:
* Request processing can complete within the estimated time range.
* The autoscaling behavior is event driven.
* The upper scaling limit is maximized.
You need to create the hosting plan for the implementation.
Which hosting plan should you create? To answer, move the appropriate hosting plans to the correct apps.
You may use each hosting plan once, more than once, or not at all. You may..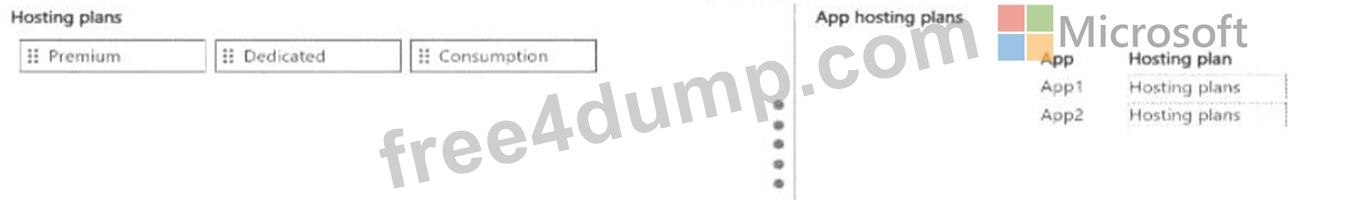
Answer:
Explanation: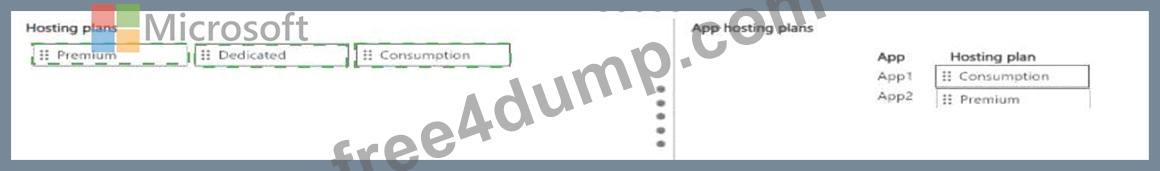
Explanation:
pp1: Consumption. App2: Premium.
Detailed Explanation: For App1, the Windows code-based Consumption plan satisfies event-driven autoscaling, allows execution up to the stated ten-minute range, and has the highest scaling ceiling among the listed event-driven choices for this workload. App2 is deployed as a Linux container image; among Premium, Dedicated, and Consumption, Premium is the event-driven plan that supports Linux containerized Functions and permits long-running execution. Dedicated hosting is not the requested event-driven autoscale model. The original Premium/Premium answer therefore did not maximize App1's upper scaling limit.
Study Guide Alignment: Azure service integration: Service Bus, Event Grid, Azure Functions triggers
/bindings, and event-driven processing.
Official Microsoft Learn References: AI-200 Study Guide | Azure Functions scale and hosting
NEW QUESTION # 140
Case Study 1 - Fabrikam Inc.
Background
Fabrikam Inc. is a global retail analytics company that provides AI-driven demand forecasting and product recommendation services to online retailers. The company is modernizing its solution to run entirely on Microsoft Azure.
The platform ingests transaction data, generates embeddings for semantic retrieval, performs vector similarity search, and returns product recommendations through containerized microservices. Developers use Python and Azure SDKs. Operations teams manage container orchestration, scaling, monitoring, and security.
The solution must meet strict performance, scalability, and security requirements.
Current environment
Application architecture
The Recommendation engine is a customer-facing HTTP API running as a containerized Python application. The engine is deployed to Azure Container Apps (ACA).
Embeddings are stored in Azure Database for PostgreSQL by using pgvector.
Semantic retrieval uses metadata filtering combined with vector similarity search.
Azure Managed Redis is used as a caching layer.
Front-end and API workloads are deployed to Azure Container Apps (ACA).
Batch model retraining workloads run in Azure Kubernetes Service (AKS).
Container and CI/CD
Container images are stored in Azure Container Registry (ACR).
CI/CD uses ACR Tasks to build images on commit.
ACA environments support revision management.
AKS workloads are deployed by using Kubernetes manifest files stored in Git.
Monitoring
Logs are collected in Azure Monitor.
Teams inspect container logs and Kubernetes events when troubleshooting.
Developers write KQL queries to analyze latency spikes.
Business requirements
Customer experience: Maintain a seamless, low-latency recommendation experience for end- users, even during unpredictable seasonal traffic spikes.
Operational cost efficiency: Minimize compute expenditures by deallocating resources during periods of inactivity and by preventing runaway scaling costs.
Data integrity and freshness: Ensure that product recommendations always reflect the most current catalog metadata and pricing to prevent customer dissatisfaction.
Security and compliance: Adhere to a Zero Trust security model by eliminating long-lived credentials and centralizing the management of all sensitive secrets.
Global scalability: Support the rapid ingestion of millions of new product embeddings daily without degrading query performance for existing retailers.
Technical requirements
Performance: Semantic search latency must remain under 200 milliseconds at peak load.
Database optimization: Use pgvector for embeddings and implement metadata filtering to reduce compute overhead. Configure compute and memory appropriately for vector workloads to ensure high-dimensional index residency in RAM and efficient mathematical throughput. Vector similarity calculations must be performed only against products that satisfy mandatory metadata constraints.
Database performance: Database connections must support high concurrency with minimal latency through the implementation of connection optimization.
Data load strategy: To ensure maximum ingestion throughput, secondary indexes must be applied only after bulk loading of embeddings is complete.
Caching: Redis cache entries must expire automatically after 10 minutes. Implement a reactive mechanism to invalidate cache entries upon metadata updates.
Identity: Use managed identities for all service-to-service and service-to-database authentication.
Plain-text credentials in configuration files are strictly prohibited.
Secret management: All secrets must be stored centrally. Secrets must be rotated automatically by using a centralized lifecycle policy.
Scaling: Use Kubernetes event-driven autoscaling (KEDA) for event-driven scaling. The Recommendation API must scale based on HTTP traffic, while batch jobs must scale based on queue length and support scale-to-zero.
CI/CD: All images must be stored in Azure Container Registry. Use ACR Tasks to automate image builds triggered by source code commits.
Monitoring: Use KQL to analyze performance telemetry and troubleshoot microservice connectivity failures. Inspect logs and events when troubleshooting AKS and ACA.
You need to improve throughput for concurrent application requests to PostgreSQL. What should you implement?
Answer: B
Explanation:
To improve throughput for highly concurrent application requests in this architecture, you should implement connection pooling.
PostgreSQL follows a process-based architecture where each client connection spawns a separate backend process. This consumes significant memory and CPU overhead during high concurrency. Connection pooling (using tools like PgBouncer or Azure's built-in pooler) allows containerized microservices to reuse a fixed set of database connections. This drastically reduces connection overhead, prevents database exhaustion, and maximizes throughput for short, rapid API queries like vector similarity searches.
Reference:
https://medium.com/@srajanpathak45/a-principal-engineers-guide-to-postgresql-and-modern-alternatives-e8920fd6269a
NEW QUESTION # 141
You need to secure an Azure OpenAI resource so that it is only reachable from your virtual network and not from the public internet. What should you configure?
Answer: C
NEW QUESTION # 142
......
Free4Dump is a leading platform that is committed to offering to make the Microsoft Exam Questions preparation simple, smart, and successful. To achieve this objective Free4Dump has got the services of experienced and qualified AI-200 Exam trainers. They work together and put all their efforts and ensure the top standard of Free4Dump Microsoft AI-200 exam dumps all the time.
AI-200 Prepaway Dumps: https://www.free4dump.com/AI-200-braindumps-torrent.html