NVIDIA AI Operations Exam Practice Dump Provide Best NCP-AIO Study Questions

DOWNLOAD the newest ExamPrepAway NCP-AIO PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1rXGjJDOHyk0vbCaSSI6lYri8otd4Xaxv
We provide our customers with the most reliable learning materials about NCP-AIO certification exam and the guarantee of pass. We assist you to prepare the key knowledge points of NCP-AIO actual test and obtain the up-to-dated exam answers. All NCP-AIO Test Questions offered by us are tested and selected by our senior experts in IT filed, which only need little time to focus on the practice and the preparation.
NVIDIA NCP-AIO Exam Overview:
| Certification Vendor: | NVIDIA |
|---|
| Exam Name: | NVIDIA-Certified Professional: AI Operations Exam |
|---|
| Exam Number: | NCP-AIO |
|---|
| Available Languages: | English |
|---|
| Exam Price: | $500 USD |
|---|
| Exam Format: | Hands-on lab exercises, Multiple choice, Scenario-based |
|---|
| Related Certifications: | NVIDIA-Certified Professional: AI Infrastructure (NCP-AII)
NVIDIA-Certified Associate: AI Infrastructure and Operations (NCA-AIIO)
NVIDIA-Certified Professional: AI Networking (NCP-AIN) |
|---|
| Exam Duration: | 120 minutes |
|---|
| Real Exam Qty: | 30–75 |
|---|
| Certificate Validity Period: | 2 years |
|---|
| Passing Score: | Pass/Fail (not officially disclosed) |
|---|
| Recommended Training: | NVIDIA AI Operations Training |
|---|
| Exam Registration: | Certiverse Exam Platform
NVIDIA Certification Portal |
|---|
| Sample Questions: | NVIDIA NCP-AIO Sample Questions |
|---|
| Exam Way: | Online remote proctored exam |
|---|
| Pre Condition: | Recommended: 2–3 years of experience managing AI infrastructure, GPU systems, or data center operations; familiarity with Kubernetes, containers, and NVIDIA software stack |
|---|
| Official Syllabus URL: | https://www.nvidia.com/en-us/learn/certification/ai-operations-professional/ |
|---|
>> Dumps NCP-AIO Questions <<
NCP-AIO Exam Consultant | Reliable NCP-AIO Exam Papers
The ExamPrepAway NCP-AIO exam practice test questions will provide you with everything that you need to learn, prepare and pass the NVIDIA AI Operations NCP-AIO exam. The ExamPrepAway NCP-AIO exam questions are the real PSE questions that will help you to understand the real NVIDIA AI Operations NCP-AIO Exam Pattern and answers and you can easily pass the final NVIDIA AI Operations NCP-AIO exam.
| Topic | Details |
|---|
| Topic 1 | - Administration: This section of the exam measures the skills of system administrators and covers essential tasks in managing AI workloads within data centers. Candidates are expected to understand fleet command, Slurm cluster management, and overall data center architecture specific to AI environments. It also includes knowledge of Base Command Manager (BCM), cluster provisioning, Run.ai administration, and configuration of Multi-Instance GPU (MIG) for both AI and high-performance computing applications.
|
| Topic 2 | - Workload Management: This section of the exam measures the skills of AI infrastructure engineers and focuses on managing workloads effectively in AI environments. It evaluates the ability to administer Kubernetes clusters, maintain workload efficiency, and apply system management tools to troubleshoot operational issues. Emphasis is placed on ensuring that workloads run smoothly across different environments in alignment with NVIDIA technologies.
|
| Topic 3 | - Troubleshooting and Optimization: NVIThis section of the exam measures the skills of AI infrastructure engineers and focuses on diagnosing and resolving technical issues that arise in advanced AI systems. Topics include troubleshooting Docker, the Fabric Manager service for NVIDIA NVlink and NVSwitch systems, Base Command Manager, and Magnum IO components. Candidates must also demonstrate the ability to identify and solve storage performance issues, ensuring optimized performance across AI workloads.
|
| Topic 4 | - Installation and Deployment: This section of the exam measures the skills of system administrators and addresses core practices for installing and deploying infrastructure. Candidates are tested on installing and configuring Base Command Manager, initializing Kubernetes on NVIDIA hosts, and deploying containers from NVIDIA NGC as well as cloud VMI containers. The section also covers understanding storage requirements in AI data centers and deploying DOCA services on DPU Arm processors, ensuring robust setup of AI-driven environments.
|
NVIDIA AI Operations Sample Questions (Q61-Q66):
NEW QUESTION # 61
A system administrator is troubleshooting a Docker container that is repeatedly failing to start.
They want to gather more detailed information about the issue by generating debugging logs.
Why would generating debugging logs be an important step in resolving this issue?
- A. Debugging logs fix issues related to container performance and resource allocation.
- B. Debugging logs provide detailed insights into the Docker daemon's internal operations.
- C. Debugging logs disable other logging mechanisms, reducing noise in the output.
- D. Debugging logs prevent the container from being removed after it stops, allowing for easier inspection.
Answer: B
Explanation:
Generating debugging logs enables detailed visibility into the internal operations of the Docker daemon. These logs expose low-level errors, misconfigurations, and runtime issues that standard logs might not capture, making them essential for diagnosing why a container repeatedly fails to start.
NEW QUESTION # 62
Consider the following BCM configuration snippet (simplified). What potential issue might this snippet cause, and how would you address it?
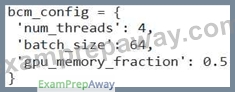
- A. The 'batch_size' is too large, causing CUDA out-of-memory errors. Decrease it to a smaller value.
- B. There is no immediate issue. This configuration appears reasonable without knowing the specific hardware or workload.
- C. B and C.
- D. The num_threads' value is too low, leading to CPU underutilization. Increase it to match the number of CPU cores.
- E. The gpu_memory_fraction' is too high, potentially leaving insufficient memory for other applications. Reduce it if other GPU processes are running.
Answer: C
Explanation:
Without further information on the use case, batch size and GPU fraction are potentially too high and might need to be decreased.
NEW QUESTION # 63
You are deploying a stateful application to your Kubernetes cluster running on NVIDIA hardware provisioned through BCM. This application requires direct access to a persistent volume on a high-performance NVMe drive. Which of the following methods is MOST appropriate for providing this access while ensuring high performance and data consistency?
- A. Using a 'hostPatW volume, directly mapping the NVMe drive's path on the host node to the container.
- B. Using a Network File System (NFS) share mounted on the host and exposed to the container via a PersistentVolume.
- C. Configuring a standard Persistent Volume Claim backed by a software-defined storage solution like Ceph or Rook.
- D. Creating a PersistentVolumeClaim (PVC) backed by a cloud-based block storage service (e.g., AWS EBS, Azure Disk).
- E. Leveraging a local Persistent Volume with 'volumeBindingMode: WaitForFirstConsumer' and node affinity to ensure the pod is scheduled on the node with the NVMe drive.
Answer: E
Explanation:
Local Persistent Volumes with 'WaitForFirstConsumer' and node affinity are designed for scenarios requiring direct access to local storage like NVMe drives. This approach provides the best performance and data consistency compared to network-based solutions like NFS or cloud-based block storage, or shared storage solutions such as Ceph. 'hostPath' is discouraged for production use because it bypasses Kubernetes volume management. Local PV ensures the PVC is bound to PV at time of first use rather than during cluster set up.
NEW QUESTION # 64
You're implementing a preemption policy in your Slurm cluster to allow higher-priority jobs to interrupt lower-priority jobs. Which Slurm configuration parameters are MOST relevant to configure preemption? (Select TWO)
- A. PreemptMode
- B. FastSchedule
- C. SchedulerRootFilter
- D. PreemptType
- E. AccountingStorageType
Answer: A,D
Explanation:
'PreemptMode' defines when preemption is triggered (e.g., 'OFF', 'CANCEL', 'REQUEUE'). 'preemptType' determines which jobs are eligible for preemption (e.g., 'priority', 'qos').
NEW QUESTION # 65
You're tasked with configuring Slurm to prioritize jobs submitted by a specific research group. Which Slurm feature provides the MOST direct way to implement this prioritization?
- A. Setting a higher 'nice' value for jobs submitted by other groups.
- B. Configuring Slurm's Fairshare scheduling with appropriate shares assigned to the research group.
- C. Using the 'sinfo' command to manually reorder pending jobs.
- D. Manually editing the Slurm job queue database.
- E. Disabling preemption.
Answer: A
Explanation:
Fairshare scheduling allows you to allocate resources based on a share value assigned to each user or group. By assigning a higher share value to the research group, their jobs will be prioritized for resource allocation.
NEW QUESTION # 66
......
NCP-AIO Exam Consultant: https://www.examprepaway.com/NVIDIA/braindumps.NCP-AIO.ete.file.html
- NCP-AIO Passguide 🔈 NCP-AIO Valid Exam Format 🎋 Study NCP-AIO Reference 😉 Go to website ▶ www.troytecdumps.com ◀ open and search for [ NCP-AIO ] to download for free 🖌Vce NCP-AIO Download
- NCP-AIO Excellect Pass Rate 🛬 Valid NCP-AIO Exam Bootcamp 👇 NCP-AIO Latest Study Plan ❗ Open ☀ www.pdfvce.com ️☀️ enter ➡ NCP-AIO ️⬅️ and obtain a free download 🚚New NCP-AIO Test Question
- NCP-AIO Excellect Pass Rate 🎨 Valid NCP-AIO Exam Bootcamp ⬇ Current NCP-AIO Exam Content 💘 Open website ➤ www.vceengine.com ⮘ and search for ▛ NCP-AIO ▟ for free download 🏨Accurate NCP-AIO Answers
- Dumps NCP-AIO Questions 🔟 NCP-AIO Test Questions Vce 🌰 Dumps NCP-AIO Questions 🤤 Easily obtain free download of ▶ NCP-AIO ◀ by searching on ⇛ www.pdfvce.com ⇚ 👤Current NCP-AIO Exam Content
- Exam NCP-AIO Score 😗 Reliable NCP-AIO Exam Guide 🧱 Trustworthy NCP-AIO Dumps 🎫 Simply search for ⮆ NCP-AIO ⮄ for free download on ➤ www.practicevce.com ⮘ 🤢Sample NCP-AIO Questions Pdf
- NCP-AIO Vce Test Simulator 🎾 Vce NCP-AIO Download 🌼 Trustworthy NCP-AIO Dumps ✳ Search for ☀ NCP-AIO ️☀️ and download it for free on { www.pdfvce.com } website 🍽Trustworthy NCP-AIO Dumps
- 2026 NCP-AIO: Authoritative Dumps NVIDIA AI Operations Questions 🦝 The page for free download of ➡ NCP-AIO ️⬅️ on [ www.prepawayexam.com ] will open immediately 🏞Reliable NCP-AIO Exam Guide
- 2026 NCP-AIO: Authoritative Dumps NVIDIA AI Operations Questions 🧞 Open ( www.pdfvce.com ) enter ▶ NCP-AIO ◀ and obtain a free download 🏗Dumps NCP-AIO Questions
- Try Free NVIDIA NCP-AIO Questions Demo Before Buy 🤢 ▷ www.prep4sures.top ◁ is best website to obtain ▷ NCP-AIO ◁ for free download 🩳Valid NCP-AIO Test Voucher
- NCP-AIO Vce Test Simulator 🚧 NCP-AIO Reliable Mock Test 👛 Vce NCP-AIO Download 😡 Search for ▶ NCP-AIO ◀ and download it for free on 「 www.pdfvce.com 」 website 🎲NCP-AIO Excellect Pass Rate
- NCP-AIO Vce Test Simulator 🎅 Trustworthy NCP-AIO Dumps 💜 New NCP-AIO Test Question 🏋 Download ☀ NCP-AIO ️☀️ for free by simply entering { www.testkingpass.com } website 🧡Trustworthy NCP-AIO Dumps
- www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.wonderlink.de, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, Disposable vapes
2026 Latest ExamPrepAway NCP-AIO PDF Dumps and NCP-AIO Exam Engine Free Share: https://drive.google.com/open?id=1rXGjJDOHyk0vbCaSSI6lYri8otd4Xaxv