What's more, part of that PracticeVCE SPS-C01 dumps now are free: https://drive.google.com/open?id=1dHFgNmiD_vp0faCuCuAi3ERt9stv5NNI
We have 24/7 Service Online Support services, and provide professional staff Remote Assistance. Besides, if you need an invoice of our SPS-C01 practice materials please specify the invoice information and send us an email. And you can download the trial of our SPS-C01 training engine for free before your purchase. This kind of service shows our self-confidence and actual strength about SPS-C01 Study Materials in our company. Besides, our company's website purchase process holds security guarantee, so you needn’t be anxious about download and install our SPS-C01 exam questions.
| Section | Weight | Objectives |
|---|---|---|
| Data Transformations and Operations | 35% | - User-defined logic
|
| Snowpark API and Development | 30% | - Python API fundamentals
|
| Performance and Best Practices | 10% | - Optimization techniques
|
| Snowpark Concepts and Architecture | 25% | - Snowpark architecture and execution model
|
>> Exam SPS-C01 Questions Fee <<
If I tell you, you can get international certification by using SPS-C01 preparation materials for twenty to thirty hours. You must be very surprised. However, you must believe that this is true! You can ask anyone who has used SPS-C01 Actual Exam. We can receive numerous warm feedbacks every day. Our reputation is really good. After you have learned about the achievements of SPS-C01 study questions, you will definitely choose us!
NEW QUESTION # 207
You have a Snowpark Python stored procedure 'process_data' that takes a Snowpark DataFrame as input, performs several data transformations using functions defined in a separate Python module 'data utils.py', and returns a transformed DataFrame. The 'data utils.py' file is located in your local directory. You want to register this stored procedure so that it can be called from Snowflake. Which of the following code snippets demonstrate(s) the correct way to register the stored procedure, ensuring that the 'data utils.py' module is available within the Snowpark environment? (Select TWO)





Answer: B,E
Explanation:
Option C correctly specifies the 'data_utils.py' file in the 'imports' parameter of the gsproc' decorator, making it available within the Snowpark environment. It also includes re-importing the 'data_utilS package within the function. Option D specifies the file in the 'imports parameter and uses the '_import_' function to load and use the module, which is a valid approach. Option A would error at runtime because "data_utils' won't be found unless it is in the same file as the stored procedure definition or the user has installed the python packages. Option B contains incorrect usage of 'return_type', and and doesn't account for importing 'data_utils.pV. Option E has the same problem as A as the dependent file 'data_utils.py' has not been imported. The 'stage_location' parameter specifies the stage where the Python file should be uploaded. The two correct ways ensure that the data_utils module will be loaded and accessible in the Snowpark environment.
NEW QUESTION # 208
You are developing a Snowpark Python application that needs to process large datasets. You want to optimize performance by leveraging user-defined functions (UDFs) to perform complex calculations in parallel across the Snowflake data warehouse. Which of the following statements regarding Snowpark UDFs are TRUE?
Answer: B,D
Explanation:
Snowpark UDFs can be either scalar or vectorized, offering different performance tradeoffs. Vectorized UDFs are generally more efficient for large datasets as they process batches of rows. Snowpark UDFs do distribute the data and computation across multiple nodes automatically; however, the distribution strategy, while not directly controlled, is influenced by how the UDF is applied to the data and the inherent distribution of the underlying data itself. Python is the primary UDF language. Option A is false because UDFs are designed for parallel processing. Option C is not always true; custom channels might be necessary for specific dependencies. Option E is partially correct in the older releases but Python is used primarily now.
NEW QUESTION # 209
You have a complex data pipeline implemented using Snowpark Tasks in a Directed Acyclic Graph (DAG). One of the tasks, , depends on the successful completion of two parent tasks, and 'task B'. You need to implement error handling such that if 'task_R fails, 'task_C' should not be executed, but should still complete its execution regardless of status. If 'task B' fails, 'task_C' should not be executed. How do you configure the task dependencies and error handling in Snowflake to achieve this behavior?





Answer: C
Explanation:
Setting to execute 'AFTER task_A, task_B' establishes the dependency. Configuring on both 'task_R and 'task_B' ensures that if either task fails, it will suspend itself and prevent 'task_C' from running. This achieves the required behavior. Option A is incorrect because setting the parameter on 'task_C' will not prevent the execution of 'task_C' if either 'task_R or failed, but only suspend it after it tries to execute and fails. Option B is not correct because Snowflake's default behavior does not inherently skip 'task_C' unless specifically configured through dependencies. Option C is overly complex and doesn't accurately reflect intended behaviour.Option E is overly complex and doesn't accurately reflect intended behaviour. Option D will ensure only if both 'task_A' and runs successfully then runs else it will suspend the further execution.
NEW QUESTION # 210
You have a Snowpark DataFrame with columns 'order_id', 'product_id', 'sale_date' (DATE), and 'sale_amount'. You need to perform the following transformations: 1. Filter out sales records before January 1, 2023.2. Group the data by 'product_id' and calculate the total 'sale_amount' for each product. 3. Create a new column 'average_sale_amount' by dividing the total 'sale_amount' by the number of distinct 'order_id' for each product. You must alias the aggregate function. Which of the following Snowpark code snippets correctly implements these transformations?





Answer: B
Explanation:
Option E is the most appropriate and correct. It uses for explicit date conversion, ensures correct filtering, aggregates with aliases, and calculates the 'average_sale_amount' correctly using the aliased columns. Options A, B, C and D are all valid for Snowflake. Option B incorrectly passes the date string. 'as_' instead of 'alias' are not valid and will cause an issue.
NEW QUESTION # 211
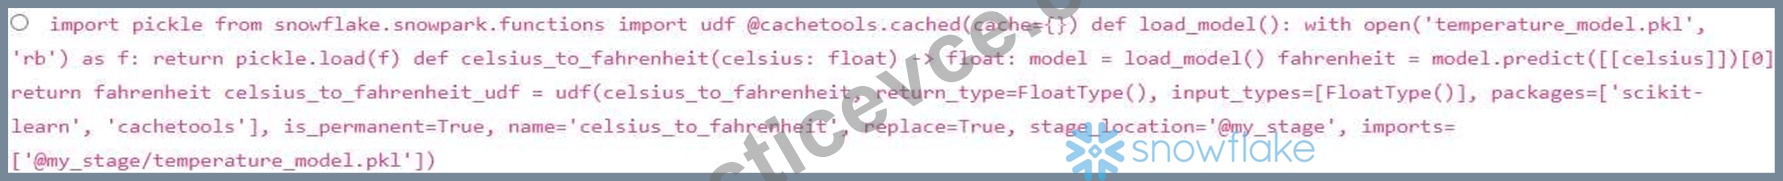
You are developing a Snowpark application to process sensor data'. You need to define a UDF that converts temperature readings from Celsius to Fahrenheit. However, the conversion formula is computationally intensive and requires access to a pre-trained machine learning model stored as a resource in a stage. Given the following considerations, what is the most efficient and correct way to define this UDF? The model file is named 'temperature_model.pkl'.



Answer: C
Explanation:
Option C is the most efficient and correct way. It correctly uses the 'imports' parameter in the @sf.UDF decorator to specify the location of the model file in the stage. This ensures that the model file is available to the UDF at runtime. Options A and B attempts to open the file without properly importing, and would fail. Option D includes caching, which is good for frequently called functions with the same input, but the primary issue lies in correctly importing the model from the stage. Using caching is also possible, but it is not required. Option C is the most direct and correct approach to fulfilling the prompt's requirements. The other options will result in errors or are less efficient.
NEW QUESTION # 212
......
We provide Snowflake SPS-C01 web-based self-assessment practice software that will help you to prepare for the Snowflake certification exam. Snowflake SPS-C01 Web-based software offers computer-based assessment solutions to help you automate the entire Snowflake Certified SnowPro Specialty - Snowpark testing procedure. The stylish and user-friendly interface works with all browsers, including Mozilla Firefox, Google Chrome, Opera, Safari, and Internet Explorer. It will make your certification exam preparation simple, quick, and smart. So, rest certain that you will discover all you need to study for and pass the Snowflake SPS-C01 Exam on the first try.
SPS-C01 Dumps Free: https://www.practicevce.com/Snowflake/SPS-C01-practice-exam-dumps.html
What's more, part of that PracticeVCE SPS-C01 dumps now are free: https://drive.google.com/open?id=1dHFgNmiD_vp0faCuCuAi3ERt9stv5NNI