Es ist unnötig für Sie, zu viel Zeit eine Prüfung vorzubereiten. Kaufen Sie bitte Microsoft AI-103 Dumps von ZertFragen. Mit diesen Dumps können Sie wissen, wie Microsoft AI-103 Prüfung hocheffektiv vorzubereiten. Das ist ein seltenes Gerät, das Ihnen helfen, sehr einfach die Microsoft AI-103 Prüfung zu bestehen. Sie werden bereuen, dass Sie diese Chance verlieren. So handeln Sie bitte schnell damit.
| Section | Objectives |
|---|---|
| Plan and Manage Azure AI Solutions | - Model selection and lifecycle management - Azure AI resource provisioning and configuration - Responsible AI principles and governance |
| Develop Generative AI Applications and Agents | - AI agents architecture
|
| Implement Natural Language Processing Solutions | - Translation and multilingual support - Text analytics and summarization - Language understanding and intent recognition |
| Implement Computer Vision Solutions | - Image classification and object detection - OCR and document intelligence |
| Knowledge Mining and Information Retrieval | - RAG (Retrieval Augmented Generation) patterns - Indexing and semantic search - Azure AI Search configuration |
>> Microsoft AI-103 Kostenlos Downloden <<
Über die Prüfungsfragen und Antworten zur Microsoft AI-103 Zertifizierung hat ZertFragen eine gute Qualität. ZertFragen wird die zuverlässigsten Informationsressourcen sein. Durch die Feedbacks und tiefintensive Analyse sind wir in einer Stelle. Wir müssen darüber entscheiden, welche Anbieter Ihnen die neuesten Übungen von guter Qualität zur Microsoft AI-103 Zertifizierungsprüfung bieten und aktualisieren zu können. Unsere Schulungsunterlagen zur Microsoft AI-103 Zertifizierungsprüfung werden ständig bearbeitet und modifiziert. Wir haben die umfassendesten Ausbildungserfahrugnen. Wenn Sie Zertifikate erhalten wollen, benutzen Sie doch unsere Schulungsunterlagen zur Microsoft AI-103 Zertifizierungsprüfung. Schicken ZertFragen doch schnell in Ihren Warenkorb. Unzählige Überraschungen warten schon auf Sie.
101. Frage
Note: This section contains one or more sets of questions with the same scenario and problem. Each question presents a unique solution to the problem. You must determine whether the solution meets the stated goals. More than one solution in the set might solve the problem. It is also possible that none of the solutions in the set solve the problem.
After you answer a question in this section, you will NOT be able to return. As a result, these questions do not appear on the Review Screen.
You have a multimodal Al generative model that accepts image uploads and uses extracted image text to generate responses.
You discover that users can upload unsafe images and embed hidden instructions into images to manipulate the model.
You need to implement controls to mitigate the risk.
Solution: You configure protected material detection.
Does this meet the goal?
Antwort: B
Begründung:
The solution does not meet the goal. Protected material detection is intended to identify large language model output that matches known protected text or code, such as copyrighted text, selected web content, song lyrics, articles, recipes, or code. Microsoft describes protected material detection as a control for preventing AI- generated content from reproducing known protected material, not as a control for image safety or prompt injection.
The stated risk has two parts: users can upload unsafe images, and users can embed hidden instructions in images to manipulate the model. Unsafe image uploads require image moderation, because Azure AI Content Safety provides image APIs that detect harmful content across modalities and can support blocking decisions by harm category and severity. Hidden instructions extracted from images are indirect prompt injection or document attacks; Microsoft Prompt Shields are the capability designed to detect user prompt attacks and document attacks, including harmful instructions embedded in third-party content.
Therefore, protected material detection alone does not mitigate either primary risk. Reference topics: Azure AI Content Safety, image moderation, Prompt Shields, document attacks, indirect prompt injection, and protected material detection.
Topic 1, Case Study Contoso, Ltd
Overview
Contoso, Ltd is a multinational retail company that builds, deploys, and manages generative Al and agent- based solutions by using Microsoft Foundry.
Identity Environment:
Contoso uses Microsoft Entra ID for identity management, authentication, and authorization capabilities that enable agents to access organizational resources and services.
Contoso recently formed a new Al engineering team named Agent1Dev Team to optimize and maintain existing Al solutions.
The team collaborates with solution architects, DevOps engineers, and security engineers to design, implement, monitor, and secure Al applications.
Contoso also has a team named Agent1Test Team that is responsible for validating Al solutions before the solution deployments.
Generative Environment:
Contoso has a Microsoft Foundry deployment that contains two projects named Project1 and Project2.
Project1
Project1 contains a customer support agent named Agent1 that assists customers with product inquiries and troubleshooting requests.
Agent1 has the following configurations:
* Agent1 uses a base model deployment.
* A safety evaluation pipeline is NOT enabled.
* Tool invocation approval workflows are NOT enabled.
* Conversation memory constraints are NOT configured.
Agent1 interacts with customers by using digital support channels and answers general questions about Contoso products.
Project1 is deployed to an Azure region located in the European Union (EU).
Agent1Dev Team will use Project1 to optimize and maintain Agent1.
Project2
Project2 contains a deployed video generation model. The marketing department at Contoso has access to Project2 and plans to use the model to develop a video creation solution.
Development of the solution is incomplete.
Data Environment:
Contoso stores product-related information in Azure resources that support Al applications.
The Azure environment contains an Azure Blob Storage account named storage1 that stores product detail sheets for all the Contoso products.
The product sheets include specifications, feature descriptions, and product support information that Agent1 can use to answer customer questions. The product sheets are stored in the PDF format.
Problem Statement:
Contoso identifies the following issues:
* Agent1 has only general knowledge of the Contoso products.
* A recent chat interaction with Agent1 was analyzed for sentiment. The results of the analysis have NOT been processed yet.
* Agent1 does NOT use the detailed product information in the product sheets stored in storage1 when responding to customer questions.
* The finance department at Contoso reports that vendor invoices must be reviewed manually to ensure that the invoices match the terms defined in the vendor contracts. The invoices contain tables, logos, and varied layouts that make the documents difficult to process consistently.
Requirement:
Planned Changes:
Contoso plans to implement the following changes:
* Implement a solution for Project1 that analyzes the vendor invoices by evaluating both the visual layout and the textual content of the invoices, so that the invoice details can be verified against the vendor contract terms.
* Update the base model deployment used by Agent1 and standardize the model version to ensure continuity and consistent responses.
* Enable Agent1 to retrieve and use the detailed product information from the product sheets stored in storage1.
* Implement an indexing solution for the product sheets that Agent1 can use to answer customer questions.
* Complete the development of the video creation solution.
Technical Requirements:
Contoso identifies the following technical requirements:
* The model deployment used by Agent1 must support scalable, high-throughput generative Al workloads and dynamically scale to handle variable customer support traffic, without requiring reserved throughput capacity.
* The product sheets must be processed by using an indexing pipeline that enables semantic and vector search, so that Agent1 can retrieve the relevant product information.
* Responses generated by using the product sheet information must be relevant, complete, and accurate.
* Agent1 must be able to use the product sheets to answer natural language questions about product details.
* The model version used by Agent1 must remain consistent to ensure stable responses.
* The data processed by the model must remain within the EU.
Safety and Compliance Requirements:
Contoso identifies the following security and compliance requirements:
* API keys must NOT be used to access Foundry-deployed models.
* Access to the Azure resources must follow the principle of least privilege.
* The developers at Contoso must authenticate to Microsoft Foundry resources by using Microsoft Entra authentication.
* Access to Project1 must be assigned to the members of Agent1Dev Team by using a security group named SC_Agent1_Dev.
* Access to Project1 must be assigned to the members of Agent1Test Team by using a security group named SC_Agent1_Test.
* Agent1 must never reveal customer information, even if a document that contains customer data is added erroneously to the product sheet repository in storage1.
* The product sheets might contain images that include embedded text. Agent1 must be protected from malicious instructions potentially hidden within the images.
Business Information:
Contoso identifies the following business requirements:
* Users that interact with Agent1 must have a personalized experience in future interactions, including the ability for Agent1 to retain conversation context and recall relevant information from previous interactions.
* Agent1 must answer questions only about the products sold by Contoso.
102. Frage
You need to configure the model deployment for Agent1 to meet the technical requirements.
What should you configure? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.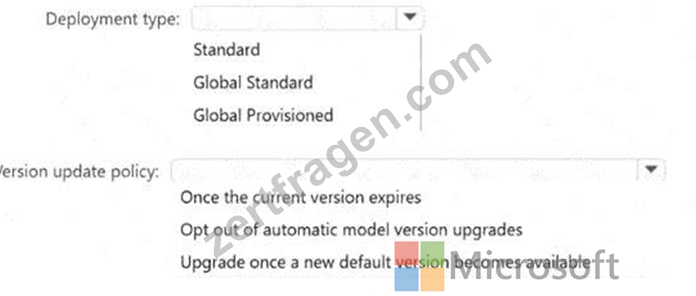
Antwort:
Begründung: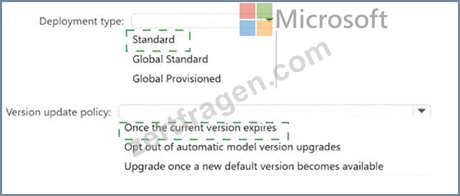
Explanation:
Deployment type: Standard
Version update policy: Once the current version expires
The correct deployment type is Standard . The case study specifies that Project1 is deployed in an EU Azure region and that model-processed data must remain within the EU. It also requires scalable, high-throughput generative AI workloads that dynamically handle variable customer support traffic without reserved throughput capacity. In Microsoft Foundry Models, Standard is a pay-per-token deployment type that processes data in a single Azure region, while Global Standard can process requests across regions and Global Provisioned uses reserved provisioned throughput. Microsoft's deployment-type guidance identifies Standard as single-region, pay-per-token, whereas Global Provisioned is cross-region with reserved capacity.
The correct version update policy is Once the current version expires . This keeps Agent1 on the selected model version during its supported lifecycle, which supports stable and consistent responses, but still preserves continuity by automatically moving to a supported replacement when the current version is retired.
Microsoft's model versioning guidance states that this policy updates only when the current model version expires, while upgrading when a new default is available changes the deployment sooner and opting out can cause the deployment to stop working after retirement. Reference topics: deployment types, regional data processing, model versioning, throughput capacity, and stable production deployments.
103. Frage
You have a Microsoft Foundry project. You need to deploy a model from the model catalog to support real- time inference. The solution must meet the following requirements:
* Use key-based authentication
* Support real-time REST API access
* Not consume the vCPU quota of the virtual machines in the Azure subscription Which type of deployment should you use?
Antwort: C
Begründung:
A serverless API deployment exposes a model from the Microsoft Foundry model catalog as a managed inference endpoint without hosting the model on virtual-machine compute in the customer's subscription.
Consequently, it does not consume the subscription's VM-family vCPU quota. Capacity is managed by the service and controlled through deployment-level token and request rate limits rather than customer-managed compute instances.
The generated serverless endpoint uses key authentication. Foundry provides a target URI and associated primary or secondary credentials that the application uses to authorize inference requests. Serverless deployments support the Azure AI Model Inference API, enabling real-time application access through a consistent API interface suitable for REST-based prediction requests.
A self-hosted container requires customer-managed infrastructure and therefore consumes the compute capacity on which it runs. A compute-backed standard deployment generally requires provisioned hosting resources and applicable quota. A batch deployment is designed for asynchronous, high-volume processing rather than interactive real-time inference.
The serverless option therefore satisfies all three requirements simultaneously: key-based authorization, online API inference, and no dependency on the subscription's virtual-machine vCPU quota.
Study Guide alignment: Planning and managing Azure AI solutions - select model deployment options, deploy catalog models, configure endpoint authentication, and evaluate compute and quota requirements.
104. Frage
You have a customer support agent built by using the Microsoft Foundry Agent Service. The agent calls an Azure OpenAI model deployment.
During load testing, calls intermittently fail and return an HTTP 429 rate limit exceeded error.
You need to handle throttling to reduce call failures and improve reliability under load. The solution must remain within the service and model limits.
What should you do?
Antwort: D
Begründung:
To handle HTTP 429 throttling and improve load testing reliability for your Microsoft Foundry Agent Service, implement exponential backoff with jitter on the client side, deploy a load- balancing gateway across multiple Azure OpenAI regions, or upgrade your deployment to Provisioned Throughput Units (PTU).
*-> 1. Implement Client-Side Retry LogicConfigure your agent's HTTP client or SDK to handle
429 errors gracefully rather than failing immediately.
Exponential Backoff: Increase the wait time between subsequent retry attempts exponentially .
Jitter: Add a small amount of random delay (jitter) to the backoff time to prevent a "thundering herd" effect where all throttled requests retry simultaneously.
Header Inspection: Programmatically read the Retry-After or x-ratelimit-reset values from the HTTP 429 response headers to pause execution for the exact duration requested by Azure.
2. Set Up Multi-Region Load Balancing
3. Switch to Provisioned Throughput (PTU)
4. Optimize Token Consumption
Reference:
https://learn.microsoft.com/en-us/answers/questions/1518859/help-with-resolving-ptu-m-service-429-error
105. Frage
You have a Microsoft Foundry project that contains two agents named PolicyWriter and RiskReviewer.
PolicyWriter generates draft updates for customer policies, and RiskReviewer reviews the drafts. In the visual builder, you need to create a workflow that meets the following requirements:
* Finalizes low-risk updates without manual intervention
* Ensures predictable execution across the agents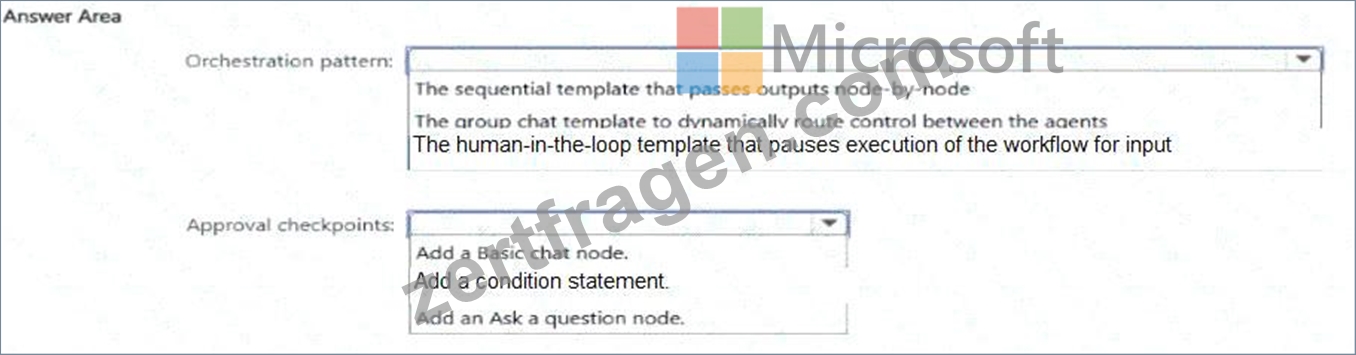
Antwort:
Begründung: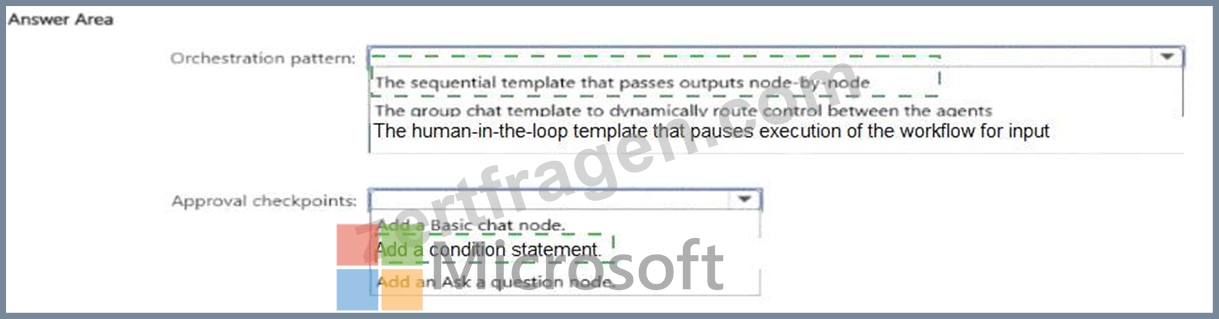
Explanation:
* Orchestration pattern: The sequential template that passes outputs node-by-node
* Approval checkpoints: Add a condition statement
Use the sequential orchestration template because the agents must execute in a fixed, predictable order.
PolicyWriter first generates the proposed policy update, and its output is then passed directly to RiskReviewer. Microsoft defines the sequential pattern as passing the result from one agent to the next in a defined order, making it appropriate for deterministic, multistage processing. The group-chat pattern would allow control to move dynamically between agents, which would reduce execution predictability.
After RiskReviewer returns a structured risk classification, add a condition statement that evaluates the result. The low-risk branch can proceed directly to the finalization action without requesting human input. A separate higher-risk branch can route to an approval step, such as an Ask a question node. Adding an Ask a question node without conditional branching would pause every workflow execution, including low-risk updates, and therefore would not satisfy the automation requirement. Microsoft Foundry workflows support if
/else branching and condition expressions for selecting the next action.
Study Guide alignment: implement orchestrated multi-agent solutions and build autonomous or semiautonomous workflows with safeguards and approval-flow controls .
106. Frage
......
Microsoft AI-103 dumps von ZertFragen sind die unentbehrliche Prüfungsunterlagen, mit denen Sie sich auf Microsoft AI-103 Zertifizierung vorbereiten. Der Wert dieser Unterlagen ist gleich wie die anderen Nachschlagsbücher. Diese Meinung ist nicht übertrieben. Wenn Sie diese Schulungsunterlagen zur Microsoft AI-103 Zertifizierung benutzen, finden Sie es wirklich.
AI-103 Online Praxisprüfung: https://www.zertfragen.com/AI-103_prufung.html