さらに、It-Passports DP-700ダンプの一部が現在無料で提供されています:https://drive.google.com/open?id=1RBk7iHpUjJ9imwsjdtYNwKlHPjj7VIBk
近年、市場は資格試験のDP-700学習製品の急増に悩まされているため、多くの類似製品でDP-700テスト問題を見つけて選択することは非常に困難です。ただし、当社のDP-700学習資料の優れた品質と評判により、多くの製品でユーザーが当社を選択できるようになると考えています。当社の学習資料では、ユーザーがDP-700認定ガイドを無料で使用して、ユーザーが製品をよりよく理解できるようにしています。
| トピック | 出題範囲 |
|---|---|
| トピック 1 |
|
| トピック 2 |
|
| トピック 3 |
|
ただ一つの試験の準備をするだけで時間をたくさん無駄にすることをやめてください。はやくIt-PassportsのDP-700問題集を入手しましょう。この問題集を持っていたら、どうやって効率的に試験の準備をすべきなのかをよく知るようになります。このDP-700問題集はあなたを楽に試験に合格させる素晴らしいツールですから、この成功できチャンスを見逃せば絶対後悔になりますから、尻込みしないで急いで行動しましょう。
質問 # 138
You need to ensure that processes for the bronze and silver layers run in isolation How should you configure the Apache Spark settings?
正解:A
質問 # 139
You have a Fabric workspace that contains a lakehouse named Lakehousel. Lakehousel contains a table named Status_Target that has the following columns:
* Key
* Status
* LastModified
The data source contains a table named Status.Source that has the same columns as Status_Target. Status.Source is used to populate Status_Target. In a notebook name Notebook!, you load Status_Source to a DataFrame named sourceDF and Status_Target to a DataFrame named targetDF. You need to implement an incremental loading pattern by using Notebook-!. The solution must meet the following requirements:
* For all the matching records that have the same value of key, update the value of LastModified in Status_Target to the value of LastModified in Status_Source.
* Insert all the records that exist in Status_Source that do NOT exist in Status_Target.
* Set the value of Status in Status_Target to inactive for all the records that were last modified more than seven days ago and that do NOT exist in Status.Source.
How should you complete the statement? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.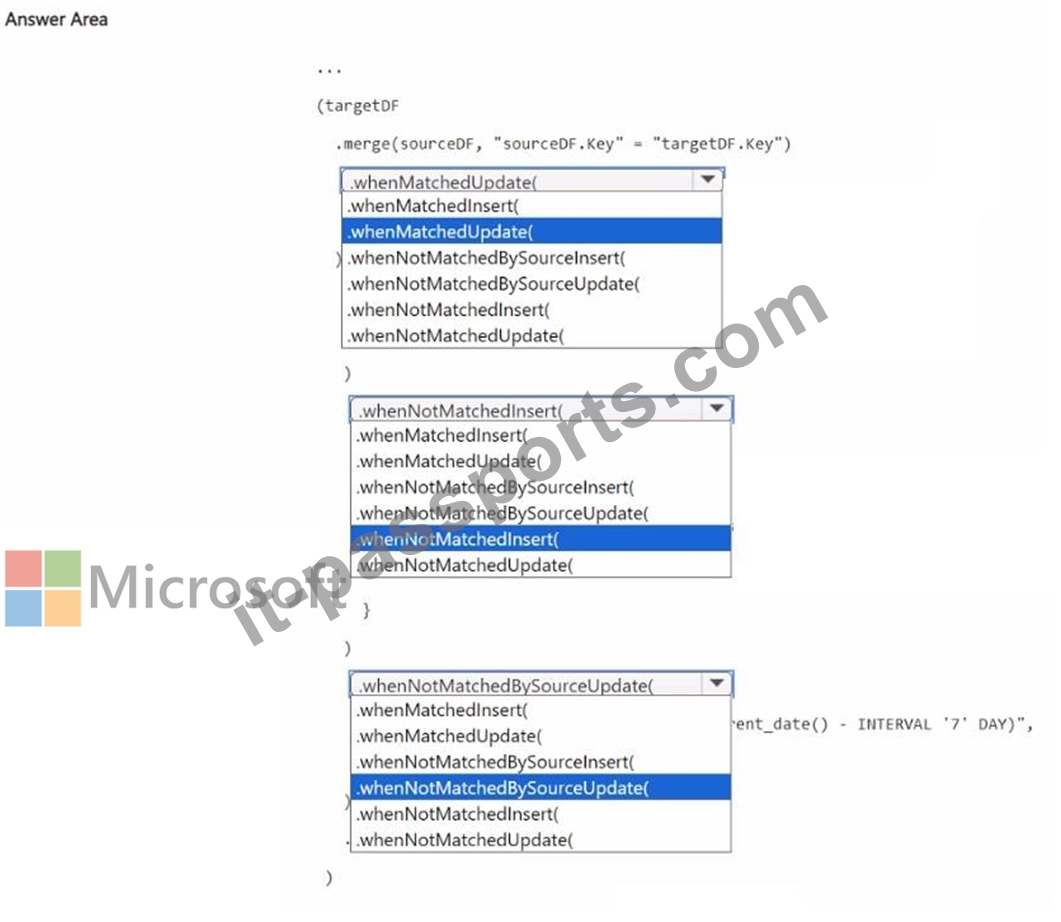
正解:
解説: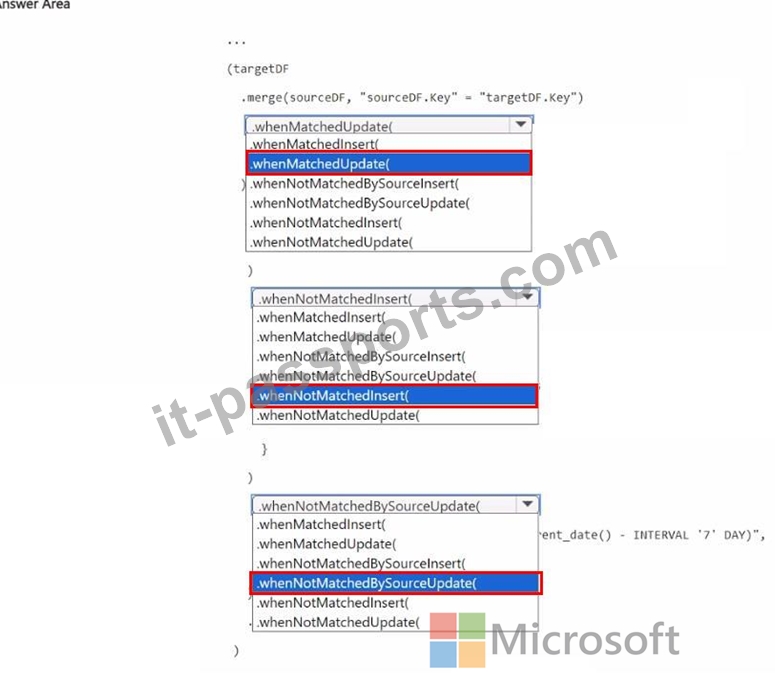
質問 # 140
Exhibit.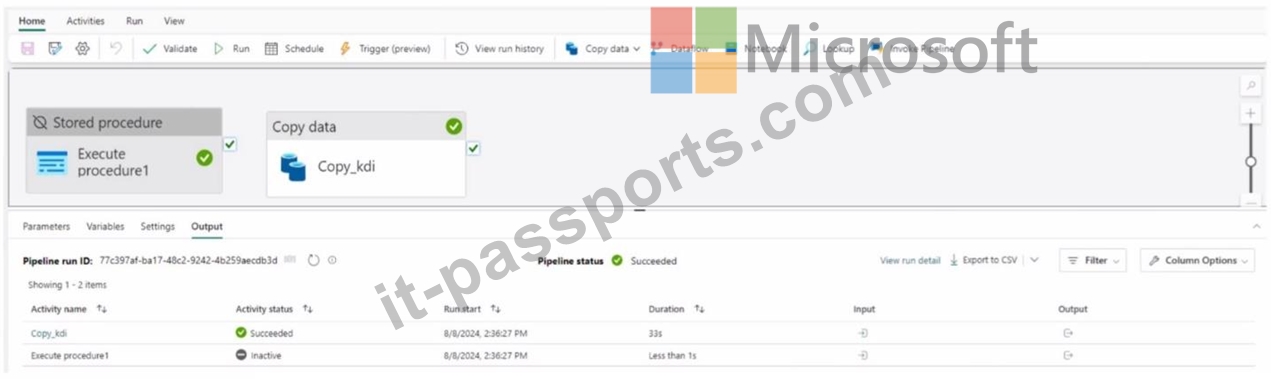
You have a Fabric workspace that contains a write-intensive warehouse named DW1. DW1 stores staging tables that are used to load a dimensional model. The tables are often read once, dropped, and then recreated to process new data.
You need to minimize the load time of DW1.
What should you do?
正解:C
質問 # 141
You have an Azure Data Lake Storage Gen2 account named storage1 and an Amazon S3 bucket named storage2.
You have the Delta Parquet files shown in the following table.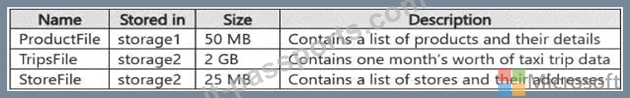
You have a Fabric workspace named Workspace1 that has the cache for shortcuts enabled. Workspace1 contains a lakehouse named Lakehouse1. Lakehouse1 has the following shortcuts:
A shortcut to ProductFile aliased as Products
A shortcut to StoreFile aliased as Stores
A shortcut to TripsFile aliased as Trips
The data from which shortcuts will be retrieved from the cache?
正解:A
解説:
When the cache for shortcuts is enabled in Fabric, the data retrieval is governed by the caching behavior, which generally retains data for a specific period after it was last accessed. The data from the shortcuts will be retrieved from the cache if the data is stored in locations that support caching. Here's a breakdown based on the data's location:
Products: The ProductFile is stored in Azure Data Lake Storage Gen2 (storage1). Since Azure Data Lake is a supported storage system in Fabric and the file is relatively small (50 MB), this data is most likely cached and can be retrieved from the cache.
Stores: The StoreFile is stored in Amazon S3 (storage2), and even though it is stored in a different cloud provider, Fabric can cache data from Amazon S3 if caching is enabled. This data (25 MB) is likely cached and retrievable.
Trips: The TripsFile is stored in Amazon S3 (storage2) and is significantly larger (2 GB) compared to the other files. While Fabric can cache data from Amazon S3, the larger size of the file (2 GB) may exceed typical cache sizes or retention windows, causing this file to likely be retrieved directly from the source instead of the cache.
質問 # 142
You have a Fabric workspace that contains a lakehouse named Lakehouse1. Data is ingested into Lakehouse1 as one flat table. The table contains the following columns.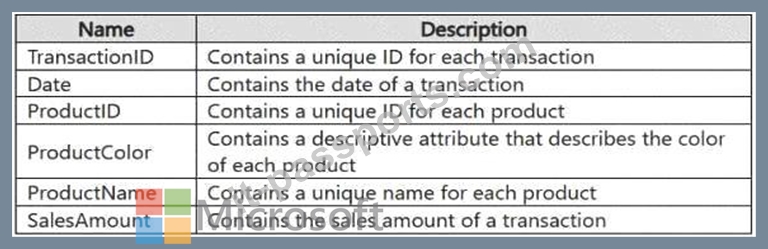
You plan to load the data into a dimensional model and implement a star schema. From the original flat table, you create two tables named FactSales and DimProduct. You will track changes in DimProduct.
You need to prepare the data.
Which three columns should you include in the DimProduct table? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
正解:B、D、E
解説:
In a star schema, the DimProduct table serves as a dimension table that contains descriptive attributes about products. It will provide context for the FactSales table, which contains transactional data. The following columns should be included in the DimProduct table:
* ProductName: The ProductName is an important descriptive attribute of the product, which is needed for analysis and reporting in a dimensional model.
* ProductColor: ProductColor is another descriptive attribute of the product. In a star schema, it makes sense to include attributes like color in the dimension table to help categorize products in the analysis.
* ProductID: ProductID is the primary key for the DimProduct table, which will be used to join the FactSales table to the product dimension. It's essential for uniquely identifying each product in the model.
質問 # 143
......
誰もが異なる学習習慣を持っているため、DP-700試験シミュレーションでは、PDFバージョン、ソフトウェアバージョン、およびAPPバージョンのさまざまなシステムバージョンが提供されます。特定の状況に基づいて、最適なバージョンを選択するか、複数のバージョンを同時に使用できます。結局のところ、DP-700準備質問の各バージョンには独自の利点があります。非常に忙しい場合は、DP-700学習資料を使用するために非常に断片化された時間の一部しか使用できません。また、DP-700試験の各質問は、確実に試験に合格するのに役立ちます。
DP-700テスト問題集: https://www.it-passports.com/DP-700.html
無料でクラウドストレージから最新のIt-Passports DP-700 PDFダンプをダウンロードする:https://drive.google.com/open?id=1RBk7iHpUjJ9imwsjdtYNwKlHPjj7VIBk