Due to lots of same products in the market, maybe you have difficulty in choosing the AI-300 guide test. We can confidently tell you that our products are excellent in all aspects. You can directly select our products. Firstly, we have free trials of the AI-300 exam study materials to help you know our products. Once you find it unsuitable for you, you can choose other types of the study materials. You will never be forced to purchase our AI-300 Test Answers. Just make your own decisions. We can satisfy all your demands and deal with all your problems.
| Section | Objectives |
|---|---|
| Topic 1: Optimize generative AI systems and model performance | - Fine-tune and distill models for specific use cases - Optimize inference performance, caching, and throughput - Tune prompts, system messages, and grounding strategies - Implement cost management and scaling strategies for GenAI workloads |
| Topic 2: Implement generative AI quality assurance and observability | - Conduct red teaming, adversarial testing, and content filtering - Implement logging, tracing, and telemetry for GenAI applications - Monitor latency, token usage, cost, and error rates - Evaluate generative AI outputs for quality, safety, and grounding |
| Topic 3: Implement machine learning model lifecycle and operations | - Deploy models to real-time and batch endpoints - Monitor model performance, data drift, and operational health - Train, register, and version models using Azure Machine Learning - Retrain, update, and manage model versions in production |
| Topic 4: Design and implement a GenAIOps infrastructure | - Manage API keys, rate limits, and responsible AI guardrails - Set up Microsoft Foundry and Azure AI services for generative AI workloads - Configure prompt orchestration, prompt flows, and agent frameworks - Implement RAG (Retrieval-Augmented Generation) pipelines and vector search |
| Topic 5: Design and implement an MLOps infrastructure | - Set up Azure Machine Learning workspace and compute targets - Configure source control, CI/CD pipelines, and automation for ML workflows - Manage environments, data stores, and model registries - Implement security, governance, and compliance for MLOps |
>> AI-300 Practice Exam Online <<
Get the Microsoft certification to validate your IT expertise and broaden your network to get more improvement in your career. RealValidExam will help you with its valid and high quality AI-300 prep torrent. AI-300 questions & answers are compiled by our senior experts who with rich experience. Besides, we check the update about AI-300 Training Pdf every day. If there is any update, the newest and latest information will be added into the AI-300 complete dumps, while the old and useless questions will be removed of the AI-300 torrent. The hiogh quality and high pass rate can ensure you get high scores in the AI-300 actual test.
NEW QUESTION # 25
An Azure Machine Learning workspace contains multiple registered versions of a model that is used in production.
An older model version must no longer be deployable, but it must remain available for compliance review and potential rollback.
You need to change the state of the model version to meet the requirements.
What should you do?
Answer: A
Explanation:
To ensure that older Azure Machine Learning model versions are no longer deployable but remain available for reference or historical tracking, you should archive those specific versions.
How to Archive Model Versions
Archiving a model version effectively hides it from standard list queries and management interfaces, preventing accidental deployment while maintaining its metadata and files in the workspace.
Behavior of Archived Models:
Hidden by Default: They will no longer appear in the Azure Machine Learning Studio model list unless you explicitly filter for archived assets.
Referenceable: You can still reference and use an archived model version in existing workflows if you have its specific version number.
Restoreable: If you need to redeploy the model in the future, you can use the restore command to make it active again.
Reference:
https://learn.microsoft.com/en-us/azure/machine-learning/how-to-manage-models
NEW QUESTION # 26
Hotspot Question
You are using hyperparameter tuning in Azure Machine Learning Python SDK v2 to train a model.
You configure the hyperparameter tuning experiment by running the following code: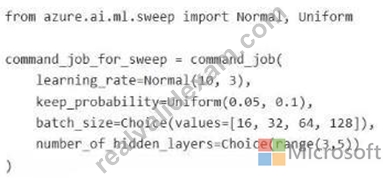
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.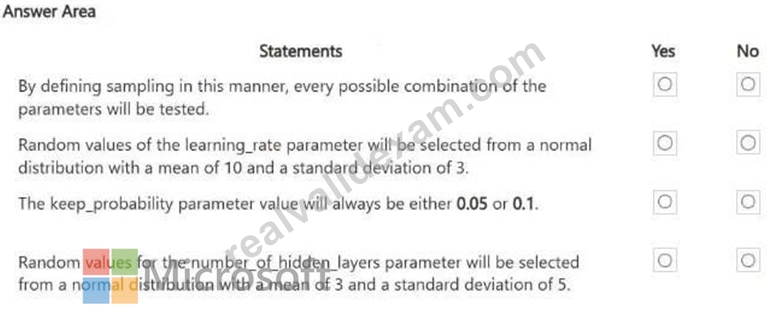
Answer:
Explanation: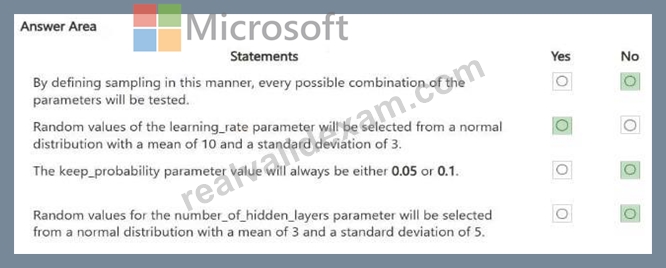
Explanation:
Box 1: No
No - By defining sampling in this manner, every possible combination of the parameters will be tested.
No, every possible combination will not be tested.
Continuous Spaces: Normal and Uniform distributions define continuous search spaces, creating an infinite number of possible decimal values.
Sampling Limits: The sweep job will only try a finite number of combinations based on your configuration.
Termination Rules: The total number of trials evaluated is strictly determined by the max_total_trials parameter and the chosen sampling_algorithm (e.g., Random, Grid, or Bayesian) that you apply to the sweep.
Box 2: Yes
Yes - Random values of the learning_rate parameter will be selected from a normal distribution with a mean of 10 and a standard deviation of 3.
The Normal(mu, sigma) distribution sampler in the Azure Machine Learning Python SDK v2 selects random values from a normal distribution defined by a mean (mu) and a standard deviation (sigma). In the code, Normal(10, 3) explicitly sets the mean to 10 and the standard deviation to 3.
Box 3: No
No - The keep_probabilily parameter value will always be either 0.05 or 0.1.
Because it is defined using Uniform(0.05, 0.1), Azure Machine Learning treats it as a continuous hyperparameter. This means the sweep job will sample any real number (floating-point value) distributed uniformly between 0.05 and 0.1 inclusive (for example, 0.063, 0.087, or 0.091), rather than choosing strictly between the two boundaries.
Box 4: No
No - Random values for the number_of_hidden_layers parameter will be selected from a normal distribution with a mean of 3 and standard deviation of 5.
The values for number_of_hidden_layers will be selected uniformly from a discrete list of choices, not from a normal distribution.
The Choice function: The Choice(range(3,5)) expression creates a discrete set of options: [3, 4].
Reference:
https://learn.microsoft.com/en-us/Azure/machine-Learning/how-to-tune-hyperparameters
https://github.com/Azure/azureml-examples/blob/main/sdk/python/jobs/single-step/lightgbm/iris/lightgbm-iris-sweep.ipynb
NEW QUESTION # 27
A team deploys a model to a real-time endpoint in Azure Machine Learning. You deploy some updates to the endpoint.
The endpoint returns errors after the new deployment is released.
You need to restore the service as quickly as possible.
What should you do first?
Answer: D
Explanation:
Speed of recovery is the central requirement. Rolling back traffic to the previous deployment is the fastest possible action: because the previous deployment still exists on the same endpoint, you simply update the traffic weights - setting the old deployment to 100% and the new deployment to 0% - using a single Azure ML CLI command or SDK call that completes in seconds without reprovisioning any compute. Deleting and redeploying (option B) requires tearing down the endpoint, waiting for deprovisioning, recreating it, re- deploying the model, and waiting for containers to start - potentially 10 to 30 minutes. Changing authentication type (option C) does not affect application errors caused by a bad model. Increasing compute size (option D) does not fix model logic errors. The entire reason Azure ML supports multiple concurrent deployments with traffic splitting is precisely to enable this instant rollback pattern.
Microsoft Learn Reference Topic: Roll back deployments on managed online endpoints - Azure Machine Learning safe deployment practices
NEW QUESTION # 28
You have an Azure subscription named Sub1 that contains an Azure Machine Learning workspace named Workspace1. Workspace1 contains the following assets:
- a registered MLflow model named Model1
- an online endpoint named Endpoint1
Outbound network connectivity from Endpoint1 is blocked.
You need to deploy Model1 to Endpoint1.
What should you do first?
Answer: C
Explanation:
To successfully deploy the registered MLflow model to an online endpoint that lacks outbound internet connectivity, you must use model packaging to build a deployment package before deploying.
By default, Azure Machine Learning deploys MLflow models using a "no-code deployment" approach, which requires an outbound internet connection during container runtime to dynamically download and install Python dependencies listed in the model's conda.yaml file.
Because outbound connectivity is blocked, this process fails. Packaging the model bundles the model binaries, dependencies, and environment ahead of time, entirely removing the requirement for runtime internet access.
Reference:
https://docs.azure.cn/en-us/machine-learning/how-to-deploy-mlflow-models-online-endpoints
NEW QUESTION # 29
A data science team trains a classification model that predicts loan approval outcomes.
Before registering the model, the team must ensure the following:
- Predictions must not disproportionately impact protected groups.
- Prediction errors can be evaluated across different data segments.
You need to assess whether the model meets Responsible AI expectations.
Which two approaches should you use? Each correct answer presents part of the solution.
Choose two.
NOTE: Each correct selection is worth one point.
Answer: C,E
Explanation:
[D]
To evaluate a trained loan classification model for Responsible AI expectations--ensuring no disproportionate impact on protected groups, evaluating error across segments, and verifying prediction transparency--you can employ SHAP (SHapley Additive exPlanations) values to assess feature importance.
This approach allows you to identify which variables (e.g., credit history, debt levels) drive the model's predictions, fostering trust and fairness.
Feature Importance for Transparency: Use SHAP (model-agnostic) or LIME (local approximations) to explain why the model approved or denied a loan. These techniques identify how each feature contributes to individual predictions.
[E]
To ensure a trained loan approval classification model meets responsible AI expectations-- specifically, that it does not disproportionately impact protected groups and that errors can be evaluated across segments--you should analyze error rates across defined demographic cohorts using Fairness-Aware Machine Learning metrics.
Reference:
https://urfpublishers.com/journal/artificial-intelligence/article/view/explainable-aiml-testing- ensuring-transparency-accountability-and-compliance
https://timvero.com/blog/ethics-in-automated-lending-can-ai-make-fair-credit-decisions
NEW QUESTION # 30
......
Our company is professional brand established for compiling AI-300 exam materials for candidates, and we aim to help you to pass the examination as well as getting the related certification in a more efficient and easier way. Owing to the superior quality and reasonable price of our AI-300 Exam Materials, our company has become a top-notch one in the international market. Our AI-300 exam torrents are not only superior in price than other makers in the international field, but also are distinctly superior in the following respects.
Latest AI-300 Test Vce: https://www.realvalidexam.com/AI-300-real-exam-dumps.html