BTW, DOWNLOAD part of Itcertking Databricks-Generative-AI-Engineer-Associate dumps from Cloud Storage: https://drive.google.com/open?id=12qEDMTg4B0BU7TxvLBSJ0T3nfa07kJ3s
Itcertking provides you with actual Databricks Databricks-Generative-AI-Engineer-Associate dumps in PDF format, Desktop-Based Practice tests, and Web-based Practice exams. These 3 formats of Databricks Certified Generative AI Engineer Associate exam preparation are easy to use. This is a printable Databricks Databricks-Generative-AI-Engineer-Associate PDF dumps file. The Databricks Databricks-Generative-AI-Engineer-Associate Pdf Dumps enables you to study without any device, as it is a portable and easily shareable format, thus you can study Databricks Databricks-Generative-AI-Engineer-Associate dumps on your preferred smart device such as your smartphone or in hard copy format.
| Section | Objectives |
|---|---|
| Databricks Mosaic AI Platform | - Model development and serving
|
| Retrieval-Augmented Generation (RAG) | - RAG architecture
|
| Prompt Engineering | - Prompt design techniques
|
| Foundations of Generative AI | - Large Language Models (LLMs)
|
| Responsible AI and Governance | - AI safety and ethics
|
>> Free Databricks-Generative-AI-Engineer-Associate Braindumps <<
Each IT person is working hard for promotion and salary increases. It is also a reflection of the pressure of modern society. We should use the strength to prove ourselves. Participate in the Databricks Databricks-Generative-AI-Engineer-Associate exam please. In fact, this examination is not so difficult as what you are thinking. You only need to select the appropriate training materials. Itcertking's Databricks Databricks-Generative-AI-Engineer-Associate Exam Training materials is the best training materials. Select the materials is to choose what you want. In order to enhance your own, do it quickly.
NEW QUESTION # 62
A Generative AI Engineer I using the code below to test setting up a vector store: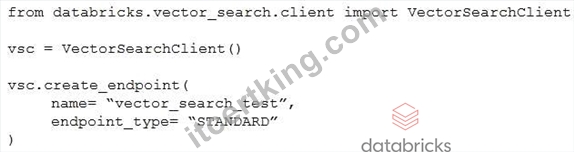
Assuming they intend to use Databricks managed embeddings with the default embedding model, what should be the next logical function call?
Answer: B
Explanation:
Context: The Generative AI Engineer is setting up a vector store using Databricks' VectorSearchClient. This is typically done to enable fast and efficient retrieval of vectorized data for tasks like similarity searches.
Explanation of Options:
* Option A: vsc.get_index(): This function would be used to retrieve an existing index, not create one, so it would not be the logical next step immediately after creating an endpoint.
* Option B: vsc.create_delta_sync_index(): After setting up a vector store endpoint, creating an index is necessary to start populating and organizing the data. The create_delta_sync_index() function specifically creates an index that synchronizes with a Delta table, allowing automatic updates as the data changes. This is likely the most appropriate choice if the engineer plans to use dynamic data that is updated over time.
* Option C: vsc.create_direct_access_index(): This function would create an index that directly accesses the data without synchronization. While also a valid approach, it's less likely to be the next logical step if the default setup (typically accommodating changes) is intended.
* Option D: vsc.similarity_search(): This function would be used to perform searches on an existing index; however, an index needs to be created and populated with data before any search can be conducted.
Given the typical workflow in setting up a vector store, the next step after creating an endpoint is to establish an index, particularly one that synchronizes with ongoing data updates, henceOption B.
NEW QUESTION # 63
A Generative AI Engineer is building a compound AI system for an organization. The goal is to automate the processing of incoming customer event reports against a coding system and corporate-guidelines documentation. The system must handle three distinct user-request types: answering questions from guidelines documents, extracting specific event codes from reviewers' notes, and routing ambiguous requests to the appropriate specialized handler. All three capabilities must operate under a single entry point that interprets user intent and delegates accordingly.
Which Agent Brick should serve as the top-level orchestrator in this architecture?
Answer: A
Explanation:
The Multi-Agent Supervisor is designed to coordinate specialized agents and tools behind a unified entry point. It interprets the incoming request, selects suitable capabilities, delegates work, and combines results when necessary. In this scenario, document questions can be handled by a knowledge-retrieval specialist, while event-code extraction can be assigned to a specialized extraction capability. The supervisor provides the coordination needed to select between those tasks and handle requests requiring multiple steps. A Knowledge Assistant's conversational interface does not itself make it the appropriate general-purpose orchestrator.
Adding vector indexes also does not establish specialized extraction and routing behavior. Although option A names the same component, its justification misses the central requirement: coordinated delegation across distinct capabilities. Databricks documentation
NEW QUESTION # 64
A Generative AI Engineer is experimenting with using parameters to configure an agent in Mosaic Agent Framework. However, they are struggling to get the agent to respond with relevant information with this configuration:
config = { " prompt_template " : " You are a trivia bot. Generate a question based on the user ' s input:
{user_input} " , " input_vars " : [ " user_input " ], " parameters " : { " temperature " : 0.01, " max_tokens " :
500}}
Which error is causing the problem?
Answer: C
Explanation:
In the Mosaic AI Agent Framework and underlying LangChain-based configurations, the " input_vars " or " input_variables " must be correctly mapped and referenced within the template. If the configuration dictionary identifies user_input as the variable but the logic executing the chain does not correctly " inject " the runtime value into the {user_input} placeholder, the LLM will receive a literal string (or an empty value) rather than the user ' s actual question. This results in the model failing to provide relevant information because it essentially doesn ' t know what the user asked. Engineering standards require ensuring that the key used in the input_vars list matches the key in the JSON payload sent to the model serving endpoint. If there is a mismatch or a failure to parse, the prompt remains static, leading to generic or irrelevant responses.
NEW QUESTION # 65
A company selling gourmet mushroom-growing supplies has a script that runs once per day to scrape various social media platforms for posts that mention its name. The scraped text data is loaded into a Delta table each night for a downstream processing task that summarizes each post and its sentiment for internal use. Given the small size of the company, it only receives a couple hundred posts per day.
Which solution best optimizes for cost and ease of implementation?
Answer: D
Explanation:
A scheduled SQL query using ai_query() is a straightforward way to process text already stored in a Delta table. The query can send each post to a supported model with instructions to return a summary and sentiment, then persist the results for internal reporting. A pay-per-token service avoids dedicating serving capacity to a workload containing only a few hundred daily records. Calling an external batch API introduces additional integration and result-handling work, while downloading and hosting a model adds infrastructure responsibilities. Provisioned throughput is generally more appropriate when sustained demand justifies dedicated capacity. B is the best fit among these choices; actual costs still depend on model selection, token volume, SQL compute, and the applicable inference pricing. Databricks documentation
NEW QUESTION # 66
A company has a typical RAG-enabled, customer-facing chatbot on its website.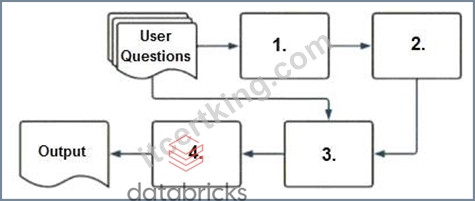
Select the correct sequence of components a user's questions will go through before the final output is returned. Use the diagram above for reference.
Answer: D
Explanation:
To understand how a typical RAG-enabled customer-facing chatbot processes a user's question, let's go through the correct sequence as depicted in the diagram and explained in option A:
* Embedding Model (1):The first step involves the user's question being processed through an embedding model. This model converts the text into a vector format that numerically represents the text. This step is essential for allowing the subsequent vector search to operate effectively.
* Vector Search (2):The vectors generated by the embedding model are then used in a vector search mechanism. This search identifies the most relevant documents or previously answered questions that are stored in a vector format in a database.
* Context-Augmented Prompt (3):The information retrieved from the vector search is used to create a context-augmented prompt. This step involves enhancing the basic user query with additional relevant information gathered to ensure the generated response is as accurate and informative as possible.
* Response-Generating LLM (4):Finally, the context-augmented prompt is fed into a response- generating large language model (LLM). This LLM uses the prompt to generate a coherent and contextually appropriate answer, which is then delivered as the final output to the user.
Why Other Options Are Less Suitable:
* B, C, D: These options suggest incorrect sequences that do not align with how a RAG system typically processes queries. They misplace the role of embedding models, vector search, and response generation in an order that would not facilitate effective information retrieval and response generation.
Thus, the correct sequence isembedding model, vector search, context-augmented prompt, response- generating LLM, which is option A.
NEW QUESTION # 67
......
The language of our Databricks-Generative-AI-Engineer-Associate qualification test guide is simple. The learners may come from many social positions and their abilities to master our Databricks-Generative-AI-Engineer-Associate test materials are varied. Based on this consideration we apply the most simple and easy-to-be-understood language to help the learners no matter he or she is the students or the in-service staff, the novice or the experienced employee which have worked for many years. Databricks-Generative-AI-Engineer-Associate Certification guide use the simple language to explain the answers and detailed knowledge points to help pass the Databricks-Generative-AI-Engineer-Associate exam.
Databricks-Generative-AI-Engineer-Associate Reliable Test Notes: https://www.itcertking.com/Databricks-Generative-AI-Engineer-Associate_exam.html
BTW, DOWNLOAD part of Itcertking Databricks-Generative-AI-Engineer-Associate dumps from Cloud Storage: https://drive.google.com/open?id=12qEDMTg4B0BU7TxvLBSJ0T3nfa07kJ3s