P.S. Free 2026 Snowflake SPS-C01 dumps are available on Google Drive shared by TrainingDumps: https://drive.google.com/open?id=1ZEEzc4kG44frBMvcJN_QCTdACf9DwNEb
Holding a SPS-C01 certification in a certain field definitely shows that one have a good command of the SPS-C01 knowledge and professional skills in the related field. However, it is universally accepted that the majority of the candidates for the Snowflake Certified SnowPro Specialty - Snowpark exam are those who do not have enough spare time and are not able to study in the most efficient way. Our SPS-C01 Study Materials sove this problem perfectly for you with high-efficience and you will know if you can just have a try!
| Section | Weight | Objectives |
|---|---|---|
| Data Transformations and Operations | 35% | - User-defined logic
|
| Performance and Best Practices | 10% | - Security and governance
|
| Snowpark Concepts and Architecture | 25% | - Session management and connection
|
| Snowpark API and Development | 30% | - Python API fundamentals
|
>> Latest SPS-C01 Learning Material <<
With TrainingDumps's help, you do not need to spend a lot of money to participate in related cram or spend a lot of time and effort to review the relevant knowledge, but can easily pass the exam. Simulation test software of Snowflake SPS-C01 Exam is developed by TrainingDumps's research of previous real exams. TrainingDumps's Snowflake SPS-C01 exam practice questions have a lot of similarities with the real exam practice questions.
NEW QUESTION # 68
You are tasked with building a Snowpark function to perform an upsert operation on a Snowflake table using a DataFrame. The function should take the target table name, a staging DataFrame, a join key column, and a list of columns to update. The function needs to handle potential schema evolution (i.e., columns may be added or removed from either the target table or the staging DataFrame) gracefully without causing the entire upsert to fail. Which of the following approaches, or combinations of approaches, would best address this requirement?
Answer: A,E
Explanation:
Approaches A and D are the most suitable for handling schema evolution during an upsert operation. Approach A involves dynamically generating the SQL WERGE statement by inspecting the schemas of both the target table and the staging DataFrame. This ensures that only the common columns are included in the update and insert clauses, preventing errors due to missing columns. Approach D suggests projecting the staging DataFrame to only include the columns that exist in the target table using DataFrame.select' . This effectively harmonizes the schema of the staging data with the target table's schema, avoiding issues during the 'merge' operation. While Snowflake does have some schema evolution capabilities, explicitly handling it in the code provides more control and predictability.
NEW QUESTION # 69
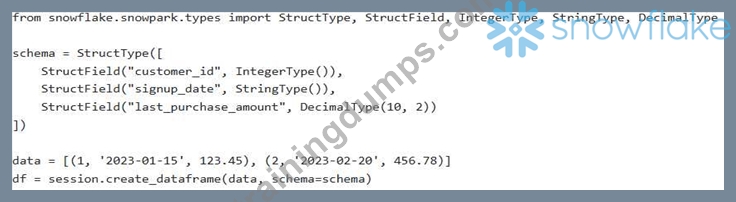
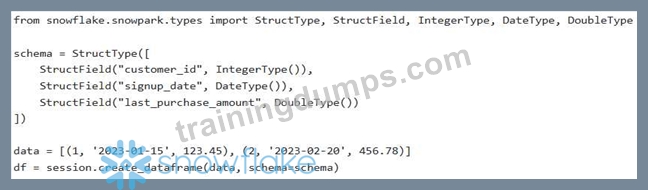
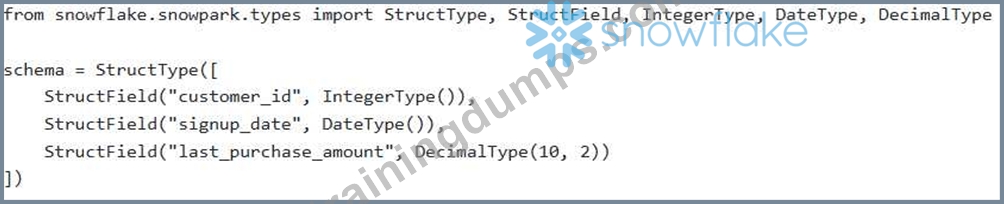
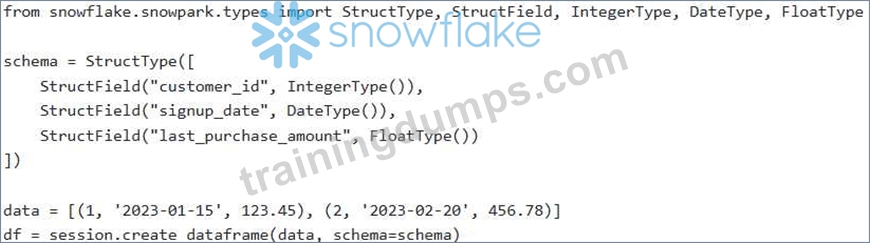
You are tasked with creating a Snowpark DataFrame from a Python list of tuples. Each tuple represents a customer record with the following structure: '(customer_id, signup_date, The 'customer _ id' should be an integer, 'signup_date' should be a date, and should be a decimal. You want to define the schema explicitly for type safety and performance. Which of the following code snippets correctly defines the schema and creates the Snowpark DataFrame?
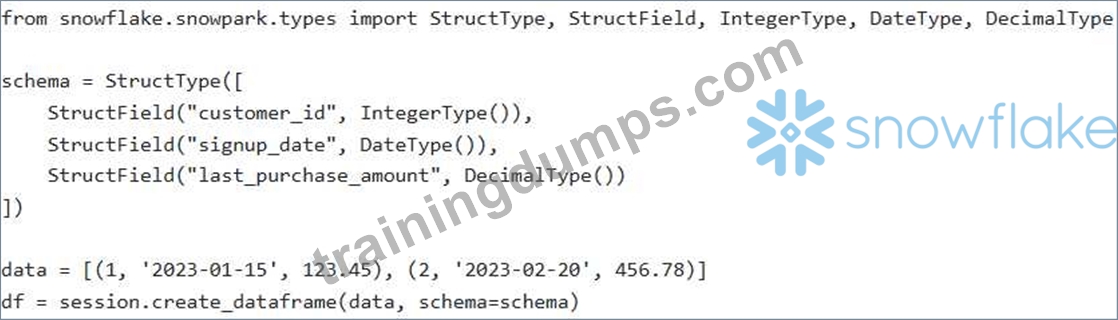
Answer: C
Explanation:
Option A correctly defines the schema using 'StructType', 'StructField', 'Integer Type', 'DateType' , and 'DecimalType' . It also specifies the precision and scale for the 'DecimalType' which is important for accurately representing monetary values. The date values in the data are also compatible with DateType. The other options use incorrect data types for the last_purchase_amount (FloatType, DoubleType, StringType) or don't specify precision and scale for the DecimalType. Note that Snowflake DateType only accepts values formatted as YYYY-MM-DD'.
NEW QUESTION # 70
A data engineering team is using Snowpark Python to build a complex ETL pipeline. They notice that certain transformations are not being executed despite being defined in the code. Which of the following are potential reasons why transformations in Snowpark might not be executed immediately, reflecting the principle of lazy evaluation? Select TWO correct answers.
Answer: D,E
Explanation:
Snowpark employs lazy evaluation, which means transformations are not executed until an action is performed on the DataFrame. This allows Snowflake to optimize the entire query plan before execution. Setting 'eager_execution' to True does NOT exist in Snowpark Python. Data size exceeding Snowflake's limits would result in an error, not skipped transformations.
NEW QUESTION # 71
A data engineering team has created several Snowpark Python UDFs and UDTFs in the 'TRANSFORMATIONS' schema of the 'ANALYTICS' database. A data science team needs to use these functions in their data analysis notebooks. What is the MINIMUM set of privileges that must be granted to the data science team's role ('DATA SCIENTIST') to allow them to discover and execute these UDFs and UDTFs?
Answer: E
Explanation:
The 'USAGE privilege on the database and schema is required for the role to discover (see) the UDFs and UDTFs. The 'EXECUTE privilege on the functions themselves is required to execute them. 'ALL PRIVILEGES' is an overly permissive grant and not the minimum required. Option D is missing the execute privilege. Option E is missing USAGE on Database and Schema.
NEW QUESTION # 72
You are setting up a development environment for Snowpark using Anaconda and encounter the following error: 'ModuleNotFoundError: No module named 'snowflake.snowpark". You have already installed the package using pip. What is the MOST likely cause of this error and how do you resolve it?
Answer: D,E
Explanation:
The most common reasons for 'ModuleNotFoundErroff are that the Anaconda environment is not activated (B), meaning the Python interpreter doesn't know where to find the installed packages, or the package was installed in a different environment (D) than the one being used. While Python version compatibility (A) and Snowflake driver (C) can cause issues, they usually manifest as different errors. A misconfigured account identifier (E) would prevent a connection to Snowflake, but wouldn't directly cause a 'ModuleNotFoundError' for the Snowpark library itself.
NEW QUESTION # 73
......
You can trust the SPS-C01 practice test and start this journey with complete peace of mind and satisfaction. The SPS-C01 exam PDF questions will not assist you in Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) exam preparation but also provide you with in-depth knowledge about the Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) exam topics. This knowledge will be helpful to you in your professional life. So Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) exam questions are the ideal study material for quick Snowflake SPS-C01 exam preparation.
Valid Test SPS-C01 Test: https://www.trainingdumps.com/SPS-C01_exam-valid-dumps.html
BONUS!!! Download part of TrainingDumps SPS-C01 dumps for free: https://drive.google.com/open?id=1ZEEzc4kG44frBMvcJN_QCTdACf9DwNEb