P.S. Free 2026 NVIDIA NCP-AII dumps are available on Google Drive shared by PassReview: https://drive.google.com/open?id=1z73tCJYEH-Y_Ibayp-Vu_dQVhEoQHEK1
There are a lot of free online resources to study for the NVIDIA AI Infrastructure NCP-AII certification exam. Some of these resources are free, while others require payment for access. you've downloaded a free NVIDIA dumps, and PassReview offers 365 days updates. NVIDIA AI Infrastructure NCP-AII price is affordable.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
| Topic 5 |
|
>> Accurate NVIDIA NCP-AII Prep Material <<
It is universally acknowledged that NVIDIA certification can help present you as a good master of some knowledge in certain areas, and it also serves as an embodiment in showcasing one’s personal skills. However, it is easier to say so than to actually get the NVIDIA certification. We have to understand that not everyone is good at self-learning and self-discipline, and thus many people need outside help to cultivate good study habits, especially those who have trouble in following a timetable. To handle this, our NCP-AII test training will provide you with a well-rounded service so that you will not lag behind and finish your daily task step by step. At the same time, our NCP-AII study torrent will also save your time and energy in well-targeted learning as we are going to make everything done in order that you can stay focused in learning our NCP-AII study materials without worries behind. We are so honored and pleased to be able to read our detailed introduction and we will try our best to enable you a better understanding of our NCP-AII test training better.
NEW QUESTION # 144
A systems engineer is updating firmware across a large DGX cluster using automation. What is the best practice for minimizing risk and ensuring cluster health during and after the process?
Answer: C
Explanation:
Large-cluster firmware updates should be performed in controlled batches after draining nodes from the scheduler so active workloads are not disrupted. Running pre-update diagnostics establishes baseline health, and post-update verification confirms each batch is stable before expanding the update to more nodes.
NEW QUESTION # 145
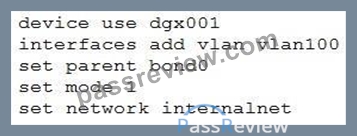
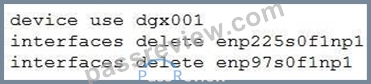
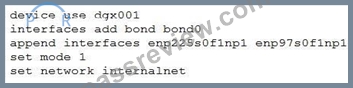
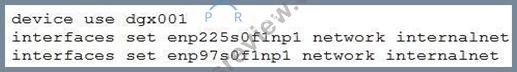
During BCM cluster setup, an engineer must configure bonded network interfaces on DGX nodes for high availability. Which cmsh command sequence properly configures a bond0 interface with two physical NICs?
Answer: C
Explanation:
In BCM cmsh, a bonded interface is created by adding a bond interface, appending the two physical NICs as bond members, setting the bonding mode, and assigning the bond to the appropriate network. This configures bond0 with the two physical interfaces for high availability on the internal network.
NEW QUESTION # 146
Your AI training workload involves a large dataset stored in an object storage system (like AWS S3). You notice that fetching data directly from S3 during training is a bottleneck. Which of the following strategies can significantly improve data loading performance?
Answer: C
Explanation:
A caching layer brings frequently accessed data closer to the compute nodes, reducing latency and improving throughput. Increasing retries only addresses transient errors. Reducing data loaders worsens performance. Switching providers might not solve the underlying latency issue. S3 Glacier is for archival, so will result in worse performance.
NEW QUESTION # 147
You are configuring a network bridge on a Linux host that will connect multiple physical network interfaces to a virtual machine. You need to ensure that the virtual machine receives an IP address via DHCP. Which of the following is the correct command sequence to create the bridge interface 'br0', add physical interfaces 'eth0' and 'eth1' to it, and bring up the bridge interface? Assume the required packages are installed. Consider using 'ip' command.





Answer: E
Explanation:
Option D is the correct sequence using the Sip' command. First, create the bridge ' bro'. Then, add the physical interfaces 'eth0 and "eth1' as slaves to the bridge. Next, bring up the physical interfaces. After that, bring up the bridge interface . Finally, use "dhclient bro to obtain an IP address for the bridge via DHCP. Option C is the old way, using 'brctr and 'ifconfig', which are deprecated. The others lack the crucial step of bringing up the bridge after attaching the physical interfaces and before running 'dhclient'.
NEW QUESTION # 148
A company deploys a large language model training cluster containing multiple NVIDIA HGX servers. During benchmarking, GPUs within each server communicate efficiently, but gradient synchronization across servers introduces significantly higher latency than expected. The infrastructure engineer needs to identify the component primarily responsible for optimizing GPU- to-GPU communication between different servers while maintaining maximum bandwidth and minimum latency.
Answer: D
Explanation:
NVSwitch accelerates communication among GPUs inside a single HGX server, but it does not extend across physical servers. Multi-node distributed training depends on the InfiniBand fabric and technologies such as GPUDirect RDMA to provide low-latency, high-bandwidth communication. PCIe switches remain local to the server, while MIG partitions GPUs rather than improving network communication.
NEW QUESTION # 149
......
NVIDIA NCP-AII certification exams are a great way to analyze and evaluate the skills of a candidate effectively. Big companies are always on the lookout for capable candidates. You need to pass the NVIDIA NCP-AII Certification Exam to become a certified professional. This task is considerably tough for unprepared candidates however with the right NCP-AII prep material there remains no chance of failure.
New NCP-AII Exam Experience: https://www.passreview.com/NCP-AII_exam-braindumps.html
P.S. Free & New NCP-AII dumps are available on Google Drive shared by PassReview: https://drive.google.com/open?id=1z73tCJYEH-Y_Ibayp-Vu_dQVhEoQHEK1