2026 Latest DumpsTorrent AIF-C01 PDF Dumps and AIF-C01 Exam Engine Free Share: https://drive.google.com/open?id=1HM6pGnQwUPPYIFOvn4pSLLcocvQvzGkm
We sincerely suggest you to try these demos of our AIF-C01 study guide and make a well-content choice. Different demos have different functions and each version has its advantages during the process of learning. Our AIF-C01 Preparation exam is suitable for various consumer groups in the world we assure that after having a knowledge of those demos, you can purchase the most suitable AIF-C01 exam materials.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
| Topic 5 |
|
>> Examcollection AIF-C01 Dumps <<
We own three versions of the AIF-C01 exam torrent for you to choose. They conclude PDF version, PC version and APP online version. You can choose the most convenient version of the AIF-C01 quiz torrent. The three versions of the AIF-C01 test prep boost different strengths and you can find the most appropriate choice. For example, the PDF version is convenient for download and printing and is easy and convenient for review and learning. It can be printed into papers and is convenient to make notes. You can learn the AIF-C01 Test Prep at any time or place and repeatedly practice.
NEW QUESTION # 137
An AI practitioner trained a custom model on Amazon Bedrock by using a training dataset that contains confidential data. The AI practitioner wants to ensure that the custom model does not generate inference responses based on confidential data.
How should the AI practitioner prevent responses based on confidential data?
Answer: C
Explanation:
When a model is trained on a dataset containing confidential or sensitive data, the model may inadvertently learn patterns from this data, which could then be reflected in its inference responses. To ensure that a model does not generate responses based on confidential data, the most effective approach is to remove the confidential data from the training dataset and then retrain the model.
Explanation of Each Option:
* Option A (Correct): "Delete the custom model. Remove the confidential data from the training dataset.
Retrain the custom model."This option is correct because it directly addresses the core issue: the model has been trained on confidential data. The only way to ensure that the model does not produce inferences based on this data is to remove the confidential information from the training dataset and then retrain the model from scratch. Simply deleting the model and retraining it ensures that no confidential data is learned or retained by the model. This approach follows the best practices recommended by AWS for handling sensitive data when using machine learning services like Amazon Bedrock.
* Option B: "Mask the confidential data in the inference responses by using dynamic data masking."This option is incorrect because dynamic data masking is typically used to mask or obfuscate sensitive data in a database. It does not address the core problem of the model being trained on confidential data.
Masking data in inference responses does not prevent the model from using confidential data it learned during training.
* Option C: "Encrypt the confidential data in the inference responses by using Amazon SageMaker."This option is incorrect because encrypting the inference responses does not prevent the model from generating outputs based on confidential data. Encryption only secures the data at rest or in transit but does not affect the model's underlying knowledge or training process.
* Option D: "Encrypt the confidential data in the custom model by using AWS Key Management Service (AWS KMS)."This option is incorrect as well because encrypting the data within the model does not prevent the model from generating responses based on the confidential data it learned during training.
AWS KMS can encrypt data, but it does not modify the learning that the model has already performed.
AWS AI Practitioner References:
* Data Handling Best Practices in AWS Machine Learning: AWS advises practitioners to carefully handle training data, especially when it involves sensitive or confidential information. This includes preprocessing steps like data anonymization or removal of sensitive data before using it to train machine learning models.
* Amazon Bedrock and Model Training Security: Amazon Bedrock provides foundational models and customization capabilities, but any training involving sensitive data should follow best practices, such as removing or anonymizing confidential data to prevent unintended data leakage.
NEW QUESTION # 138
A company wants to create an application to summarize meetings by using meeting audio recordings.
Select and order the correct steps from the following list to create the application. Each step should be selected one time or not at all. (Select and order THREE.)
* Convert meeting audio recordings to meeting text files by using Amazon Polly.
* Convert meeting audio recordings to meeting text files by using Amazon Transcribe.
* Store meeting audio recordings in an Amazon S3 bucket.
* Store meeting audio recordings in an Amazon Elastic Block Store (Amazon EBS) volume.
* Summarize meeting text files by using Amazon Bedrock.
* Summarize meeting text files by using Amazon Lex.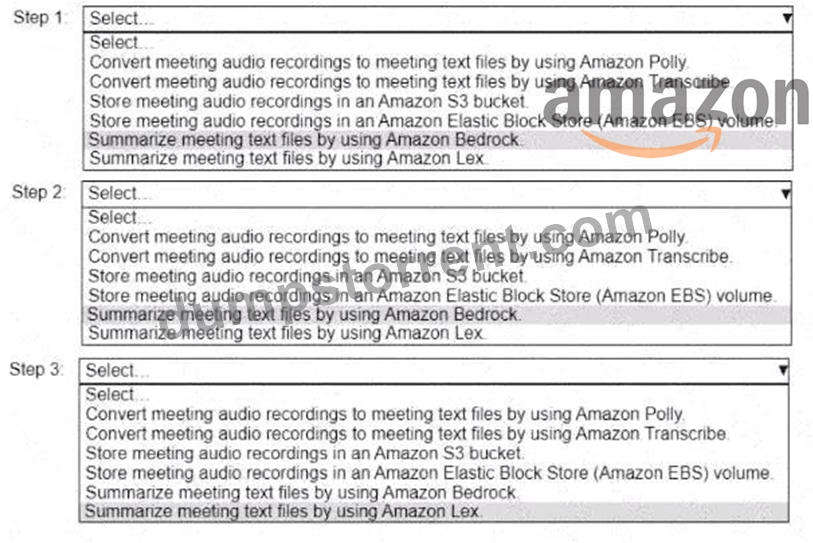
Answer:
Explanation: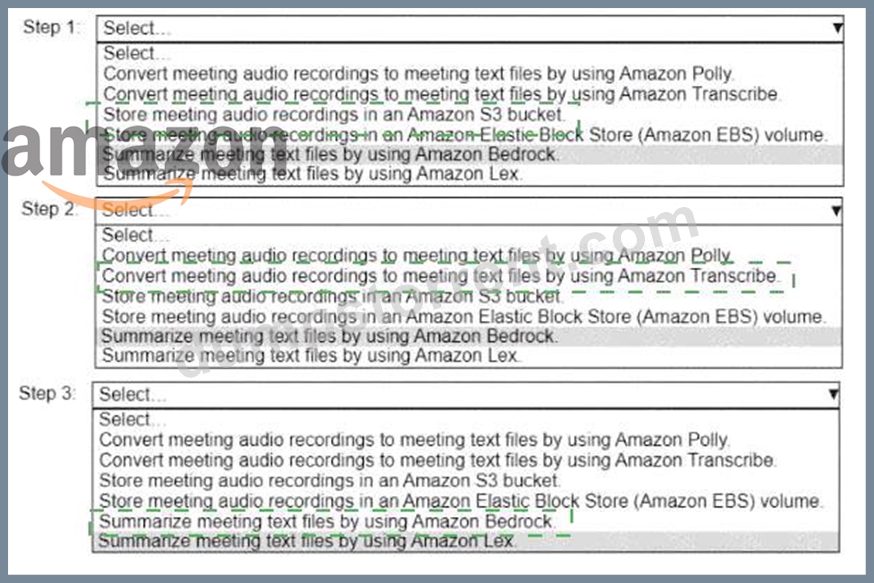
Explanation:
Step 1: Store meeting audio recordings in an Amazon S3 bucket.
Step 2: Convert meeting audio recordings to meeting text files by using Amazon Transcribe.
Step 3: Summarize meeting text files by using Amazon Bedrock.
The company wants to create an application to summarize meeting audio recordings, which requires a sequence of steps involving storage, speech-to-text conversion, and text summarization. Amazon S3 is the recommended storage service for audio files, Amazon Transcribe converts audio to text, and Amazon Bedrock provides generative AI capabilities for summarization. These three steps, in this order, create an efficient workflow for the application.
Exact Extract from AWS AI Documents:
From the Amazon Transcribe Developer Guide:
"Amazon Transcribe uses deep learning to convert audio files into text, supporting applications such as meeting transcription. Audio files can be stored in Amazon S3, and Transcribe can process them directly from an S3 bucket." From the AWS Bedrock User Guide:
"Amazon Bedrock provides foundation models that can perform text summarization, enabling developers to build applications that generate concise summaries from text data, such as meeting transcripts." (Source: Amazon Transcribe Developer Guide, Introduction to Amazon Transcribe; AWS Bedrock User Guide, Text Generation and Summarization) Detailed Explanation:
Step 1: Store meeting audio recordings in an Amazon S3 bucket.Amazon S3 is the standard storage service for audio files in AWS workflows, especially for integration with services like Amazon Transcribe. Storing the recordings in S3 allows Transcribe to access and process them efficiently. This is the first logical step.
Step 2: Convert meeting audio recordings to meeting text files by using Amazon Transcribe.Amazon Transcribe is designed for automatic speech recognition (ASR), converting audio files (stored in S3) into text.
This step is necessary to transform the meeting recordings into a format that can be summarized.
Step 3: Summarize meeting text files by using Amazon Bedrock.Amazon Bedrock provides foundation models capable of generative AI tasks like text summarization. Once the audio is converted to text, Bedrock can summarize the meeting transcripts, completing the application's requirements.
Unused Options Analysis:
Convert meeting audio recordings to meeting text files by using Amazon Polly.Amazon Polly is a text-to- speech service, not for converting audio to text. This option is incorrect and not used.
Store meeting audio recordings in an Amazon Elastic Block Store (Amazon EBS) volume.Amazon EBS is for block storage, typically used for compute instances, not for storing files for processing by services like Transcribe. S3 is the better choice, so this option is not used.
Summarize meeting text files by using Amazon Lex.Amazon Lex is for building conversational interfaces (chatbots), not for text summarization. Bedrock is the appropriate service for summarization, so this option is not used.
Hotspot Selection Analysis:
The task requires selecting and ordering three steps from the list, with each step used exactly once or not at all. The selected steps-storing in S3, converting with Transcribe, and summarizing with Bedrock-form a complete and logical workflow for the application.
References:
Amazon Transcribe Developer Guide: Introduction to Amazon Transcribe (https://docs.aws.amazon.com
/transcribe/latest/dg/what-is.html)
AWS Bedrock User Guide: Text Generation and Summarization (https://docs.aws.amazon.com/bedrock/latest
/userguide/what-is-bedrock.html)
AWS AI Practitioner Learning Path: Module on Speech-to-Text and Generative AI Amazon S3 User Guide: Storing Data for Processing (https://docs.aws.amazon.com/AmazonS3/latest
/userguide/Welcome.html)
NEW QUESTION # 139
A publishing company built a Retrieval Augmented Generation (RAG) based solution to give its users the ability to interact with published content. New content is published daily. The company wants to provide a near real-time experience to users.
Which steps in the RAG pipeline should the company implement by using offline batch processing to meet these requirements? (Select TWO.)
Answer: B,D
Explanation:
Comprehensive and Detailed Explanation From Exact Extract:
In a RAG (Retrieval Augmented Generation) architecture, there are steps that can be optimized using offline batch processing, particularly for operations that do not require real-time updates:
A . Generation of content embeddings:
When new content is published, it can be processed in batches to generate embeddings (vector representations) offline. These embeddings are then used at query time for similarity search. As new documents come in daily, batch processing is ideal for generating embeddings for all new content together.
"Content/document embeddings are typically generated offline, as this operation can be computationally expensive and does not need to happen in real-time." (Reference: AWS GenAI RAG Blog, Amazon Bedrock RAG Pattern) C . Creation of the search index:
After generating the content embeddings, these are indexed in a vector database or search service. This indexing is also typically performed in batch as part of the offline pipeline.
"Building or updating the vector index is often performed as a batch operation, reflecting the latest state of the content repository." (Reference: AWS RAG Pattern Whitepaper) B, D, and E are real-time steps. Embeddings for user queries (B), retrieval of relevant content (D), and response generation (E) must be processed in real-time to provide an interactive experience.
Reference:
Retrieval Augmented Generation (RAG) on AWS
Amazon Bedrock RAG Documentation
NEW QUESTION # 140
Select the correct prompt engineering technique from the following list for each description. Select each prompt engineering technique one time or not at all. (Select THREE.)
* Chain-of-thought prompting
* Few-shot prompting
* Role-based prompting
* Single-shot prompting
* Zero-shot prompting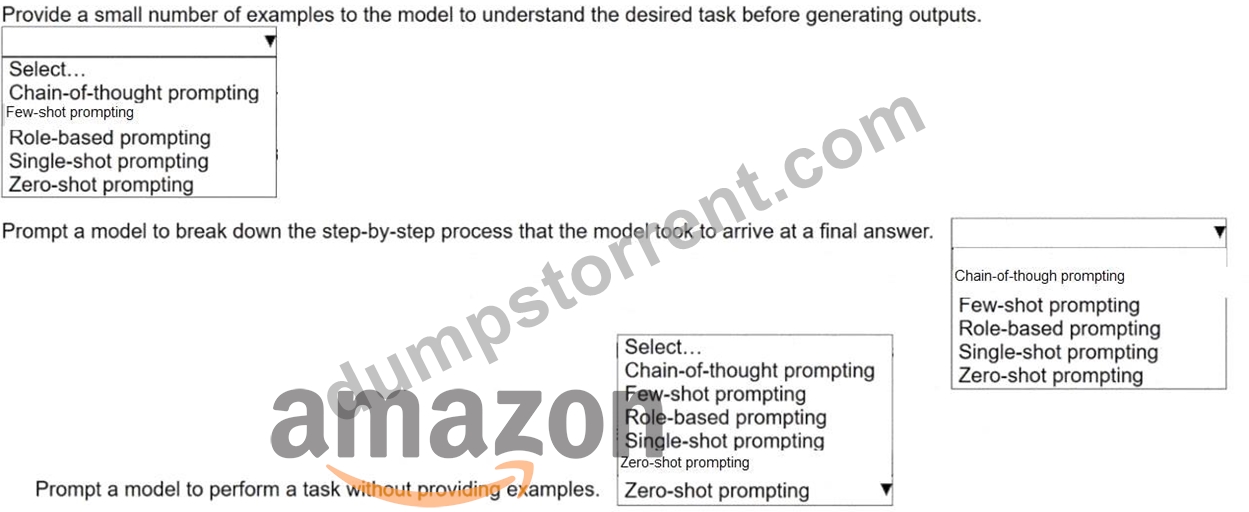
Answer:
Explanation: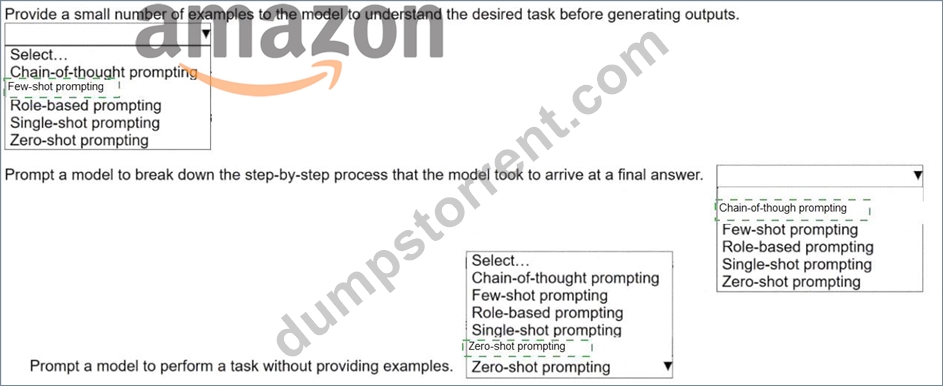
Explanation: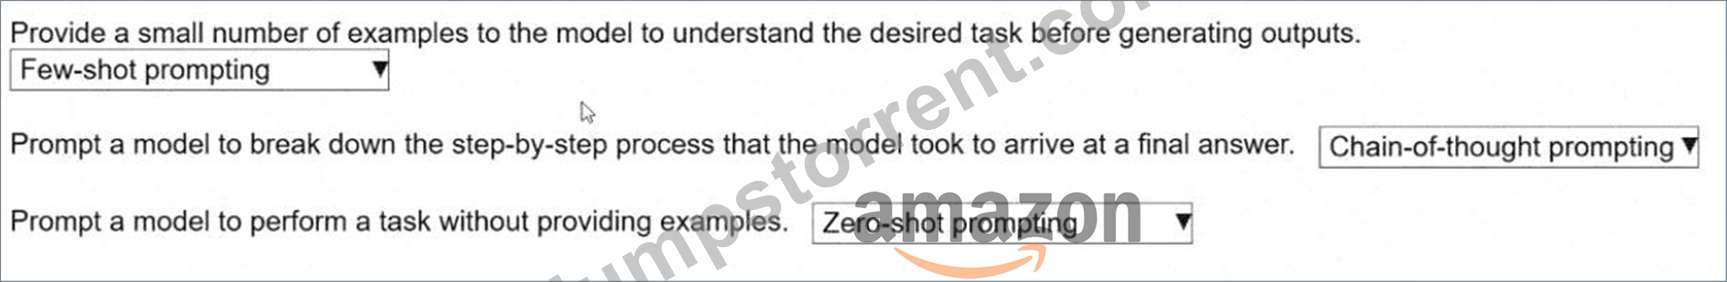
The verified selections are Few-shot prompting , Chain-of-thought prompting , and Zero-shot prompting . The first description matches few-shot prompting because AWS describes few-shot prompting as a technique that includes example outputs or demonstrations in the initial prompt so the model can understand the expected pattern before generating a response. The phrase "provide a small number of examples" is the key indicator.
A few-shot prompt gives the model limited examples of the desired task, format, or reasoning style, and the model uses those examples as context for the next output.
The second description matches chain-of-thought prompting . AWS describes chain-of-thought prompting as a technique that helps a model solve a problem by following a series of intermediate reasoning steps before reaching the final answer. The wording "break down the step-by-step process" directly points to chain-of- thought prompting. This method is commonly associated with reasoning, arithmetic, logic, planning, and multi-step problem solving because the prompt encourages the model to work through intermediate steps rather than immediately outputting a final answer.
The third description matches zero-shot prompting because AWS describes zero-shot prompting as asking the model to perform a task without providing examples in the prompt. The model relies only on the instruction and its pre-trained knowledge. The phrase "without providing examples" is the decisive clue.
Role-based prompting is not used here because none of the descriptions asks the model to act as a specific persona, job role, or domain expert, such as "Act as a financial analyst" or "You are a security engineer." Single-shot prompting is also not used because the first description says a "small number of examples," which indicates few-shot prompting, not exactly one example. Therefore, the three correct hotspot mappings are Few-shot prompting , Chain-of-thought prompting , and Zero-shot prompting .
NEW QUESTION # 141
A large retail bank wants to develop an ML system to help the risk management team decide on loan allocations for different demographics.
What must the bank do to develop an unbiased ML model?
Answer: D
Explanation:
Class imbalance in a training dataset can cause ML models to favor overrepresented groups, leading to biased predictions. The AWS AI Practitioner guide and SageMaker Clarify documentation emphasize the need to identify and mitigate class imbalance to ensure fairness and unbiased model outcomes.
* D is correct: By measuring class imbalance and adapting the training process (e.g., through oversampling, undersampling, or using class weights), organizations can improve fairness and reduce bias across demographic groups.
* A (reducing data size) could worsen bias by removing potentially useful diverse data.
* B (consistency with historical results) might reinforce existing biases.
* C (separate models) is not scalable and can introduce other fairness issues.
"To reduce bias, examine class imbalance in your training data and use techniques to ensure all groups are fairly represented." (Reference: AWS SageMaker Clarify: Mitigating Bias, AWS Responsible AI)
NEW QUESTION # 142
......
First and foremost, the pass rate of our AIF-C01 training guide among our customers has reached as high as 98% to 100%, which marks the highest pass rate in the field, we are waiting for you to be the next beneficiary. Second, you can get our AIF-C01 practice test only in 5 to 10 minutes after payment, which enables you to devote yourself to study with our AIF-C01 Exam Questions as soon as possible. Last but not least, you will get the privilege to enjoy free renewal of our AIF-C01 preparation materials during the whole year. All of the staffs in our company wish you early success.
Popular AIF-C01 Exams: https://www.dumpstorrent.com/AIF-C01-exam-dumps-torrent.html
BONUS!!! Download part of DumpsTorrent AIF-C01 dumps for free: https://drive.google.com/open?id=1HM6pGnQwUPPYIFOvn4pSLLcocvQvzGkm