P.S. Kostenlose 2026 Databricks Databricks-Certified-Professional-Data-Engineer Prüfungsfragen sind auf Google Drive freigegeben von EchteFrage verfügbar: https://drive.google.com/open?id=1coeiz0wNOjMZMdKP2Zs_QyeZlwR9YeyW
Wir EchteFrage haben uns seit Jahren um die Entwicklung der Software bemühen, die die Leute helfen, die in der IT-Branche bessere Arbeitsperspektive möchten, die Databricks Databricks-Certified-Professional-Data-Engineer Prüfung zu bestehen. Trotzdem es schon zahlreiche Databricks Databricks-Certified-Professional-Data-Engineer Prüfungsunterlagen auf dem Markt gibt, ist die Databricks Databricks-Certified-Professional-Data-Engineer Prüfungssoftware von uns EchteFrage am verlässlichsten. Es wird durch Praxis schon beweist, dass fast alle der Prüfungsteilnehmer, die unsere Software benutzt haben, Databricks Databricks-Certified-Professional-Data-Engineer Prüfung bestanden. Viele davon verwenden nur Ihre Freizeit für die Vorbereitung auf Databricks Databricks-Certified-Professional-Data-Engineer Prüfung. Die Zertifizierung zu erwerben überrascht Sie.
| Section | Weight | Objectives |
|---|---|---|
| Data Warehouse and Lakehouse Architecture | 15-20% | - Lakehouse architecture principles
|
| Delta Lake | 20-25% | - Delta Lake fundamentals
|
| Pipeline Development and Orchestration | 10-15% | - Databricks workflows
|
| Data Ingestion | 15-20% | - Batch ingestion methods
|
| Data Processing with Spark | 25-30% | - Python and SQL for data engineering
|
>> Databricks-Certified-Professional-Data-Engineer Antworten <<
EchteFrage bietet Ihnen die neuesten Schulungsunterlagen zur Databricks Databricks-Certified-Professional-Data-Engineer Zertifizierungsprüfung. Die fleißigen IT-Experten von EchteFrage aktualisieren ständig Schulungsunterlagen durch ihre eigene Kompetenz und Erfahrung, so dass die IT-Fachleute die Prüfung mühlos bestehen können. Das Databricks Databricks-Certified-Professional-Data-Engineer Zertifikat stellt eine immer wichtigere Stelle in der IT-Branche dar. Und immer mehr Leute haben sich an dieser Prüfung beteiligt. Und viele davon benutzen unsere Produkte von EchteFrage und haben die Databricks Databricks-Certified-Professional-Data-Engineer Zertifizierungsprüfung bestanden. Die Feedbacks von diesen Leute haben bewiesen, dass unsere Produkte von EchteFrage eher zuverlässig sind.
148. Frage
A data engineer has three notebooks in an ELT pipeline. The notebooks need to be executed in a specific order
for the pipeline to complete successfully. The data engineer would like to use Delta Live Tables to manage this
process.
Which of the following steps must the data engineer take as part of implementing this pipeline using Delta
Live Tables?
Antwort: E
149. Frage
Given the following error traceback (from display(df.select(3*"heartrate"))) which shows AnalysisException: cannot resolve 'heartrateheartrateheartrate', which statement describes the error being raised?
Antwort: B
Begründung:
Comprehensive and Detailed Explanation From Exact Extract:
Exact extract: "select() expects column names or Column expressions."
Exact extract: "Use col("name") (or df["name"]) to reference a column; Python string operations act on strings, not columns."
150. Frage
Given the following error traceback:
AnalysisException: cannot resolve ' heartrateheartrateheartrate ' given input columns:
[spark_catalog.database.table.device_id, spark_catalog.database.table.heartrate, spark_catalog.database.table.mrn, spark_catalog.database.table.time] The code snippet was:
display(df.select(3* " heartrate " ))
Which statement describes the error being raised?
Antwort: B
Begründung:
* Exact extract: "select() expects column names or Column expressions."
* Exact extract: "When using strings directly, Spark SQL interprets them as literal column names."
* Exact extract: "Python string operations, such as " colname " *3, return repeated strings, not column expressions." The expression 3* " heartrate " is Python string multiplication, which evaluates to " heartrateheartrateheartrate
" . The select() method interprets this as a literal column name. Since there is no column with that name in the DataFrame schema, Spark raises AnalysisException saying it cannot resolve that column. To correctly multiply a column by a scalar, one must use the column expression form:
from pyspark.sql.functions import col
df.select((col( " heartrate " ) * 3).alias( " heartrate_x3 " ))
This ensures Spark evaluates the arithmetic operation on the column instead of misinterpreting the string.
References: PySpark DataFrame select; PySpark Column expressions with col().
151. Frage
In order to facilitate near real-time workloads, a data engineer is creating a helper function to leverage the schema detection and evolution functionality of Databricks Auto Loader. The desired function will automatically detect the schema of the source directly, incrementally process JSON files as they arrive in a source directory, and automatically evolve the schema of the table when new fields are detected.
The function is displayed below with a blank: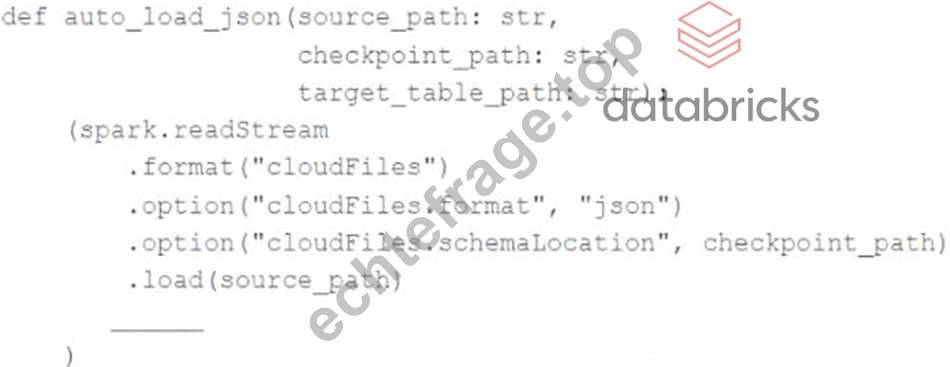
Which response correctly fills in the blank to meet the specified requirements?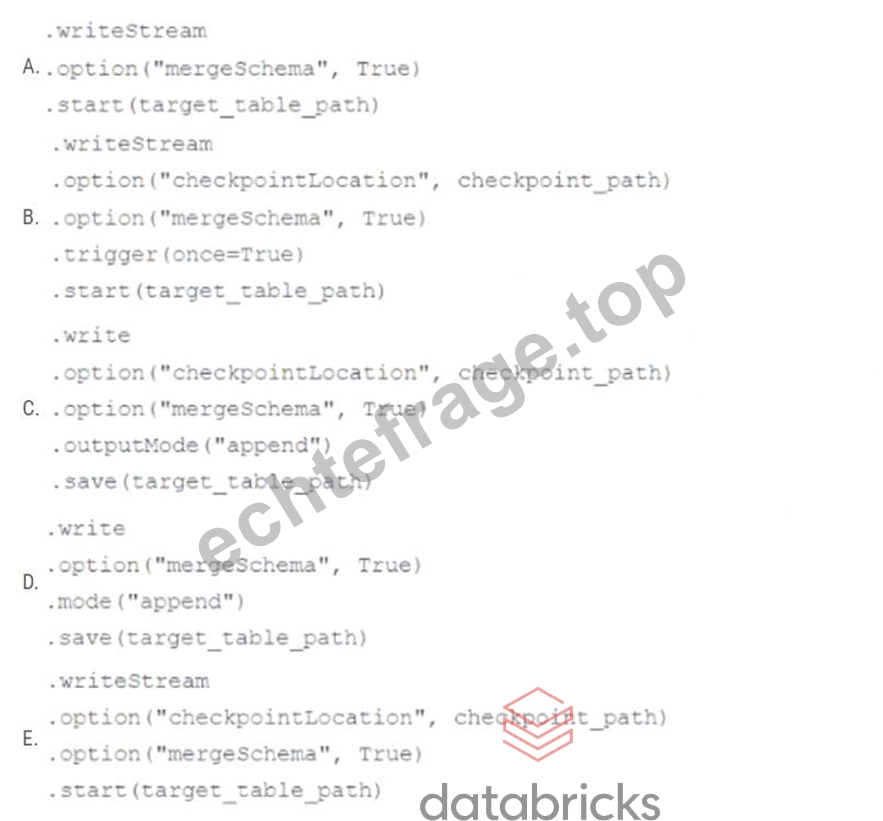
Antwort: E
Begründung:
Option B correctly fills in the blank to meet the specified requirements. Option B uses the "cloudFiles.
schemaLocation" option, which is required for the schema detection andevolution functionality of Databricks Auto Loader. Additionally, option B uses the "mergeSchema" option, which is required for the schema evolution functionality of Databricks Auto Loader. Finally, option B uses the "writeStream" method, which is required for the incremental processing of JSON files as they arrive in a source directory. The other options are incorrect because they either omit the required options, use the wrong method, or use the wrong format. References:
* Configure schema inference and evolution in Auto Loader: https://docs.databricks.com/en/ingestion
/auto-loader/schema.html
* Write streaming data: https://docs.databricks.com/spark/latest/structured-streaming/writing-streaming- data.html
152. Frage
Question-3: In machine learning, feature hashing, also known as the hashing trick (by analogy to the kernel
trick), is a fast and space-efficient way of vectorizing features (such as the words in a language), i.e., turning
arbitrary features into indices in a vector or matrix. It works by applying a hash function to the features and
using their hash values modulo the number of features as indices directly, rather than looking the indices up in
an associative array. So what is the primary reason of the hashing trick for building classifiers?
Antwort: A
Begründung:
Explanation
This hashed feature approach has the distinct advantage of requiring less memory and one less pass through
the training data, but it can make it much harder to reverse engineer vectors to determine which original
feature mapped to a vector location. This is because multiple features may hash to the same location. With
large vectors or with multiple locations per feature, this isn't a problem for accuracy but it can make it hard to
understand what a classifier is doing.
Models always have a coefficient per feature, which are stored in memory during model building. The hashing
trick collapses a high number of features to a small number which reduces the number of coefficients and thus
memory requirements. Noisy features are not removed; they are combined with other features and so still have
an impact.
The validity of this approach depends a lot on the nature of the features and problem domain; knowledge of
the domain is important to understand whether it is applicable or will likely produce poor results. While
hashing features may produce a smaller model, it will be one built from odd combinations of real-world
features, and so will be harder to interpret.
An additional benefit of feature hashing is that the unknown and unbounded vocabularies typical of word-like
variables aren't a problem.
153. Frage
......
Nach dem Entstehen der Dumps zur Databricks Databricks-Certified-Professional-Data-Engineer Zertifizierungsprüfung ist es kein Traum der IT-Fachleuten mehr, die Databricks Databricks-Certified-Professional-Data-Engineer Zertifizierungsprüfung zu bestehen. Die Qualität der Prüfungsfragen und Antworten zur Databricks Databricks-Certified-Professional-Data-Engineer Zertifizierungsprüfung von EchteFrage ist hoch. Die Ähnlichkeit mit den realen Fragen beträgt 95%. EchteFrage ist Ihnen doch besitzenswert. Wenn Sie die Produkte von EchteFrage wählen, heißt das, dass Sie sich gut auf die Databricks Databricks-Certified-Professional-Data-Engineer Zertifizierungsprüfung vorbereitet haben. Ohne Zweifel können Sie die Databricks Databricks-Certified-Professional-Data-Engineer Prüfung sicher bestehen.
Databricks-Certified-Professional-Data-Engineer Online Praxisprüfung: https://www.echtefrage.top/Databricks-Certified-Professional-Data-Engineer-deutsch-pruefungen.html
P.S. Kostenlose 2026 Databricks Databricks-Certified-Professional-Data-Engineer Prüfungsfragen sind auf Google Drive freigegeben von EchteFrage verfügbar: https://drive.google.com/open?id=1coeiz0wNOjMZMdKP2Zs_QyeZlwR9YeyW