DOWNLOAD the newest Exam4Docs AI-300 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1xop9TJ7om0cyAzmlDO96Oc7owGstAAsZ
When preparing to take the Operationalizing Machine Learning and Generative AI Solutions (AI-300) exam dumps, knowing where to start can be a little frustrating, but with Exam4Docs Microsoft AI-300 practice questions, you will feel fully prepared. Using our Microsoft AI-300 practice test software, you can prepare for the increased difficulty on Microsoft AI-300 Exam day. Plus, we have various question types and difficulty levels so that you can tailor your Operationalizing Machine Learning and Generative AI Solutions (AI-300) exam dumps preparation to your requirements.
| Section | Weight | Objectives |
|---|---|---|
| Design and implement a GenAIOps infrastructure | 20–25% | - Implement infrastructure for generative AI workloads
|
| Optimize generative AI systems and model performance | 15–20% | - Optimize model selection and configuration
|
| Implement machine learning model lifecycle and operations | 25–30% | - Deploy models to production
|
| Implement generative AI quality assurance and observability | 10–15% | - Monitor generative AI systems
|
| Design and implement an MLOps infrastructure | 15–20% | - Create and manage Machine Learning workspace resources and assets
|
First and foremost, in order to cater to the different needs of people from different countries in the international market, we have prepared three kinds of versions of our AI-300 learning questions in this website. Second, we can assure you that you will get the latest version of our AI-300 training materials for free from our company in the whole year after payment on AI-300 practice materials. Last but not least, we will provide the most considerate after sale service for our customers in twenty four hours a day seven days a week on our AI-300 exam questions.
NEW QUESTION # 50
Drag and Drop Question
A team operates a generative AI-powered customer support assistant built on Microsoft Foundry.
The application serves users globally and supports both real-time chat interactions and batch summarization jobs.
The team must ensure that the application continues to meet defined service-level objectives (SLO) as usage increases.
The team requires visibility into runtime behavior to identify performance regressions that affect the user experience and system capacity.
You need to select the performance metrics that meet the requirements.
Which performance metric should you monitor for each requirement? To answer, move the appropriate performance metrics to the correct requirements. You may use each performance metric once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.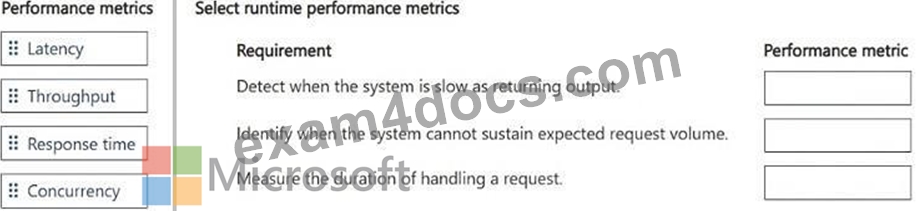
Answer:
Explanation: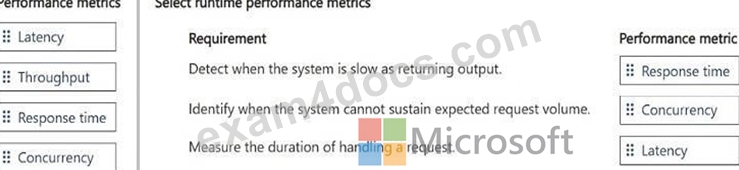
NEW QUESTION # 51
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear on the review screen.
You manage an Azure Machine Learning workspace. The Python script named script.py reads an argument named training_data. The training_data argument specifies the path to the training data in a file named dataset1.csv.
You plan to run the script.py Python script as a command job that trains a machine learning model.
You need to provide the command to pass the path for the dataset as a parameter value when you submit the script as a training job.
Solution: python train.py --training_data training_data
Does the solution meet the goal?
Answer: A
Explanation:
Correct:
* python script.py --training_data ${{inputs.training_data}}
The scipt is named script.py.
For the parameter use ${{inputs.training_data}}
Incorrect:
* python script.py --training_data dataset1.csv
* python script.py dataset1.csv
* python train.py --training_data training_data
Note: Read a TabularDataset, Example
In the Input object, specify the type as AssetTypes.MLTABLE, and mode as InputOutputModes.DIRECT:
* Details omitted*
job = command(
code="./src", # Local path where the code is stored
*-> command="python train.py --inputs ${{inputs.input_data}}",
inputs=my_job_inputs,
environment="<environment_name>:<version>",
compute="cpu-cluster",
)
Reference:
https://learn.microsoft.com/en-us/azure/machine-learning/how-to-read-write-data-v2
NEW QUESTION # 52
A real-time endpoint is deployed in Azure Machine Learning to serve predictions to a web application.
Users report intermittent failures and unexpected responses when calling the endpoint.
You need to identify the appropriate troubleshooting action for each reported issue.
Which troubleshooting action should you perform for each issue? To answer, move the appropriate troubleshooting actions to the correct issues. You may use each troubleshooting action once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content. NOTE: Each correct selection is worth one point.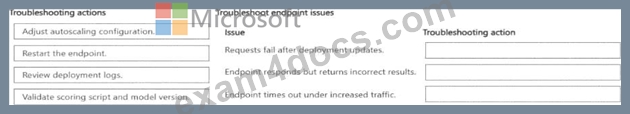
Answer:
Explanation: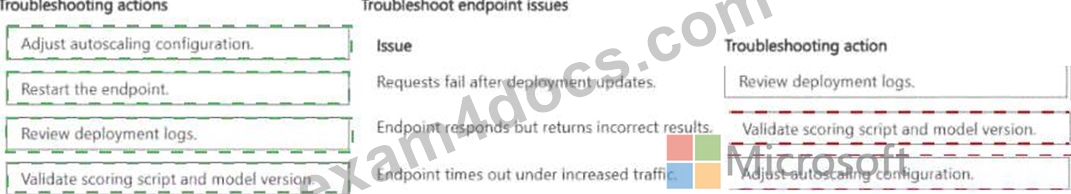
Explanation:
For deployment failures when containers do not start, review deployment logs in Azure ML Studio or use the CLI get-logs command to surface dependency installation errors, missing files, or scoring script import failures. For authentication errors such as 401 or 403 responses, check that client applications are using valid authentication keys or bearer tokens, as mismatched or expired credentials cause auth failures. For performance degradation and slow responses, review compute instance scaling configuration, since a surge in traffic saturates a fixed number of replicas causing queuing and high latency without autoscaling. For internal server errors such as HTTP 500, these typically originate in the scoring script, so inspect the init and run functions for unhandled exceptions and verify the environment has all required packages installed.
Microsoft Learn Reference Topic: Troubleshoot online endpoint deployment failures - Azure Machine Learning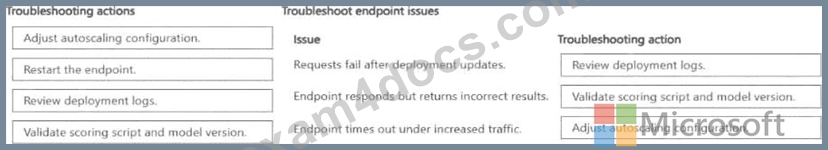
NEW QUESTION # 53
You have a Microsoft Foundry project.
You plan to use the Microsoft Foundry portal to fine-tune a base Azure OpenAI Service model that can accept both text and images as input.
You need to choose the suitable model.
Which model should you choose?
Answer: B
Explanation:
GPT-4o is OpenAI ' s multimodal model that accepts both text and image inputs natively. The ' o ' in GPT-4o stands for ' omni, ' reflecting its ability to process multiple modalities in a single inference call. It is available in Microsoft Foundry for both inference and fine-tuning, and it supports vision inputs alongside text prompts, making it the correct choice for any fine-tuning scenario requiring multimodal input. Davinci-002 (option A) is a legacy text-completion model with no vision capabilities and limited fine-tuning support for modern chat formats. GPT-3.5-Turbo (option C) is a text-only chat model that does not accept image inputs. GPT-4 (option D) has a standard version that is text-only; the vision variant GPT-4V is distinct from GPT-4o and has more limited fine-tuning availability in Foundry. For multimodal text plus image fine-tuning, GPT-4o is the only correct choice.
Microsoft Learn Reference Topic: Azure OpenAI Service models available for fine-tuning - GPT-4o multimodal capabilities
NEW QUESTION # 54
You are reviewing a dataset that will be used for an advanced fine-tuning job in Microsoft Foundry.
The fine-tuning job uses preference comparison data.
You review the following dataset excerpt.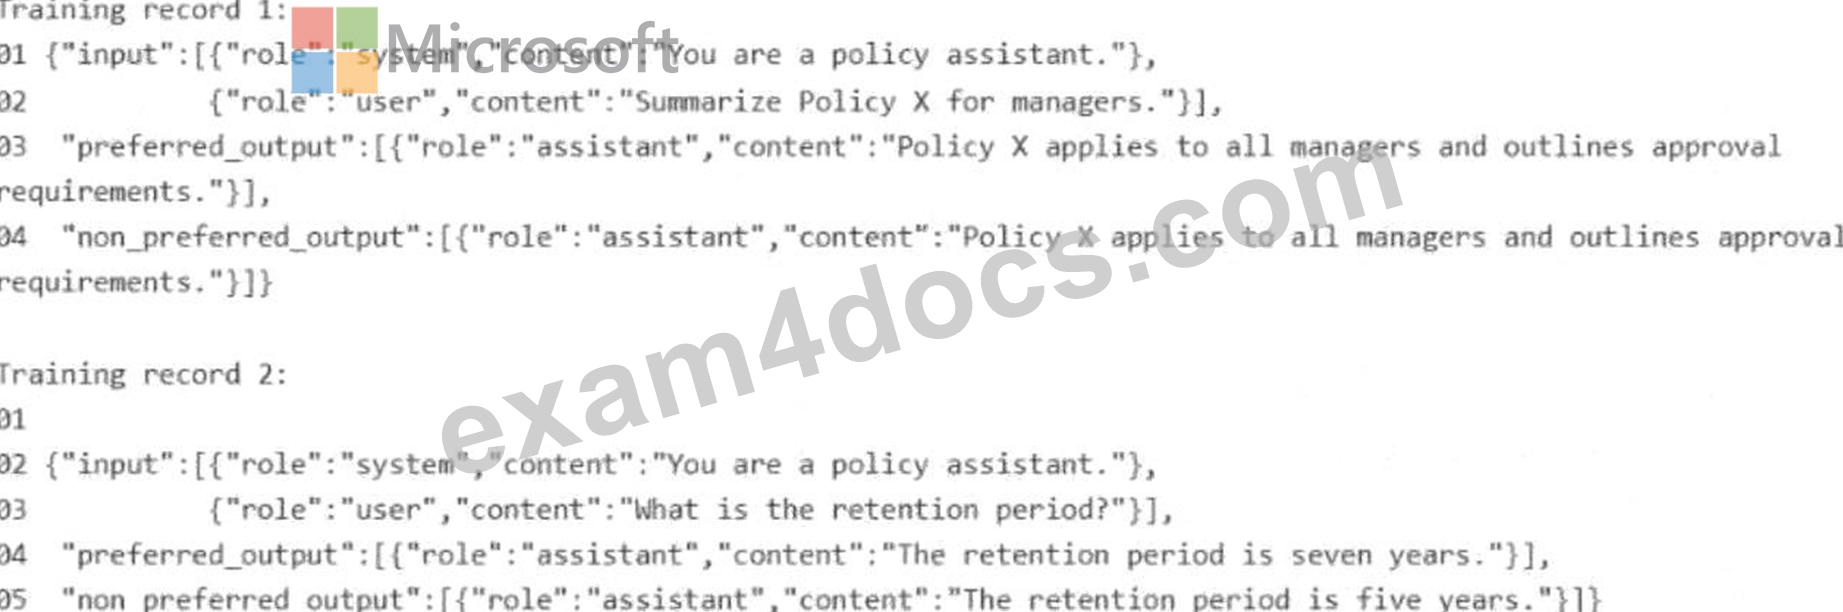
For each of the following statements, select Yes if the statement is true. Otherwise, select No . NOTE: Each correct selection is worth one point.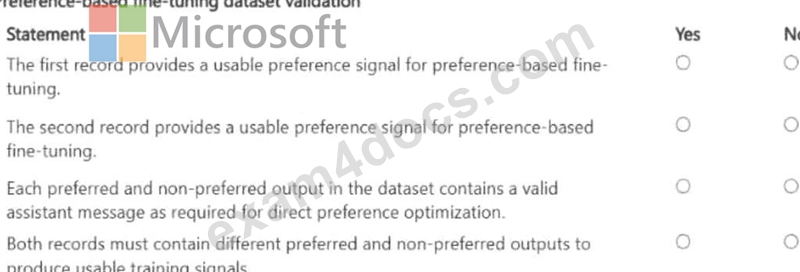
Answer:
Explanation: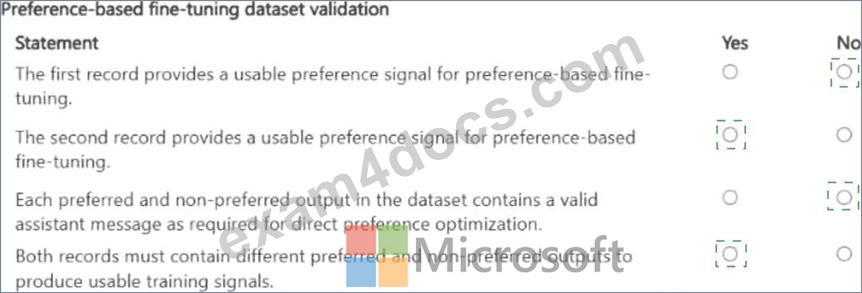
Explanation:
Preference comparison data with chosen versus rejected response pairs is the input format for Direct Preference Optimization (DPO) or RLHF-style fine-tuning - an advanced fine-tuning technique available in Microsoft Foundry. A valid DPO dataset record must have three fields: a prompt as the input, a chosen field containing the preferred response, and a rejected field containing the less preferred response. The file must be in JSONL format with UTF-8 encoding, where each line represents one complete preference pair. When evaluating statements about this dataset, mark True if the dataset contains all three required fields and chosen responses represent higher-quality outputs than rejected ones. Mark False if the format is incompatible with DPO requirements, if the required rejected field is missing, or if the chosen and rejected responses appear to be of equivalent quality with no clear preference signal.
Microsoft Learn Reference Topic: Advanced fine-tuning with preference data in Microsoft Foundry - DPO dataset format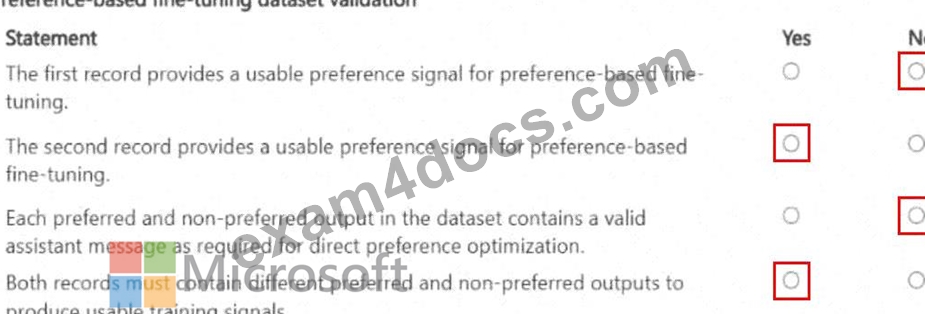
NEW QUESTION # 55
......
Many candidates compliment that Microsoft AI-300 study guide materials are best assistant and useful for qualification exams, they have no need to purchase other training courses or books to study, and only by practicing our Microsoft AI-300 Exam Braindumps several times before exam, they can pass exam in short time easily.
AI-300 Accurate Prep Material: https://www.exam4docs.com/AI-300-study-questions.html
BTW, DOWNLOAD part of Exam4Docs AI-300 dumps from Cloud Storage: https://drive.google.com/open?id=1xop9TJ7om0cyAzmlDO96Oc7owGstAAsZ