Simulation Certified-Data-Engineer-Professional Questions & Databricks Reliable Certified-Data-Engineer-Professional Test Prep: Databricks Certified Data Engineer Professional Latest Released

P.S. Free & New Certified-Data-Engineer-Professional dumps are available on Google Drive shared by PDFDumps: https://drive.google.com/open?id=12VtarPwAZmc6PV1x69iYhLoSya_4m2Sn
All the PDFDumps Databricks Certified-Data-Engineer-Professional practice questions are real and based on actual Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) exam topics. The web-based Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) practice test is compatible with all operating systems like Mac, IOS, Android, and Windows. Because of its browser-based Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) practice exam, it requires no installation to proceed further. Similarly, Chrome, IE, Firefox, Opera, Safari, and all the major browsers support the Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) practice test.
| Section | Objectives |
|---|
| Data Sharing and Federation | - Delta Sharing
- 1. Share live Lakehouse data with external computing platforms
- 2. Configure sharing with external platforms using the open sharing protocol
- 3. Configure Databricks-to-Databricks Sharing
- Lakehouse Federation
- 1. Configure Lakehouse Federation with appropriate governance
|
| Cost & Performance Optimisation | - Cost Optimization
- 1. Understand how Unity Catalog managed tables reduce operational overhead
- Delta Optimization
- 1. Understand deletion vectors and liquid clustering
- 2. Apply data skipping and file pruning techniques
- 3. Use Change Data Feed to address streaming table limitations and improve latency
- Query Performance
- 1. Identify inefficient joins and excessive data shuffling
- 2. Use Query Profile to identify performance bottlenecks
|
| Data Governance | - Metadata and Discoverability
- 1. Create and maintain descriptions and metadata for enterprise data
- Unity Catalog Permissions
- 1. Understand the Unity Catalog permission inheritance model
|
| Debugging and Deploying | - Debugging and Troubleshooting
- 1. Use Spark UI, cluster logs, system tables, and query profiles for diagnostics
- 2. Use Lakeflow Spark Declarative Pipelines event logs and Spark UI for debugging
- 3. Analyze errors and remediate failed job runs
- Deploying CI/CD
- 1. Integrate Git-based CI/CD workflows using Databricks Git Folders
- 2. Build and deploy Databricks resources using Databricks Asset Bundles
|
| Developing Code for Data Processing using Python and SQL | - Using Python and Tools for Development
- 1. Develop User-Defined Functions using Pandas/Python UDFs
- 2. Manage and troubleshoot third-party library installations and dependencies
- 3. Design and implement scalable Python project structures optimized for Databricks Asset Bundles
- Building and Testing ETL Pipelines
- 1. Compare Spark Structured Streaming and Lakeflow Spark Declarative Pipelines
- 2. Create and automate ETL workloads using Jobs through UI, APIs, and CLI
- 3. Configure environments, dependencies, memory, and retry behavior
- 4. Use APPLY CHANGES APIs for change data capture
- 5. Build production-ready batch and streaming pipelines using Lakeflow Spark Declarative Pipelines and Auto Loader
- 6. Develop unit and integration tests for data processing code
- 7. Use control flow operators in pipeline components
- 8. Compare streaming tables and materialized views
|
| Monitoring and Alerting | - Monitoring
- 1. Use Query Profiler and Spark UI to monitor workloads
- 2. Use Databricks REST APIs and CLI for monitoring jobs and pipelines
- 3. Use Lakeflow Spark Declarative Pipelines event logs for monitoring
- 4. Use system tables for resource, cost, audit, and workload monitoring
- Alerting
- 1. Configure Lakeflow Jobs notifications for job status and performance issues
- 2. Use SQL Alerts for data quality monitoring
|
| Data Modelling | - Scalable Data Models
- 1. Design and implement scalable data models using Delta Lake
- 2. Understand Liquid Clustering versus partitioning and Z-Ordering
- 3. Optimize data layout using Liquid Clustering
- Dimensional Modelling
- 1. Design dimensional models for analytical workloads
|
| Data Transformation, Cleansing, and Quality | - Data Quality
- 1. Apply data quality controls using Lakeflow Spark Declarative Pipelines or Auto Loader
- 2. Develop data quarantining processes for invalid data
- Advanced Data Transformation
- 1. Apply window functions, joins, and aggregations to large datasets
- 2. Write efficient Spark SQL and PySpark transformations
|
| Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Ingest data from message buses and cloud storage
- 2. Build append-only pipelines for batch and streaming data using Delta
- 3. Ingest Delta Lake, Parquet, ORC, Avro, JSON, CSV, XML, Text, and Binary data
|
| Ensuring Data Security and Compliance | - Data Security
- 1. Use row filters and column masks for sensitive data
- 2. Use ACLs to secure workspace objects and enforce least privilege
- 3. Apply anonymization and pseudonymization techniques
- Compliance
- 1. Develop data purging solutions according to data retention policies
- 2. Implement pipelines that detect and mask personally identifiable information
|
>> Simulation Certified-Data-Engineer-Professional Questions <<
Reliable Certified-Data-Engineer-Professional Test Prep | Certified-Data-Engineer-Professional Hot Questions
Our evaluation system for Certified-Data-Engineer-Professional test material is smart and very powerful. First of all, our researchers have made great efforts to ensure that the data scoring system of our Certified-Data-Engineer-Professional test questions can stand the test of practicality. Once you have completed your study tasks and submitted your training results, the evaluation system will begin to quickly and accurately perform statistical assessments of your marks on the Certified-Data-Engineer-Professional Exam Torrent. You only need to spend 20 to 30 hours on practicing and consolidating of our Certified-Data-Engineer-Professional learning material, you will have a good result. After years of development practice, our Certified-Data-Engineer-Professional test torrent is absolutely the best. You will embrace a better future if you choose our Certified-Data-Engineer-Professional exam materials.
Databricks Certified Data Engineer Professional Sample Questions (Q81-Q86):
NEW QUESTION # 81
Which of the following is true of Delta Lake and the Lakehouse?
- A. Because Parquet compresses data row by row. strings will only be compressed when a character is repeated multiple times.
- B. Primary and foreign key constraints can be leveraged to ensure duplicate values are never entered into a dimension table.
- C. Views in the Lakehouse maintain a valid cache of the most recent versions of source tables at all times.
- D. Delta Lake automatically collects statistics on the first 32 columns of each table which are leveraged in data skipping based on query filters.
- E. Z-order can only be applied to numeric values stored in Delta Lake tables
Answer: D
Explanation:
Delta Lake automatically collects statistics on the first 32 columns of each table, which are leveraged in data skipping based on query filters. Data skipping is a performance optimization technique that aims to avoid reading irrelevant data from the storage layer. By collecting statistics such as min/max values, null counts, and bloom filters, Delta Lake can efficiently prune unnecessary files or partitions from the query plan. This can significantly improve the query performance and reduce the I/O cost.
NEW QUESTION # 82
The data science team has created and logged a production model using MLflow. The model accepts a list of column names and returns a new column of type DOUBLE.
The following code correctly imports the production model, loads the customers table containing the customer_id key column into a DataFrame, and defines the feature columns needed for the model.
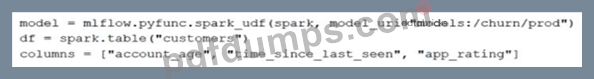
Which code block will output a DataFrame with the schema "customer_id LONG, predictions DOUBLE"?
- A. df.select("customer_id", pandas_udf(model, columns).alias("predictions"))
- B. df.select("customer_id", model(*columns).alias("predictions"))
- C. df.map(lambda x:model(x[columns])).select("customer_id, predictions")
- D. model.predict(df, columns)
- E. df.apply(model, columns).select("customer_id, predictions")
Answer: B
Explanation:
This code block applies the Spark UDF created from the MLflow model to the DataFrame df by selecting the existing customer_id column and the new column produced by the model, which is aliased to predictions. The model(*columns) part is where the UDF is applied to the columns specified in the columns list, and alias("predictions") is used to name the output column of the model's predictions. This will result in a DataFrame with the desired schema: "customer_id LONG, predictions DOUBLE".
NEW QUESTION # 83
A DLT pipeline includes the following streaming tables:
Raw_lot ingest raw device measurement data from a heart rate tracking device.
Bpm_stats incrementally computes user statistics based on BPM measurements from raw_lot.
How can the data engineer configure this pipeline to be able to retain manually deleted or updated records in the raw_iot table while recomputing the downstream table when a pipeline update is run?
- A. Set the SkipChangeCommits flag to true raw_lot
- B. Set the skipChangeCommits flag to true on bpm_stats
- C. Set the pipelines, reset, allowed property to false on raw_iot
- D. Set the pipelines, reset, allowed property to false on bpm_stats
Answer: C
Explanation:
In Databricks Lakehouse, to retain manually deleted or updated records in the raw_iot table while recomputing downstream tables when a pipeline update is run, the property pipelines.reset.allowed should be set to false. This property prevents the system from resetting the state of the table, which includes the removal of the history of changes, during a pipeline update. By keeping this property as false, any changes to the raw_iot table, including manual deletes or updates, are retained, and recomputation of downstream tables, such as bpm_stats, can occur with the full history of data changes intact.
NEW QUESTION # 84
A data engineering team is configuring access controls in Databricks Unity Catalog. They grant the SELECT privilege on the sales catalog to the analyst_group, expecting that members of this group will automatically have SELECT access to all current and future schemas, tables, and views within the catalog. What describes the privilege inheritance behavior in Unity Catalog?
- A. Privileges granted at the schema level override any catalog-level privileges and prevent access unless explicitly revoked.
- B. Granting SELECT on a catalog automatically applies SELECT to all current and future schemas, tables, and views within that catalog.
- C. Granting SELECT at the catalog level applies to existing schemas and tables but not to those created in the future.
- D. Privileges in Unity Catalog do not cascade; SELECT must be explicitly granted on each schema and table, even if granted at the catalog level.
Answer: D
Explanation:
In Unity Catalog, privileges are non-cascading--meaning that granting a privilege (like SELECT) on a catalog does not automatically grant the same privilege on contained objects (schemas, tables, or views). Each object type has its own independent access control hierarchy.
According to the Databricks access control documentation: "Privileges do not automatically cascade from catalog to schema or table levels." Administrators must explicitly grant privileges on each level if users need access across objects. This design ensures tighter governance and least-privilege enforcement. Therefore, option B correctly describes Unity Catalog's privilege model, while A and D incorrectly imply automatic inheritance.
NEW QUESTION # 85
The Databricks workspace administrator has configured interactive clusters for each of the data engineering groups. To control costs, clusters are set to terminate after 30 minutes of inactivity.
Each user should be able to execute workloads against their assigned clusters at any time of the day.
Assuming users have been added to a workspace but not granted any permissions, which of the following describes the minimal permissions a user would need to start and attach to an already configured cluster.
- A. "Can Restart" privileges on the required cluster
- B. Cluster creation allowed. "Can Restart" privileges on the required cluster
- C. Cluster creation allowed. "Can Attach To" privileges on the required cluster
- D. Workspace Admin privileges, cluster creation allowed. "Can Attach To" privileges on the required cluster
- E. "Can Manage" privileges on the required cluster
Answer: A
Explanation:
https://learn.microsoft.com/en-us/azure/databricks/security/auth-authz/access-control/cluster-acl
https://docs.databricks.com/en/security/auth-authz/access-control/cluster-acl.html
NEW QUESTION # 86
......
Our Certified-Data-Engineer-Professional exam questions are designed from the customer's perspective, and experts that we employed will update our Certified-Data-Engineer-Professional learning materials according to changing trends to ensure the high quality of the Certified-Data-Engineer-Professional practice materials. What are you still waiting for? Choosing our Certified-Data-Engineer-Professional guide questions and work for getting the certificate, you will make your life more colorful and successful.
Reliable Certified-Data-Engineer-Professional Test Prep: https://www.pdfdumps.com/Certified-Data-Engineer-Professional-valid-exam.html
- 2026 Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional Fantastic Simulation Questions 🐟 Search for ➡ Certified-Data-Engineer-Professional ️⬅️ and download it for free on ➥ www.practicevce.com 🡄 website 😦Reliable Certified-Data-Engineer-Professional Braindumps
- Reliable Certified-Data-Engineer-Professional Mock Test 📚 Certified-Data-Engineer-Professional Sample Questions Pdf 💳 Latest Certified-Data-Engineer-Professional Exam Forum 🤥 Open ➥ www.pdfvce.com 🡄 enter ▷ Certified-Data-Engineer-Professional ◁ and obtain a free download 😺Latest Test Certified-Data-Engineer-Professional Discount
- Certified-Data-Engineer-Professional Valid Study Materials 😡 Certified-Data-Engineer-Professional Valid Exam Registration 🚝 Latest Certified-Data-Engineer-Professional Exam Forum 🐎 Copy URL ⮆ www.validtorrent.com ⮄ open and search for 【 Certified-Data-Engineer-Professional 】 to download for free 🦞Certified-Data-Engineer-Professional Valid Exam Registration
- Valid Certified-Data-Engineer-Professional Exam Syllabus 👟 Certified-Data-Engineer-Professional Valid Exam Registration 🚄 Certified-Data-Engineer-Professional Exam Simulator Fee ⛷ Search for { Certified-Data-Engineer-Professional } and obtain a free download on ⏩ www.pdfvce.com ⏪ ⛴Reliable Certified-Data-Engineer-Professional Mock Test
- Certified-Data-Engineer-Professional Exam Simulator Fee 🐨 Certified-Data-Engineer-Professional Real Braindumps 🦉 Latest Test Certified-Data-Engineer-Professional Discount 🧑 Search for ⮆ Certified-Data-Engineer-Professional ⮄ and download it for free on 《 www.prepawaypdf.com 》 website 🥂Certified-Data-Engineer-Professional Valid Exam Camp Pdf
- Vce Certified-Data-Engineer-Professional Torrent 〰 Vce Certified-Data-Engineer-Professional Torrent ⏹ Certified-Data-Engineer-Professional Valid Study Materials ⏲ Search on ➡ www.pdfvce.com ️⬅️ for ▛ Certified-Data-Engineer-Professional ▟ to obtain exam materials for free download 🚜Certified-Data-Engineer-Professional Valid Study Materials
- Databricks Certified-Data-Engineer-Professional Exam Practice Questions are Real and Verified By Experts 🦄 Search for ☀ Certified-Data-Engineer-Professional ️☀️ and download it for free immediately on ✔ www.vce4dumps.com ️✔️ 😐Certified-Data-Engineer-Professional Valid Study Materials
- Certified-Data-Engineer-Professional Passing Score 🦲 Certified-Data-Engineer-Professional Original Questions 🏃 Certified-Data-Engineer-Professional Passing Score 🚑 Copy URL “ www.pdfvce.com ” open and search for ⮆ Certified-Data-Engineer-Professional ⮄ to download for free 🎊Certified-Data-Engineer-Professional Reliable Test Guide
- Certified-Data-Engineer-Professional Valid Dumps Pdf 🦐 Reliable Certified-Data-Engineer-Professional Braindumps 🥱 Certified-Data-Engineer-Professional Original Questions 👜 Easily obtain ▛ Certified-Data-Engineer-Professional ▟ for free download through ▶ www.vce4dumps.com ◀ 🦼Valid Certified-Data-Engineer-Professional Exam Syllabus
- Reliable Certified-Data-Engineer-Professional Braindumps 👨 Latest Test Certified-Data-Engineer-Professional Discount 🍢 Certified-Data-Engineer-Professional Valid Study Materials 💥 Immediately open [ www.pdfvce.com ] and search for ➤ Certified-Data-Engineer-Professional ⮘ to obtain a free download 🍌Latest Test Certified-Data-Engineer-Professional Discount
- 100% Pass Quiz 2026 Databricks Certified-Data-Engineer-Professional: Authoritative Simulation Databricks Certified Data Engineer Professional Questions 📆 Open ☀ www.practicevce.com ️☀️ enter ➡ Certified-Data-Engineer-Professional ️⬅️ and obtain a free download 🙉Certified-Data-Engineer-Professional Passing Score
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, disqus.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, Disposable vapes
P.S. Free & New Certified-Data-Engineer-Professional dumps are available on Google Drive shared by PDFDumps: https://drive.google.com/open?id=12VtarPwAZmc6PV1x69iYhLoSya_4m2Sn