Free Download Certified-Data-Engineer-Professional Valid Test Topics & High-quality Certified-Data-Engineer-Professional Latest Exam Tips Ensure You a High Passing Rate

The Channel Partner Program Databricks Certified Data Engineer Professional Certified-Data-Engineer-Professional certification is a valuable credential earned by individuals to validate their skills and competence to perform certain job tasks. Your Databricks Certified Data Engineer Professional Certified-Data-Engineer-Professional Certification is usually displayed as proof that you’ve been trained, educated, and prepared to meet the specific requirement for your professional role.
| Section | Objectives |
|---|
| Ensuring Data Security and Compliance | - Data Security
- 1. Use row filters and column masks for sensitive data
- 2. Apply anonymization and pseudonymization techniques
- 3. Use ACLs to secure workspace objects and enforce least privilege
- Compliance
- 1. Implement pipelines that detect and mask personally identifiable information
- 2. Develop data purging solutions according to data retention policies
|
| Developing Code for Data Processing using Python and SQL | - Building and Testing ETL Pipelines
- 1. Create and automate ETL workloads using Jobs through UI, APIs, and CLI
- 2. Compare streaming tables and materialized views
- 3. Use control flow operators in pipeline components
- 4. Configure environments, dependencies, memory, and retry behavior
- 5. Build production-ready batch and streaming pipelines using Lakeflow Spark Declarative Pipelines and Auto Loader
- 6. Use APPLY CHANGES APIs for change data capture
- 7. Develop unit and integration tests for data processing code
- 8. Compare Spark Structured Streaming and Lakeflow Spark Declarative Pipelines
- Using Python and Tools for Development
- 1. Manage and troubleshoot third-party library installations and dependencies
- 2. Develop User-Defined Functions using Pandas/Python UDFs
- 3. Design and implement scalable Python project structures optimized for Databricks Asset Bundles
|
| Cost & Performance Optimisation | - Delta Optimization
- 1. Apply data skipping and file pruning techniques
- 2. Use Change Data Feed to address streaming table limitations and improve latency
- 3. Understand deletion vectors and liquid clustering
- Query Performance
- 1. Identify inefficient joins and excessive data shuffling
- 2. Use Query Profile to identify performance bottlenecks
- Cost Optimization
- 1. Understand how Unity Catalog managed tables reduce operational overhead
|
| Debugging and Deploying | - Deploying CI/CD
- 1. Integrate Git-based CI/CD workflows using Databricks Git Folders
- 2. Build and deploy Databricks resources using Databricks Asset Bundles
- Debugging and Troubleshooting
- 1. Analyze errors and remediate failed job runs
- 2. Use Spark UI, cluster logs, system tables, and query profiles for diagnostics
- 3. Use Lakeflow Spark Declarative Pipelines event logs and Spark UI for debugging
|
| Data Sharing and Federation | - Lakehouse Federation
- 1. Configure Lakehouse Federation with appropriate governance
- Delta Sharing
- 1. Share live Lakehouse data with external computing platforms
- 2. Configure sharing with external platforms using the open sharing protocol
- 3. Configure Databricks-to-Databricks Sharing
|
| Data Modelling | - Dimensional Modelling
- 1. Design dimensional models for analytical workloads
- Scalable Data Models
- 1. Optimize data layout using Liquid Clustering
- 2. Design and implement scalable data models using Delta Lake
- 3. Understand Liquid Clustering versus partitioning and Z-Ordering
|
| Data Governance | - Metadata and Discoverability
- 1. Create and maintain descriptions and metadata for enterprise data
- Unity Catalog Permissions
- 1. Understand the Unity Catalog permission inheritance model
|
| Monitoring and Alerting | - Alerting
- 1. Use SQL Alerts for data quality monitoring
- 2. Configure Lakeflow Jobs notifications for job status and performance issues
- Monitoring
- 1. Use system tables for resource, cost, audit, and workload monitoring
- 2. Use Lakeflow Spark Declarative Pipelines event logs for monitoring
- 3. Use Databricks REST APIs and CLI for monitoring jobs and pipelines
- 4. Use Query Profiler and Spark UI to monitor workloads
|
| Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Ingest data from message buses and cloud storage
- 2. Build append-only pipelines for batch and streaming data using Delta
- 3. Ingest Delta Lake, Parquet, ORC, Avro, JSON, CSV, XML, Text, and Binary data
|
| Data Transformation, Cleansing, and Quality | - Advanced Data Transformation
- 1. Apply window functions, joins, and aggregations to large datasets
- 2. Write efficient Spark SQL and PySpark transformations
- Data Quality
- 1. Develop data quarantining processes for invalid data
- 2. Apply data quality controls using Lakeflow Spark Declarative Pipelines or Auto Loader
|
>> Certified-Data-Engineer-Professional Valid Test Topics <<
Certified-Data-Engineer-Professional Latest Exam Tips & New Certified-Data-Engineer-Professional Learning Materials
Nowadays, online shopping has been greatly developed, but because of the fear of some uncontrollable problems after payment, there are still many people don't trust to buy things online, especially electronic products. But you don't have to worry about this when buying our Certified-Data-Engineer-Professional Actual Exam. Not only will we fully consider for customers before and during the purchase on our Certified-Data-Engineer-Professional practice guide, but we will also provide you with warm and thoughtful service on the Certified-Data-Engineer-Professional training guide.
Databricks Certified Data Engineer Professional Sample Questions (Q100-Q105):
NEW QUESTION # 100
To identify the top users consuming compute resources, a data engineering team needs to monitor usage within their Databricks workspace for better resource utilization and cost control.
The team decided to use Databricks system tables, available under the System catalog in Unity Catalog, to gain detailed visibility into workspace activity. Which SQL query should the team run from the System catalog to achieve this?
- A. SELECT sku_name,
identity_metadata.created_by AS user_email,
COUNT(usage_quantity) AS total_dbus
FROM system.billing.usage
GROUP BY user_email, sku_name
ORDER BY total_dbus DESC
LIMIT 10 - B. SELECT identity_metadata.run_as AS user_email,
SUM(usage_quantity) AS total_dbus
FROM system.billing.usage
GROUP BY user_email
ORDER BY total_dbus DESC
LIMIT 10 - C. SELECT sku_name,
identity_metadata.created_by AS user_email,
SUM(usage_quantity * usage_unit) AS total_dbus
FROM system.billing.usage
GROUP BY user_email, sku_name
ORDER BY total_dbus DESC
LIMIT 10 - D. SELECT sku_name,
usage_metadata.run_name AS user_email,
SUM(usage_quantity) AS total_dbus
FROM system.billing.usage
GROUP BY user_email, sku_name
ORDER BY total_dbus DESC
LIMIT 10
Answer: B
Explanation:
The system.billing.usage table in the Unity Catalog System schema provides detailed usage metrics for each workload in the workspace. The field identity_metadata.run_as identifies the user or service principal under which the job or query executed. Summing usage_quantity provides total DBU (Databricks Unit) consumption per user. According to Databricks documentation, this table is the authoritative source for monitoring workspace cost drivers, showing compute SKU, user, and DBU consumption over time. Grouping by identity_metadata.run_as and summing usage_quantity produces the correct aggregation to determine top users. Other queries use non- existent or incorrect fields (created_by, run_name, or multiplied usage quantities), which do not reflect actual billing metrics.
NEW QUESTION # 101
A Delta Lake table was created with the below query:
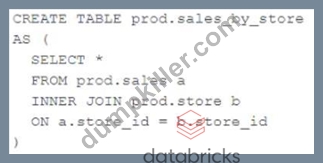
Consider the following query:
DROP TABLE prod.sales_by_store
If this statement is executed by a workspace admin, which result will occur?
- A. Nothing will occur until a COMMIT command is executed.
- B. The table will be removed from the catalog but the data will remain in storage.
- C. The table will be removed from the catalog and the data will be deleted.
- D. Data will be marked as deleted but still recoverable with Time Travel.
- E. An error will occur because Delta Lake prevents the deletion of production data.
Answer: C
Explanation:
When a table is dropped in Delta Lake, the table is removed from the catalog and the data is deleted. This is because Delta Lake is a transactional storage layer that provides ACID guarantees. When a table is dropped, the transaction log is updated to reflect the deletion of the table and the data is deleted from the underlying storage.
NEW QUESTION # 102
A data engineer deploys a multi-task Databricks job that orchestrates three notebooks. One task intermittently fails with Exit Code 1 but succeeds on retry. The engineer needs to collect detailed logs for the failing attempts, including stdout/stderr and cluster lifecycle context, and share them with the platform team. What steps the data engineer needs to follow using built-in tools?
- A. Use the notebook interactive debugger to re-run the entire multi-task job, and capture step- through traces for the failing task.
- B. From the job run details page, export the job's logs or configure log delivery; then retrieve the compute driver logs and event logs from the compute details page to correlate stdout/stderr with cluster events.
- C. Download worker logs directly from the Spark UI and ignore driver logs, as worker logs contain stdout/stderr for all tasks and cluster events.
- D. Export the notebook run results to HTML; this bundle includes complete stdout, stderr, and cluster event history across all tasks.
Answer: B
Explanation:
The recommended way to troubleshoot and collect detailed job logs is through the Job Run Details page in Databricks. From there, engineers can export run logs or configure automatic log delivery to a storage destination. The driver and event logs available under compute details provide stdout, stderr, and cluster lifecycle context required for root-cause analysis.
NEW QUESTION # 103
The data engineer team has been tasked with configured connections to an external database that does not have a supported native connector with Databricks. The external database already has data security configured by group membership. These groups map directly to user group already created in Databricks that represent various teams within the company. A new login credential has been created for each group in the external database. The Databricks Utilities Secrets module will be used to make these credentials available to Databricks users. Assuming that all the credentials are configured correctly on the external database and group membership is properly configured on Databricks, which statement describes how teams can be granted the minimum necessary access to using these credentials?
- A. "Read" permissions should be set on a secret scope containing only those credentials that will be used by a given team.
- B. "Manage" permission should be set on a secret scope containing only those credentials that will be used by a given team.
- C. No additional configuration is necessary as long as all users are configured as administrators in the workspace where secrets have been added.
- D. "Read'' permissions should be set on a secret key mapped to those credentials that will be used by a given team.
Answer: A
Explanation:
In Databricks, using the Secrets module allows for secure management of sensitive information such as database credentials. Granting 'Read' permissions on a secret key that maps to database credentials for a specific team ensures that only members of that team can access these credentials. This approach aligns with the principle of least privilege, granting users the minimum level of access required to perform their jobs, thus enhancing security.
NEW QUESTION # 104
Although the Databricks Utilities Secrets module provides tools to store sensitive credentials and avoid accidentally displaying them in plain text users should still be careful with which credentials are stored here and which users have access to using these secrets.
Which statement describes a limitation of Databricks Secrets?
- A. Account administrators can see all secrets in plain text by logging on to the Databricks Accounts console.
- B. Because the SHA256 hash is used to obfuscate stored secrets, reversing this hash will display the value in plain text.
- C. Iterating through a stored secret and printing each character will display secret contents in plain text.
- D. Secrets are stored in an administrators-only table within the Hive Metastore; database administrators have permission to query this table by default.
- E. The Databricks REST API can be used to list secrets in plain text if the personal access token has proper credentials.
Answer: E
Explanation:
This is the correct answer because it describes a limitation of Databricks Secrets. Databricks Secrets is a module that provides tools to store sensitive credentials and avoid accidentally displaying them in plain text. Databricks Secrets allows creating secret scopes, which are collections of secrets that can be accessed by users or groups. Databricks Secrets also allows creating and managing secrets using the Databricks CLI or the Databricks REST API. However, a limitation of Databricks Secrets is that the Databricks REST API can be used to list secrets in plain text if the personal access token has proper credentials. Therefore, users should still be careful with which credentials are stored in Databricks Secrets and which users have access to using these secrets.
NEW QUESTION # 105
......
The clients can have a free download and tryout of our Certified-Data-Engineer-Professional test practice dump before they decide to buy our products. They can use our products immediately after they pay for the Certified-Data-Engineer-Professional test practice dump successfully. If the clients are unlucky to fail in the test we will refund them as quickly as we can. There are so many advantages of our products that we can’t summarize them with several simple words. You’d better look at the introduction of our Certified-Data-Engineer-Professional Exam Questions in detail as follow by yourselves.
Certified-Data-Engineer-Professional Latest Exam Tips: https://www.dumpkiller.com/Certified-Data-Engineer-Professional_braindumps.html
- Certified-Data-Engineer-Professional Best Vce 🐾 Reliable Certified-Data-Engineer-Professional Test Camp 🖱 Certified-Data-Engineer-Professional Latest Test Sample 🦜 Search on ⇛ www.practicevce.com ⇚ for ➥ Certified-Data-Engineer-Professional 🡄 to obtain exam materials for free download 🤣New Certified-Data-Engineer-Professional Exam Notes
- Certified-Data-Engineer-Professional Reliable Exam Price ♻ Certification Certified-Data-Engineer-Professional Exam 🕜 Certified-Data-Engineer-Professional Discount 🎻 Search for ➥ Certified-Data-Engineer-Professional 🡄 and download it for free on “ www.pdfvce.com ” website 🧁Test Certified-Data-Engineer-Professional Collection
- Certified-Data-Engineer-Professional Exam Training 🪓 Certified-Data-Engineer-Professional Reliable Exam Answers 🔟 Certified-Data-Engineer-Professional Exam Training 🕠 Download 《 Certified-Data-Engineer-Professional 》 for free by simply entering ☀ www.pdfdumps.com ️☀️ website 🦅New Certified-Data-Engineer-Professional Mock Exam
- New Certified-Data-Engineer-Professional Mock Exam 🦋 Certified-Data-Engineer-Professional Discount 🟢 Online Certified-Data-Engineer-Professional Bootcamps 🎦 Search for ➡ Certified-Data-Engineer-Professional ️⬅️ and download it for free on ⏩ www.pdfvce.com ⏪ website 💌New Certified-Data-Engineer-Professional Mock Exam
- Certified-Data-Engineer-Professional Prep Training - Certified-Data-Engineer-Professional Study Guide - Certified-Data-Engineer-Professional Test Pdf 💱 Open website ⏩ www.testkingpass.com ⏪ and search for ▷ Certified-Data-Engineer-Professional ◁ for free download 🦂Certified-Data-Engineer-Professional Reliable Exam Price
- 100% Pass Quiz 2026 Marvelous Databricks Certified-Data-Engineer-Professional Valid Test Topics 🐹 Search for ▶ Certified-Data-Engineer-Professional ◀ and download it for free immediately on ➽ www.pdfvce.com 🢪 🏦Certified-Data-Engineer-Professional Training Materials
- Online Certified-Data-Engineer-Professional Bootcamps ⌨ Certified-Data-Engineer-Professional Exam Quiz 🎣 Reliable Certified-Data-Engineer-Professional Test Camp 🍉 Open 「 www.examcollectionpass.com 」 and search for 【 Certified-Data-Engineer-Professional 】 to download exam materials for free 🐡Sample Certified-Data-Engineer-Professional Exam
- Reliable Certified-Data-Engineer-Professional Test Camp 🐃 Certified-Data-Engineer-Professional Training Materials 🕛 Certified-Data-Engineer-Professional Discount 🩳 Search for 【 Certified-Data-Engineer-Professional 】 and easily obtain a free download on { www.pdfvce.com } 🩱Certification Certified-Data-Engineer-Professional Exam
- Maximize Your Chances of Getting Databricks Certified-Data-Engineer-Professional Certification Exam 🛵 Easily obtain 《 Certified-Data-Engineer-Professional 》 for free download through ➽ www.practicevce.com 🢪 🤸Certified-Data-Engineer-Professional Exam Quiz
- 2026 Certified-Data-Engineer-Professional Valid Test Topics | Valid Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional 100% Pass 🎄 ⮆ www.pdfvce.com ⮄ is best website to obtain ▛ Certified-Data-Engineer-Professional ▟ for free download 🪐Certified-Data-Engineer-Professional Reliable Exam Answers
- Certified-Data-Engineer-Professional Valid Test Topics - 100% Pass-Sure Questions Pool 🚁 Easily obtain 【 Certified-Data-Engineer-Professional 】 for free download through { www.testkingpass.com } 🟫New Certified-Data-Engineer-Professional Exam Notes
- www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.ted.com, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, nvinio.com, mooc.ifro.edu.br, Disposable vapes