In today's rapidly changing Microsoft industry, the importance of obtaining Microsoft DP-750 certification has become increasingly evident. With the constant evolution of technology, staying competitive in the job market requires professionals to continuously upgrade their skills and knowledge. The Exam4PDF is committed to completely assisting you in exam preparation with DP-750 Questions. Success in the Implementing Data Engineering Solutions Using Azure Databricks (DP-750) certification exam is crucial in the tech sector, where the stakes are high, and a single mistake can have significant consequences.
| Section | Weight | Objectives |
|---|---|---|
| Secure and govern data using Unity Catalog | 15-20% | - Access control and policies
|
| Prepare and process data | 30-35% | - Data quality and validation
|
| Deploy and manage data pipelines and workloads | 30-35% | - Operational reliability
|
| Configure and manage Azure Databricks environments | 15-20% | - Workspace and compute configuration
|
We are now in a fast-paced era, and for this we have no right to choose. Just as a proverb says "Time is money." This is the reason why we must value time. That is to say, we should make full use of our time to do useful things. As examinee whose want to pass the DP-750, you shouldn’t waste your time on some useless books or materials. Our DP-750 Materials are tool that can not only to help you save a lot of time, but also help you pass the DP-750 exam. In this way, you can much time to complete your other goals and improve yourself better. What a rare opportunity it is! Never miss it because of your hesitation.
NEW QUESTION # 58
You have an Azure Databricks workspace that contains a Delta table named Table1.
Table1 has accumulated obsolete files.
You need to reduce storage costs. The solution must preserve 30 days of time travel history.
Which two actions should you perform? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
Answer: B,E
Explanation:
To diminish storage costs while preserving 60 days of time travel history, you must perform the following two actions: Set the delta.deletedFileRetentionDuration table property to 60 days and Run the vacuum command on the table.
Set the delta.deletedFileRetentionDuration table property to 30 days
This property controls how long data files must be deleted before they become eligible for removal by a cleanup process. By default, it is set to 7 days. Increasing it to 60 days ensures that Delta Lake preserves the underlying parquet files required to query any historical snapshot within your 30-day time travel window.
Run the vacuum command on the tableChanging the retention property alone does not delete files or reduce costs. You must explicitly execute the VACUUM command. The command scans the table and permanently deletes uncommitted or deleted data files that are older than the 60- day threshold defined by your retention duration, thereby freeing up storage space.
Incorrect:
[Not C]
Set the delta.logRetentionDuration table property to 30 days
This property controls how long the transaction log (_delta_log) history is kept, which defaults to
30 days. While the transaction log is required for time travel, modifying this property alone does not delete the heavy data files causing high storage costs. Furthermore, it governs the logs rather than the actual deleted data files.
Reference:
https://www.cloudmatter.io/post/data-audit-with-databricks-delta-time-travel
NEW QUESTION # 59
You have an Azure Databricks workspace that contains a Delta table named Table 1. Table 1 has accumulated obsolete files.
You need to reduce storage costs. The solution must preserve 30 days of time travel history. Which two actions should you perform? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
Answer: D,E
Explanation:
The correct answers are B and E.
The goal is to reduce storage costs while preserving 30 days of time travel. Two actions are needed:
Set delta.deletedFileRetentionDuration to a value aligned with the 30-day requirement (Option B). Note: the answer option states '10 days' which would be insufficient for 30-day time travel - in practice this property should be set to at least 30 days. This property defines the retention floor: VACUUM will not delete any file newer than this threshold.
Run VACUUM on Table1 (Option E). VACUUM physically removes unreferenced data files older than the retention duration from storage. Without running VACUUM, obsolete files accumulate indefinitely regardless of the retention property setting - the property tells VACUUM what to keep; VACUUM is what does the actual cleanup.
Option C (OPTIMIZE) compacts small files for better query performance but never deletes anything. Option D (logRetentionDuration) keeps the transaction log for time travel but doesn't free up the data file storage.
Reference: https://learn.microsoft.com/en-us/azure/databricks/sql/language-manual/delta-vacuum
NEW QUESTION # 60
You need to configure compute for the ingestion of telemetry data. The solution must meet the data ingestion and processing requirements.
What should you do?
Answer: D
Explanation:
The correct answer is A. Photon is Azure Databricks' native vectorized query engine, written in C++, designed to accelerate data ingestion and SQL-heavy workloads significantly over the standard Spark JVM path. Enabling it on a job compute cluster directly addresses Contoso's requirement for 'fast and consistent performance for BI workloads' and 'production ingestion workloads that can scale automatically during telemetry spikes.' Photon integrates transparently - no code changes are needed - and pairs well with autoscaling job clusters to handle the bursty 40,000-sensor telemetry load.
Option B contradicts the isolation requirement: Contoso explicitly needs production and development separated, not merged onto shared compute. Option C with a fixed large node gives peak capacity at all times, driving up costs even during quiet periods. Option D disabling autoscaling is the opposite of what's needed - telemetry spikes require elastic scaling, not a locked node count.
Reference: https://learn.microsoft.com/en-us/azure/databricks/compute/photon
NEW QUESTION # 61
You need to recommend a compute type for the production ingestion workloads and BI workloads. The solution must meet the environment and compute requirements.
What should you recommend for each type of workload? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.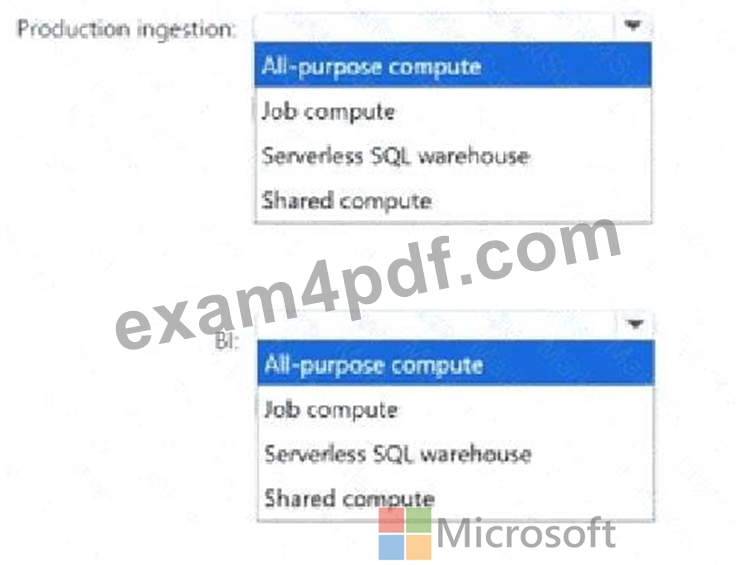
Answer:
Explanation: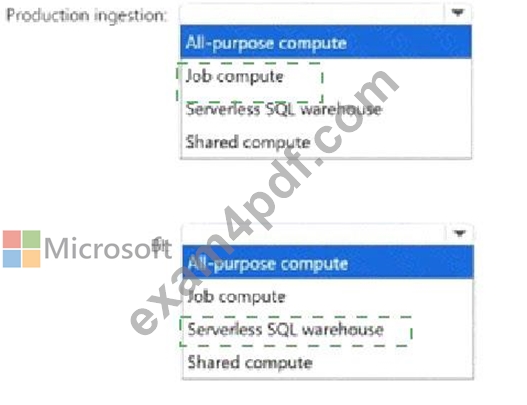
Explanation:
Production ingestion: Job compute
BI: Serverless SQL warehouse
Job compute is designed for automated production workloads executed through Lakeflow Jobs. Its lifecycle can be tied to the job run, providing workload isolation and avoiding the cost of maintaining an interactive all- purpose cluster continuously. It is therefore appropriate for scheduled ingestion and transformation processing. A serverless SQL warehouse is designed for BI and Databricks SQL workloads. It provides rapid startup, automatic infrastructure management, scaling, and optimized SQL-query execution for dashboards and reporting tools. All-purpose compute is intended primarily for interactive notebook development and exploration, while shared compute does not provide the same job-specific isolation or SQL-serving experience. Consequently, job compute should support production ingestion, and a serverless SQL warehouse should serve the BI workload.
NEW QUESTION # 62
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a catalog named Catalog 1. Catalog 1 contains a table named Transactions. Transactions contains the following columns:
* transaction_id
* customet_name
* email address
* credit_card_number
* transaction_amount
You need to ensure that business analysts can query all the tows in the Transactions table. The solution must meet the following requirements:
* Prevent the analysts from seeing the full values in the email_address and credit_catd_number columns.
* Ensure that the analysts can see only the values after the @ character in each email address.
* Ensure that the analysts can see only the last four digits of each credit card number.
* Enable the analysts to query the table without errors.
* Follow the principle of least privilege.
What should you do?
Answer: D
Explanation:
The correct answer is C. Column masks are the right tool when you need to partially expose sensitive data rather than hide it entirely. A column mask is a SQL function attached to a column that rewrites the returned value based on who is querying. For email_address, the mask returns only the substring after '@'. For credit_card_number, it returns only the last four digits. Business analysts get useful data without seeing anything sensitive, and they can still query the table without errors.
Option A (row-level filters) controls which rows a user sees, not the values within a row - it can't partially redact a column. Option B (grant SELECT only on non-sensitive columns) removes the columns entirely, so analysts can't see even partial email or card values - that doesn't meet the 'can see only partial values' requirement. Option D (column-level encryption) requires key management infrastructure and decryption at query time, which is significantly more complex than column masking for this use case.
Reference: https://learn.microsoft.com/en-us/azure/databricks/data-governance/unity-catalog/row-and-column- filters
NEW QUESTION # 63
......
If you want to pass a high percentage of the Microsoft DP-750 Exam, you should consider studying for the actual exam. These practice tests are designed to help you prepare for the exam and ensure you know the syllabus content. It will also help you improve your time management skills, as these tests are designed like an actual exam. Moreover, they will help you learn to answer all questions in the time allowed.
Flexible DP-750 Testing Engine: https://www.exam4pdf.com/DP-750-dumps-torrent.html