Study Databricks-Certified-Professional-Data-Engineer Group, Valid Databricks-Certified-Professional-Data-Engineer Exam Pdf

BTW, DOWNLOAD part of PDFDumps Databricks-Certified-Professional-Data-Engineer dumps from Cloud Storage: https://drive.google.com/open?id=1JfboJfqVsLB5DivkTdvxpZ59mlYMDAv0
Never stop challenging your limitations. If you want to dig out your potentials, just keep trying. Repeated attempts will sharpen your minds. Maybe our Databricks-Certified-Professional-Data-Engineer study materials are suitable for you. We strongly advise you to have a brave attempt. You will own a wonderful experience after you learning our Databricks-Certified-Professional-Data-Engineer Study Materials. Our study materials are different from common study materials, which can motivate you to concentrate on study.
| Section | Weight | Objectives |
|---|
| Delta Lake | 20-25% | - Delta Lake operations
- 1. Delta Live Tables
- 2. Schema evolution and enforcement
- 3. Merge, update, delete operations
- Delta Lake fundamentals
- 1. ACID transactions
- 2. Optimize and Z-order
- 3. Time travel and data versioning
|
| Data Processing with Spark | 25-30% | - Spark DataFrames and Spark SQL
- 1. Spark SQL queries and functions
- 2. Window functions
- 3. DataFrame operations and transformations
- Python and SQL for data engineering
- 1. Performance optimization techniques
- 2. Spark APIs in Python
- 3. Built-in and user-defined functions
|
| Pipeline Development and Orchestration | 10-15% | - Databricks workflows
- 1. Task dependencies and orchestration
- 2. Monitoring and alerting
- 3. Jobs and job scheduling
|
| Data Ingestion | 15-20% | - Streaming ingestion
- 1. Kafka integration
- 2. Structured streaming fundamentals
- Batch ingestion methods
- 1. DBR autoloader
- 2. Spark APIs for ingestion
- 3. Integration with external systems
|
| Data Warehouse and Lakehouse Architecture | 15-20% | - Lakehouse architecture principles
- 1. Data governance fundamentals
- 2. Differences between data lake, data warehouse, and lakehouse
- 3. Bronze, silver, gold data layers
|
>> Study Databricks-Certified-Professional-Data-Engineer Group <<
Valid Databricks-Certified-Professional-Data-Engineer Exam Pdf, New Databricks-Certified-Professional-Data-Engineer Exam Test
And you can also use the Databricks Databricks-Certified-Professional-Data-Engineer PDF on smart devices like smartphones, laptops, and tablets. The second one is the web-based Databricks Databricks-Certified-Professional-Data-Engineer practice exam which can be accessed through the browsers like Firefox, Safari, and Google Chrome. The customers don't need to download or install excessive plugins or software to get the full advantage from web-based Databricks-Certified-Professional-Data-Engineer Practice Tests.
Databricks Certified Professional Data Engineer Exam Sample Questions (Q102-Q107):
NEW QUESTION # 102
Which of the following describes a benefit of a data lakehouse that is unavailable in a traditional data
warehouse?
- A. A data lakehouse provides a relational system of data management
- B. A data lakehouse couples storage and compute for complete control
- C. A data lakehouse utilizes proprietary storage formats for data
- D. A data lakehouse captures snapshots of data for version control purposes
- E. A data lakehouse enables both batch and streaming analytics
Answer: E
NEW QUESTION # 103
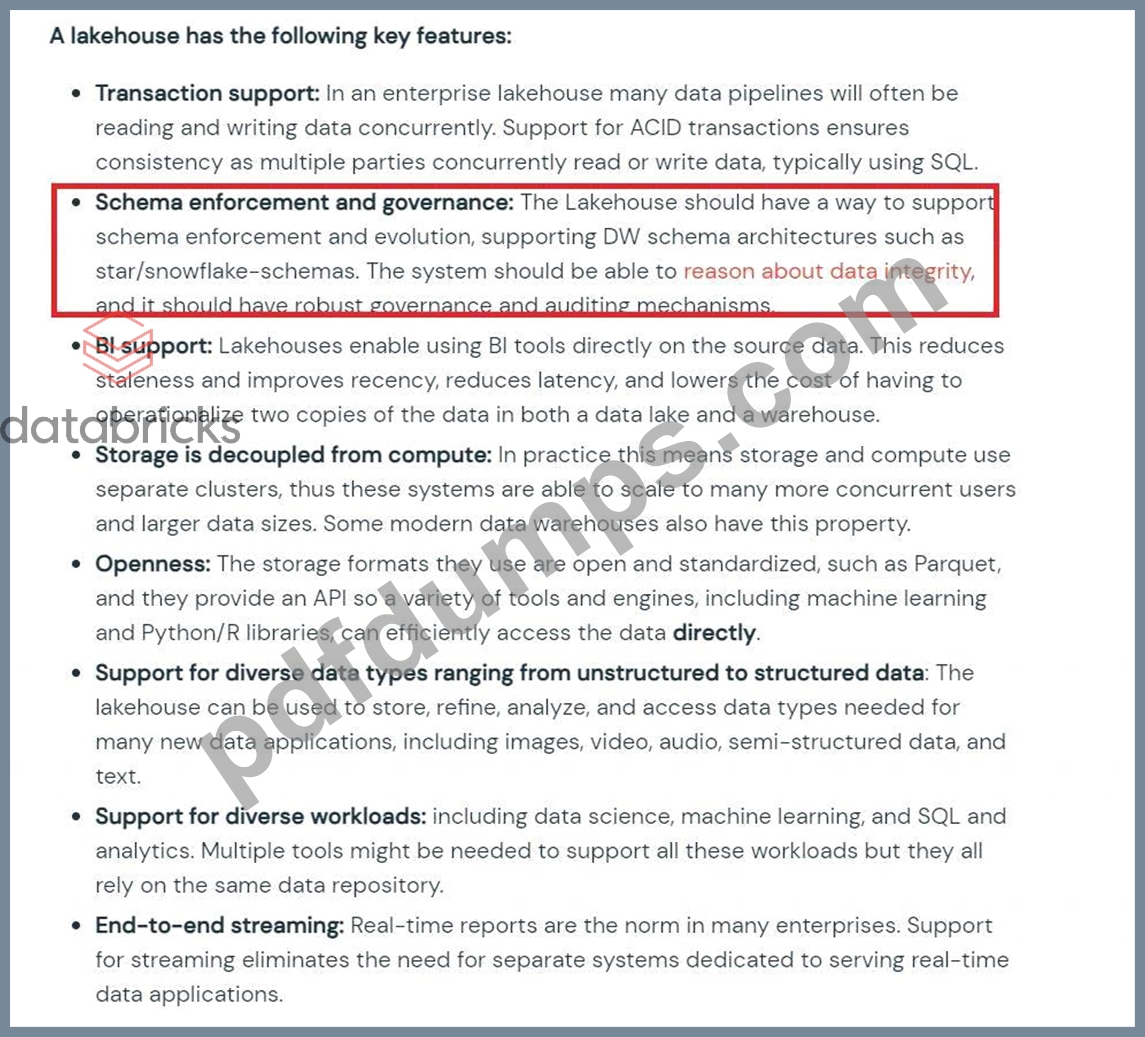
Which of the statements are correct about lakehouse?
- A. Lakehouse does not support ACID
- B. Lakehouse only supports Machine learning workloads and Data warehouses support BI workloads
- C. Lakehouse supports schema enforcement and evolution
- D. In Lakehouse Storage and compute are coupled
- E. Lakehouse only supports end-to-end streaming workloads and Data warehouses support Batch workloads
Answer: C
Explanation:
Explanation
The answer is Lakehouse supports schema enforcement and evolution,
Lakehouse using Delta lake can not only enforce a schema on write which is contrary to traditional big data systems that can only enforce a schema on read, it also supports evolving schema over time with the ability to control the evolution.
For example below is the Dataframe writer API and it supports three modes of enforcement and evolution, Default: Only enforcement, no changes are allowed and any schema drift/evolution will result in failure.
Merge: Flexible, supports enforcement and evolution
* New columns are added
* Evolves nested columns
* Supports evolving data types, like Byte to Short to Integer to Bigint How to enable:
* DF.write.format("delta").option("mergeSchema", "true").saveAsTable("table_name")
* or
* spark.databricks.delta.schema.autoMerge = True ## Spark session
Overwrite: No enforcement
* Dropping columns
* Change string to integer
* Rename columns
How to enable:
* DF.write.format("delta").option("overwriteSchema", "True").saveAsTable("table_name") What Is a Lakehouse? - The Databricks Blog Graphical user interface, text, application Description automatically generated
NEW QUESTION # 104
An upstream source writes Parquet data as hourly batches to directories named with the current date. A nightly batch job runs the following code to ingest all data from the previous day as indicated by the date variable:
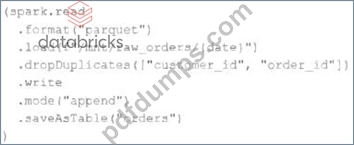
Assume that the fields customer_id and order_id serve as a composite key to uniquely identify each order.
If the upstream system is known to occasionally produce duplicate entries for a single order hours apart, which statement is correct?
- A. Each write to the orders table will only contain unique records; if existing records with the same key are present in the target table, these records will be overwritten.
- B. Each write to the orders table will run deduplication over the union of new and existing records, ensuring no duplicate records are present.
- C. Each write to the orders table will only contain unique records; if existing records with the same key are present in the target table, the operation will tail.
- D. Each write to the orders table will only contain unique records, but newly written records may have duplicates already present in the target table.
- E. Each write to the orders table will only contain unique records, and only those records without duplicates in the target table will be written.
Answer: D
Explanation:
This is the correct answer because the code uses the dropDuplicates method to remove any duplicate records within each batch of data before writing to the orders table. However, this method does not check for duplicates across different batches or in the target table, so it is possible that newly written records may have duplicates already present in the target table. To avoid this, a better approach would be to use Delta Lake and perform an upsert operation using mergeInto. Verified References: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "DROP DUPLICATES" section.
NEW QUESTION # 105
A data engineering team is configuring access controls in Databricks Unity Catalog. They grant the SELECT privilege on the sales catalog to the analyst_group, expecting that members of this group will automatically have SELECT access to all current and future schemas, tables, and views within the catalog.
What describes the privilege inheritance behavior in Unity Catalog?
- A. Privileges in Unity Catalog do not cascade; SELECT must be explicitly granted on each schema and table, even if granted at the catalog level.
- B. Privileges granted at the schema level override any catalog-level privileges and prevent access unless explicitly revoked.
- C. Granting SELECT at the catalog level applies to existing schemas and tables but not to those created in the future.
- D. Granting SELECT on a catalog automatically applies SELECT to all current and future schemas, tables, and views within that catalog.
Answer: A
Explanation:
Comprehensive and Detailed Explanation From Exact Extract of Databricks Data Engineer Documents:
In Unity Catalog, privileges are non-cascading-meaning that granting a privilege (like SELECT) on a catalog does not automatically grant the same privilege on contained objects (schemas, tables, or views). Each object type has its own independent access control hierarchy.
According to the Databricks access control documentation: "Privileges do not automatically cascade from catalog to schema or table levels." Administrators must explicitly grant privileges on each level if users need access across objects. This design ensures tighter governance and least-privilege enforcement. Therefore, option B correctly describes Unity Catalog's privilege model, while A and D incorrectly imply automatic inheritance.
NEW QUESTION # 106
The data science team has created and logged a production using MLFlow. The model accepts a list of column names and returns a new column of type DOUBLE.
The following code correctly imports the production model, load the customer table containing the customer_id key column into a Dataframe, and defines the feature columns needed for the model.
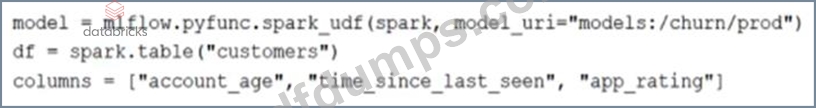
Which code block will output DataFrame with the schema'' customer_id LONG, predictions DOUBLE''?
- A. Model, predict (df, columns)
- B. Df, map (lambda k:midel (x [columns]) ,select (''customer_id predictions'')
- C. Df. Select (''customer_id''.
Model (''columns) alias (''predictions'') - D. Df.apply(model, columns). Select (''customer_id, prediction''
Answer: A
Explanation:
Given the information that the model is registered with MLflow and assuming predict is the method used to apply the model to a set of columns, we use the model.predict() function to apply the model to the DataFrame df using the specified columns. The model.predict() function is designed to take in a DataFrame and a list of column names as arguments, applying the trained model to these features to produce a predictions column. When working with PySpark, this predictions column needs to be selected alongside the customer_id to create a new DataFrame with the schema customer_id LONG, predictions DOUBLE.
Reference:
MLflow documentation on using Python function models: https://www.mlflow.org/docs/latest/models.html#python-function-python PySpark MLlib documentation on model prediction: https://spark.apache.org/docs/latest/ml-pipeline.html#pipeline
NEW QUESTION # 107
......
The Databricks-Certified-Professional-Data-Engineer exam questions by experts based on the calendar year of all kinds of exam after analysis, it is concluded that conforms to the exam thesis focus in the development trend, and summarize all kind of difficulties you will face, highlight the user review must master the knowledge content. Our Databricks Certified Professional Data Engineer Exam study question has high quality. So there is all effective and central practice for you to prepare for your test. With our professional ability, we can accord to the necessary testing points to edit Databricks-Certified-Professional-Data-Engineer Exam Questions. It points to the exam heart to solve your difficulty.
Valid Databricks-Certified-Professional-Data-Engineer Exam Pdf: https://www.pdfdumps.com/Databricks-Certified-Professional-Data-Engineer-valid-exam.html
- Databricks-Certified-Professional-Data-Engineer Dump with the Help of www.troytecdumps.com Exam Questions 🟨 Download { Databricks-Certified-Professional-Data-Engineer } for free by simply searching on ☀ www.troytecdumps.com ️☀️ 🥁Latest Databricks-Certified-Professional-Data-Engineer Exam Forum
- Realistic Study Databricks-Certified-Professional-Data-Engineer Group | Easy To Study and Pass Exam at first attempt - Trusted Databricks-Certified-Professional-Data-Engineer: Databricks Certified Professional Data Engineer Exam 😑 { www.pdfvce.com } is best website to obtain ⮆ Databricks-Certified-Professional-Data-Engineer ⮄ for free download 📓Reliable Databricks-Certified-Professional-Data-Engineer Exam Tutorial
- 100% Pass Quiz 2026 Trustable Databricks Databricks-Certified-Professional-Data-Engineer: Study Databricks Certified Professional Data Engineer Exam Group 🥎 Search for ➥ Databricks-Certified-Professional-Data-Engineer 🡄 and obtain a free download on 「 www.practicevce.com 」 👶New Databricks-Certified-Professional-Data-Engineer Test Duration
- Databricks-Certified-Professional-Data-Engineer Download Fee 🏇 Databricks-Certified-Professional-Data-Engineer Exam Questions And Answers 😀 Databricks-Certified-Professional-Data-Engineer Certification Exam 🛄 Search for ⏩ Databricks-Certified-Professional-Data-Engineer ⏪ and download it for free on ⏩ www.pdfvce.com ⏪ website 😼Reliable Databricks-Certified-Professional-Data-Engineer Test Cost
- 100% Pass Quiz 2026 Trustable Databricks Databricks-Certified-Professional-Data-Engineer: Study Databricks Certified Professional Data Engineer Exam Group 🛥 Search for ☀ Databricks-Certified-Professional-Data-Engineer ️☀️ and easily obtain a free download on 【 www.verifieddumps.com 】 👧Latest Databricks-Certified-Professional-Data-Engineer Dumps
- Databricks-Certified-Professional-Data-Engineer Download Fee 💅 Valid Dumps Databricks-Certified-Professional-Data-Engineer Sheet 💭 Test Databricks-Certified-Professional-Data-Engineer Dump 👐 Enter 《 www.pdfvce.com 》 and search for ➠ Databricks-Certified-Professional-Data-Engineer 🠰 to download for free 🎻New Databricks-Certified-Professional-Data-Engineer Test Duration
- Databricks-Certified-Professional-Data-Engineer Download Fee 😢 Reliable Databricks-Certified-Professional-Data-Engineer Exam Tutorial 💕 Training Databricks-Certified-Professional-Data-Engineer For Exam 😏 Search on ☀ www.prepawayete.com ️☀️ for [ Databricks-Certified-Professional-Data-Engineer ] to obtain exam materials for free download 🙂Latest Databricks-Certified-Professional-Data-Engineer Dumps
- Databricks-Certified-Professional-Data-Engineer Exam Study Group- Perfect Valid Databricks-Certified-Professional-Data-Engineer Exam Pdf Pass Success 📹 Enter ▷ www.pdfvce.com ◁ and search for ☀ Databricks-Certified-Professional-Data-Engineer ️☀️ to download for free 🌉Exam Databricks-Certified-Professional-Data-Engineer Fee
- Only The Validest Study Databricks-Certified-Professional-Data-Engineer Group Can Provide The Promise of Passing Databricks Certified Professional Data Engineer Exam 🏂 Immediately open { www.troytecdumps.com } and search for ⏩ Databricks-Certified-Professional-Data-Engineer ⏪ to obtain a free download 📔Databricks-Certified-Professional-Data-Engineer Download Fee
- Reliable Databricks-Certified-Professional-Data-Engineer Test Cost 😤 Databricks-Certified-Professional-Data-Engineer Exam Questions And Answers 🔧 Databricks-Certified-Professional-Data-Engineer Exam Preview 🔋 Immediately open ⇛ www.pdfvce.com ⇚ and search for ⇛ Databricks-Certified-Professional-Data-Engineer ⇚ to obtain a free download 🐅Databricks-Certified-Professional-Data-Engineer Exam Questions And Answers
- Databricks-Certified-Professional-Data-Engineer Pdf Dumps 🧒 Databricks-Certified-Professional-Data-Engineer Exam Questions And Answers 🦠 Databricks-Certified-Professional-Data-Engineer Exam Questions And Answers 😖 Simply search for ⇛ Databricks-Certified-Professional-Data-Engineer ⇚ for free download on ➽ www.validtorrent.com 🢪 👍Test Databricks-Certified-Professional-Data-Engineer Dump
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, Disposable vapes
DOWNLOAD the newest PDFDumps Databricks-Certified-Professional-Data-Engineer PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1JfboJfqVsLB5DivkTdvxpZ59mlYMDAv0