The ExamDiscuss team regularly revises the Databricks Certified Data Engineer Professional Exam (Databricks-Certified-Data-Engineer-Professional) PDF version to add new questions and update Databricksmation, so candidates are always up-to-date. We provide candidates with comprehensive Databricks Certified Data Engineer Professional Exam (Databricks-Certified-Data-Engineer-Professional) exam questions with up to 1 year of free updates. If you are doubtful, feel free to download a free demo of ExamDiscuss Databricks Certified Data Engineer Professional Exam (Databricks-Certified-Data-Engineer-Professional) PDF dumps, desktop practice exam software, and web-based Databricks Certified Data Engineer Professional Exam (Databricks-Certified-Data-Engineer-Professional) practice exam. Don't wait. Purchase Databricks Certified Data Engineer Professional Exam (Databricks-Certified-Data-Engineer-Professional) exam dumps at an affordable price and start preparing for the updated Databricks Databricks-Certified-Data-Engineer-Professional certification exam today.
| Section | Weight | Objectives |
|---|---|---|
| Monitoring and Alerting | 10% | - Track data lineage and metrics - Set up alerts and notifications - Monitor pipeline performance and health |
| Data Transformation, Cleansing, and Quality | 10% | - Implement schema evolution and management - Enforce data quality standards - Apply data cleansing and validation rules |
| Debugging and Deploying | 10% | - Implement CI/CD and DevOps practices - Deploy using Asset Bundles, CLI, and APIs - Troubleshoot and debug pipelines |
| Developing Code for Data Processing using Python and SQL | 22% | - Implement complex data processing logic - Write efficient and maintainable code - Use Databricks-specific libraries and APIs |
| Cost & Performance Optimisation | 13% | - Improve query and pipeline performance - Apply cost management best practices - Optimize compute and storage resources |
| Data Ingestion & Acquisition | 7% | - Use Auto Loader and structured streaming - Ingest data from diverse sources - Handle incremental and batch data loads |
| Data Sharing and Federation | 5% | - Manage cross-platform data access - Use Delta Sharing for secure data sharing - Implement Lakehouse Federation |
| Data Governance | 7% | - Use Unity Catalog for governance - Manage data assets and metadata - Enforce data policies and standards |
| Ensuring Data Security and Compliance | 10% | - Implement access control and permissions - Secure data at rest and in transit - Ensure data privacy and compliance |
| Data Modelling | 6% | - Implement dimensional and relational models - Design Medallion Architecture - Optimize table design and partitioning |
>> Databricks-Certified-Data-Engineer-Professional Free Practice <<
Our team of experts updates actual Databricks Certified Data Engineer Professional Exam (Databricks-Certified-Data-Engineer-Professional) questions regularly so you can prepare for the Databricks Certified Data Engineer Professional Exam (Databricks-Certified-Data-Engineer-Professional) exam according to the latest syllabus. Additionally, we also offer up to 1 year of free Databricks Certified Data Engineer Professional Exam (Databricks-Certified-Data-Engineer-Professional) exam questions updates. We have a 24/7 customer service team available for your assistance if you get stuck somewhere. Buy Databricks Databricks-Certified-Data-Engineer-Professional Latest Questions of ExamDiscuss now and get ready to crack the Databricks-Certified-Data-Engineer-Professional certification exam in a single attempt.
NEW QUESTION # 125
A data engineer wants to join a stream of advertisement impressions (when an ad was shown) with another stream of user clicks on advertisements to correlate when impression led to monitizable clicks.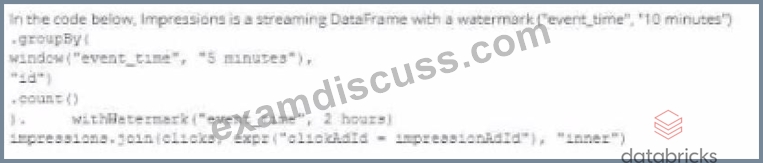
Which solution would improve the performance?




Answer: B
Explanation:
When joining a stream of advertisement impressions with a stream of user clicks, you want to minimize the state that you need to maintain for the join. Option A suggests using a left outer join with the condition that clickTime == impressionTime, which is suitable for correlating events that occur at the exact same time. However, in a real-world scenario, you would likely need some leeway to account for the delay between an impression and a possible click. It's important to design the join condition and the window of time considered to optimize performance while still capturing the relevant user interactions. In this case, having the watermark can help with state management and avoid state growing unbounded by discarding old state data that's unlikely to match with new data.
NEW QUESTION # 126
A data engineer is building a Lakeflow Declarative Pipelines pipeline to process healthcare claims data. A metadata JSON file defines data quality rules for multiple tables, including:
{
"claims": [
{"name": "valid_patient_id", "constraint": "patient_id IS NOT NULL"},
{"name": "non_negative_amount", "constraint": "claim_amount >= 0"}
]
}
The pipeline must dynamically apply these rules to the claims table without hardcoding the rules.
How should the data engineer achieve this?
Answer: A
Explanation:
Lakeflow Declarative Pipelines provide the expect_all method for programmatically applying multiple data quality expectations at once. The documentation explains that @dlt.expect_all accepts a dictionary of expectation names mapped to SQL constraints, allowing rules to be dynamically loaded from metadata such as JSON files. This ensures that pipelines remain maintainable and scalable without needing to hardcode individual @dlt.expect decorators. The event logs will track each expectation's pass and fail counts individually, making it auditable.
NEW QUESTION # 127
A data engineer is configuring a Databricks Asset Bundle to deploy a job with granular permissions.
The requirements are:
- Grant the data-engineers group CAN_MANAGE access to the job.
- Ensure the auditors' group can view the job but not modify/run it.
- Avoid granting unintended permissions to other users/groups.
How should the data engineer deploy the job while meeting the requirements?
Answer: C
Explanation:
Databricks Asset Bundles (DABs) allow jobs, clusters, and permissions to be defined as code in YAML configuration files. According to the Databricks documentation on job permissions and bundle deployment, when defining permissions within a job resource, they must be scoped directly under that specific job's definition. This ensures that permissions are applied only to the intended job resource and not inadvertently propagated to other jobs or resources.
In this scenario, the data engineer must grant the data-engineers group CAN_MANAGE access, allowing them to configure, edit, and manage the job, while the auditors group should only have CAN_VIEW, giving them read-only access to see configurations and results without the ability to modify or execute. Importantly, no additional groups should be granted permissions, in order to follow the principle of least privilege.
Options A and B introduce unnecessary or unintended groups (like admin-team in A) or define permissions outside of the job scope (as in B). Option C improperly separates the permissions block outside the job resource, which is not aligned with Databricks bundle best practices.
Option D is the correct approach because it defines the job resource my-job with its name, tasks, clusters, and the exact intended permissions (CAN_MANAGE for data-engineers and CAN_VIEW for auditors). This aligns with Databricks' principle of least privilege and ensures compliance with governance standards in Unity Catalog-enabled workspaces.
NEW QUESTION # 128
A table named user_ltv is being used to create a view that will be used by data analysts on various teams. Users in the workspace are configured into groups, which are used for setting up data access using ACLs.
The user_ltv table has the following schema:
email STRING, age INT, ltv INT
The following view definition is executed: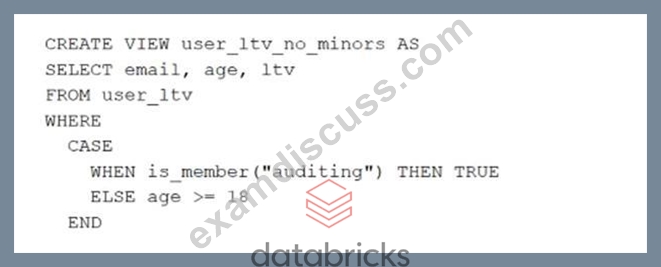
An analyst who is not a member of the auditing group executes the following query:
SELECT * FROM user_ltv_no_minors
Which statement describes the results returned by this query?
Answer: D
Explanation:
Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from Explanation:
Given the CASE statement in the view definition, the result set for a user not in the auditing group would be constrained by the ELSE condition, which filters out records based on age. Therefore, the view will return all columns normally for records with an age greater than 18, as users who are not in the auditing group will not satisfy the is_member('auditing') condition. Records not meeting the age > 18 condition will not be displayed.
NEW QUESTION # 129
The data governance team has instituted a requirement that all tables containing Personal Identifiable Information (PH) must be clearly annotated. This includes adding column comments, table comments, and setting the custom table property "contains_pii" = true.
The following SQL DDL statement is executed to create a new table: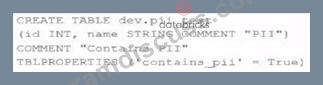
Which command allows manual confirmation that these three requirements have been met?
Answer: B
Explanation:
This is the correct answer because it allows manual confirmation that these three requirements have been met. The requirements are that all tables containing Personal Identifiable Information (PII) must be clearly annotated, which includes adding column comments, table comments, and setting the custom table property "contains_pii" = true. The DESCRIBE EXTENDED command is used to display detailed information about a table, such as its schema, location, properties, and comments. By using this command on the dev.pii_test table, one can verify that the table has been created with the correct column comments, table comment, and custom table property as specified in the SQL DDL statement.
NEW QUESTION # 130
......
According to different kinds of questionnaires based on study condition among different age groups, we have drawn a conclusion that the majority learners have the same problems to a large extend, that is low-efficiency, low-productivity, and lack of plan and periodicity. As a consequence of these problem, our Databricks-Certified-Data-Engineer-Professional test prep is totally designed for these study groups to improve their capability and efficiency when preparing for Databricks-Certified-Data-Engineer-Professional Exams, thus inspiring them obtain the targeted Databricks-Certified-Data-Engineer-Professional certificate successfully. Our Databricks-Certified-Data-Engineer-Professional question torrent can play a very important part in helping you achieve your dream.
Databricks-Certified-Data-Engineer-Professional Latest Dumps Questions: https://www.examdiscuss.com/Databricks/exam/Databricks-Certified-Data-Engineer-Professional/