Our CCAR-P exam question is widely known throughout the education market. Almost all the candidates who are ready for the qualifying examination know our CCAR-P exam questions. Even when they find that their classmates or colleagues are preparing a CCAR-P exam, they will introduce our study materials to you. So, our learning materials help users to be assured of the CCAR-P Exam. Currently, my company has introduced three versions of CCAR-P learning materials, covering almost all the needs of the different customers.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Developer Productivity & Operational Enablement | 7% | - Support debugging, monitoring, and operational resolution - Configure Claude tools and environments for teams - Improve developer workflows with AI-assisted tooling |
| Topic 2: Evaluation, Testing & Optimization | 16% | - Implement iterative improvement pipelines - Define evaluation metrics and success criteria - Test accuracy, reliability, latency, and cost - Optimize performance, prompting, and model selection |
| Topic 3: Stakeholder Communication & Lifecycle Management | 14% | - Manage stakeholder feedback and expectation alignment - Conduct structured discovery and requirement gathering - Communicate architectural decisions and trade-offs - Document architectures and support full lifecycle phases |
| Topic 4: Integration | 19% | - Integrate with data pipelines and RAG systems - Integrate Claude with enterprise systems, APIs, and tools - Design authentication, authorization, and observability - Implement Model Context Protocol (MCP) integrations |
| Topic 5: Solution Design & Architecture | 17% | - Translate business problems into Claude-based AI solutions - Design multi-agent systems and orchestration strategies - Align solutions to business value pillars - Design end-to-end architectures and feedback loops - Select architectural patterns: workflow, agentic, augmented LLM |
| Topic 6: Governance, Safety & Risk Management | 14% | - Ensure regulatory compliance (GDPR, HIPAA, etc.) - Address ethical AI considerations and bias mitigation - Implement guardrails and safety controls - Manage data privacy and security compliance |
| Topic 7: Claude Models, Prompting & Context Engineering | 13% | - Design system prompts, templates, and guardrails - Select appropriate Claude models based on trade-offs - Apply context engineering and context management techniques - Mitigate prompt injection, leaks, and jailbreak risks |
Our CCAR-P practice materials are high quality and high accuracy rate products. It is all about their superior concreteness and precision that helps. Every page and every points of knowledge have been written from professional experts who are proficient in this line and are being accounting for this line over ten years. Many exam candidates attach great credence to our CCAR-P practice materials. Our CCAR-P practice materials do not need any ads, their quality has propaganda effect themselves.
NEW QUESTION # 97
You are evaluating retrieval-strategy claims used by a peer team.
For each claim, select yes if the statement is generally accurate. Otherwise, select no.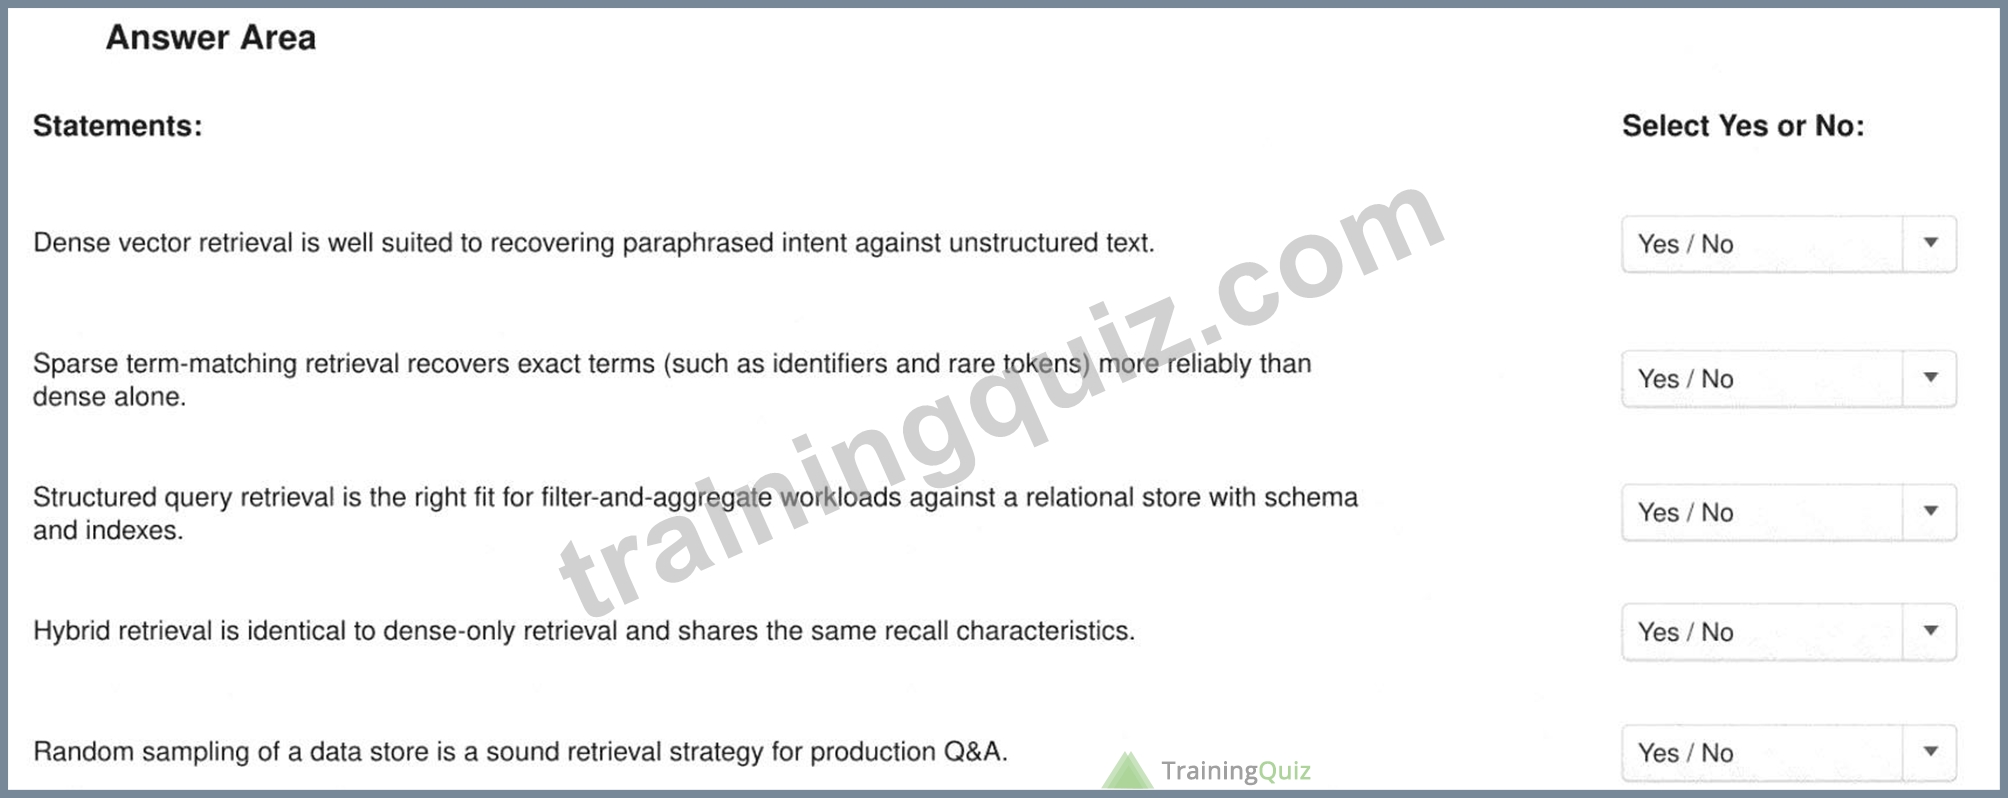
Answer:
Explanation: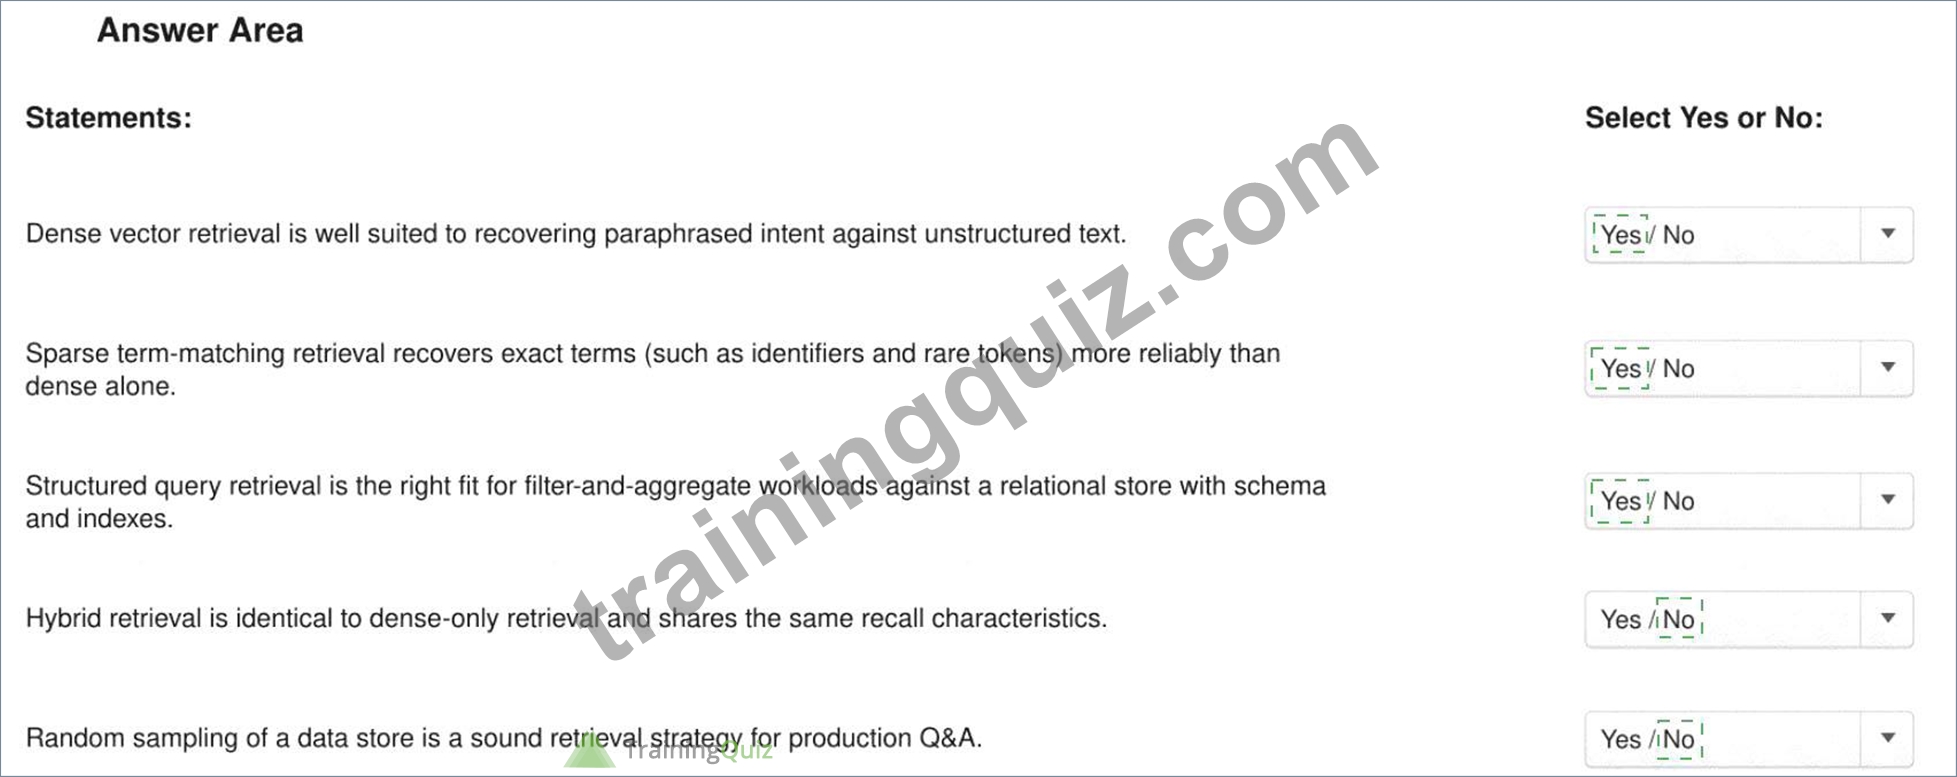
Explanation:
Yes, Yes, Yes, No, No
Dense vector retrieval represents semantic similarity, making it suitable for matching paraphrases and conceptually related language even when the query and source do not share identical words. Sparse lexical retrieval, including BM25-style matching, retains strong sensitivity to exact tokens and is therefore valuable for identifiers, product codes, technical names, and uncommon terminology.
Structured query retrieval is appropriate when the required operation depends on explicit fields, predicates, joins, counts, grouping, or aggregation over a relational schema. In that situation, generating or invoking a constrained database query is more precise than approximating the operation through semantic similarity.
Hybrid retrieval is not identical to dense retrieval. It combines semantic and lexical candidate sets, typically followed by rank fusion or reranking. Anthropic's contextual-retrieval guidance explains that semantic search captures meaning and paraphrases, while BM25 captures exact terminology; combining them improves coverage. Contextual Retrieval, Contextual Retrieval Cookbook Random sampling is not a relevance strategy. It provides no systematic relationship between the query and selected evidence, producing unstable coverage and preventable hallucination risk. Production Q & A requires deterministic or evaluated relevance mechanisms, access filters, suitable indexes, and measurable retrieval metrics such as recall at k.
Study Guide references/topics: Dense retrieval; sparse retrieval; structured queries; hybrid search; rank fusion; retrieval evaluation; production RAG design.
NEW QUESTION # 98
You are defining when to introduce a project subagent versus relying on Claude Code's general capabilities.
Which scenario most directly justifies a dedicated subagent?
Answer: C
Explanation:
A dedicated subagent is justified when specialization is recurring and operationally valuable. Option A allows the team to encode a database-review role once, including its system prompt, triggering description, permitted tools, model, and review criteria. This improves consistency across sessions, isolates specialized context, and applies least privilege by withholding unrelated capabilities. Anthropic's custom subagent documentation supports task-specific prompts, model selection, tool allowlists, permission modes, hooks, skills, and persistent memory. A one-time question does not justify the maintenance overhead of a reusable agent definition, while Options C and D explicitly provide no specialization requirement. The subagent should also have clear invocation conditions, evaluation cases, ownership, and lifecycle review.
Study Guide references/topics: Claude Code subagents; task specialization; context isolation; model routing; scoped permissions; reusable automation.
NEW QUESTION # 99
A Claude-based research assistant begins producing responses that confidently contradict its retrieved source documents despite no change to the retrieval pipeline.
Which two diagnostic actions most directly identify the root cause of this behavior? (Select two.)
Answer: D,E
Explanation:
The retrieval pipeline is stated to be unchanged, so the first investigation should isolate changes in generation behavior and grounding instructions. Replaying the failing cases on the previous model version determines whether the regression follows the model upgrade or current model-prompt combination. Inspecting the system prompt establishes whether source-use rules, uncertainty behavior, citation requirements, or prohibitions against unsupported claims were removed or weakened. Increasing context or replacing the embedding model changes a component for which no failure evidence exists and may introduce additional noise. Lowering temperature may reduce variation but does not explain systematic contradiction of retrieved evidence. The investigation should compare identical requests, retrieved passages, prompts, and model versions before applying a fix. Define success criteria and evaluations
NEW QUESTION # 100
You are compiling guardrail tactics for a customer-facing assistant.
Which two tactics belong on the guardrail list?
Each correct answer presents a complete solution.
Answer: B,C
Explanation:
Option C introduces a deterministic validation boundary between probabilistic model output and downstream execution. Structured validation can reject missing fields, invalid types, unauthorized actions, malformed arguments, and values outside approved enumerations before any tool or business process acts on the response. Anthropic recommends Structured Outputs when guaranteed schema conformance is required.
Increase Output Consistency
Option D implements defense in depth. Prompt-level instructions establish intended behavior, while runtime classifiers, content filters, policy engines, output validators, tool permissions, and human confirmation gates provide controls outside the model. Anthropic's guardrail guidance recommends combining safeguards rather than depending on one mechanism. Mitigate Jailbreaks and Prompt Injections Option A creates a bypass mechanism that adversaries may discover or imitate. Option B may alter output variability but is not a security boundary and cannot guarantee policy compliance. Option E places complete reliance on a system prompt, which remains vulnerable to ambiguity, conflicting inputs, model errors, and indirect prompt injection.
Guardrails should be risk-based, independently enforceable where possible, observable, tested against adversarial cases, and proportional to the consequences of downstream actions.
Study Guide references/topics: Layered guardrails; structured validation; runtime content checks; prompt injection; deterministic enforcement; defense in depth.
NEW QUESTION # 101
You are classifying token-management tactics by where each tactic applies in the request lifecycle: "Input Preparation," "Prompt Construction," or "Output Handling."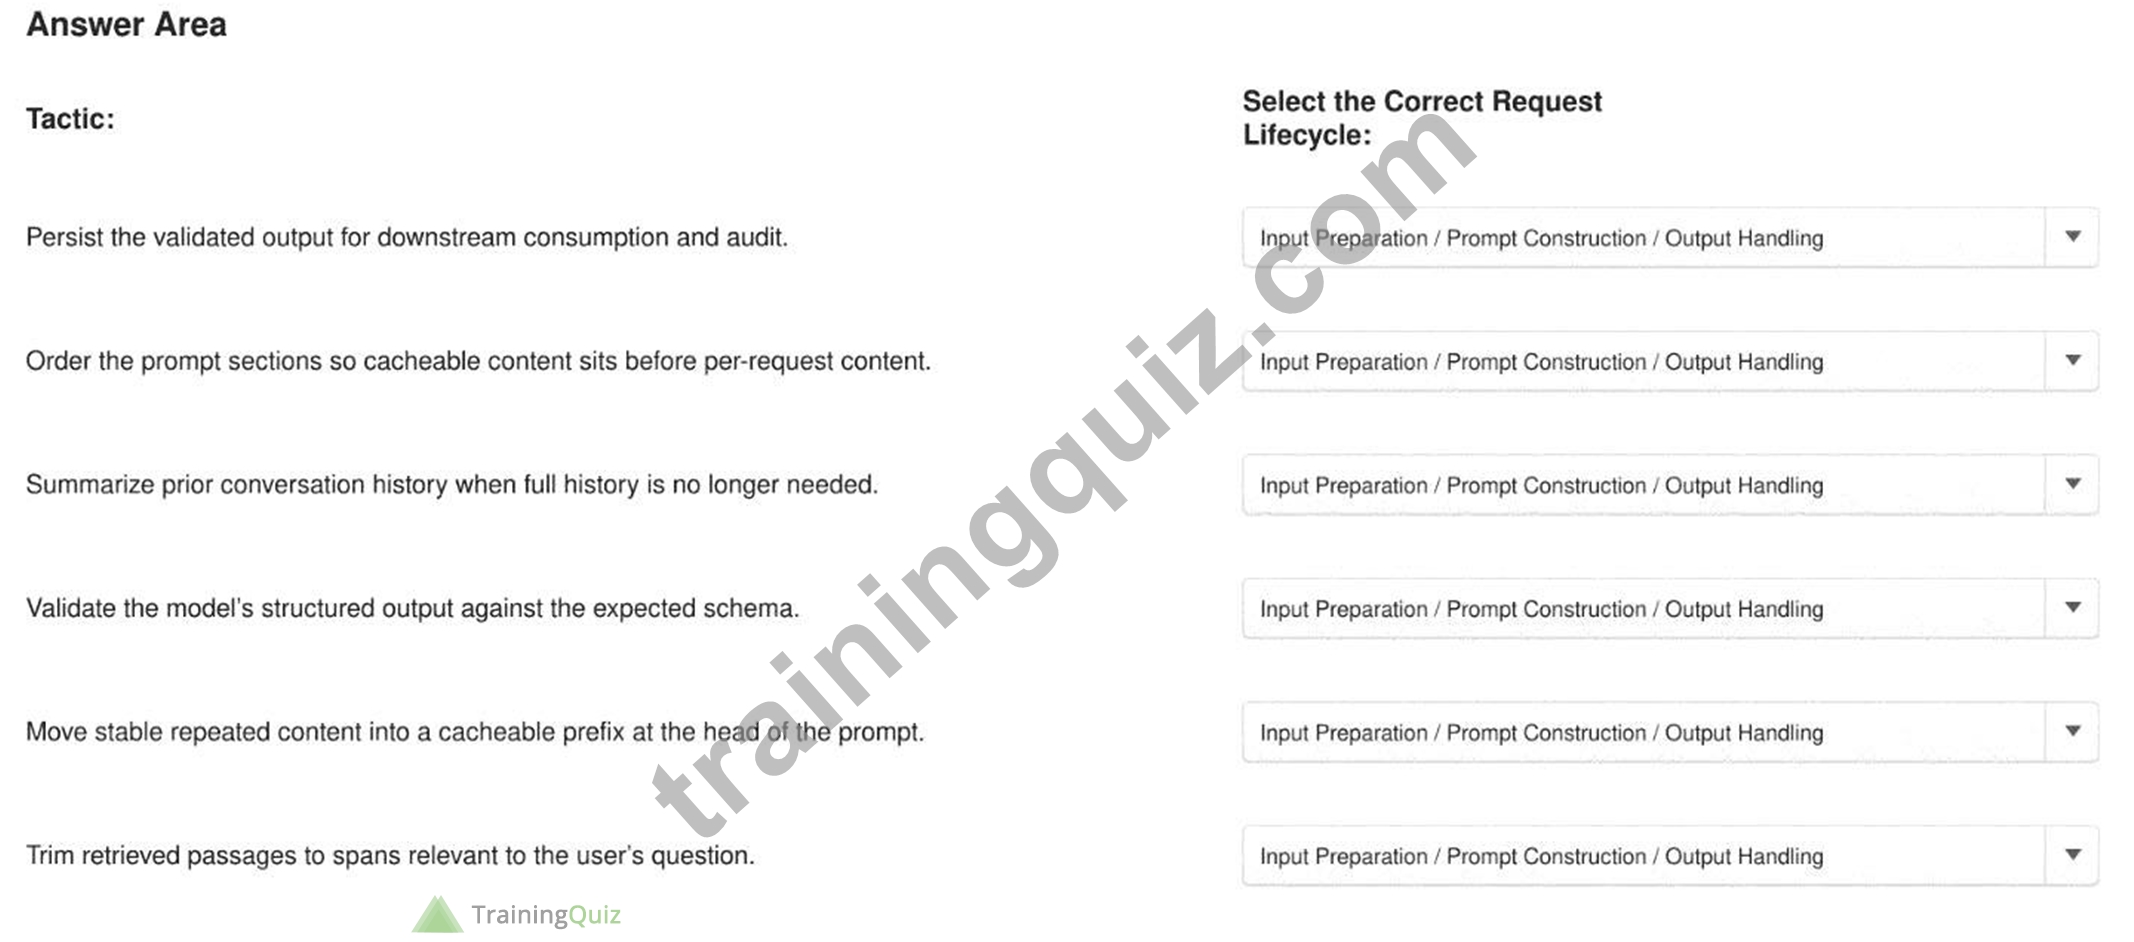
Answer:
Explanation: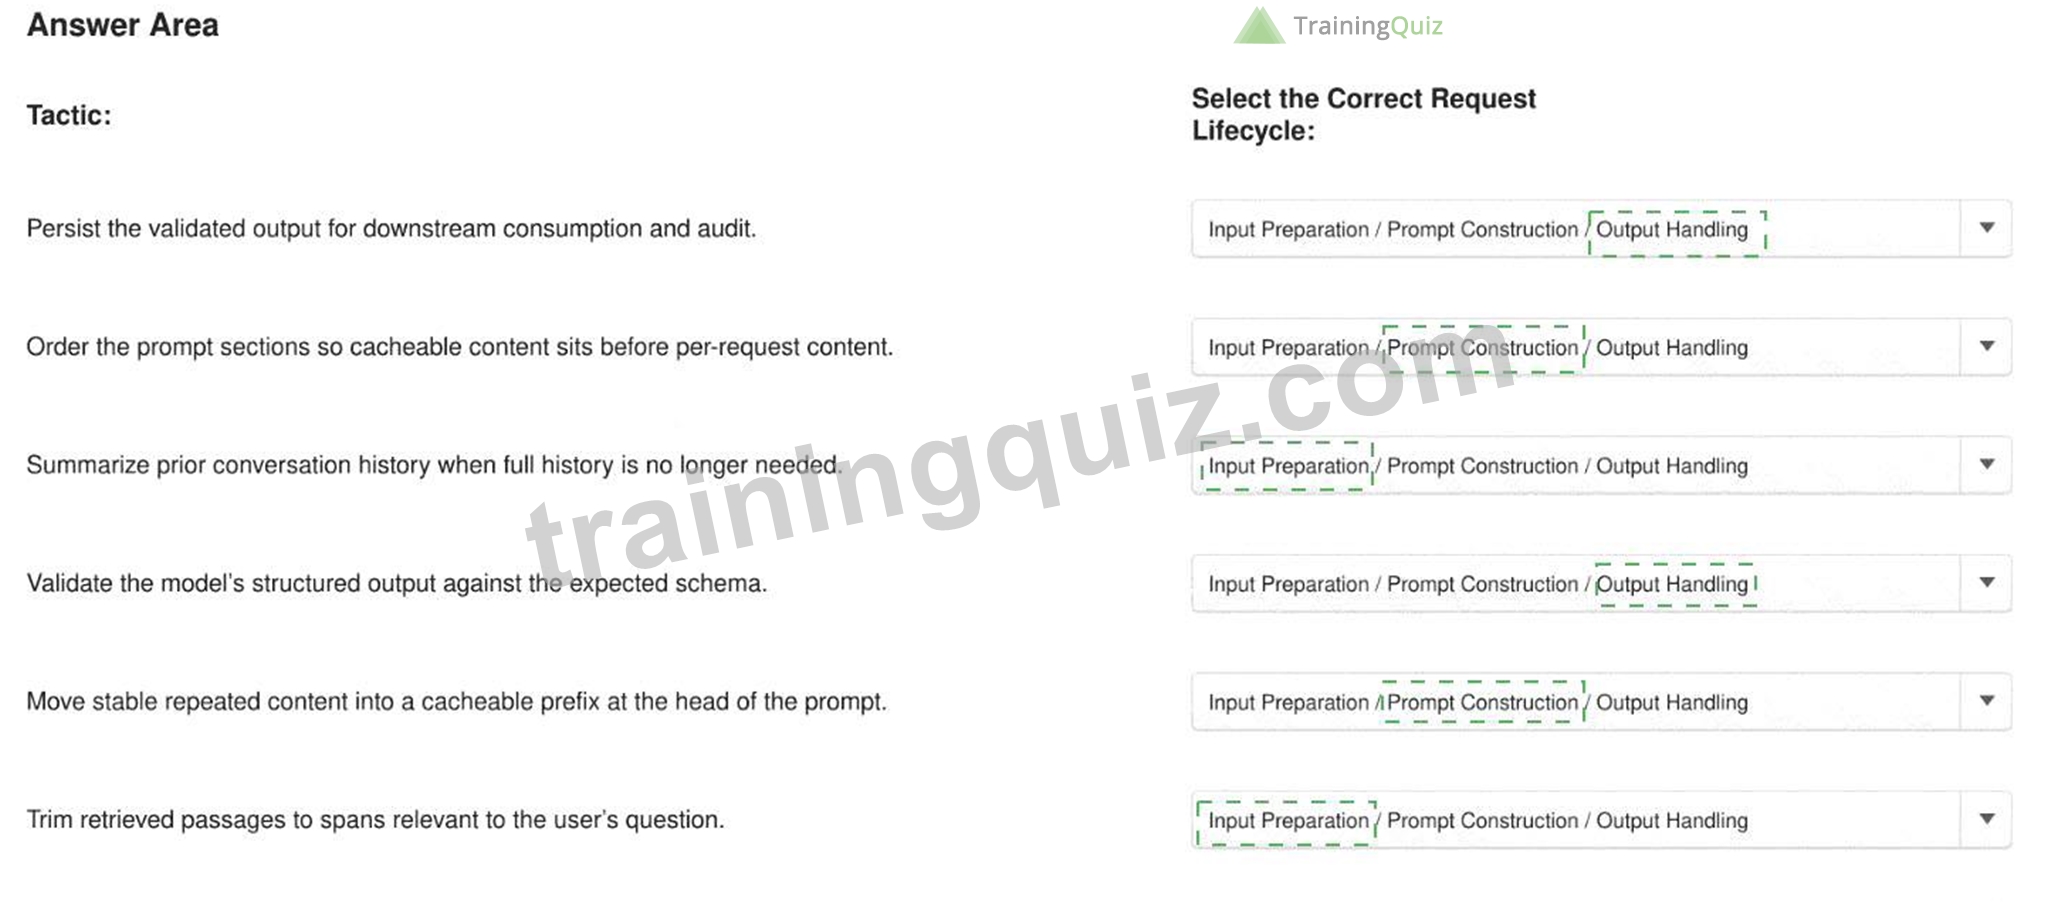
Explanation:
* Persist the validated output for downstream consumption and audit - Output Handling
* Order prompt sections so cacheable content appears before per-request content - Prompt Construction
* Summarize prior conversation history when full history is no longer needed - Input Preparation
* Validate the model's structured output against the expected schema - Output Handling
* Move stable repeated content into a cacheable prefix at the beginning of the prompt - Prompt Construction
* Trim retrieved passages to spans relevant to the user's question - Input Preparation Input preparation determines what evidence and history should enter the request, so summarization and retrieval trimming belong there. Prompt construction determines ordering and cache boundaries; stable repeated instructions must precede dynamic per-request content to maximize cache reuse. Output handling begins after generation and includes schema validation, persistence, auditing, and downstream delivery.
Mixing these responsibilities creates inefficient prompts and weak validation boundaries. Anthropic's context guidance emphasizes curating the smallest useful context because unnecessary tokens can reduce recall and accuracy. Prompt caching similarly depends on a stable reusable prefix, while structured outputs or schema validation protect downstream systems from malformed responses. Context windows; prompt caching
NEW QUESTION # 102
......
The third format is desktop CCAR-P practice exam software that can be accessed easily after installing it on your Windows PC or Laptop. These formats are there so that the students can use them as per their unique needs and prepare successfully for CCAR-P the on first try. The CCAR-P mock tests are specially built for you to evaluate what you have studied. These Claude Certified Architect - Professional (CCAR-P) practice exams (desktop and web-based) are customizable, which means that you can change the time and questions according to your needs. Our CCAR-P practice tests teach you time management so you can pass the Claude Certified Architect - Professional (CCAR-P) certification exam.
Valid CCAR-P Dumps: https://www.trainingquiz.com/CCAR-P-practice-quiz.html