2026 Latest Actualtests4sure DP-800 PDF Dumps and DP-800 Exam Engine Free Share: https://drive.google.com/open?id=1MUqxsvaJv6NhVL1t2l4RoLEkvq9Pwf6P
There are three versions of Developing AI-Enabled Database Solutions test torrent—PDF, software on pc, and app online,the most distinctive of which is that you can install DP-800 test answers on your computer to simulate the real exam environment, without limiting the number of computers installed. Through a large number of simulation tests, you can rationally arrange your own DP-800 exam time, adjust your mentality in the examination room, find your own weak points and carry out targeted exercises. But I am so sorry to say that DP-800 Test Answers can only run on Windows operating systems and our engineers are stepping up to improve this. In fact, many people only spent 20-30 hours practicing our DP-800 guide torrent and passed the exam. This sounds incredible, but we did, helping them save a lot of time.
| Section | Weight | Objectives |
|---|---|---|
| Design and develop database solutions (35–40%) | 35-40% | - Implement data management
|
| Secure, optimize, and deploy database solutions (35–40%) | 35-40% | - Implement security
|
| Implement AI capabilities in database solutions (25–30%) | 25-30% | - Integrate Azure AI services
|
>> High Microsoft DP-800 Quality <<
Passing an Developing AI-Enabled Database Solutions exam on the first attempt can be stressful, but Microsoft DP-800 exam questions can help manage stress and allow you to perform at your best. We at Actualtests4sure give you the techniques and resources to make sure you get the most out of your exam study. We provide preparation material for the Developing AI-Enabled Database Solutions exam that will guide you when you sit to study for it. DP-800 updated questions give you enough confidence to sit for the Microsoft exam.
NEW QUESTION # 16
You are developing an Azure SQL database solution from a locally cloned GitHub repository by using Microsoft Visual Studio Code and GitHub Copilot Chat.
You need to ensure that GitHub Copilot Chat can call the hosted GitHub MCP Server tools by using OAuth. The MCP server configuration must be scoped to the repository.
What should you do in Visual Studio Code?
Answer: D
Explanation:
To connect GitHub Copilot Chat to an Azure SQL Database using a hosted GitHub MCP (Model Context Protocol) Server, follow these steps. This setup ensures that Copilot can interact directly with your repository and database schema using OAuth.
Step 1: Configure the MCP Server in VS Code
You must set the scope to the Workspace level to ensure the server is restricted to your specific repository.
Open your locally cloned GitHub repository in VS Code.
Open the Command Palette (Ctrl+Shift+P or Cmd+Shift+P).
Type and select: MCP: Add Server.
Select HTTP (HTTP or Server-Sent Events).
Enter the URL: https://api.githubcopilot.com/mcp/
Crucial: When prompted for the configuration scope, select Workspace Settings.
This saves the config to .vscode/settings.json, binding the server to this repo.
Step 2: Authenticate via OAuth
Once the server is added, Copilot needs permission to act on your behalf.
Open the GitHub Copilot Chat panel.
You will see a notification or a prompt within the chat asking to Authorize the MCP server.
Follow the browser prompts to sign in and grant OAuth permissions.
This allows the hosted MCP server to "see" your repository's code and metadata.
Reference:
https://skywork.ai/skypage/en/The-Ultimate-Guide-to-GitHub's-MCP-Server:-Bridging-AI-and- Your-Codebase/1970685991323758592
NEW QUESTION # 17
You have an Azure SQL database named AdventureWorksDB that contains a table named dbo.Employee.
You have a C# Azure Functions app that uses an HTTP-triggered function with an Azure SQL input binding to query dbo.Employee.
You are adding a second function that will react to row changes in dbo.Employee and write structured logs.
You need to configure AdventureWorksDB and the app to meet the following requirements:
* Changes to dbo.Employee must trigger the new function within five seconds.
* Each invocation must processes no more than 100 changes.
Which two database configurations should you perform? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
Answer: A,B
Explanation:
Azure Functions' Azure SQL trigger requires change tracking to be enabled on the source table. Microsoft' s SQL trigger documentation states that setting up change tracking for the Azure SQL trigger requires two steps : enable change tracking on the database and enable change tracking on the table being monitored.
Since the question asks specifically which database configurations you should perform, enabling change tracking on dbo.Employee is one of the required database-side steps.
To meet the latency requirement that changes trigger the function within five seconds , the relevant trigger setting is Sql_Trigger_PollingIntervalMs . Microsoft documents this setting as the delay, in milliseconds, between processing each batch of changes, and a value of 5000 means the trigger polls every 5 seconds .
A few clarifications about the other options:
* B is not the documented setting name. The documented app setting is Sql_Trigger_BatchSize or host setting MaxBatchSize , not "SetSql Trigger MaxBatchSize". The screenshot wording suggests a distractor.
* D is also required in practice for the trigger to work, but the question asks for two answers and includes the polling setting plus the table-level CT setting as the actionable choices presented.
* F is wrong because the Azure SQL trigger uses change tracking , not CDC.
NEW QUESTION # 18
Drag and Drop Question
You have an Azure SQL database that contains a table named dbo.Customers. dbo.Customers contains the following columns:
- CustomerId (int)(primary key)
- ProfileJson (nvarchar(max))
You have an application that returns phone numbers in a format of +000 000-000-0000. The phone numbers are stored in ProfileJson.
You need to write a query that returns:
- One row per customer
- A PhoneNUmerals column that contains only the digits
How should you complete the Transact-SQL query? To answer, drag the appropriate values to the correct targets. Each value may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.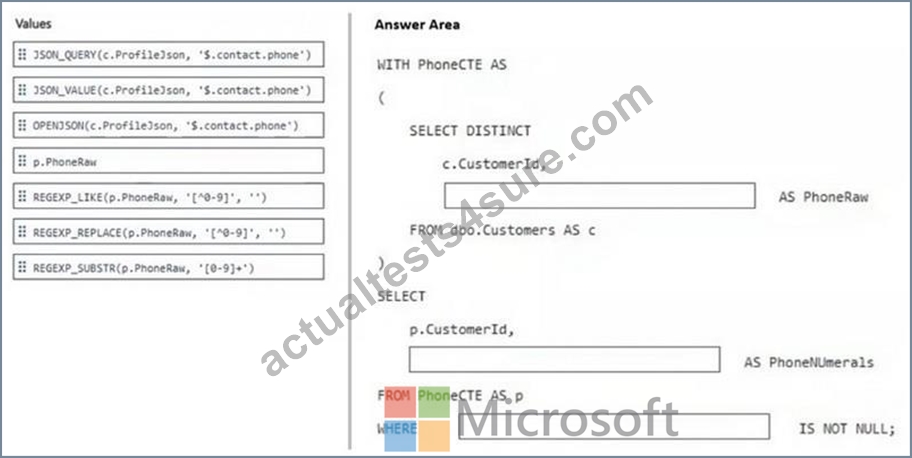
Answer:
Explanation: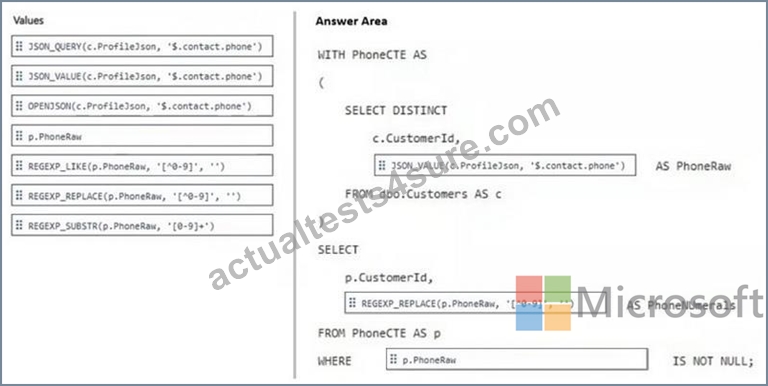
NEW QUESTION # 19
Hotspot Question
You have an SDK-style SQL database project named MyDatabaseProject.sqlprojstored in a private GitHub repository. The repository contains the following GitHub Actions workflow.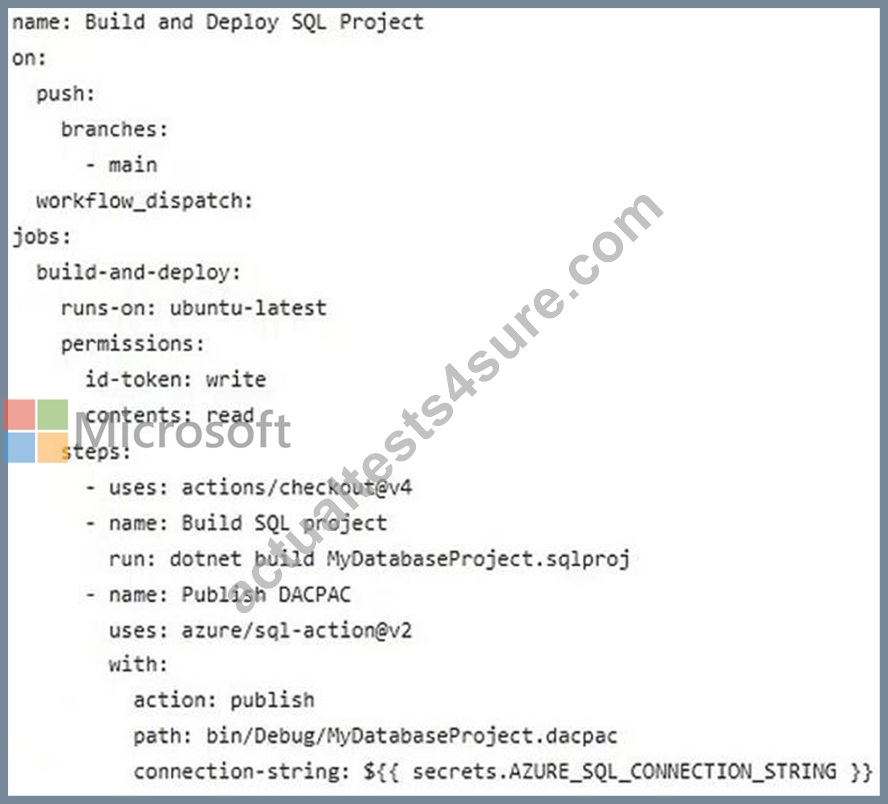
The repository contains the AZURE_SQL_CONNECTION_STRING secrets.
The target is an Azure SQL database that allows access to Azure services and is configured to support mixed authentication.
The workflow runs successfully.
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.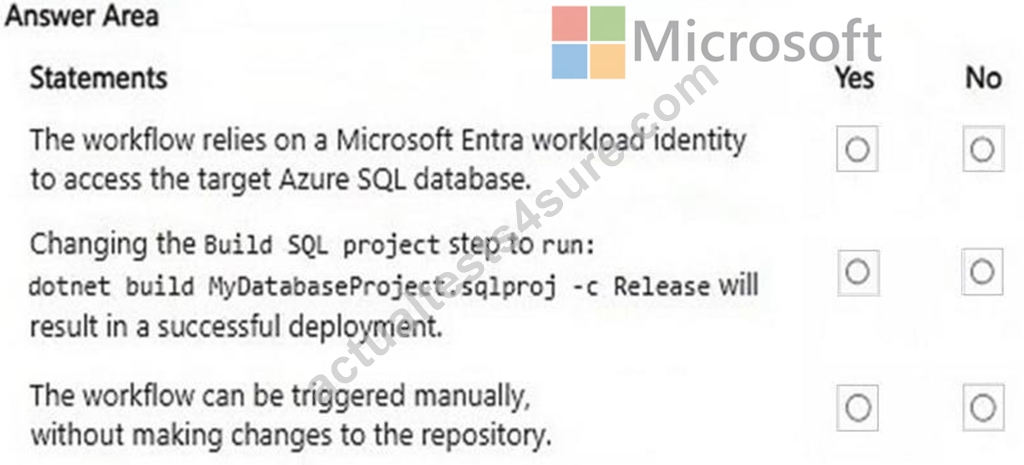
Answer:
Explanation: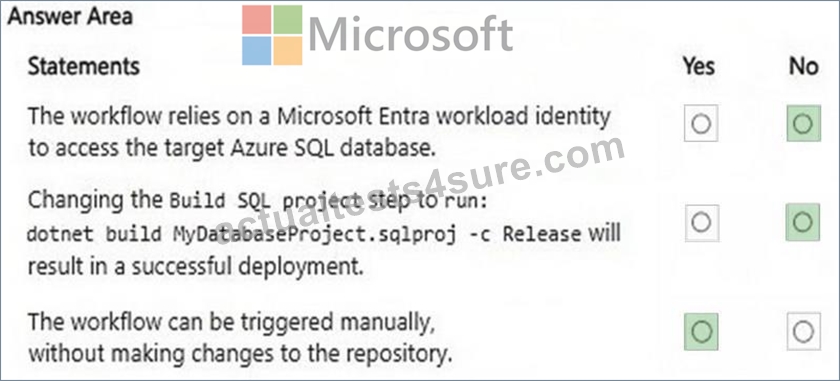
NEW QUESTION # 20
You have an Azure SQL database named DB1 that contains two tables named knowledgebase and query_cache. knowledge_base contains support articles and embeddings. query_cache contains chat questions, responses, and embeddings DB1 supports an Al-enabled chat agent.
You need to design a solution that meets the following requirements:
* Serializes the retrieved rows from knowledee_base
* Extracts the answer field from the response
* Extracts the embeddings to store in query_cache
You will call the external large language model (LLM) by using the sp_irwoke_external_re standpoint stored procedure.
Which Transact-SGL commands should you use for each requirement? To answer, drag the appropriate commands to the correct requirements. Each command may be used once, mote than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.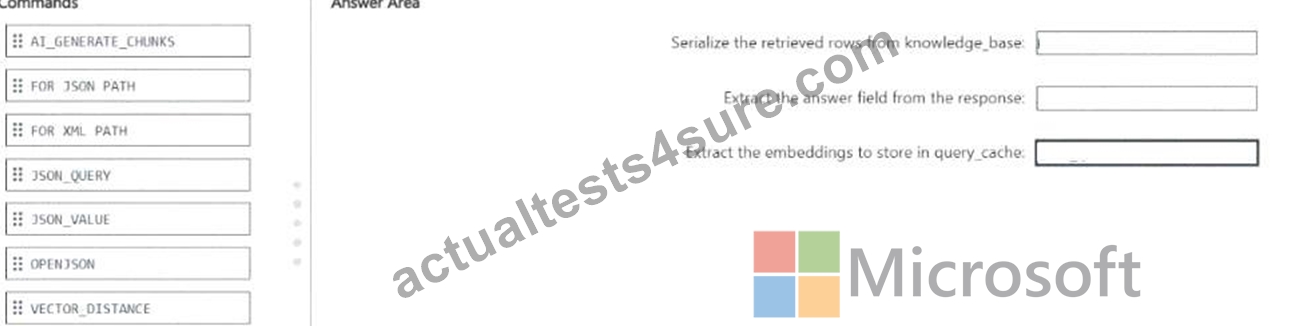
Answer:
Explanation: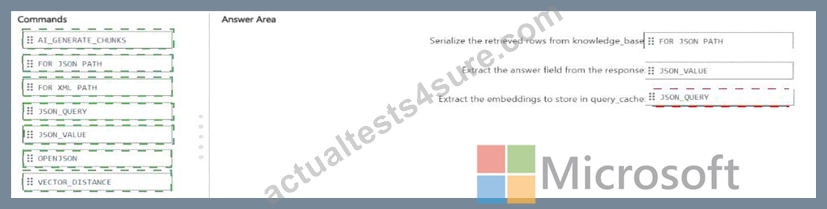
Explanation: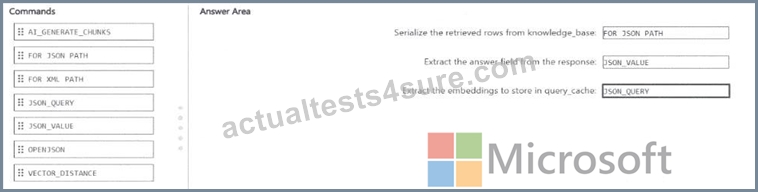
The correct mapping is:
* FOR JSON PATH
* JSON_VALUE
* JSON_QUERY
To serialize the retrieved rows from knowledge_base , the correct command is FOR JSON PATH .
Microsoft documents that FOR JSON formats query results as JSON, and PATH mode is the standard way to shape relational rows into JSON for downstream application or AI use.
To extract the answer field from the response , the correct command is JSON_VALUE because answer is a single scalar field . Microsoft states that JSON_VALUE is used to extract a scalar value from JSON text.
To extract the embeddings to store in query_cache , the correct command is JSON_QUERY because embeddings are returned as a JSON array , not a scalar. Microsoft states that JSON_QUERY extracts an object or array from JSON text, which is exactly the right behavior for an embeddings payload.
The unused options are not the best fit here:
* OPENJSON is mainly for shredding JSON into rows and columns.
* AI_GENERATE_CHUNKS is for chunking text, not extracting fields from a response payload.
* VECTOR_DISTANCE computes similarity between vectors and is unrelated to JSON extraction.
* FOR XML PATH produces XML, not JSON.
NEW QUESTION # 21
......
The PDF version of the Actualtests4sure Developing AI-Enabled Database Solutions (DP-800) prep material is easily accessible. This format is ideal for someone who is constantly on the move, as you can prepare for your Developing AI-Enabled Database Solutions (DP-800) exam whether you are using your smartphone, tablet, or laptop. You can study anywhere, at any time, without having to worry about installing anything. Furthermore, you can study with a hard copy by printing all of your Developing AI-Enabled Database Solutions (DP-800) PDF questions. We offer regular updates in PDF format to improve Developing AI-Enabled Database Solutions (DP-800) questions according to changes in the exam.
DP-800 Sample Questions Pdf: https://www.actualtests4sure.com/DP-800-test-questions.html
P.S. Free & New DP-800 dumps are available on Google Drive shared by Actualtests4sure: https://drive.google.com/open?id=1MUqxsvaJv6NhVL1t2l4RoLEkvq9Pwf6P