The print option of this format allows you to carry a hard copy with you at your leisure. We update our Databricks Certified Professional Data Engineer Exam (Databricks-Certified-Professional-Data-Engineer) pdf format regularly so keep calm because you will always get updated Databricks Certified Professional Data Engineer Exam (Databricks-Certified-Professional-Data-Engineer) questions. DumpsTests offers authentic and up-to-date Databricks Certified Professional Data Engineer Exam (Databricks-Certified-Professional-Data-Engineer) study material that every candidate can rely on for good preparation. Our top priority is to help you pass the Databricks Certified Professional Data Engineer Exam (Databricks-Certified-Professional-Data-Engineer) exam on the first try.
| Section | Objectives |
|---|---|
| Topic 1: Production Pipelines and Orchestration | - Automate ETL pipelines and scheduling - Pipeline reliability and fault tolerance - Build and manage workflows using Databricks Jobs |
| Topic 2: Data Ingestion and Transformation | - Ingest data using Apache Spark and Databricks - Handle batch and streaming data pipelines - Transform and clean datasets using Spark SQL and DataFrame APIs |
| Topic 3: Security, Governance, Monitoring, and Optimization | - Monitor and optimize Spark workloads - Implement Unity Catalog governance and access control - Cost optimization and performance tuning |
| Topic 4: Data Modeling and Storage | - Delta Lake table design and optimization - Schema evolution and data partitioning strategies - Design scalable data lakehouse architectures |
>> Latest Databricks-Certified-Professional-Data-Engineer Mock Exam <<
Owing to the industrious dedication of our experts and other working staff, our Databricks-Certified-Professional-Data-Engineer study materials grow to be more mature and are able to fight against any difficulties. Our Databricks-Certified-Professional-Data-Engineer preparation exam have achieved high pass rate in the industry, and we always maintain a 99% pass rate with our endless efforts. We have to admit that behind such a starling figure, there embrace mass investments from our company on our Databricks-Certified-Professional-Data-Engineer learning quiz. But it is all worth that as the high pass rate can make sure our customers pass the exam by the best percentage.
NEW QUESTION # 125
The data engineering team maintains the following code: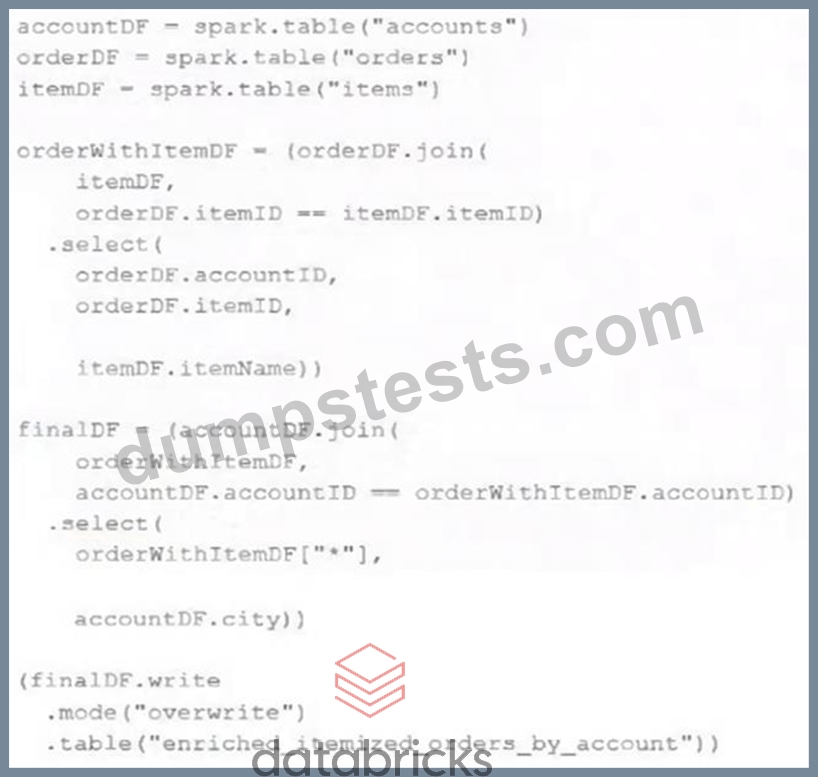
Assuming that this code produces logically correct results and the data in the source tables has been de-duplicated and validated, which statement describes what will occur when this code is executed?
Answer: D
Explanation:
Cmd 1: min("sale_date").alias("first_transaction_date"): Determines the earliest sale date for the customer.
Cmd 2: max("sale_date").alias("last_transaction_date"): Determines the latest sale date for the customer.
Cmd 3: mean("sale_total").alias("average_sales"): Calculates the average sale amount for the customer.
Cmd 4: countDistinct("order_id").alias("total_orders"): Counts the number of unique orders placed by the customer.
Cmd 5: sum("sale_total").alias("lifetime_value"): Calculates the total sales amount (lifetime value) for the customer.
Writes Data to gold_customer_lifetime_sales_summary Table:
The .write.mode("overwrite").table("gold_customer_lifetime_sales_summary") command writes the aggregated data to the gold_customer_lifetime_sales_summary table.
The mode("overwrite") specifies that the existing data in the gold_customer_lifetime_sales_summary table will be completely replaced by the new aggregated data.
Conclusion:
When this code is executed, it reads all records from the silver_customer_sales table, performs the specified aggregations grouped by customer_id, and then overwrites the entire gold_customer_lifetime_sales_summary table with the aggregated results. Therefore, option D accurately describes this process: "The gold_customer_lifetime_sales_summary table will be overwritten by aggregated values calculated from all records in the silver_customer_sales table as a batch job." Explanation:
The provided PySpark code performs the following operations:
Reads Data from silver_customer_sales Table:
The code starts by accessing the silver_customer_sales table using the spark.table method.
Groups Data by customer_id:
The .groupBy("customer_id") function groups the data based on the customer_id column.
Aggregates Data:
The .agg() function computes several aggregate metrics for each customer_id:
Reference:
PySpark DataFrame groupBy
PySpark Basics
NEW QUESTION # 126
A junior data engineer has manually configured a series of jobs using the Databricks Jobs UI. Upon reviewing their work, the engineer realizes that they are listed as the "Owner" for each job. They attempt to transfer
"Owner" privileges to the "DevOps" group, but cannot successfully accomplish this task.
Which statement explains what is preventing this privilege transfer?
Answer: C
Explanation:
The reason why the junior data engineer cannot transfer "Owner" privileges to the "DevOps" group is that Databricks jobs must have exactly one owner, and the owner must be an individual user, not a group. A job cannot have more than one owner, and a job cannot have a group as an owner. The owner of a job is the user who created the job, or the user who was assigned the ownership by another user. The owner of a job has the highest level of permission on the job, and can grant or revoke permissions to other users or groups. However, the owner cannot transfer the ownership to a group, only to another user. Therefore, the junior data engineer's attempt to transfer "Owner" privileges to the "DevOps" group is not possible. References:
* Jobs access control: https://docs.databricks.com/security/access-control/table-acls/index.html
* Job permissions: https://docs.databricks.com/security/access-control/table-acls/privileges.html#job- permissions
NEW QUESTION # 127
The marketing team is looking to share data in an aggregate table with the sales organization, but the field names used by the teams do not match, and a number of marketing specific fields have not been approval for the sales org.
Which of the following solutions addresses the situation while emphasizing simplicity?
Answer: B
Explanation:
Creating a view is a straightforward solution that can address the need for field name standardization and selective field sharing between departments. A view allows for presenting a transformed version of the underlying data without duplicating it. In this scenario, the view would only include the approved fields for the sales team and rename any fields as per their naming conventions.
References:
* Databricks documentation on using SQL views in Delta Lake: https://docs.databricks.com/delta/quick- start.html#sql-views
NEW QUESTION # 128
A data governance team at a large enterprise is improving data discoverability across its organization. The team has hundreds of tables in their Databricks Lakehouse with thousands of columns that lack proper documentation. Many of these tables were created by different teams over several years, with missing context about column meanings and business logic. The data governance team needs to quickly generate comprehensive column descriptions for all existing tables to meet compliance requirements and improve data literacy across the organization. They want to leverage modern capabilities to automatically generate meaningful descriptions rather than manually documenting each column, which would take months to complete.
Which approach should the team use in Databricks to automatically generate column comments and descriptions for existing tables?
Answer: C
Explanation:
Comprehensive and Detailed Explanation From Exact Extract of Databricks Data Engineer Documents:
Databricks Catalog Explorer provides a feature called AI Generate that automatically produces intelligent comments for columns. This feature uses metadata such as column names, types, patterns, and sampled values to generate human-readable documentation. According to the documentation, this is the recommended method to rapidly enrich schema metadata and improve data discoverability, especially at enterprise scale. Unlike DESCRIBE HISTORY or DESCRIBE TABLE, which only surface technical schema details, AI Generate directly produces business-oriented descriptions. PySpark statistical functions (df.describe) only return numeric statistics and cannot generate descriptive metadata. Thus, AI Generate in Catalog Explorer is the correct approach.
NEW QUESTION # 129
A data engineer manages a production Lakeflow Declarative Pipeline that processes customer transaction data. The pipeline includes several data quality expectations such as transaction_amount > 0 and customer_id IS NOT NULL. These expectations are defined using the EXPECT clause in SQL.
The engineer aims to monitor the pipeline's data quality by analyzing the number of records that passed or failed each expectation during the latest pipeline update. The Lakeflow Declarative Pipelines event logs are stored in a Delta table named event_log_table.
For the most recent pipeline update, determine a programmatically appropriate approach to extract information like the name of each expectation, associated dataset, count of records that passed the expectation, and count of records that failed the expectation.
Which method retrieves the desired data quality metrics from the Lakeflow Declarative Pipelines event log?
Answer: D
Explanation:
The Databricks documentation specifies that for Lakeflow Declarative Pipelines, detailed data quality metrics are logged as events of type expectation_result within the event log. Each record of this type contains fields including expectation_name, dataset_name, passed_records, and failed_records. Filtering on event_type = ' expectation_result ' and expanding the details field allows retrieving metrics for each expectation from the most recent pipeline update. While flow_progress provides summary statistics and data_quality events aggregate results, only expectation_result events provide granular, per-expectation metrics required for audit and monitoring automation.
NEW QUESTION # 130
......
In short, we live in an age full of challenges. So we must continually update our knowledge and ability. If you are an ambitious person, our Databricks-Certified-Professional-Data-Engineer exam questions can be your best helper. There are many kids of Databricks-Certified-Professional-Data-Engineer study materials in the market. You must have no idea to choose which one. It does not matter. Our Databricks Certification guide braindumps are the most popular products in the market now. Just buy our Databricks-Certified-Professional-Data-Engineer learning quiz, and you will get all you want.
Databricks-Certified-Professional-Data-Engineer Exam Testking: https://www.dumpstests.com/Databricks-Certified-Professional-Data-Engineer-latest-test-dumps.html