Quiz 2026 Databricks Databricks-Certified-Professional-Data-Engineer: Databricks Certified Professional Data Engineer Exam Exam Review

Our brand has marched into the international market and many overseas clients purchase our Databricks-Certified-Professional-Data-Engineer exam dump online. As the saying goes, Rome is not build in a day. The achievements we get hinge on the constant improvement on the quality of our Databricks-Certified-Professional-Data-Engineer latest study question and the belief we hold that we should provide the best service for the clients. The great efforts we devote to the Databricks exam dump and the experiences we accumulate for decades are incalculable. All of these lead to our success of Databricks-Certified-Professional-Data-Engineer learning file and high prestige.
| Section | Weight | Objectives |
|---|
| Data Warehouse and Lakehouse Architecture | 15-20% | - Lakehouse architecture principles
- 1. Bronze, silver, gold data layers
- 2. Data governance fundamentals
- 3. Differences between data lake, data warehouse, and lakehouse
|
| Delta Lake | 20-25% | - Delta Lake fundamentals
- 1. Optimize and Z-order
- 2. ACID transactions
- 3. Time travel and data versioning
- Delta Lake operations
- 1. Delta Live Tables
- 2. Merge, update, delete operations
- 3. Schema evolution and enforcement
|
| Data Ingestion | 15-20% | - Streaming ingestion
- 1. Kafka integration
- 2. Structured streaming fundamentals
- Batch ingestion methods
- 1. Integration with external systems
- 2. Spark APIs for ingestion
- 3. DBR autoloader
|
| Pipeline Development and Orchestration | 10-15% | - Databricks workflows
- 1. Monitoring and alerting
- 2. Jobs and job scheduling
- 3. Task dependencies and orchestration
|
| Data Processing with Spark | 25-30% | - Python and SQL for data engineering
- 1. Built-in and user-defined functions
- 2. Spark APIs in Python
- 3. Performance optimization techniques
- Spark DataFrames and Spark SQL
- 1. Spark SQL queries and functions
- 2. Window functions
- 3. DataFrame operations and transformations
|
>> Databricks-Certified-Professional-Data-Engineer Exam Review <<
New Databricks-Certified-Professional-Data-Engineer Test Prep & Reliable Databricks-Certified-Professional-Data-Engineer Braindumps Files
Whether you are a student or a professional who has already taken part in the work, you must feel the pressure of competition now. However, no matter how fierce the competition is, as long as you have the strength, you can certainly stand out. And our Databricks-Certified-Professional-Data-Engineer exam questions can help on your way to be successful. Our data shows that 98% to 100% of our worthy customers passed the Databricks-Certified-Professional-Data-Engineer Exam and got the certification. And we believe you will be the next one as long as you buy our Databricks-Certified-Professional-Data-Engineer study guide.
Databricks Certified Professional Data Engineer Exam Sample Questions (Q20-Q25):
NEW QUESTION # 20
The data engineering team maintains the following code:
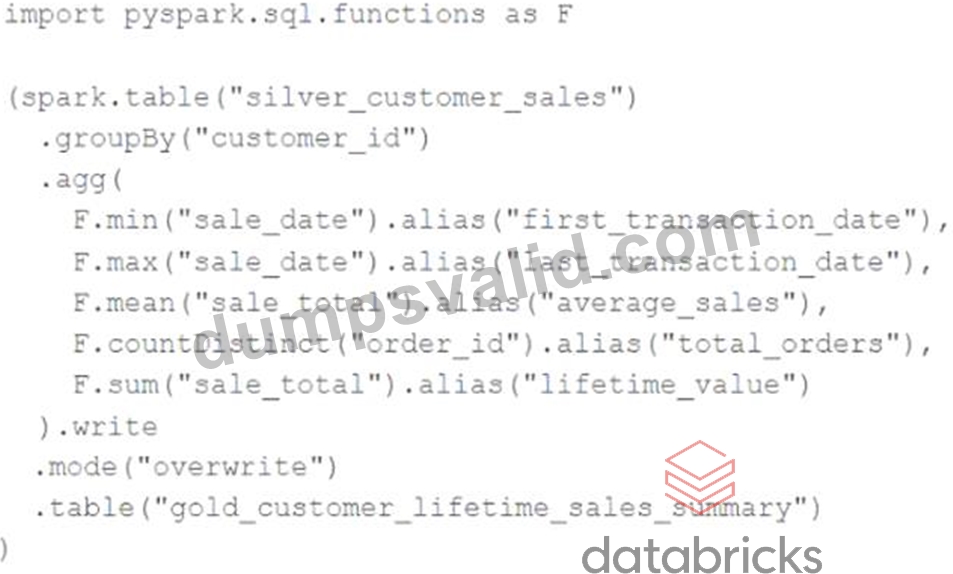
Assuming that this code produces logically correct results and the data in the source table has been de-duplicated and validated, which statement describes what will occur when this code is executed?
- A. An incremental job will detect if new rows have been written to the silver_customer_sales table; if new rows are detected, all aggregates will be recalculated and used to overwrite the gold_customer_lifetime_sales_summary table.
- B. An incremental job will leverage running information in the state store to update aggregate values in the gold_customer_lifetime_sales_summary table.
- C. A batch job will update the gold_customer_lifetime_sales_summary table, replacing only those rows that have different values than the current version of the table, using customer_id as the primary key.
- D. The silver_customer_sales table will be overwritten by aggregated values calculated from all records in the gold_customer_lifetime_sales_summary table as a batch job.
- E. The gold_customer_lifetime_sales_summary table will be overwritten by aggregated values calculated from all records in the silver_customer_sales table as a batch job.
Answer: E
Explanation:
This code is using the pyspark.sql.functions library to group the silver_customer_sales table by customer_id and then aggregate the data using the minimum sale date, maximum sale total, and sum of distinct order ids.
The resulting aggregated data is then written to the gold_customer_lifetime_sales_summary table, overwriting any existing data in that table. This is a batch job that does not use any incremental or streaming logic, and does not perform any merge or update operations. Therefore, the code will overwrite the gold table with the aggregated values from the silver table every time it is executed. References:
* https://docs.databricks.com/spark/latest/dataframes-datasets/introduction-to-dataframes-python.html
* https://docs.databricks.com/spark/latest/dataframes-datasets/transforming-data-with-dataframes.html
* https://docs.databricks.com/spark/latest/dataframes-datasets/aggregating-data-with-dataframes.html
NEW QUESTION # 21
A data engineering team uses Databricks Lakehouse Monitoring to track the percent_null metric for a critical column in their Delta table. The profile metrics table ( prod_catalog.prod_schema.
customer_data_profile_metrics ) stores hourly percent_null values. The team wants to trigger an alert when the daily average of percent_null exceeds 5% for three consecutive days, while ensuring notifications are not spammed during sustained issues. Which SQL alert configuration achieves this goal while minimizing false positives and redundant notifications?
- A. SELECT percent_null
FROM prod_catalog.prod_schema.customer_data_profile_metrics
WHERE window.end > = CURRENT_TIMESTAMP - INTERVAL ' 1 ' DAY
Alert Condition: percent_null > 5
Notification Frequency: At most every 24 hours - B. SELECT SUM(CASE WHEN percent_null > 5 THEN 1 ELSE 0 END) AS violation_days FROM prod_catalog.prod_schema.customer_data_profile_metrics WHERE window.end > = CURRENT_TIMESTAMP - INTERVAL ' 3 ' DAY Alert Condition: violation_days > = 3 Notification Frequency: Just once
- C. SELECT AVG(percent_null) AS daily_avg
FROM prod_catalog.prod_schema.customer_data_profile_metrics
WHERE window.end > = CURRENT_TIMESTAMP - INTERVAL ' 3 ' DAY
Alert Condition: daily_avg > 5
Notification Frequency: Each time alert is evaluated - D. WITH daily_avg AS (
SELECT
DATE_TRUNC( ' DAY ' , window.end) AS day,
AVG(percent_null) AS avg_null
FROM prod_catalog.prod_schema.customer_data_profile_metrics
GROUP BY DATE_TRUNC( ' DAY ' , window.end)
)
SELECT day, avg_null
FROM daily_avg
ORDER BY day DESC
LIMIT 3
Alert Condition: ALL avg_null > 5 for the latest 3 rows
Notification Frequency: Just once
Answer: D
Explanation:
Databricks SQL alerts support alert conditions over aggregated query results, including AVG , and they support notification-frequency behavior that avoids repeated alerts during a sustained triggered state.
Databricks documents that with Just Once , a notification is sent when the alert changes from OK to TRIGGERED , but not repeatedly while it remains triggered. ( Databricks Documentation ) Option A is the only choice that correctly computes a daily average, checks the latest three daily rows, and pairs that with the anti-spam Just Once notification behavior. Option B checks only raw hourly values over one day, option C averages across the entire three-day span rather than requiring three consecutive daily breaches, and option D counts hourly threshold violations instead of true daily-average violations. ( Databricks Documentation )
======
NEW QUESTION # 22
A junior data engineer has manually configured a series of jobs using the Databricks Jobs UI. Upon reviewing their work, the engineer realizes that they are listed as the " Owner " for each job. They attempt to transfer " Owner " privileges to the " DevOps " group, but cannot successfully accomplish this task.
Which statement explains what is preventing this privilege transfer?
- A. A user can only transfer job ownership to a group if they are also a member of that group.
- B. Databricks jobs must have exactly one owner; " Owner " privileges cannot be assigned to a group.
- C. The creator of a Databricks job will always have " Owner " privileges; this configuration cannot be changed.
- D. Only workspace administrators can grant " Owner " privileges to a group.
- E. Other than the default " admins " group, only individual users can be granted privileges on jobs.
Answer: B
Explanation:
The reason why the junior data engineer cannot transfer "Owner" privileges to the "DevOps" group is that Databricks jobs must have exactly one owner, and the owner must be an individual user, not a group. A job cannot have more than one owner, and a job cannot have a group as an owner. The owner of a job is the user who created the job, or the user who was assigned the ownership by another user. The owner of a job has the highest level of permission on the job, and can grant or revoke permissions to other users or groups. However, the owner cannot transfer the ownership to a group, only to another user. Therefore, the junior data engineer's attempt to transfer "Owner" privileges to the "DevOps" group is not possible. References:
* Jobs access control : https://docs.databricks.com/security/access-control/table-acls/index.html
* Job permissions : https://docs.databricks.com/security/access-control/table-acls/privileges.html#job- permissions
NEW QUESTION # 23
A data engineer is using Lakeflow Declarative Pipeline to propagate row deletions from a source bronze table (user_bronze) to a target silver table (user_silver). The engineer wants deletions in user_bronze to automatically delete corresponding rows in user_silver during pipeline execution.
Which configuration ensures deletions in the bronze table are propagated to the silver table?
- A. Enable CDF on user_silver, read its transaction log, and use MERGE to sync deletions.
- B. Enable Change Data Feed (CDF) on user_bronze, read its CDF stream, and use apply_changes() with apply_as_deletes=True for user_silver.
- C. Configure VACUUM on user_bronze to delete files, then rebuild user_silver from scratch.
- D. Use apply_changes without CDF and filter rows where _soft_deleted is true.
Answer: B
Explanation:
Comprehensive and Detailed Explanation From Exact Extract of Databricks Data Engineer Documents:
According to Databricks documentation, Change Data Feed (CDF) allows pipelines to read incremental data changes, including inserts, updates, and deletes, from a Delta table. When deletions occur in the source table, reading the CDF stream ensures downstream consumers receive the deletion records. The Lakeflow Declarative Pipelines API provides the apply_changes() function (or auto-CDC pipelines) with the apply_as_deletes parameter to correctly apply those deletions to the target table. This enables automatic synchronization between bronze and silver layers. Options A and D either require manual handling or complete rebuilds, and C incorrectly applies CDF to the target rather than the source. Therefore, enabling CDF on the bronze table and using apply_as_deletes=True is the correct, Databricks-supported configuration.
NEW QUESTION # 24
The data engineering team maintains the following code:
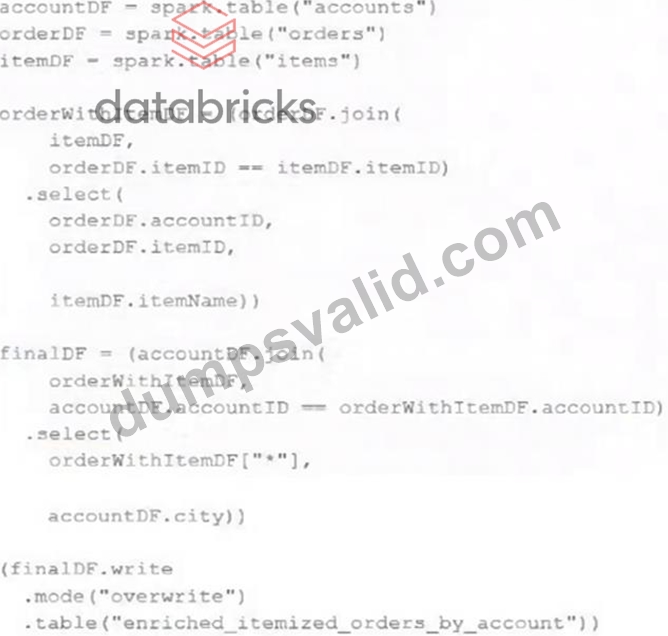
Assuming that this code produces logically correct results and the data in the source tables has been de- duplicated and validated, which statement describes what will occur when this code is executed?
- A. An incremental job will detect if new rows have been written to any of the source tables; if new rows are detected, all results will be recalculated and used to overwrite the enriched_itemized_orders_by_account table.
- B. An incremental job will leverage information in the state store to identify unjoined rows in the source tables and write these rows to the enriched_iteinized_orders_by_account table.
- C. A batch job will update the enriched_itemized_orders_by_account table, replacing only those rows that have different values than the current version of the table, using accountID as the primary key.
- D. The enriched_itemized_orders_by_account table will be overwritten using the current valid version of data in each of the three tables referenced in the join logic.
- E. No computation will occur until enriched_itemized_orders_by_account is queried; upon query materialization, results will be calculated using the current valid version of data in each of the three tables referenced in the join logic.
Answer: D
Explanation:
The provided PySpark code performs the following operations:
* Reads Data from silver_customer_sales Table:
* The code starts by accessing the silver_customer_sales table using the spark.table method.
* Groups Data by customer_id:
* The .groupBy( " customer_id " ) function groups the data based on the customer_id column.
* Aggregates Data:
* The .agg() function computes several aggregate metrics for each customer_id:
* F.min( " sale_date " ).alias( " first_transaction_date " ): Determines the earliest sale date for the customer.
* F.max( " sale_date " ).alias( " last_transaction_date " ): Determines the latest sale date for the customer.
* F.mean( " sale_total " ).alias( " average_sales " ): Calculates the average sale amount for the customer.
* F.countDistinct( " order_id " ).alias( " total_orders " ): Counts the number of unique orders placed by the customer.
* F.sum( " sale_total " ).alias( " lifetime_value " ): Calculates the total sales amount (lifetime value) for the customer.
* Writes Data to gold_customer_lifetime_sales_summary Table:
* The .write.mode( " overwrite " ).table( " gold_customer_lifetime_sales_summary " ) command writes the aggregated data to the gold_customer_lifetime_sales_summary table.
* The mode( " overwrite " ) specifies that the existing data in the
gold_customer_lifetime_sales_summary table will be completely replaced by the new aggregated data.
Conclusion:
When this code is executed, it reads all records from the silver_customer_sales table, performs the specified aggregations grouped by customer_id, and then overwrites the entire gold_customer_lifetime_sales_summary table with the aggregated results. Therefore, option D accurately describes this process: " The gold_customer_lifetime_sales_summary table will be overwritten by aggregated values calculated from all records in the silver_customer_sales table as a batch job. " References:
PySpark DataFrame groupBy
PySpark Basics
NEW QUESTION # 25
......
Once you browser our official websites, you are bound to love our Databricks-Certified-Professional-Data-Engineer practice questions. All our Databricks-Certified-Professional-Data-Engineer study materials are displayed orderly on the web page. Also, you just need to click one kind; then you can know much about it. There have detailed introductions about the Databricks-Certified-Professional-Data-Engineer learnign braindumps such as price, version, free demo and so on. As long as you click on it, all the information will show up right away. It is quite convenient.
New Databricks-Certified-Professional-Data-Engineer Test Prep: https://www.dumpsvalid.com/Databricks-Certified-Professional-Data-Engineer-still-valid-exam.html
- Databricks-Certified-Professional-Data-Engineer Practice Engine - Databricks-Certified-Professional-Data-Engineer Vce Study Material - Databricks-Certified-Professional-Data-Engineer Online Test Engine 💠 Download ➠ Databricks-Certified-Professional-Data-Engineer 🠰 for free by simply entering ⏩ www.prepawayexam.com ⏪ website 🔕Databricks-Certified-Professional-Data-Engineer Books PDF
- Databricks-Certified-Professional-Data-Engineer Discount Code ✋ Excellect Databricks-Certified-Professional-Data-Engineer Pass Rate 🧁 Databricks-Certified-Professional-Data-Engineer Pdf Braindumps 🏟 Search for ▛ Databricks-Certified-Professional-Data-Engineer ▟ on ( www.pdfvce.com ) immediately to obtain a free download 🟥Databricks-Certified-Professional-Data-Engineer New Dumps Ebook
- Don't Fail Databricks-Certified-Professional-Data-Engineer Exam - Verified By www.exam4labs.com 🧹 Simply search for ➽ Databricks-Certified-Professional-Data-Engineer 🢪 for free download on 「 www.exam4labs.com 」 🎺Databricks-Certified-Professional-Data-Engineer Reliable Exam Papers
- Databricks-Certified-Professional-Data-Engineer Reliable Exam Papers 🏐 Certification Databricks-Certified-Professional-Data-Engineer Training ⚒ Excellect Databricks-Certified-Professional-Data-Engineer Pass Rate 💮 Open ( www.pdfvce.com ) and search for 「 Databricks-Certified-Professional-Data-Engineer 」 to download exam materials for free 🍔Excellect Databricks-Certified-Professional-Data-Engineer Pass Rate
- Don't Fail Databricks-Certified-Professional-Data-Engineer Exam - Verified By www.exam4labs.com 🦚 Open ➤ www.exam4labs.com ⮘ enter ➽ Databricks-Certified-Professional-Data-Engineer 🢪 and obtain a free download 🥍Databricks-Certified-Professional-Data-Engineer Pdf Braindumps
- Free Download Databricks-Certified-Professional-Data-Engineer Exam Review - Guaranteed Databricks Databricks-Certified-Professional-Data-Engineer Exam Success with Perfect New Databricks-Certified-Professional-Data-Engineer Test Prep 🍹 Search on [ www.pdfvce.com ] for { Databricks-Certified-Professional-Data-Engineer } to obtain exam materials for free download 📱Databricks-Certified-Professional-Data-Engineer Actual Dump
- Databricks-Certified-Professional-Data-Engineer Quiz Braindumps - Databricks-Certified-Professional-Data-Engineer Pass-Sure torrent - Databricks-Certified-Professional-Data-Engineer Exam Torrent 🐧 Open 【 www.troytecdumps.com 】 and search for ⮆ Databricks-Certified-Professional-Data-Engineer ⮄ to download exam materials for free ➡Premium Databricks-Certified-Professional-Data-Engineer Files
- New Databricks-Certified-Professional-Data-Engineer Exam Review | High-quality Databricks-Certified-Professional-Data-Engineer: Databricks Certified Professional Data Engineer Exam 100% Pass 🥾 Open ➡ www.pdfvce.com ️⬅️ enter ➠ Databricks-Certified-Professional-Data-Engineer 🠰 and obtain a free download 🦛Reliable Databricks-Certified-Professional-Data-Engineer Exam Cram
- Databricks-Certified-Professional-Data-Engineer Quiz Braindumps - Databricks-Certified-Professional-Data-Engineer Pass-Sure torrent - Databricks-Certified-Professional-Data-Engineer Exam Torrent 🚶 Open website ➠ www.practicevce.com 🠰 and search for 《 Databricks-Certified-Professional-Data-Engineer 》 for free download ✏Databricks-Certified-Professional-Data-Engineer Actual Dump
- Databricks-Certified-Professional-Data-Engineer Discount Code 🚕 Databricks-Certified-Professional-Data-Engineer Actual Dump 👜 Valid Databricks-Certified-Professional-Data-Engineer Practice Materials 🎶 Open ▛ www.pdfvce.com ▟ and search for [ Databricks-Certified-Professional-Data-Engineer ] to download exam materials for free 🤺Databricks-Certified-Professional-Data-Engineer Interactive Questions
- Databricks-Certified-Professional-Data-Engineer Practice Engine - Databricks-Certified-Professional-Data-Engineer Vce Study Material - Databricks-Certified-Professional-Data-Engineer Online Test Engine 🐰 Easily obtain ✔ Databricks-Certified-Professional-Data-Engineer ️✔️ for free download through ▷ www.practicevce.com ◁ 🧆Databricks-Certified-Professional-Data-Engineer Reliable Exam Papers
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, Disposable vapes