Latest Certified-Data-Engineer-Professional Study Guide, Study Certified-Data-Engineer-Professional Reference

We believe that you can buy our Certified-Data-Engineer-Professional demo PDF torrent without any misgivings, Firstly, we have a strong experts team who are devoted themselves to research of the technology, which ensure the high-quality of our Certified-Data-Engineer-Professional Dump guide, BraindumpsVCE offers Databricks Certified Data Engineer Professional Certified-Data-Engineer-Professional free Updates. It is no exaggeration to say that the value of the certification training materials is equivalent to all exam related reference books.
| Section | Objectives |
|---|
| Data Transformation, Cleansing, and Quality | - Transform and validate data
- 1. Write efficient Spark SQL and PySpark code for advanced transformations including window functions, joins, and aggregations
- 2. Develop a quarantining process for bad data with Lakeflow Declarative Pipelines or Auto Loader in classic jobs
|
| Monitoring and Alerting | - Alerting
- 1. Use SQL Alerts to monitor data quality
- 2. Use the Workflows UI and Jobs API to configure notifications for job status and performance issues
- Monitoring
- 1. Use system tables for observability of resource utilization, cost, auditing, and workloads
- 2. Use Lakeflow Declarative Pipelines event logs to monitor pipelines
- 3. Use Query Profile and Spark UI to monitor workloads
- 4. Use Databricks REST APIs and Databricks CLI to monitor jobs and pipelines
|
| Debugging and Deploying | - Debugging and Troubleshooting
- 1. Identify diagnostic information using Spark UI, cluster logs, system tables, and query profiles to troubleshoot errors
- 2. Use Lakeflow Declarative Pipelines event logs and Spark UI to debug Lakeflow Declarative Pipelines and Spark pipelines
- 3. Analyze errors and remediate failed job runs using job repairs and parameter overrides
- Deploying CI/CD
- 1. Configure and integrate Git-based CI/CD workflows using Databricks Git folders for notebook and code deployment
- 2. Build and deploy Databricks resources using Databricks Asset Bundles
|
| Ensuring Data Security and Compliance | - Ensuring Compliance
- 1. Implement compliant batch and streaming pipelines that detect and mask PII
- 2. Develop data purging solutions that comply with data retention policies
- Applying Data Security Mechanisms
- 1. Apply anonymization and pseudonymization methods including hashing, tokenization, suppression, and generalization
- 2. Use row filters and column masks to protect sensitive table data
- 3. Use ACLs to secure workspace objects and enforce the principle of least privilege
|
| Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Create an append-only data pipeline capable of handling both batch and streaming data using Delta
- 2. Ingest formats including Delta Lake, Parquet, ORC, AVRO, JSON, CSV, XML, text, and binary data from sources such as message buses and cloud storage
|
| Data Sharing and Federation | - Share and federate data
- 1. Demonstrate secure Delta Sharing between Databricks deployments using Databricks-to-Databricks sharing or with external platforms using the open sharing protocol
- 2. Configure Lakehouse Federation with appropriate governance across supported source systems
- 3. Use Delta Sharing to share live data from the Lakehouse with any computing platform
|
| Developing Code for Data Processing using Python and SQL | - Using Python and Tools for Development
- 1. Manage and troubleshoot external third-party library installations and dependencies, including PyPI packages, local wheels, and source archives
- 2. Design and implement a scalable Python project structure optimized for Databricks Asset Bundles, enabling modular development, deployment automation, and CI/CD integration
- 3. Develop User-Defined Functions using Pandas/Python UDF
- Building and Testing an ETL Pipeline with Lakeflow Declarative Pipelines, SQL, and Apache Spark
- 1. Explain the advantages and disadvantages of streaming tables compared to materialized views
- 2. Use APPLY CHANGES APIs to simplify CDC in Lakeflow Declarative Pipelines
- 3. Develop unit and integration tests using assertDataFrameEqual, assertSchemaEqual, DataFrame.transform, testing frameworks, and debugging tools
- 4. Build and manage reliable, production-ready batch and streaming data pipelines using Lakeflow Declarative Pipelines and Auto Loader
- 5. Create and automate ETL workloads using Jobs through the UI, APIs, or CLI
- 6. Create pipeline components using control flow operators such as if/else and foreach
- 7. Compare Spark Structured Streaming and Lakeflow Declarative Pipelines to determine the optimal approach for scalable ETL pipelines
- 8. Choose appropriate configurations for environments, dependencies, high-memory notebook tasks, and retry behavior
|
| Cost & Performance Optimization | - Optimize cost and performance
- 1. Understand how and why Unity Catalog managed tables reduce operational overhead and maintenance burden
- 2. Use query profiling to identify bottlenecks such as inefficient joins and data shuffling
- 3. Understand Databricks query optimization techniques for large datasets, including data skipping and file pruning
- 4. Understand Delta optimization techniques such as deletion vectors and liquid clustering
- 5. Apply Change Data Feed to address streaming table limitations and improve latency
|
| Data Modeling | - Design and optimize data models
- 1. Identify the benefits of liquid clustering over partitioning and Z-Ordering
- 2. Simplify data layout decisions and optimize query performance using liquid clustering
- 3. Design and implement scalable data models using Delta Lake to manage large datasets
- 4. Design dimensional models for analytical workloads with efficient querying and aggregation
|
| Data Governance | - Govern enterprise data
- 1. Demonstrate understanding of the Unity Catalog permission inheritance model
- 2. Create and add descriptions and metadata to enterprise data to improve discoverability
|
>> Latest Certified-Data-Engineer-Professional Study Guide <<
Study Certified-Data-Engineer-Professional Reference & Vce Certified-Data-Engineer-Professional Files
Recent years many ambitious young men take part in Databricks certification exams. Many candidates may wonder how to prepare for Certified-Data-Engineer-Professional exam (questions and answers). My advice is that firstly you should inquire about exam details from exam center such as exam cost, how many times you can take exam per year and the exact date, how long the real test last, the examination requirements and syllabus. And then purchase our Certified-Data-Engineer-Professional Exam Questions And Answers, you will clear exams certainly.
Databricks Certified Data Engineer Professional Sample Questions (Q142-Q147):
NEW QUESTION # 142
A data engineer wants to refactor the following DLT code, which includes multiple table definitions with very similar code.
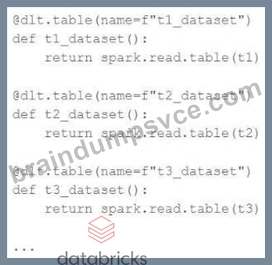
In an attempt to programmatically create these tables using a parameterized table definition, the data engineer writes the following code.
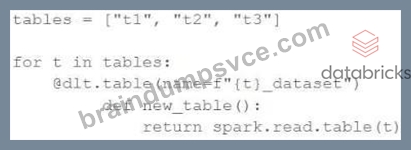
The pipeline runs an update with this refactored code, but generates a different DAG showing incorrect configuration values for these tables.
How can the data engineer fix this?
- A. Wrap the for loop inside another table definition, using generalized names and properties to replace with those from the inner table definition.
- B. Convert the list of configuration values to a dictionary of table settings, using table names as keys.
- C. Load the configuration values for these tables from a separate file, located at a path provided by a pipeline parameter.
- D. Move the table definition into a separate function, and make calls to this function using different input parameters inside the for loop.
Answer: D
Explanation:
In the provided refactored code, the for loop dynamically attempts to define multiple tables, but the use of a loop within the DLT (@dlt.table) decorator does not work properly because it results in a single function reference being overwritten for each iteration. This leads to an incorrect DAG because all the table definitions end up pointing to the last iteration of the loop.
NEW QUESTION # 143
A member of the data engineering team has submitted a short notebook that they wish to schedule as part of a larger data pipeline. Assume that the commands provided below produce the logically correct results when run as presented.
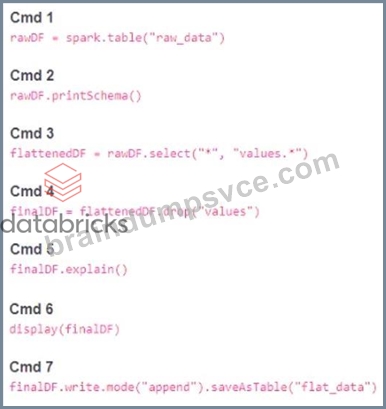
Which command should be removed from the notebook before scheduling it as a job?
- A. Cmd 4
- B. Cmd 6
- C. Cmd 5
- D. Cmd 3
- E. Cmd 2
Answer: B
Explanation:
When scheduling a Databricks notebook as a job, it's generally recommended to remove or modify commands that involve displaying output, such as using the display() function. Displaying data using display() is an interactive feature designed for exploration and visualization within the notebook interface and may not work well in a production job context.
The finalDF.explain() command, which provides the execution plan of the DataFrame transformations and actions, is often useful for debugging and optimizing queries. While it doesn't display interactive visualizations like display(), it can still be informative for understanding how Spark is executing the operations on your DataFrame.
NEW QUESTION # 144
A data engineer wants to enforce the principle of least privilege when configuring ACLs for Databricks jobs in a collaborative workspace. Which approach should the data engineer use?
- A. Grant CAN RUN permission to everyone and CAN MANAGE to a single admin group.
- B. Use only folder-level permissions and avoid setting permissions on individual jobs.
- C. Assign users only the minimum permission level (e.g., CAN RUN or CAN VIEW) required for their role on each job.
- D. Grant all users CAN MANAGE permission on all jobs to avoid access issues.
Answer: C
Explanation:
Assigning the minimum required permission level on each job ensures users can perform only the actions necessary for their role. This directly enforces the principle of least privilege while maintaining secure and controlled access in a collaborative workspace.
NEW QUESTION # 145
While reviewing a query's execution in the Databricks Query Profiler, a data engineer observes that the Top Operators panel shows a Sort operator with high Time Spent and Memory Peak metrics. The Spark UI also reports frequent data spilling. How should the data engineer address this issue?
- A. Increase the number of shuffle partitions to better distribute data.
- B. Switch to a broadcast join to reduce memory usage.
- C. Convert the sort operation to a filter operation.
- D. Repartition the DataFrame to a single partition before sorting.
Answer: A
Explanation:
Increasing the number of shuffle partitions distributes the data across more tasks, reducing per- task memory pressure during the sort operation. This helps mitigate spilling by lowering memory peak usage per task and improves overall sort performance in large-scale distributed queries.
NEW QUESTION # 146
A Delta Lake table representing metadata about content from user has the following schema:
user_id LONG, post_text STRING, post_id STRING, longitude FLOAT, latitude FLOAT, post_time TIMESTAMP, date DATE Based on the above schema, which column is a good candidate for partitioning the Delta Table?
- A. User_id
- B. Date
- C. Post_time
- D. Post_id
- E. latitude
Answer: B
Explanation:
Partitioning a Delta Lake table improves query performance by organizing data into partitions based on the values of a column. In the given schema, the date column is a good candidate for partitioning for several reasons:
Time-Based Queries: If queries frequently filter or group by date, partitioning by the date column can significantly improve performance by limiting the amount of data scanned. Granularity: The date column likely has a granularity that leads to a reasonable number of partitions (not too many and not too few). This balance is important for optimizing both read and write performance.
Data Skew: Other columns like post_id or user_id might lead to uneven partition sizes (data skew), which can negatively impact performance.
Partitioning by post_time could also be considered, but typically date is preferred due to its more manageable granularity.
NEW QUESTION # 147
......
Considering all customers’ sincere requirements, Certified-Data-Engineer-Professional test question persist in the principle of “Quality First and Clients Supreme” all along and promise to our candidates with plenty of high-quality products, considerate after-sale services as well as progressive management ideas. To be out of the ordinary and seek an ideal life, we must master an extra skill to get high scores and win the match in the workplace. Our Certified-Data-Engineer-Professional Exam Question can help make your dream come true. What’s more, you can have a visit of our website that provides you more detailed information about the Certified-Data-Engineer-Professional guide torrent.
Study Certified-Data-Engineer-Professional Reference: https://www.braindumpsvce.com/Certified-Data-Engineer-Professional_exam-dumps-torrent.html
- Pass Guaranteed 2026 Databricks Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional –Trustable Latest Study Guide 💔 Open 【 www.troytecdumps.com 】 enter ⮆ Certified-Data-Engineer-Professional ⮄ and obtain a free download 🆖Certified-Data-Engineer-Professional Reliable Test Question
- New Certified-Data-Engineer-Professional Exam Dumps ♿ Study Certified-Data-Engineer-Professional Material 🎍 Test Certified-Data-Engineer-Professional Sample Online 🕊 Open ➤ www.pdfvce.com ⮘ and search for ⏩ Certified-Data-Engineer-Professional ⏪ to download exam materials for free 🎳Certified-Data-Engineer-Professional Latest Exam Vce
- Certified-Data-Engineer-Professional Certification Sample Questions 🚌 Test Certified-Data-Engineer-Professional Sample Online 🥼 Braindump Certified-Data-Engineer-Professional Free 👬 Enter ▛ www.troytecdumps.com ▟ and search for ▷ Certified-Data-Engineer-Professional ◁ to download for free 👩Certified-Data-Engineer-Professional Latest Test Questions
- Practice Exam Software Databricks Certified-Data-Engineer-Professional Exam Questions ✋ Search for ☀ Certified-Data-Engineer-Professional ️☀️ and download it for free immediately on ✔ www.pdfvce.com ️✔️ 🏏Valid Certified-Data-Engineer-Professional Exam Duration
- Databricks Certified-Data-Engineer-Professional Exam Questions - Easy Way To Prepare [2026] 🎡 Open ➡ www.testkingpass.com ️⬅️ enter ▷ Certified-Data-Engineer-Professional ◁ and obtain a free download 📶Certified-Data-Engineer-Professional Latest Test Questions
- Certified-Data-Engineer-Professional Reliable Test Question 🛢 Certified-Data-Engineer-Professional Certification Sample Questions 👺 Instant Certified-Data-Engineer-Professional Access 👪 Open website 【 www.pdfvce.com 】 and search for ➠ Certified-Data-Engineer-Professional 🠰 for free download 🕧Latest Certified-Data-Engineer-Professional Dumps Questions
- Quiz 2026 Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional Pass-Sure Latest Study Guide 🥀 Search for ⏩ Certified-Data-Engineer-Professional ⏪ and easily obtain a free download on ➤ www.dumpsmaterials.com ⮘ 💈Valid Certified-Data-Engineer-Professional Exam Duration
- Pass Guaranteed Quiz 2026 Databricks Certified-Data-Engineer-Professional – The Best Latest Study Guide 🌐 Search on ( www.pdfvce.com ) for ⏩ Certified-Data-Engineer-Professional ⏪ to obtain exam materials for free download 🌙Latest Certified-Data-Engineer-Professional Dumps Questions
- Test Certified-Data-Engineer-Professional Simulator 🔚 Latest Certified-Data-Engineer-Professional Dumps Questions 🏨 Certified-Data-Engineer-Professional Latest Exam Vce ⛪ Open ⏩ www.testkingpass.com ⏪ enter ➥ Certified-Data-Engineer-Professional 🡄 and obtain a free download 🆑Certified-Data-Engineer-Professional Certification Sample Questions
- Test Certified-Data-Engineer-Professional Sample Online 🌕 Certified-Data-Engineer-Professional Trustworthy Pdf 💅 Certified-Data-Engineer-Professional Reliable Test Question ✋ 「 www.pdfvce.com 」 is best website to obtain ☀ Certified-Data-Engineer-Professional ️☀️ for free download 🕜Pdf Certified-Data-Engineer-Professional Free
- Pass Guaranteed Databricks - Certified-Data-Engineer-Professional - Trustable Latest Databricks Certified Data Engineer Professional Study Guide 🦯 Search for 【 Certified-Data-Engineer-Professional 】 and obtain a free download on ⏩ www.examdiscuss.com ⏪ 🚨Valid Certified-Data-Engineer-Professional Exam Duration
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, Disposable vapes