P.S.CertShikenがGoogle Driveで共有している無料の2026 Databricks Databricks-Generative-AI-Engineer-Associateダンプ:https://drive.google.com/open?id=1y50-ZioKznYk_lZJWmbFHLRZboeMU_FX
我々はDatabricksのDatabricks-Generative-AI-Engineer-Associate試験に準備するお客様により良いDatabricks-Generative-AI-Engineer-Associate問題集、より良いサービスを提供できて喜んでいます。あなたのDatabricks-Generative-AI-Engineer-Associate問題集を入手した後、我々はDatabricks-Generative-AI-Engineer-Associate真題の一年間の無料更新を提供します。我々の専門家たちはタイムリーに問題集を更新しています。この一年間で、もし更新したら、更新したDatabricks-Generative-AI-Engineer-Associate問題集は自動的にあなたのメールアドレスに送付します。あなたの満足度は、我々の行きているパワーです。
| Section | Objectives |
|---|---|
| Topic 1: Responsible AI and Governance | - Model governance
|
| Topic 2: Prompt Engineering | - Prompt design techniques
|
| Topic 3: Databricks Mosaic AI Platform | - Model development and serving
|
| Topic 4: Foundations of Generative AI | - Large Language Models (LLMs)
|
| Topic 5: Retrieval-Augmented Generation (RAG) | - RAG architecture
|
>> Databricks-Generative-AI-Engineer-Associate学習教材 <<
Databricks-Generative-AI-Engineer-Associate試験問題を選択した後は、プロセス全体を主導する傾向があるため、販売後のサービスプロバイダーとして常に知られています。したがって、Databricks-Generative-AI-Engineer-Associateラーニングガイドについて悩む必要はありません。 Databricks-Generative-AI-Engineer-Associateトレーニング資料は、パフォーマンスの向上とDatabricks-Generative-AI-Engineer-Associate試験の包括的なサービスに対する情熱を引き続き追求します。世界中のアフターセールススタッフがオンラインになり、お客様の疑問を安心させるだけでなく、すべての顧客に対する困難や不安を排除します。パズルを教えてください。一緒に考えてみましょう。
質問 # 22
A Generative Al Engineer is building a system which will answer questions on latest stock news articles.
Which will NOT help with ensuring the outputs are relevant to financial news?
正解:C
解説:
In the context of ensuring that outputs are relevant to financial news, increasing compute power (option B) does not directly improve the relevance of the LLM-generated outputs. Here's why:
Compute Power and Relevancy:
Increasing compute power can help the model process inputs faster, but it does not inherently improve the relevance of the answers. Relevancy depends on the data sources, the retrieval method, and the filtering mechanisms in place, not on how quickly the model processes the query.
What Actually Helps with Relevance:
Other methods, like content filtering, guardrails, or manual review, can directly impact the relevance of the model's responses by ensuring the model focuses on pertinent financial content. These methods help tailor the LLM's responses to the financial domain and avoid irrelevant or harmful outputs.
Why Other Options Are More Relevant:
A (Comprehensive Guardrail Framework): This will ensure that the model avoids generating content that is irrelevant or inappropriate in the finance sector.
C (Profanity Filter): While not directly related to financial relevancy, ensuring the output is clean and professional is still important in maintaining the quality of responses.
D (Manual Review): Incorporating human oversight to catch and correct issues with the LLM's output ensures the final answers are aligned with financial content expectations.
Thus, increasing compute power does not help with ensuring the outputs are more relevant to financial news, making option B the correct answer.
質問 # 23
A Generative AI Engineer is testing a simple prompt template in LangChain using the code below, but is getting an error.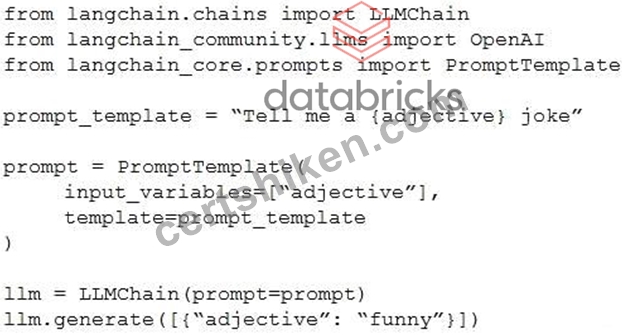
Assuming the API key was properly defined, what change does the Generative AI Engineer need to make to fix their chain?
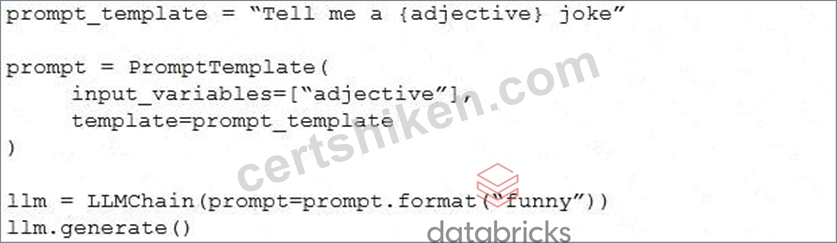
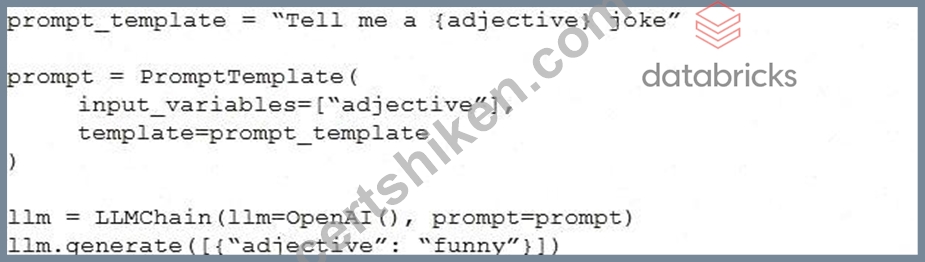
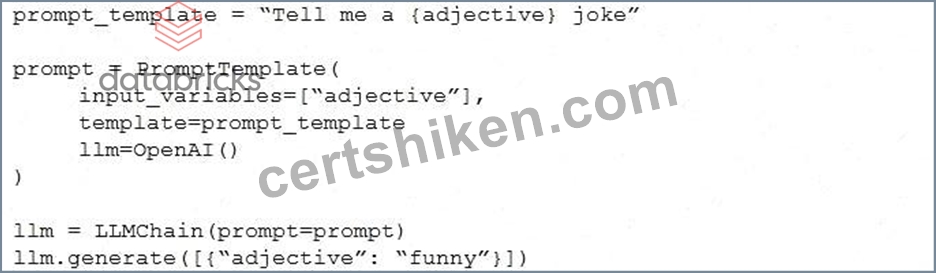
正解:D
解説:
To fix the error in the LangChain code provided for using a simple prompt template, the correct approach is Option C. Here ' s a detailed breakdown of why Option C is the right choice and how it addresses the issue:
* Proper Initialization : In Option C, the LLMChain is correctly initialized with the LLM instance specified as OpenAI(), which likely represents a language model (like GPT) from OpenAI. This is crucial as it specifies which model to use for generating responses.
* Correct Use of Classes and Methods :
* The PromptTemplate is defined with the correct format, specifying that adjective is a variable within the template. This allows dynamic insertion of values into the template when generating text.
* The prompt variable is properly linked with the PromptTemplate, and the final template string is passed correctly.
* The LLMChain correctly references the prompt and the initialized OpenAI() instance, ensuring that the template and the model are properly linked for generating output.
Why Other Options Are Incorrect:
* Option A : Misuses the parameter passing in generate method by incorrectly structuring the dictionary.
* Option B : Incorrectly uses prompt.format method which does not exist in the context of LLMChain and PromptTemplate configuration, resulting in potential errors.
* Option D : Incorrect order and setup in the initialization parameters for LLMChain, which would likely lead to a failure in recognizing the correct configuration for prompt and LLM usage.
Thus, Option C is correct because it ensures that the LangChain components are correctly set up and integrated, adhering to proper syntax and logical flow required by LangChain ' s architecture. This setup avoids common pitfalls such as type errors or method misuses, which are evident in other options.
質問 # 24
A Generative Al Engineer is building a production-ready LLM system which replies directly to customers.
The solution makes use of the Foundation Model API via provisioned throughput. They are concerned that the LLM could potentially respond in a toxic or otherwise unsafe way. They also wish to perform this with the least amount of effort.
Which approach will do this?
正解:B
解説:
The task is to prevent toxic or unsafe responses in an LLM system using the Foundation Model API with minimal effort. Let's assess the options.
* Option A: Host Llama Guard on Foundation Model API and use it to detect unsafe responses
* Llama Guard is a safety-focused model designed to detect toxic or unsafe content. Hosting it via the Foundation Model API (a Databricks service) integrates seamlessly with the existing system, requiring minimal setup (just deployment and a check step), and leverages provisioned throughput for performance.
* Databricks Reference:"Foundation Model API supports hosting safety models like Llama Guard to filter outputs efficiently"("Foundation Model API Documentation," 2023).
* Option B: Add some LLM calls to their chain to detect unsafe content before returning text
* Using additional LLM calls (e.g., prompting an LLM to classify toxicity) increases latency, complexity, and effort (crafting prompts, chaining logic), and lacks the specificity of a dedicated safety model.
* Databricks Reference:"Ad-hoc LLM checks are less efficient than purpose-built safety solutions" ("Building LLM Applications with Databricks").
* Option C: Add a regex expression on inputs and outputs to detect unsafe responses
* Regex can catch simple patterns (e.g., profanity) but fails for nuanced toxicity (e.g., sarcasm, context-dependent harm), requiring significant manual effort to maintain and update rules.
* Databricks Reference:"Regex-based filtering is limited for complex safety needs"("Generative AI Cookbook").
* Option D: Ask users to report unsafe responses
* User reporting is reactive, not preventive, and places burden on users rather than the system. It doesn't limit unsafe outputs proactively and requires additional effort for feedback handling.
* Databricks Reference:"Proactive guardrails are preferred over user-driven monitoring" ("Databricks Generative AI Engineer Guide").
Conclusion: Option A (Llama Guard on Foundation Model API) is the least-effort, most effective approach, leveraging Databricks' infrastructure for seamless safety integration.
質問 # 25
A Generative AI Engineer has deployed a customer-support agent in production that retrieves product documentation and generates responses. SMEs have been reviewing agent responses and providing feedback through a web interface that captures ratings of 1-5 stars and written comments. The engineer needs to systematically collect this feedback and use it to create an evaluation dataset that can be used to compare future agent versions against the current baseline performance.
Which approach should the engineer use to accomplish this task?
正解:A
解説:
Option B preserves the relationships between each user query, generated response, and expert assessment.
That context is necessary to turn production feedback into reusable evaluation cases. The engineer can curate representative examples from the Delta table, map them into MLflow's evaluation schema, and retain the dataset for consistent comparisons between agent versions. Where correctness scoring is required, experts should provide corrected answers or expected facts; a star rating alone is not a ground-truth answer. Keeping only written comments loses essential request context. Selecting only five-star interactions biases the dataset and excludes failure cases that future versions should improve. Deploying highly rated responses is not a substitute for evaluating an updated agent against a stable, representative benchmark. Databricks documentation
質問 # 26
A Generative AI Engineer wants to build an LLM-based solution to help a restaurant improve its online customer experience with bookings by automatically handling common customer inquiries. The goal of the solution is to minimize escalations to human intervention and phone calls while maintaining a personalized interaction. To design the solution, the Generative AI Engineer needs to define the input data to the LLM and the task it should perform.
Which input/output pair will support their goal?
正解:C
解説:
Context: The goal is to improve the online customer experience in a restaurant by handling common inquiries about bookings, minimizing escalations, and maintaining personalized interactions.
Explanation of Options:
* Option A: Grouping and summarizing chat logs by user could provide insights into customer interactions but does not directly address the task of handling booking inquiries or minimizing escalations.
* Option B: Using chat logs to generate interactive buttons for booking details directly supports the goal of facilitating online bookings, minimizing the need for human intervention by providing clear, interactive options for customers to self-serve.
* Option C: Classifying sentiment of customer reviews does not directly help with booking inquiries, although it might provide valuable feedback insights.
* Option D: Providing cancellation options is helpful but narrowly focuses on one aspect of the booking process and doesn't support the broader goal of handling common inquiries about bookings.
Option Bbest supports the goal of improving online interactions by using chat logs to generate actionable items for customers, helping them complete booking tasks efficiently and reducing the need for human intervention.
質問 # 27
......
DatabricksのDatabricks-Generative-AI-Engineer-Associateの認定試験に合格すれば、就職機会が多くなります。CertShikenはDatabricksのDatabricks-Generative-AI-Engineer-Associateの認定試験の受験生にとっても適合するサイトで、受験生に試験に関する情報を提供するだけでなく、試験の問題と解答をはっきり解説いたします。
Databricks-Generative-AI-Engineer-Associateダウンロード: https://www.certshiken.com/Databricks-Generative-AI-Engineer-Associate-shiken.html
無料でクラウドストレージから最新のCertShiken Databricks-Generative-AI-Engineer-Associate PDFダンプをダウンロードする:https://drive.google.com/open?id=1y50-ZioKznYk_lZJWmbFHLRZboeMU_FX