P.S. Kostenlose 2026 Snowflake SPS-C01 Prüfungsfragen sind auf Google Drive freigegeben von ExamFragen verfügbar: https://drive.google.com/open?id=1nBsWhQtFPzo9GHbOL3wqEL-JhM4rq0s_
Gott ist gerecht, und jeder ist nicht perfekt. Wie wir alle wissen, ist der Wettbewerb in der IT-Branche sehr heftig.S o jeder will die IT-Zertifizierung erhalten, um einen Wert zu erhöhen. Ich denke auch so. Aber es ist zu schwierig für ich. Glücklicherweise habe ich die Dumps zur Snowflake SPS-C01 Zertifizierung von ExamFragen im Internet gesehen. Dann brauche ich mich keine Sorgen zu machen. Die Fragenkataloge zur Snowflake SPS-C01 Prüfung von ExamFragen sind wirklich gut. Sie sind umfassend und zielgerichtet. Wenn Sie auch ein Mitgleid der IT-Branche sind, fügen Sie schnell die Snowflake SPS-C01 Prüfung Fragenkataloge von ExamFragen in den Warenkorb hinzu. Zögern Sie nicht. Die Fragenkataloge zur Snowflake SPS-C01 Prüfung von ExamFragen sind Ihr bester Partner.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Snowpark Concepts and Architecture | 25% | - Snowpark architecture and execution model
|
| Topic 2: Snowpark API and Development | 30% | - Multi-language support
|
| Topic 3: Performance and Best Practices | 10% | - Optimization techniques
|
| Topic 4: Data Transformations and Operations | 35% | - Advanced operations
|
>> SPS-C01 Online Prüfungen <<
Wenn Sie noch zögern, ob unsere Prüfungsunterlagen der Snowflake SPS-C01 kaufen, können Sie unsere Demo der Softwaren zuerst probieren! Danach werden Sie überzeugen, dass unsere Produkte Ihnen helfen können, Snowflake SPS-C01 zu bestehen. Da unser professionelles Team der ExamFragen sich kontinuierlich kräftigen und die Unterlagen der Snowflake SPS-C01 immer aktualisieren. Auf diese Weise siegen Sie beim Anfang der Vorbereitung!
273. Frage
You have a Snowpark DataFrame with columns 'sale_date', 'product_id', and 'revenue'. You need to calculate the cumulative revenue for each product over time. Which of the following approaches will accomplish this in Snowpark using window functions?





Antwort: A,B
Begründung:
Options A and E both achieve the desired result of calculating cumulative revenue for each product. Option A utilizes 'rowsBetween' specifying that the window frame should include all rows from the beginning ('Window.unboundedPreceding') up to the current row ('Window.currentRow'). This calculates a running sum of revenue for each product over time. Option E uses 'rangeBetween' , which is equivalent to when the order-by expression is of a numeric or date type. Option B does not partition by product_id, so the cumulative revenue is calculated over the entire dataset. Option C does not include frame specification 'rowsBetween()' or 'rangeBetween(Y , therefore defaults to 'RANGE BETWEEN UNBOUNDED PRECEDING AND CURRENT ROW, which is valid for this question. While it's functionally correct, it's implicit, so 'A' is preferrable if one option is to be selected. Option D partitions incorrectly by sale_date.
274. Frage
You have a Python dictionary 'data' representing configuration settings for your Snowpark application. You need to convert this dictionary into a Snowpark DataFrame with a single row and two columns named 'Setting' and 'Value'. The 'Setting' column should contain the keys from the dictionary, and the 'Value' column should contain the corresponding values. The DataFrame needs to be created efficiently and ensure string representation of both the setting and value. Which approach is most suitable, ensuring correctness and conciseness?
Antwort: D
Begründung:
Option D is the most suitable approach. Here's why: Correctness: It correctly transforms the dictionary into a list of lists, where each inner list contains the key and its corresponding value. The 'str(vy ensures all values are converted to strings, meeting the requirement. Efficiency: It directly creates a Snowpark DataFrame without unnecessary intermediate conversions (e.g., to Pandas DataFrame). Clarity: It clearly defines the schema using a list of column names, making the code easy to understand. Option A is not correct, you need list of list for each row, the schema is not correct for dictionary structure Option B introduces Pandas dependency and incurs the overhead of converting to Pandas DataFrame and then to a Snowpark DataFrame. Option C creates a list of dictionaries, where each dictionary has the keys 'Setting' and Value'. This creates as many rows as items in the 'data' dictionary and not a single row, but each config, thus wrong. Option E is nearly correct, but the problem is 'str(v)' which ensure string type casting is missing
275. Frage
You have a Snowpark DataFrame 'df_orders' containing order data'. You want to delete all records from the underlying Snowflake table 'ORDERS TABLE' where the 'order_date' is older than '2023-01-01' using a Snowpark DataFrame operation. Which of the following code snippets is the MOST efficient and recommended way to achieve this, assuming 'spark' is your Snowpark Session object?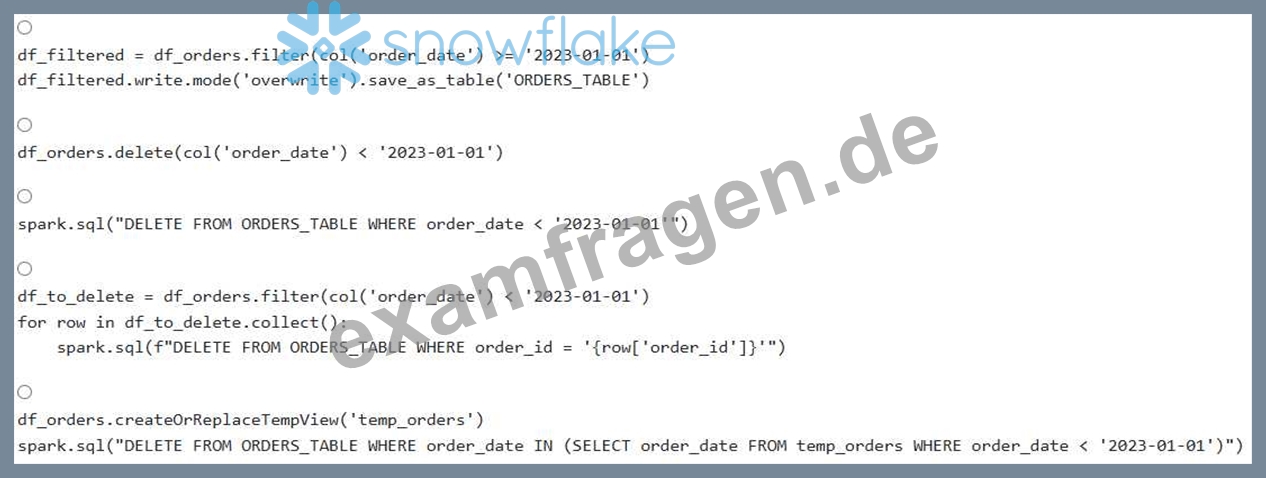
Antwort: C
Begründung:
Option B, < '2023-01-01 , is the most efficient and direct way to delete data from the underlying table using Snowpark's DataFrame API. Options A, C, D, and E are less efficient. A overwrites the entire table, C uses SQL directly (less Snowpark), D iterates row by row which is extremely slow and inefficient, and E uses a temp view and SQL, still not optimal. Option B leverages the power of Snowpark to perform the deletion operation directly.
276. Frage
Consider the following Python code snippet using Snowpark: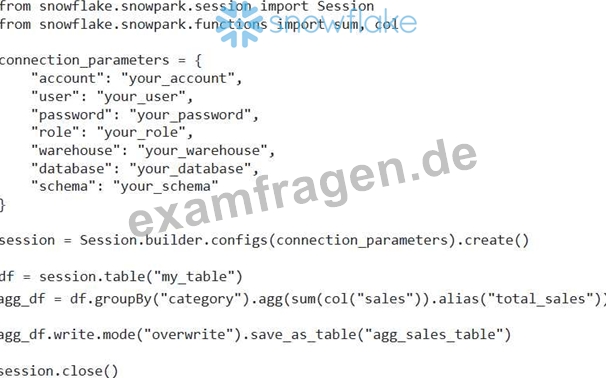
Which of the following statements are true regarding this Snowpark code?
Antwort: A,B,C,E
Begründung:
The code correctly connects to Snowflake, reads data from 'my_table', performs aggregation, and saves the result to 'agg_sales_table' with overwrite mode, and closes the session. While password authentication is discouraged, it is still supported. The other options accurately describe the code's functionality. Closing the session is a best practice to release resources.
277. Frage
You have a Snowpark DataFrame named with columns 'category', , and You want to perform the following transformations using Snowpark:





Antwort: B
Begründung:
Option E is correct, because the 'pivot' operation needs to be inside 'groupBy' . It first groups the data by 'category', then pivots the data based on the 'date' column, aggregating the 'value' column using the sum function. Options A,B,C, and D, will cause a Snowflake error.
278. Frage
......
Wollen Sie größere Errungenschaften in der IT-Branche erzielen, dann ist es richtig, ExamFragen zu wählen. Die Schulungsunterlagen zur Snowflake SPS-C01 Zertifizierungsprüfung aus ExamFragen werden von den erfahrenen Experten durch ständige Praxis und Forschung bearbeitet. Sie verfügen über hohe Genauigkeiten und große Reichweite. Haben Sie die Schulungsunterlagen zur Snowflake SPS-C01 Zertifizierungsprüfung aus ExamFragen, dann haben Sie den Schlüssel zum Erfolg.
SPS-C01 Buch: https://www.examfragen.de/SPS-C01-pruefung-fragen.html
BONUS!!! Laden Sie die vollständige Version der ExamFragen SPS-C01 Prüfungsfragen kostenlos herunter: https://drive.google.com/open?id=1nBsWhQtFPzo9GHbOL3wqEL-JhM4rq0s_