What's more, part of that ITPassLeader Databricks-Certified-Data-Engineer-Associate dumps now are free: https://drive.google.com/open?id=1voTGbF1hyIq-tCDkJEWfl1ZVDBdMAN9T
As is known to us, there are three different versions about our Databricks-Certified-Data-Engineer-Associate guide torrent, including the PDF version, the online version and the software version. The experts from our company designed the three different versions of Databricks-Certified-Data-Engineer-Associate test torrent with different functions. According to the different function of the three versions, you have the chance to choose the most suitable version of our Databricks-Certified-Data-Engineer-Associate study torrent. For instance, if you want to print the Databricks-Certified-Data-Engineer-Associate study materials, you can download the PDF version which supports printing. By the PDF version, you can print the Databricks-Certified-Data-Engineer-Associate guide torrent which is useful for you.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Data Pipeline Architecture | 15-20% | - Monitor and optimize pipeline performance - Understand ELT vs ETL patterns - Implement incremental data processing - Design data pipelines for batch and streaming |
| Topic 2: Delta Lake Fundamentals | 20-25% | - Create and manage Delta tables - Write to and read from Delta tables - Understand ACID transactions and time travel - Explain Delta Lake features and benefits |
| Topic 3: Lakehouse Platform Concepts | 10-15% | - Understand the Lakehouse architecture and its benefits - Describe key Databricks Lakehouse platform components - Explain data governance and security concepts |
| Topic 4: Apache Spark Data Processing Fundamentals | 20-25% | - Create and use Spark DataFrames - Use Spark SQL for data processing - Work with structured data types (arrays, maps, structs) - Apply transformations and actions on DataFrames |
| Topic 5: Python for Data Engineering | 10-15% | - Work with Spark APIs in Python - Implement user-defined functions (UDFs) - Use PySpark for data processing |
| Topic 6: Spark SQL and DataFrames | 15-20% | - Write and execute Spark SQL queries - Handle null values and data quality - Join and union DataFrames - Aggregate and group data |
>> Latest Databricks-Certified-Data-Engineer-Associate Test Materials <<
For the challenging Databricks Databricks-Certified-Data-Engineer-Associate exam, they make an effort to locate reputable and recent Databricks Databricks-Certified-Data-Engineer-Associate practice questions. The high anxiety and demanding workload the candidate must face being qualified for the Databricks Databricks-Certified-Data-Engineer-Associate Certification are more difficult than only passing the Databricks Databricks-Certified-Data-Engineer-Associate exam.
NEW QUESTION # 188
A data engineer has configured a Structured Streaming job to read from a table, manipulate the data, and then perform a streaming write into a new table.
The code block used by the data engineer is below: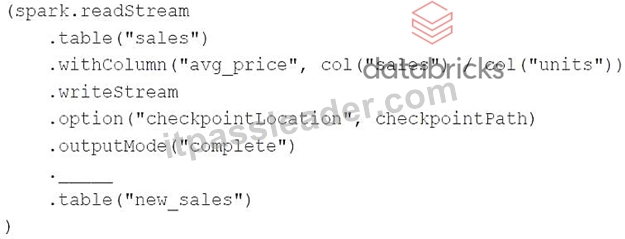
If the data engineer only wants the query to process all of the available data in as many batches as required, which of the following lines of code should the data engineer use to fill in the blank?
Answer: B
Explanation:
https://spark.apache.org/docs/latest/api/python/reference/pyspark.ss/api/pyspark.sql.streaming.DataStreamWriter
NEW QUESTION # 189
A data engineer wants to create a new table containing the names of customers that live in France.
They have written the following command: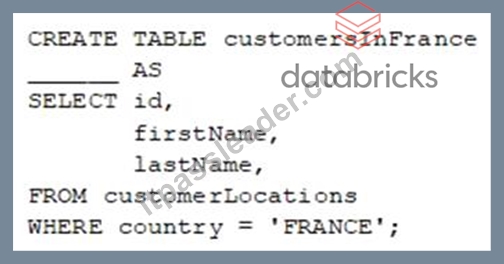
A senior data engineer mentions that it is organization policy to include a table property indicating that the new table includes personally identifiable information (PII).
Which of the following lines of code fills in the above blank to successfully complete the task?
Answer: A
Explanation:
In Databricks, when creating a table, you can add a comment to columns or the entire table to provide more information about the data it contains. In this case, since it's organization policy to indicate that the new table includes personally identifiable information (PII), option D is correct. The line of code would be added after defining the table structure and before closing with a semicolon. References: Data Engineer Associate Exam Guide, CREATE TABLE USING (Databricks SQL)
NEW QUESTION # 190
A data engineer has configured a Structured Streaming job to read from a table, manipulate the data, and then perform a streaming write into a new table.
The cade block used by the data engineer is below: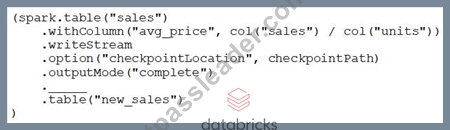
If the data engineer only wants the query to execute a micro-batch to process data every 5 seconds, which of the following lines of code should the data engineer use to fill in the blank?
Answer: C
Explanation:
The processingTime option specifies a time-based trigger interval for fixed interval micro-batches. This means that the query will execute a micro-batch to process data every 5 seconds, regardless of how much data is available. This option is suitable for near-real time processing workloads that require low latency and consistent processing frequency. The other options are either invalid syntax (A, C), default behavior (B), or experimental feature (E). Reference: Databricks Documentation - Configure Structured Streaming trigger intervals, Databricks Documentation - Trigger.
NEW QUESTION # 191
A data engineer has written a function in a Databricks Notebook to calculate the population of bacteria in a given medium.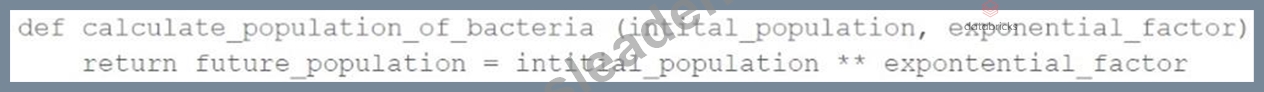
Analysts use this function in the notebook and sometimes provide input arguments of the wrong data type, which can cause errors during execution.
Which Databricks feature will help the data engineer quickly identify if an incorrect data type has been provided as input?
Answer: A
Explanation:
The Databricks debugger supports setting breakpoints that pause execution and allow inspection of variables. If the wrong data type is passed to the function, the debugger raises an error at runtime, helping the engineer quickly identify the issue.
NEW QUESTION # 192
A data engineer is onboarding a new bronze ingestion pipeline in Databricks with Unity Catalog.
The team wants Databricks to handle storage layout, apply platform optimizations over time, and simplify lifecycle management so that when a table is dropped, its underlying data is also cleaned up according to Databricks-managed retention policies.
Which table type should the data engineer create for these ingestion tables?
Answer: B
Explanation:
Managed tables allow Unity Catalog and Databricks to control both metadata and underlying data storage, enabling automatic optimizations, simplified lifecycle management, and cleanup of data files when tables are dropped according to platform-managed policies.
NEW QUESTION # 193
......
Nowadays certificates are more and more important for our job-hunters because they can prove that you are skillful to do the jobs in the certain areas and you boost excellent working abilities. Passing the test of Databricks-Certified-Data-Engineer-Associate certification can help you find a better job and get a higher salary. With this target, we will provide the best Databricks-Certified-Data-Engineer-Associate Exam Torrent to the client and help the client pass the exam easily if you buy our product.
Databricks-Certified-Data-Engineer-Associate Latest Exam Test: https://www.itpassleader.com/Databricks/Databricks-Certified-Data-Engineer-Associate-dumps-pass-exam.html
2026 Latest ITPassLeader Databricks-Certified-Data-Engineer-Associate PDF Dumps and Databricks-Certified-Data-Engineer-Associate Exam Engine Free Share: https://drive.google.com/open?id=1voTGbF1hyIq-tCDkJEWfl1ZVDBdMAN9T