2026年Fast2testの最新DA0-001 PDFダンプおよびDA0-001試験エンジンの無料共有:https://drive.google.com/open?id=12-ZUvNwjCUVOCLwbKG_31gTctj221ExU
初めて練習を選ぶことは、ギャンブルをすることに少し似ていると思うかもしれません。 ただし、DA0-001学習クイズでは、参考になる無料のデモと、バックアップとしてのプロのエリートが用意されています。 彼らは、DA0-001トレーニング資料で発生したエラーについて妥協しない検閲エリートの集まりです。 そのため、彼らの正解率は信じられないほど高く、試験の受験者の98%以上が合格しました。 あなたのように成功することに熱心な熱心な受験者に試験の知識を伝えることで、彼らはそれを助けを提供する責任として扱います。 そのため、情報の特性に従って次のDA0-001学習ガイドを入手できる場合は、目覚ましい進歩を遂げてください。
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Visualization | 23% | - Visualization best practices - Chart and dashboard creation - Tool-based visualization techniques |
| Topic 2: Data Mining | 25% | - Data acquisition and cleaning techniques - Pattern identification and extraction - Data transformation and profiling |
| Topic 3: Data Concepts and Environments | 15% | - Data sources and acquisition methods - Data concepts and terminology - Data structures and file formats |
| Topic 4: Data Governance, Quality, and Controls | 14% | - Data governance frameworks - Security, privacy, and compliance considerations - Data quality management |
| Topic 5: Data Analysis | 23% | - Trend and correlation analysis - Statistical methods and calculations - Data interpretation and reporting |
Fast2testはCompTIAのDA0-001認定試験にたいして短期で有効なウェブサイトでDA0-001認定試験に合格するのを保証したり、CompTIA認証試験に合格しなければ全額で返金いたします。あなたはFast2testが提供したDA0-001の認証試験の問題集を購入するの前にインターネットで無料な試用版をダウンロードしてください。
質問 # 258
An analyst for a small business with multiple locations is using each location's quarterly sales reports from last year to create a single revenue report for the year. Which of the following data mining techniques should the analyst use to complete this task?
正解:D
解説:
Comprehensive and Detailed In-Depth
To compile a comprehensive annual revenue report from multiple quarterly sales reports, the analyst should integrate the datasets appropriately:
Data Merge: This technique involves combining datasets based on common fields or keys. In this scenario, merging would align data from different quarters based on shared attributes, such as location identifiers, to create a unified dataset.
Data Append: Appending adds datasets sequentially, stacking them on top of each other. While this could combine the reports, it doesn't ensure integration based on common fields, which is necessary for accurate analysis.
Data Blending: Blending combines data from different sources or formats. If the quarterly reports are in varied formats or from different systems, blending would be appropriate. However, if they share the same structure, blending isn't necessary.
Data Imputation: Imputation addresses missing or incomplete data by filling in gaps. This technique isn't relevant to combining complete quarterly reports.
Therefore, merging the data ensures that all quarterly reports are integrated based on common fields, providing a cohesive annual revenue report.
質問 # 259
An analyst for a concert venue is analyzing the number of tickets sold for a recent event. Which of the following types of data is the number of sold tickets an example of?
正解:B
解説:
The number of tickets sold represents discrete data, as it consists of countable, distinct values (e.g., 1, 2, 3, etc.). Discrete data cannot take on fractional values within the count and is contrasted with continuous data, which can take on any value within a range.
CompTIA Data+ Reference:
CompTIA Data+ Study Guide (Exam DA0-001), Chapter 2: Data Types and Structures, Section "Types of Quantitative Data: Discrete vs. Continuous", Official CompTIA CertMaster Learn for Data+, Module 2.2
"Understanding Discrete Data".
質問 # 260
Given the following customer and order tables:
Which of the following describes the number of rows and columns of data that would be present after performing an INNER JOIN of the tables?
正解:A
解説:
This is because an INNER JOIN is a type of join that combines two tables based on a matching condition and returns only the rows that satisfy the condition. An INNER JOIN can be used to merge data from different tables that have a common column or a key, such as customer ID or order ID. To perform an INNER JOIN of the customer and order tables, we can use the following SQL statement:
This statement will select all the columns (*) from both tables and join them on the customer ID column, which is the common column between them. The result of this statement will be a new table that has seven rows and eight columns, as shown below: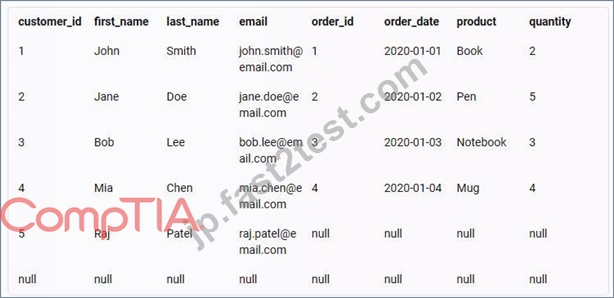
The reason why there are seven rows and eight columns in the result table is because:
* There are seven rows because there are six customers and six orders in the original tables, but only five customers have matching orders based on the customer ID column. Therefore, only five rows will have data from both tables, while one row will have data only from the customer table (customer 5), and one row will have no data at all (null values).
* There are eight columns because there are four columns in each of the original tables, and all of them are selected and joined in the result table. Therefore, the result table will have four columns from the customer table (customer ID, first name, last name, and email) and four columns from the order table (order ID, order date, product, and quantity).
質問 # 261
A customer list from a financial services company is shown below: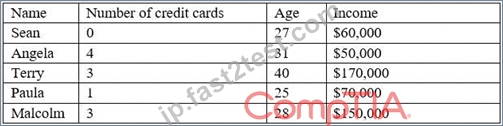
A data analyst wants to create a likely-to-buy score on a scale from 0 to 100, based on an average of the three numerical variables: number of credit cards, age, and income. Which of the following should the analyst do to the variables to ensure they all have the same weight in the score calculation?
正解:A
解説:
Explanation
Normalizing the variables means scaling them to a common range, such as 0 to 1 or -1 to 1, so that they have the same weight in the score calculation. Recoding the variables means changing their values or categories, which would alter their meaning and distribution. Calculating the percentiles of the variables means ranking them relative to each other, which would not account for their actual magnitudes. Calculating the standard deviations of the variables means measuring their variability, which would not make them comparable.
References: CompTIA Data+ Certification Exam Objectives, page 10
質問 # 262
Which of the following data elements would not normally be stored in binary format?
正解:A
質問 # 263
......
さまざまな年齢層の研究条件に基づくさまざまな種類のアンケートによると、当社のDA0-001テスト準備はこれらの研究グループ向けに完全に設計されており、DA0-001試験の準備時の能力と効率を向上させ、目標とするDA0-001証明書が正常に作成されました。 DA0-001の質問トレントには多くの利点がありますので、ご紹介します。CompTIAのDA0-001試験に合格することができます。
DA0-001最速合格: https://jp.fast2test.com/DA0-001-premium-file.html
P.S. Fast2testがGoogle Driveで共有している無料かつ新しいDA0-001ダンプ:https://drive.google.com/open?id=12-ZUvNwjCUVOCLwbKG_31gTctj221ExU