VMwareの3V0-12.26試験に合格することは容易なことではなくて、良い訓練ツールは成功の保証でJpshikenは君の試験の問題を準備してしまいました。君の初めての合格を目標にします。
| Section | Objectives |
|---|---|
| Troubleshoot and Optimize VMware Cloud Foundation Architecture | |
| VMware Cloud Foundation Products and Solutions | |
| IT Architectures, Technologies, Standards | |
| Plan and Design VMware Cloud Foundation Solutions | - Architect for availability, performance, security, and recoverability - Design conceptual, logical, and physical solutions - Translate business requirements into technical architecture |
| Install, Configure, and Administer VCF Design Elements |
国際的に認められている3V0-12.26認定は、特定の分野の知識を十分に活用できることを意味するのは当然です。ワークロードに圧倒され、息を吸うことができない場合、3V0-12.26準備トレントを選択してみませんか?私たちは、最も信頼性が高く正確な試験資料をお客様に提供することに特化しており、お客様が満足のいくスコアを達成することで試験に合格できるよう支援しています。 3V0-12.26練習教材を使用すると、試験は簡単になります。
質問 # 22
An architect is responsible for designing a VMware Cloud Foundation (VCF) Private Cloud solution. During a requirements gathering workshop, the customer supplied the following information:
* The solution must support the monitoring of all existing workloads.
* There are currently 15,000 virtual machine workloads running within the existing environment.
* All infrastructure components will also be monitored by the solution.
The solution must ensure that the 99.9% uptime Service Level Agreement can be met.
The solution must be resilient to a single fault domain failure.
The following logical design decisions have been made within the design:
* Deploy the VCF Operations cluster following the High Availability Model.
The following table is from the VCF Operations sizing guide:
Small
Medium
Single-Node Object Maximum
10,000
30,000
Single-Node Max Collected Metrics
1,600,000
5,000,000
Maximum Nodes in a cluster
2
8
Multi-Node Object Maximum
6,000
17,000
Multi-Node Max Collected Metrics
1,400,000
4,000,000
Maximum Objects in a Cluster
12,000
136,000
Maximum Metrics in a Cluster
2,800,000
32,000,000
Maximum Nodes for Continuous Availability per Fault Domain
1
4
Given the information above, which three physical design decisions meet the stated requirements? (Choose three.)
正解:B、C、E
解説:
A, D, and E meet the availability, sizing, and fault-domain requirements.
A is required because Continuous Availability (CA), rather than standard HA, provides fault-domain resilience. Broadcom states that VCF Operations CA stretches cluster nodes across two fault domains and can tolerate the loss of an entire fault domain without cluster downtime. Standard VCF Operations HA protects only against one node failure , so C does not satisfy the stated requirement for a single fault domain failure. CA requires equal node distribution across the two fault domains and a witness in a third location.
E is correct because 15,000 VMs plus all monitored infrastructure objects exceed the practical capacity of the Small configuration. Two Small nodes support only 12,000 maximum cluster objects before CA replication considerations . Four Medium nodes provide sufficient capacity and can be distributed as two analytics nodes per fault domain. Broadcom also notes that CA replication effectively reduces available object capacity compared with a non-CA deployment.
D ensures Operations analytics nodes are separated across physical hosts rather than sharing a common failure point. Broadcom specifically recommends DRS anti-affinity to keep Operations nodes on separate hosts.
Study Guide References/Topics: VCF Operations Sizing; Continuous Availability; Fault Domains; Analytics Node Placement; DRS Anti-Affinity; High Availability versus Continuous Availability.
質問 # 23
Match the definitions to the terms for MoSCoW ratings by dragging and dropping the Term on the left to the Definition on the right.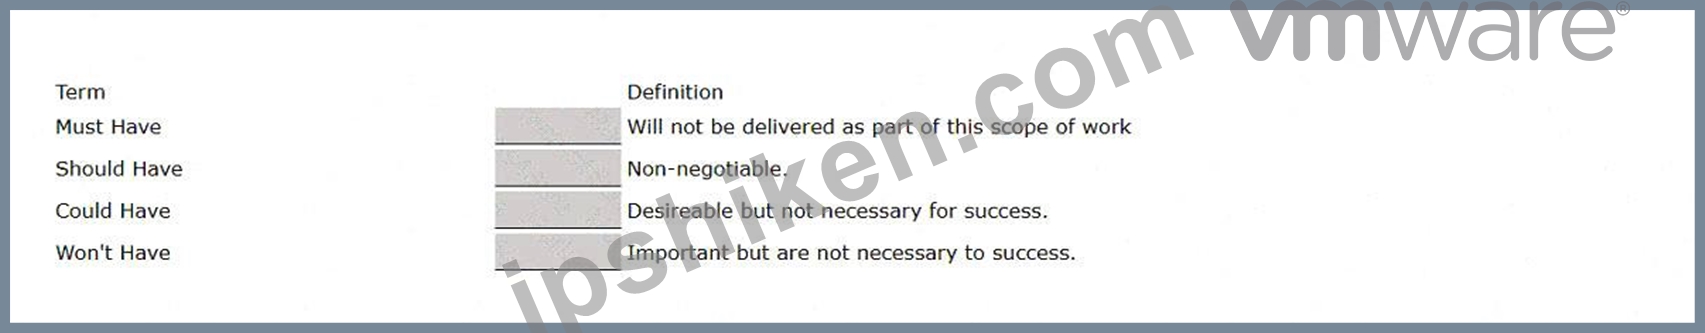
正解:
解説: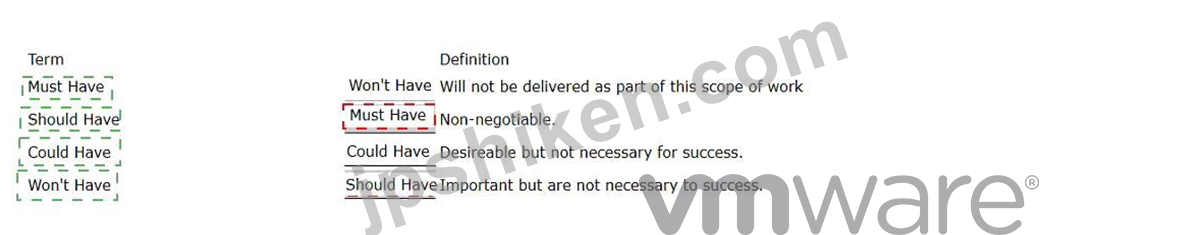
Explanation:
Term
Correct Definition
Must Have
Non-negotiable.
Should Have
Important but are not necessary to success.
Could Have
Desirable but not necessary for success.
Won ' t Have
Will not be delivered as part of this scope of work.
The MoSCoW prioritization method classifies requirements according to how critical they are to the success and scope of a solution.
A Must Have requirement is non-negotiable . Failure to satisfy it means the solution does not meet an essential business or technical requirement.
A Should Have requirement is important and normally expected, but the project can still succeed without it if necessary. Such requirements may be deferred when schedule, cost, or resource constraints demand prioritization.
A Could Have requirement is desirable but has lower business impact. These capabilities are implemented when time and resources permit and can be removed from the current delivery with comparatively little effect on overall success.
A Won ' t Have requirement is explicitly excluded from the current scope. It is not necessarily permanently rejected; it may be reconsidered in a later phase or release.
For VCF architecture work, MoSCoW helps convert workshop findings into prioritized requirements and prevents optional functionality from competing with mandatory architectural objectives.
Study Guide References/Topics: Requirements Gathering; MoSCoW Prioritization; Conceptual Design; Business and Technical Requirements; Scope Management.
質問 # 24
As part the VMware Cloud Foundation (VCF) logical design, the architect has determined that the VCF Private Cloud will encompass multiple VCF instances contained within a single VCF Fleet. The architect documented the following requirements when using VCF Operations:
* Monitoring downtime must be minimized.
* Alerting downtime must be minimized.
Which design decision supports these requirements?
正解:A
解説:
The High Availability VCF Operations model with Collector nodes at remote sites provides the strongest match for minimizing both monitoring and alerting downtime.
VCF Operations High Availability (HA) replicates monitored-object data across analytics nodes and is specifically designed to tolerate the failure of one VCF Operations cluster node . Broadcom states that HA supports one-node failure and recommends placing nodes on different ESX hosts to eliminate an infrastructure-level single point of failure. This maintains the analytics and alert-processing platform when an Operations node becomes unavailable.
Remote Collectors/Cloud Proxies place the collection function closer to the VCF instances being monitored.
Broadcom ' s VCF Operations sizing guidance specifies communication between VCF Operations and VCF instance components through the Operations collector and defines latency requirements for this architecture.
Current VCF releases similarly use Cloud Proxies or collector groups for remote collection.
A provides aggregation across separate Operations instances but does not itself deliver HA to each monitoring instance. C leaves the central Operations analytics service without HA. D centralizes monitoring across the Fleet but, without an HA model, retains a central service-failure risk.
Study Guide References/Topics: VCF Operations Deployment Models; High Availability; Collector/Cloud Proxy Architecture; Multi-VCF Instance Fleet Monitoring; Alerting Resiliency; Remote Data Collection.
質問 # 25
An architect is designing a VMware Cloud Foundation (VCF) solution for a customer who needs to provide a standardized architecture across multiple geographically dispersed locations.
During workshops with the customer, the architect gathered the following information:
* There are ten locations in scope for the initial design, with plans for an additional five to be added within the next two years.
* One location is a dedicated datacenter (DC1) owned by the customer.
* The network links between the datacenter and all branch locations have a maximum latency of 100ms and a minimum bandwidth of 10 Mbps.
* Each of the remaining locations for the design are customer branch locations.
* Each branch location operates independently, and all compute resources should be dedicated to the branch.
* There is existing NFS storage available at each of the locations.
Based on this information, the architect decides that VCF Edge design patterns would be the best approach for meeting the customer ' s requirements.
Which two design decisions should the architect include? (Choose two.)
正解:B、C
解説:
A and C match the VCF Edge pattern of centralized management with dedicated remote workload domains .
A is correct because the VCF management infrastructure can reside centrally at DC1 , providing lifecycle management and centralized operations for remote edge locations. Broadcom ' s documented VCF Edge architecture describes a central data center containing the management workload domain, with remote edge workload domains managed centrally through the VCF management plane. This avoids deploying a complete VCF instance at every branch and substantially reduces footprint and operational complexity. The stated minimum 10 Mbps bandwidth and maximum 100 ms latency also correspond directly to the documented connectivity requirements for centrally managed remote VCF edge sites. ( VMware Blogs ) C is correct because each branch must operate independently and have compute resources dedicated to that location. A dedicated workload domain for each branch creates an appropriate infrastructure and lifecycle boundary while retaining centralized VCF management. Broadcom explicitly identifies the pattern of deploying a dedicated workload domain for each edge site. ( VMware Blogs ) B and E would cause workload domains to span geographically separate branches, conflicting with the requirement for branch-specific dedicated resources and introducing WAN dependencies. D unnecessarily deploys a full VCF instance at every location, increasing resource consumption and management overhead.
Study Guide References/Topics: VCF Edge Design Patterns; Remote Workload Domains; Centralized Management; Edge Site Connectivity Requirements; Workload Domain Isolation; Remote Cluster Architecture; NFS Storage for Edge Sites.
質問 # 26
An architect has been engaged to design a new VMware Cloud Foundation (VCF) deployment for a customer that will provide platform-level high availability across three data centers to support their applications.
The customer has advised that there is high-bandwidth connectivity of 10 Gbps+ between the data centers, with less than 5 ms Round Trip Time (RTT) between each site, supporting a combination of Layer-2 and Layer-3 capabilities.
The customer has provided the following additional requirements:
* A mix of Tier-1 (mission critical), Tier-2 (business critical), and Tier-3 (business operational) applications.
* Tier-1 and Tier-2 applications require a Recovery Point Objective (RPO) of zero .
* Compliance with all data sovereignty regulations.
* Operational complexity must be reduced where possible.
* Maximum Recovery Time Objective (RTO) of 24 hours in the event of a regional failure.
Given this information, which design should be recommended for the customer?
正解:A
解説:
C is the best match because this blueprint combines metro-style availability inside the primary region with disaster recovery into an additional region .
Within the primary region, two sites can use stretched vSphere/vSAN clusters . Current VCF design guidance specifies that stretched designs require high-bandwidth connectivity and less than 5 ms RTT between the data availability zones. This enables synchronous storage replication, which is the architectural mechanism required to achieve RPO 0 for Tier-1 and Tier-2 workloads. Broadcom also documents that stretched-cluster designs can provide zero RPO because data is synchronously maintained across sites.
The additional data center can then operate as a separate regional VCF instance within the same Fleet. This provides geographic separation for regional disaster recovery and supports the stated 24-hour RTO , while avoiding the operational complexity of stretching every site across every region.
A pure single-region multi-site design does not adequately address complete regional failure. Conversely, a generic multi-region design does not inherently provide the synchronous stretched-cluster architecture required for the Tier-1/Tier-2 zero-RPO requirement.
The VCF blueprint specifically described as "Multiple Sites in a Single Region plus Additional Region(s)" combines a stretched primary region with one or more standard remote regions. ( VMware TechDocs ) Study Guide References/Topics: VCF Design Blueprints; Multi-Site Single-Region Architecture; Additional Region Design; vSAN Stretched Clusters; RPO/RTO Design; Regional Disaster Recovery; Data Sovereignty; Fleet-Level Operations.
質問 # 27
......
Jpshikenは最高のハイパスレート3V0-12.26トレーニング資料を提供しており、数千人の受験者が試験をクリアして夢のような認定を得るのに役立ちます。認定が傑出しているか重要であるほど、競争は激しくなります。 3V0-12.26の実践教材は、あなたが簡単に目立つようにするあなたの勝利の魔法です。 3V0-12.26学習ガイドには、効率的な準備に役立つ実際のテストに関する最も重要な知識が含まれています。 100%の合格率を追求する場合、3V0-12.26試験の質問と回答は、わずか20〜30時間の学習で確実にクリアするのに役立ちます。
3V0-12.26復習過去問: https://www.jpshiken.com/3V0-12.26_shiken.html