私たちが知っているように、一部の人々は以前に試験に失敗し、DP-750トレーニング資料を購入する前にこの苦しい試験に自信を失いました。私たちはここで悲しみを分けます。これから時間のかかる思考を捨てることができます。対照的に、それらは不明瞭なコンテンツを感じることなくあなたの可能性を刺激します。 DP-750試験準備を取得した後、試験期間中に大きなストレスにさらされることはありません。
| Section | Weight | Objectives |
|---|---|---|
| Deploy and maintain data pipelines and workloads | 30–35% | - Monitor, troubleshoot, and maintain workloads
|
| Set up and configure an Azure Databricks environment | 15–20% | - Integrate with Azure services
|
| Prepare and process data | 30–35% | - Ingest and transform data
|
| Secure and govern Unity Catalog objects | 15–20% | - Implement data governance and security
|
弊社の資料はすばらしくて、MicrosoftのDP-750問題集などを含めています。これらの問題集は詳しい答えと解説があります。それに、我々は一番行き届いたアフターサービスを提供して、あなたの利益を保証します。お客様はDP-750問題集を購入するなら、一年の更新サービスと半年の返金サービスが得られています。この期間、我々はDP-750問題集に関するサービスを提供します。
質問 # 18
Which tool is best for continuous ingestion of files landing in Azure Data Lake?
正解:A
解説:
Auto Loader is optimized for incremental and continuous ingestion from cloud storage. It detects new files automatically and scales efficiently. Databricks Jobs schedule tasks but do not handle file detection. Logic Apps are workflow tools. ADF is batch-oriented.
質問 # 19
You have an Azure Databricks workspace.
You are creating a Lakeflow Spark Declarative Pipelines (SDP) pipeline that scales automatically.
You need to configure compute for the pipeline. The solution must minimize operational costs and effort.
What should you use?
正解:D
解説:
The best option for a Lakeflow Spark Declarative Pipelines (SDP) pipeline that scales automatically while keeping costs and administrative effort low is a job cluster that uses autoscaling.
Lowest Costs: Job clusters (also called automated compute) are billed at a significantly lower Data Processing Unit (DBU) rate compared to all-purpose clusters. By enabling autoscaling, Databricks dynamically allocates or removes worker nodes based on real-time pipeline demand, ensuring you never pay for unutilized resources.
Low Administrative Effort: While Databricks generally recommends Serverless compute as the absolute ideal for zero-admin pipelines, when selecting from classic compute options, a job cluster automatically handles its own lifecycle. It deploys when the pipeline starts executing and terminates automatically when processing is finished.
Incorrect:
[Not A]
Databricks SQL warehouses are designed to run standalone materialized views and streaming tables via standard SQL. They are not the native compute vehicle for running a fully automated, dedicated Lakeflow Spark Declarative Pipelines (SDP) deployment framework.
[Not B]
All-purpose compute is meant for interactive development, debugging, and ad-hoc analysis. It is billed at a much higher DBU rate, which violates the requirement to keep costs low.
[Not D]
Aside from the higher billing rate of all-purpose compute, a single-node configuration does not scale horizontally. This directly conflicts with your requirement to build a pipeline that scales automatically.
Reference:
https://docs.databricks.com/gcp/en/ldp/auto-scaling
質問 # 20
You need to curate Unity Catalog objects that reference the ERP data. The solution must meet the governance requirements.
What should you do?
正解:A
解説:
A foreign catalog mirrors the external ERP database and provides read-only access through Lakehouse Federation. Consequently, it cannot host managed volumes or locally created Delta tables, and its foreign tables cannot be altered to add analytics columns. The appropriate design is to create governed views in the managed analytics catalog and have those views reference the foreign tables through fully qualified catalog.
schema.table names. This preserves the ERP data in its source system, avoids duplication, and exposes standardized curated objects through Unity Catalog. Permissions can then be granted on the managed views while access to underlying foreign objects remains controlled. Unity Catalog uses a three-level namespace, and foreign catalogs are specifically intended to make external database data queryable without copying it into Databricks-managed storage. Microsoft Learn
質問 # 21
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a catalog named CatalogV Catalog1 contains a schema named Schema! and a table named Table1.
You need to ensure that access to the data in Table1 is controlled by using attribute based access control (ABAC).
What should you apply to Table1, and how should you control access for users? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.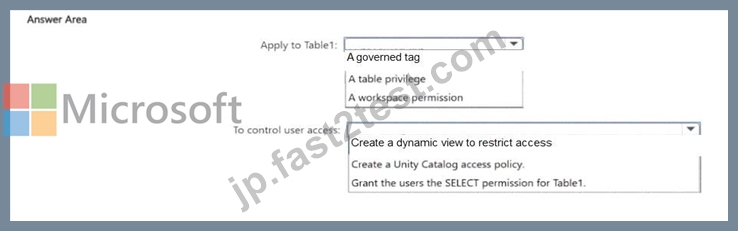
正解:
解説: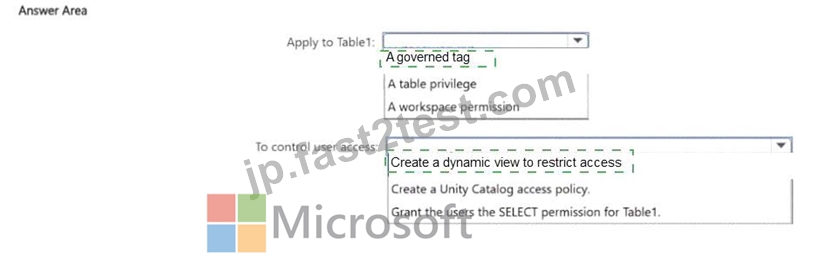
Explanation:
Attribute-based access control (ABAC) in Unity Catalog is implemented through row filters. A row filter is a SQL function registered on a table that evaluates the identity or group membership of the querying user and returns only the rows they're entitled to see.
The key functions are CURRENT_USER() (returns the logged-in user's email) and IS_ACCOUNT_GROUP_MEMBER() (returns true if the user belongs to a specified group). By building filter logic around these, you create access rules that are data-driven - a user in the 'EMEA' group sees EMEA rows, a user in 'APAC' sees APAC rows - without maintaining separate table-level grants per data segment.
This is what distinguishes ABAC from role-based access control: decisions are based on the user's attributes evaluated at query time, not on static grant lists. The filter is transparent to end users - they query the table normally and only receive rows the policy allows.
Reference: https://learn.microsoft.com/en-us/azure/databricks/data-governance/unity-catalog/row-and-column- filters
質問 # 22
You have an Azure Databricks workspace
You are creating a Lakeflow Spark Declarative Pipelines (SDP) pipeline that scales automatically. You need to configure compute for the pipeline. The solution must minimize operational costs and effort. What should you use?
正解:D
解説:
The correct answer is C - a job cluster that uses autoscaling.
Job clusters (also called pipeline clusters in the SDP context) are created exclusively for a pipeline run and terminated when the pipeline stops. You pay only for what the pipeline uses, and there's no idle cost between runs. Autoscaling on a job cluster lets the pipeline expand during heavy processing and contract during lighter stages - the combination of on-demand lifecycle and elastic scaling gives the lowest operational cost.
Option A (all-purpose cluster) runs at a higher DBU rate and persists beyond the pipeline's lifecycle, meaning you're paying for it even when the pipeline isn't running. Option B (SQL warehouse) is optimised for interactive BI and ad-hoc queries, not for the batch/streaming workloads SDP pipelines run. Option D (single- node all-purpose) has no scaling, runs at the all-purpose DBU rate, and is capped at one node - unsuitable for any production pipeline.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta-live-tables/configure-pipeline
質問 # 23
......
多くの大学生、多くの労働者、さらに多くの主婦など、DP-750試験に合格するために最善を尽くす人が増えています。 DP-750試験に合格したいこれらの人々は、試験を自分自身を向上させ、大きな進歩を遂げる唯一の機会と考えています。そのため、彼らはDP-750試験の準備に全力を尽くすことを望んでいますが、多くの人が重要なDP-750試験の準備に十分な時間がないことは明らかです。 DP-750試験の質問は、最小限の時間と労力でDP-750試験に合格するのに役立ちます。
DP-750試験過去問: https://jp.fast2test.com/DP-750-premium-file.html