DOWNLOAD the newest PDFVCE DP-750 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1SLIXdVjvsXcunifXpPeXznYf_fR2bfmb
Nowadays everyone is interested in the field of Microsoft because it is growing rapidly day by day. The DP-750 credential is designed to validate the expertise of candidates. But most of the students are confused about the right preparation material for Microsoft DP-750 Exam Dumps and they couldn't find real Implementing Data Engineering Solutions Using Azure Databricks (DP-750) exam questions so that they can pass DP-750 certification exam in a short time with good grades.
| Section | Weight | Objectives |
|---|---|---|
| Secure and govern data using Unity Catalog | 15-20% | - Access control and policies
|
| Deploy and manage data pipelines and workloads | 30-35% | - Operational reliability
|
| Configure and manage Azure Databricks environments | 15-20% | - Security and authentication setup
|
| Prepare and process data | 30-35% | - Data transformation and modeling
|
Passing the Microsoft DP-750 certification exam is necessary for professional development, and employing real DP-750 Exam Dumps can assist applicants in reaching their professional goals. These actual DP-750 questions assist students in discovering areas in which they need improvement, boost confidence, and lower anxiety. Candidates will breeze through Implementing Data Engineering Solutions Using Azure Databricks (DP-750) certification examination with flying colors and advance to the next level of their jobs if they prepare with updated DP-750 exam questions.
NEW QUESTION # 55
You have an Azure Databricks workspace that uses serverless compute.
You need to ingest data by using Lakeflow Jobs. New records must be processed as soon as they become available.
Which type of job trigger should you use for the ingestion?
Answer: B
Explanation:
The correct answer is D - Continuous trigger.
A Continuous trigger keeps the job running as a perpetual loop. As soon as one micro-batch or iteration completes, the next begins. New records are picked up with the shortest possible latency - as close to real- time as a Lakeflow Jobs pipeline gets.
File Arrival (Option B) is event-driven but introduces per-file trigger overhead and is best suited for file-based ingestion rather than continuous streaming workloads. Scheduled (Option C) runs at fixed clock intervals - if new data arrives between runs, it waits until the next scheduled execution. Manual (Option A) requires a human to start each run.
The question specifies serverless compute, which pairs naturally with Continuous trigger because serverless handles cluster lifecycle automatically - the job stays active without managing a persistent cluster. 'New records must be processed as soon as they become available' is the exact use case the Continuous trigger is designed for.
Reference: https://learn.microsoft.com/en-us/azure/databricks/jobs/triggers
NEW QUESTION # 56
Hotspot Question
You have an Azure Databricks workspace that contains an all-purpose cluster named Cluster1.
You discover that out-of-memory (OOM) errors intermittently cause jobs running on Cluster1 to fail.
You need to identify the root cause of the failures by analyzing the runtime execution behavior.
What should you do? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.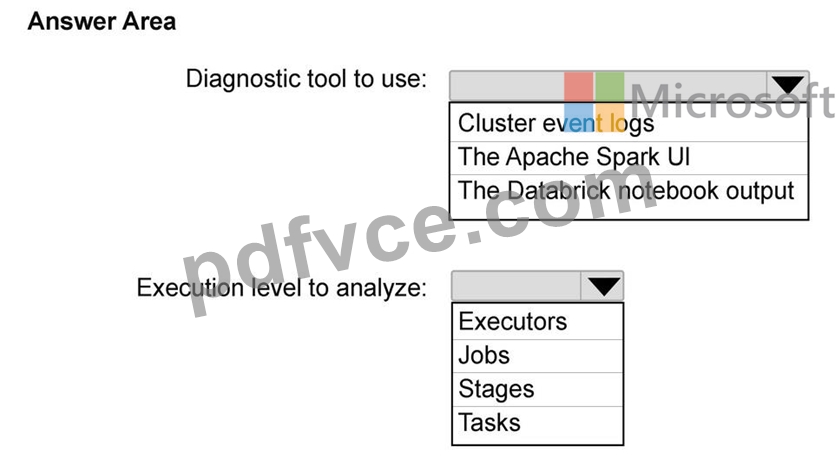
Answer:
Explanation: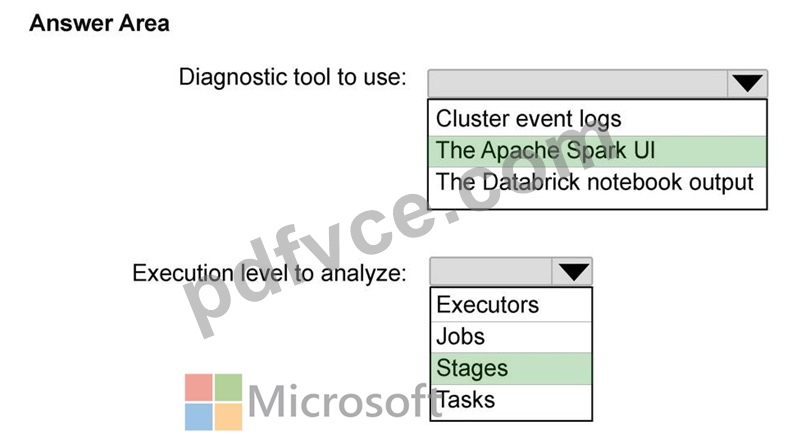
NEW QUESTION # 57
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains two managed Delta tables named sales.schema1.table1 and sales.schema1.table2.
sales.schema1.table1 contains sales data from the current year.
sales.schema1.table2 contains historical data.
You need to load all the rows from sales.schema1.table1 into sales.schema1.table2. The solution must preserve any existing data in sales.schema1.table2 and minimize processing effort.
Which command should you run?
Answer: D
Explanation:
The correct answer is A - INSERT INTO.
INSERT INTO appends all rows from the source to the target. Existing rows in table2 are untouched - the historical data stays intact - and the current year's rows from table1 are added. That is exactly what the requirement asks: 'preserve any existing data and minimise processing effort.' Option B (CREATE TABLE AS SELECT) would fail if table2 already exists, or if used with CREATE OR REPLACE it wipes table2 entirely before writing - historical data gone. Option C (INSERT OVERWRITE) replaces the entire table content with only the table1 rows, also destroying table2's existing data. Option D (CREATE OR REPLACE TABLE AS SELECT) explicitly drops and recreates the table, eliminating all historical records.
INSERT INTO is deliberately the simplest possible command here - one line, no special options, no risk of accidental data loss.
Reference: https://learn.microsoft.com/en-us/azure/databricks/sql/language-manual/delta-insert-into
NEW QUESTION # 58
You have an Azure Databricks workspace that contains a job in Lakeflow Jobs named Job1. Job1 contains multiple tasks.
Failures of non-critical tasks must be logged but must NOT trigger notifications. Notifications must be triggered only when critical tasks have failed, and Job1 has completed You need to configure the job alerting behavior.
What should trigger a notification?
Answer: C
Explanation:
The correct answer is B - a job failure.
The requirement draws a clear line: non-critical task failures should be logged silently; notifications should only fire when a critical failure causes the whole job to stop. Configuring the alert on 'Job Failure' achieves this precisely - the notification triggers when the job itself reaches a Failed terminal state, which only happens when at least one critical task has failed and the job cannot complete.
Option A (task failure) would send a notification for every task-level failure, including non-critical ones.
That's exactly the noise the question wants to avoid. Option C (job success) would never alert on failures at all. Option D (task success) confirms completion but doesn't catch failures.
Setting alerting at the job level rather than the task level is also simpler to configure - you don't need to mark individual tasks as critical or non-critical in the notification settings.
Reference: https://learn.microsoft.com/en-us/azure/databricks/jobs/alerts
NEW QUESTION # 59
Note: This section contains one or more sets of questions with the same scenario and problem. Each question presents a unique solution to the problem. You must determine whether the solution meets the stated goals. More than one solution in the set might solve the problem. It is also possible that none of the solutions in the set solve the problem.
After you answer a question in this section, you will NOT be able to return. As a result, these questions do not appear on the Review Screen.
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a Delta table named Orders.
You load the Orders table into an Apache Spark DataFrame named df.
You need to create a DataFrame that excludes rows where the order amount is null.
Solution: You run the following expression.
df.dropna(subset=["order_amount"])
Does this meet the goal?
Answer: B
Explanation:
Correct:
* You run the following expression.
df.dropna(subset=["order_amount"])
The expression df.dropna(subset=["order_amount"]) is an appropriate and effective way to exclude rows where order_amount is null.
* You run the following expression.
df.filter(df.order_amount.isNotNull())
To exclude rows where the order amount is null, you can use the isNotNull() method or a SQL expression within the filter() or where() functions.Here are the standard, appropriate expressions:
Option 1: Python/PySpark API (Recommended)
pythondf_clean = df.filter(df["order_amount"].isNotNull())
Incorrect:
* You run the following expression.
df.fillna(0, subset=['order_amount'])
* You run the following expression.
df.filter(df.order_amount != None)
Reference:
https://www.geeksforgeeks.org/python/filter-pyspark-dataframe-columns-with-none-or-null-values/
https://learn.microsoft.com/en-us/azure/databricks/pyspark/reference/classes/dataframe/dropna
NEW QUESTION # 60
......
Our DP-750 practice tests have established impressive recognition throughout the industry, diversified modes of learning enables the DP-750 exam candidates to capture at the real exam scenario. Tremendous quality of our DP-750 products makes the admirable among the professionals. Our practice tests are on demand, attending the needs of DP-750 Exams more comprehensively and dynamically as well. Lift up your learning tendency with PDFVCE practice tests training. Conceptual understanding matters the most for your success, technical excellence is certain with PDFVCE training as our experts keep it on high priority.
DP-750 Actual Dump: https://www.pdfvce.com/Microsoft/DP-750-exam-pdf-dumps.html
BTW, DOWNLOAD part of PDFVCE DP-750 dumps from Cloud Storage: https://drive.google.com/open?id=1SLIXdVjvsXcunifXpPeXznYf_fR2bfmb