Möchten Sie wissen , woher unsere Konfidenz für Microsoft AI-300 kommt? Lassen Sie mich erzählen. Zuerst, EchteFrage besitzt eine sehr erfahrene Gruppe, die Prüfungssoftware entwickelt. Zweitens, zahlose Kunden haben nach dem Benutzen unserer Produkte die Microsoft AI-300 Prüfung bestanden. Die Zertifizierung der Microsoft AI-300 wird weltweit anerkennt. Möchten Sie diese Zertifizierung besitzen? Mit Hilfe unserer Microsoft AI-300 Prüfungssoftware können Sie auch unbelastet erwerben!
| Section | Objectives |
|---|---|
| Design and implement generative AI solutions | - RAG (Retrieval Augmented Generation) solutions
|
| Plan and design AI solutions using Azure AI services | - Responsible AI design
|
| Operationalizing machine learning solutions | - Deployment and monitoring
|
| Implement secure and scalable AI systems | - Security and governance
|
Um die Microsoft AI-300 Zertifizierungsprüfung zu bestehen, brauchen Sie eine ausreichende Vorbereitung und eine vollständige Wissensstruktur. Die von EchteFrage gebotenen Microsoft AI-300 Ressourcen würden Ihre Bedürfnisse sicher abdecken.
77. Frage
-
A team is developing a Retrieval-Augmented Generation (RAG) system.
The team requires improvements to the system ' s retrieval quality to ensure accurate, grounded responses.
You need to assess RAG performance before you can suggest an improvement strategy.
Which four actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.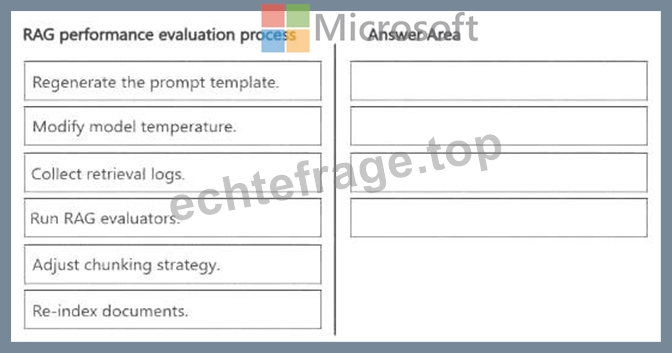
Antwort:
Begründung: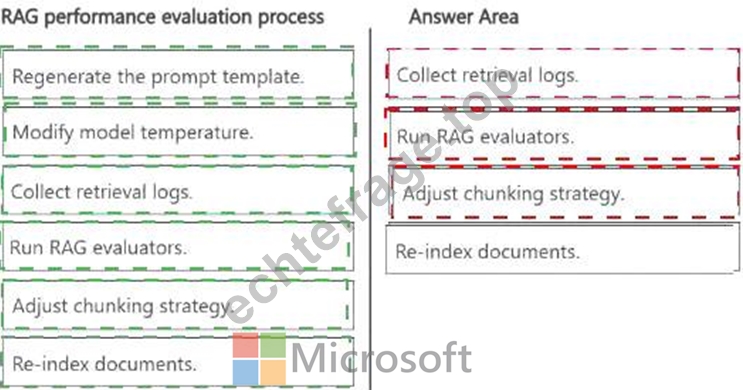
Explanation:
Correct sequence:
* Collect retrieval logs.
* Run RAG evaluators.
* Adjust chunking strategy.
* Re-index documents.
The process should begin by collecting retrieval logs . Retrieval diagnostics provide the evidence needed to understand which queries were issued, which document chunks were returned, and whether relevant content is being surfaced. Without retrieval telemetry, optimization becomes speculative rather than measurable.
Next, run RAG evaluators . Microsoft Foundry provides retrieval-oriented evaluators that assess how relevant retrieved context is to a query. The Retrieval evaluator measures contextual relevance without requiring ground truth, while the Document Retrieval evaluator can calculate metrics such as Fidelity and NDCG when labeled retrieval ground truth exists. These measurements help establish the retrieval-quality baseline before modifications are made.
After identifying retrieval deficiencies, adjust the chunking strategy . Microsoft specifically recommends reviewing chunk size and chunking methodology when retrieval returns irrelevant or incomplete passages.
Chunks that are too small can lose context, while oversized chunks can introduce irrelevant material and reduce retrieval precision.
Finally, re-index the documents so the revised chunking configuration is reflected in the searchable corpus.
Changing temperature or regenerating the prompt template primarily affects generation behavior rather than correcting the underlying retrieval pipeline.
Study Guide Reference: Implement generative AI quality assurance and observability - RAG evaluation, retrieval telemetry, retrieval-quality metrics, chunk optimization, indexing, and grounded-response assessment.
78. Frage
A team iterates prompts used by a generative AI agent. The team must support internal review before releasing changes.
The team must:
Track prompt changes with a clear history for audit and rollback.
Compare prompt variants in parallel without affecting the prompt used in the production environment.
You need to select the appropriate source control approach for each requirement.
What should you use for each requirement? To answer, move the appropriate source controls to the correct requirements. You may use each source control once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content. NOTE: Each correct selection is worth one point.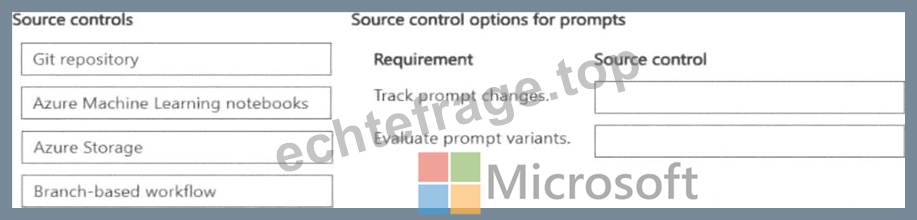
Antwort:
Begründung: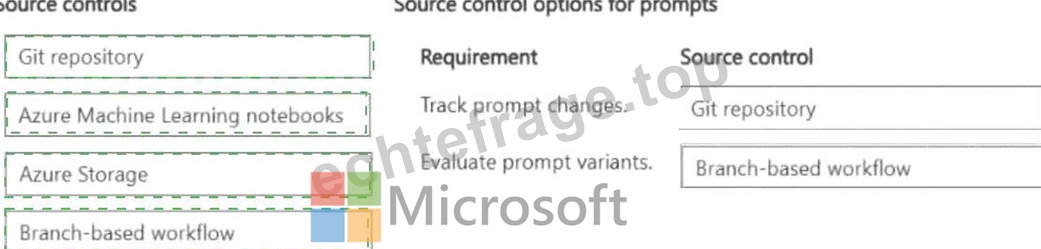
Explanation:
Git commits on the main branch provide the immutable, ordered history that auditors need: every change is timestamped, attributed to a specific developer, and reversible via git revert - this is the audit trail and rollback mechanism required by the first requirement. Git branches allow developers to create and test multiple prompt variants in complete isolation from the production prompt on the main branch, addressing the second requirement. A developer on an experiment branch can run full evaluations without touching the production prompt. When a variant is approved, it is merged via pull request. You cannot use branches alone for audit history because branches can be deleted, and you cannot use main-branch commits alone for parallel variant comparison without disrupting the history. Git ' s branch-and-merge model provides both capabilities simultaneously.
Microsoft Learn Reference Topic: Version control for AI prompts - Git branch strategies for prompt management in Microsoft Foundry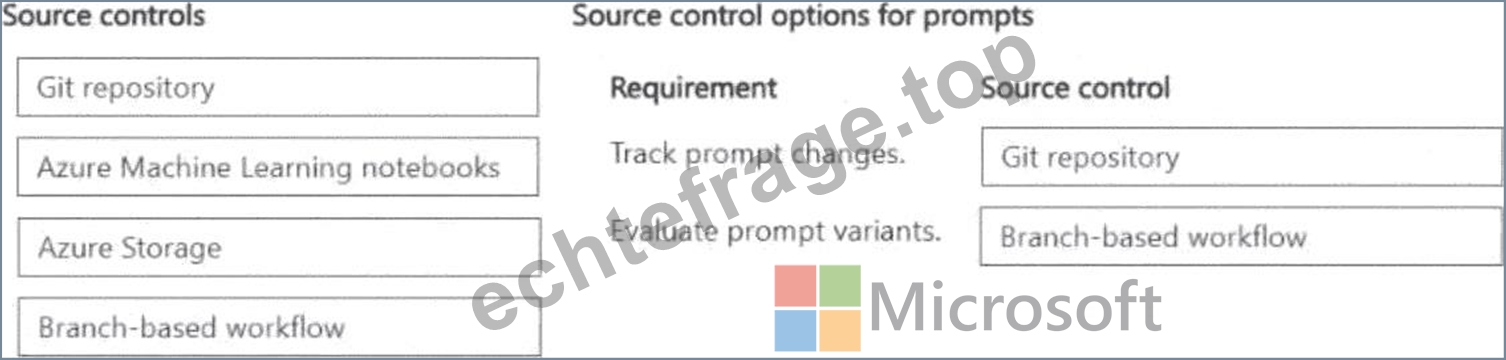
79. Frage
Drag and Drop Question
A data science team plans to evaluate multiple algorithms and hyperparameters for a classification problem without manually authoring separate training scripts.
The team must run an automated machine learning (AutoML) job that compares models and identifies the best-performing configuration.
You need to configure and run an AutoML training job.
Which four actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.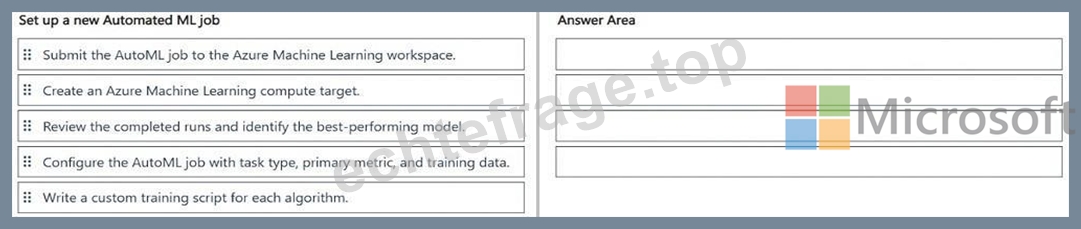
Antwort:
Begründung: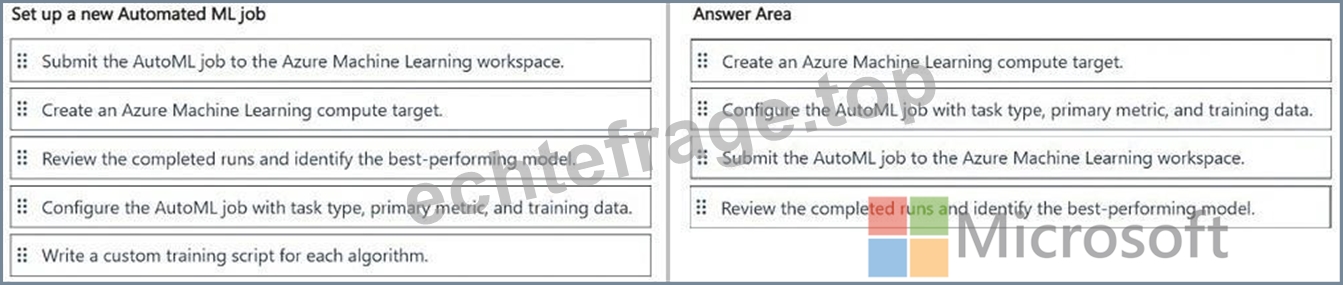
80. Frage
You run Azure Machine Learning training experiments. The training scripts directory contains 100 files that includes a file named .amlignore. The directory also contains subdirectories named ./outputs and ./logs.
There are 20 files in the training scripts directory that must be excluded from the snapshot to the compute targets. You create a file named .gitignore in the root of the directory. You add the names of the 20 files to the .gitignore file. These 20 files continue to be copied to the compute targets.
You need to exclude the 20 files.
What should you do?
Antwort: D
Begründung:
To exclude the 20 files from the training snapshot, you must add the file names to the .amlignore file located in the root of your training scripts directory.
Why the Files Are Still Copying
Azure Machine Learning training experiments use a specific order of precedence when creating a directory snapshot for compute targets:
.amlignore takes absolute priority: If an .amlignore file exists in the directory, Azure ML only respects the rules inside it. It completely ignores any .gitignore file present.
.gitignore is a fallback: Azure ML only respects .gitignore rules if an .amlignore file does not exist in the directory. Because you have both files, the .gitignore file is being completely bypassed.
Reference:
https://learn.microsoft.com/en-us/python/api/azureml-core/azureml.core.experiment.experiment
81. Frage
You manage a Retrieval-Augmented Generation (RAG) system that retrieves internal policy documents from a vector index.
Recent analysis shows that:
Retrieved results frequently include duplicated content from the same document.
Retrieved chunks sometimes span unrelated policy sections.
You review the following retrieval and ingestion configurations: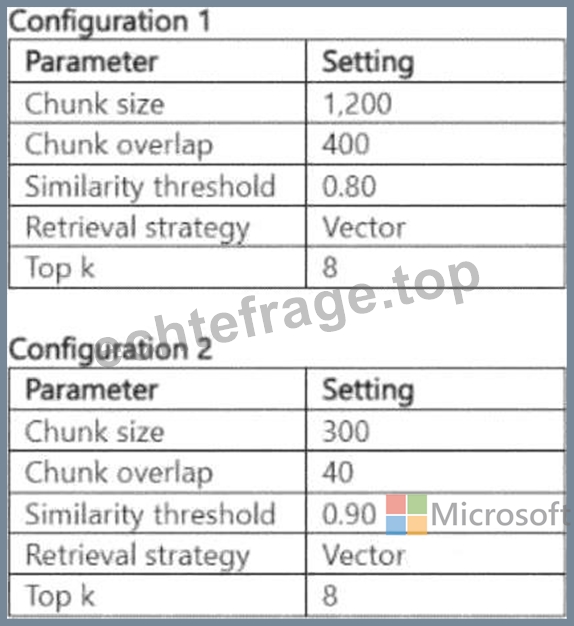
You need to reduce duplicated retrieval results and improve chunk relevance across policy sections.
For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection is worth one point.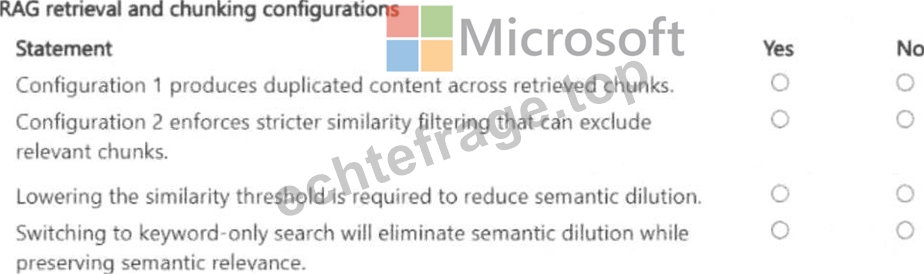
Antwort:
Begründung: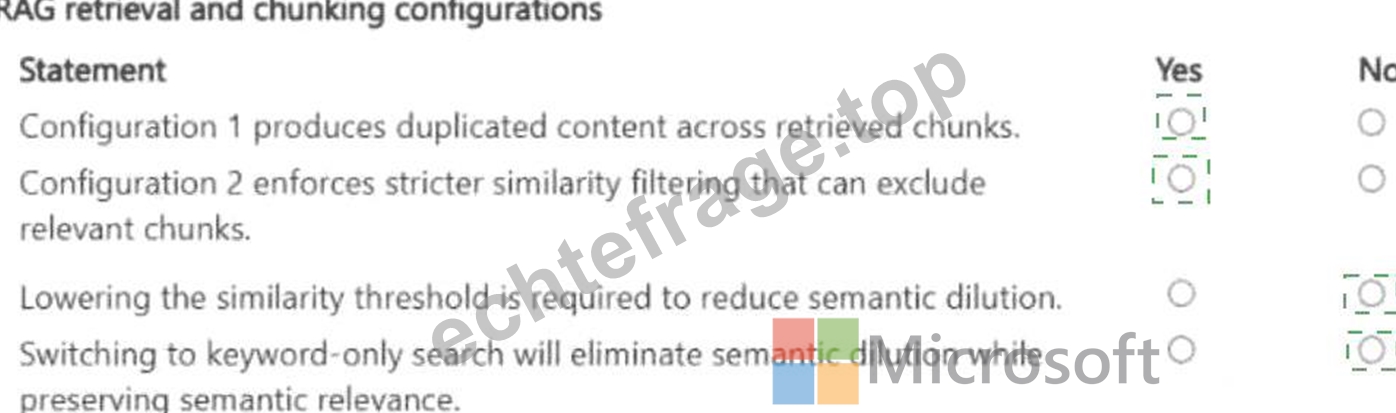
Explanation:
Two distinct RAG problems require two distinct solutions. When retrieved results frequently include duplicated content from the same document, the cause is overlapping chunks receiving similarly high similarity scores. The solution is Maximum Marginal Relevance reranking, which diversifies the result set by penalizing results that are semantically similar to already-selected results, reducing redundancy. When retrieved chunks sometimes span unrelated policy sections, the cause is fixed-size character chunking that splits content without regard for semantic boundaries. The solution is semantic chunking - splitting on natural sentence or section boundaries - ensuring each chunk is semantically coherent and does not straddle unrelated content. Both problems must be addressed together: reranking alone solves duplication but not relevance; semantic chunking alone solves relevance but not duplication.
Microsoft Learn Reference Topic: Optimize RAG retrieval in Azure AI Search - Chunking strategies and MMR reranking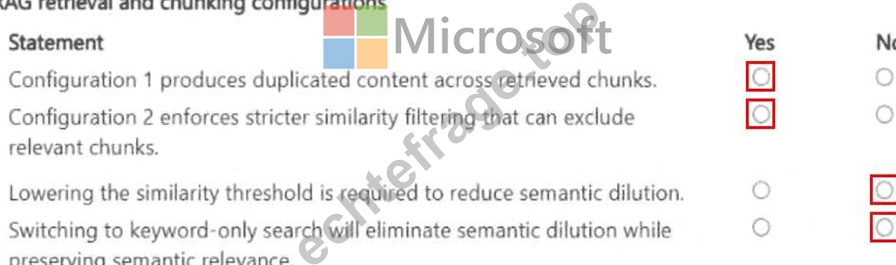
82. Frage
......
Mit den Schulungsunterlagen zur Microsoft AI-300 Zertifizierungsprüfung von EchteFrage würden Sie eine glänzende Zukunft haben und Erfolg erzielen. Sie werden Sie nicht nur zum Erfolg führen, sondern auch Ihre Fähigkeiten in der IT-Branche effizient entfalten. Sie umfassen zahlreiche Wissensgebiete und können Ihre Kenntnisse verbessern. Wenn Sie noch warten oder zögern, denn Sie wissen nicht, wie man die Microsoft AI-300 Zertifizierungsprüfung bestehen kann, keine Sorge. Die Schulungsunterlagen zur Microsoft AI-300 Zertifizierungsprüfung von EchteFrage wird alle Ihren Probleme lösen.
AI-300 Antworten: https://www.echtefrage.top/AI-300-deutsch-pruefungen.html