BONUS!!! MogiExam JN0-481ダンプの一部を無料でダウンロード:https://drive.google.com/open?id=1CK2vBjbzp-LxLzPCO9rgVZA1D7TVDUC1
チャンスは常に準備ができあがった者に属します。しかし、我々に属する成功の機会が来たとき、それをつかむことができましたか。JuniperのJN0-481認定試験を受験するために準備をしているあなたは、MogiExamという成功できるチャンスを掴みましたか。MogiExamのJN0-481問題集はあなたが楽に試験に合格する保障です。この問題集は大量な時間を節約させ、効率的に試験に準備させることができます。MogiExamの練習資料を利用すれば、あなたはこの資料の特別と素晴らしさをはっきり感じることができます。この問題集は間違いなくあなたの成功への近道で、あなたが十分にJN0-481試験を準備させます。
| トピック | 出題範囲 |
|---|---|
| トピック 1 |
|
| トピック 2 |
|
| トピック 3 |
|
| トピック 4 |
|
最近、MogiExamはIT認定試験に属するいろいろな試験に関連する最新版のJN0-481問題集を提供し始めました。例えばJN0-481日本語問題集などいろいろあります。これらの試験問題集は最新のJN0-481試験のシラバスに従って作成されたものです。試験について最新の情報を伝えられます。試験のシラバスがどのような変更をしたのか、試験に出る可能性がある新しい種類の問題について、これらの最新版の問題集には全部含まれています。ですから、IT認証試験を受験したいなら、MogiExamのJN0-481問題集を利用したほうがいいです。なぜなら、これはあなたがよりよく試験の準備をすることができる最高の方法ですから。
質問 # 77
Off-box agents are consuming too much CPU and memory on your Juniper Apstra controller. In this scenario, how would you solve this problem?
正解:C
解説:
In Apstra 5.1, off-box agents and analytics services are delivered as containerized workloads that consume CPU and memory within the Apstra cluster. When these workloads are concentrated on the controller node, the controller can become resource-constrained, impacting overall responsiveness and scaling limits. The supported architectural solution is to add a worker node (worker VM) and allow Apstra to place offbox (and, if applicable, iba) containers on that worker. This increases cluster capacity and shifts runtime load away from the controller, which should remain focused on core control-plane and management functions.
Juniper's sizing guidance also treats worker nodes as the scalable unit for off-box agent growth: each VM node (controller or worker) supports a bounded number of off-box agents, and when one VM is insufficient, the prescribed approach is to increase capacity by adding worker nodes to the Apstra VM cluster. This method scales horizontally and avoids overloading the controller with operational containers.
While increasing CPU/memory on the controller might help temporarily, the documented design pattern for sustained growth is to distribute the off-box workloads across worker nodes. Switching to on-box agents is a different operational model and not the direct remediation for controller resource pressure in an off-box deployment.
Verified Juniper sources (URLs):
https://www.juniper.net/documentation/us/en/software/apstra5.1/apstra-install-upgrade/topics/ref/apstra-server-resources.html
https://www.juniper.net/documentation/us/en/software/apstra5.0/apstra-user-guide/topics/topic-map/apstra-cluster-nodes.html
https://www.juniper.net/documentation/us/en/software/apstra4.2/apstra-user-guide/topics/topic-map/apstra-cluster-nodes.html
質問 # 78
Referring to the exhibit, what is the minimum information you must add to create a new routing zone?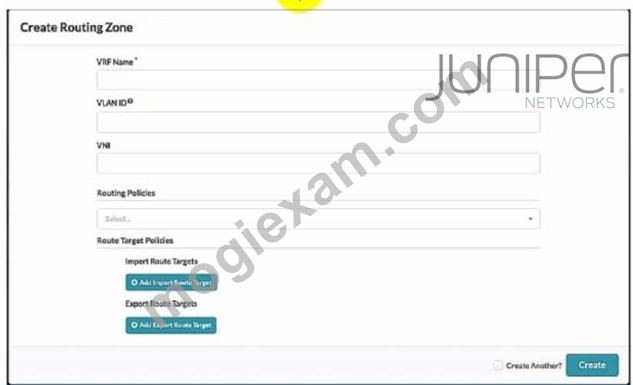
正解:B
解説:
To create a new routing zone, you must specify the VRF Name, VLAN ID, and VNI for the routing zone. These are the mandatory fields in the user interface shown in the exhibit. The VRF Name is the name of the L3 domain that isolates the IP traffic of the routing zone from other routing zones.
The VLAN ID is the identifier for the VLAN tagged Layer 3 links on external connections. The VNI is the VxLAN Network Identifier associated with the routing zone. The Routing Policies are optional fields that allow you to configure import and export route targets for the routing zone.
These are only applicable for EVPN routing zones, which use MP-EBGP as the overlay control protocol.
質問 # 79
What is the purpose of a Juniper Apstra rack?
正解:D
質問 # 80
What is the purpose of a Juniper Apstra rack?
正解:D
解説:
A Juniper Apstra rack is a physical entity that contains one or more network devices, such as leaf nodes, access switches, or generic systems. A rack is used to organize and manage the network devices in the Apstra software application. A rack has the following characteristics:
It stores information on how leaf nodes connect to generic devices. This is because a rack can include generic systems, which are devices that are not managed by Juniper Apstra, but are connected to the network. A generic system can be a server, a firewall, a load balancer, or any other device that has a network interface. A rack stores the information on how the leaf nodes, which are the devices that provide access to the end hosts, connect to the generic devices, such as the port number, the link speed, the LAG mode, and the roles1.
It has a rack type, which defines the type and number of leaf devices, access switches, and/or generic systems that are used in the rack. A rack type is a resource that is created in the data center design phase, and it does not specify the vendor or the model of the devices. A rack type can be predefined or custom-made, and it can be used to create multiple racks with the same structure and configuration2.
It has a rack build, which assigns the specific vendor and model of the devices to the rack. A rack build is created in the staged phase, and it uses the rack type as a template. A rack build can also assign the resources, such as the IP addresses, the ASNs, and the VNIs, to the devices in the rack3.
It has a rack deployment, which applies the network configuration and services to the devices in the rack. A rack deployment is performed in the active phase, and it uses the rack build as a reference. A rack deployment can also monitor the network performance and compliance of the devices in the rack4.
The following three statements are incorrect in this scenario:
It stores information on how pods connect to super spines. This is not true, because a rack does not store any information on the pod or the super spine level of the network. A pod is a cluster of leaf and spine devices that form a 3-stage Clos topology, and a super spine is a device that connects multiple pods in a 5-stage Clos topology. A rack only stores information on the leaf and the access level of the network1.
It stores IP address and ASN pool information. This is not true, because a rack does not store any information on the IP address and ASN pools. IP address and ASN pools are resources that are created in the data center design phase, and they contain a range of IP addresses and ASNs that can be assigned to the devices and the virtual networks. A rack only uses the IP address and ASN pools to assign the resources to the devices in the rack build2.
It stores device port data rates and vendor information. This is not true, because a rack does not store any information on the device port data rates and vendor information. The device port data rates and vendor information are specified in the rack build, which assigns the specific vendor and model of the devices to the rack. A rack only uses the rack build to apply the network configuration and services to the devices in the rack deployment3.
Reference:
Racks (Staged)
Rack Types (Datacenter Design)
Rack Builds (Staged)
Racks (Active)
質問 # 81
In Juniper Apstra, what does the "Staged" state of a blueprint represent?
正解:D
解説:
In Juniper Apstra, changes made to a blueprint are first placed into a Staged state, representing proposed modifications that have not yet taken effect. Administrators can review these staged changes, and once satisfied, commit them to make them Active, at which point Apstra renders and pushes the corresponding configuration to the affected devices.
質問 # 82
......
多くの人は結果が大丈夫で過程だけ重要ですって言いますが。JuniperのJN0-481試験にとってはそうではない。JuniperのJN0-481試験に合格するのはIT業界で働いているあなたに利益をもらわせることができます。もしあなたが試験に合格する決心があったら、我々のJuniperのJN0-481ソフトを利用するのはあなたの試験に成功する有効な保障です。我々のJuniperのJN0-481ソフトのデモをダウンロードしてみて我々MogiExamのあなたに合格させる自信を感じられます。
JN0-481受験料過去問: https://www.mogiexam.com/JN0-481-exam.html
2026年MogiExamの最新JN0-481 PDFダンプおよびJN0-481試験エンジンの無料共有:https://drive.google.com/open?id=1CK2vBjbzp-LxLzPCO9rgVZA1D7TVDUC1