Updated Databricks Certified-Data-Engineer-Professional Exam Questions BUNDLE PACK

ActualTestsIT is a professional website to specially provide training tools for IT certification exams and a good choice to help you pass Certified-Data-Engineer-Professional exam,too. ActualTestsIT provide exam materials about Certified-Data-Engineer-Professional certification exam for you to consolidate learning opportunities. ActualTestsIT will provide all the latest and accurate exam practice questions and answers for the staff to participate in Certified-Data-Engineer-Professional Certification Exam.
| Section | Objectives |
|---|
| Topic 1: Debugging and Deploying | - Debugging and Troubleshooting
- 1. Analyze errors and remediate failed job runs
- 2. Use Lakeflow Spark Declarative Pipelines event logs and Spark UI for debugging
- 3. Use Spark UI, cluster logs, system tables, and query profiles for diagnostics
- Deploying CI/CD
- 1. Integrate Git-based CI/CD workflows using Databricks Git Folders
- 2. Build and deploy Databricks resources using Databricks Asset Bundles
|
| Topic 2: Data Sharing and Federation | - Delta Sharing
- 1. Configure Databricks-to-Databricks Sharing
- 2. Configure sharing with external platforms using the open sharing protocol
- 3. Share live Lakehouse data with external computing platforms
- Lakehouse Federation
- 1. Configure Lakehouse Federation with appropriate governance
|
| Topic 3: Data Transformation, Cleansing, and Quality | - Advanced Data Transformation
- 1. Apply window functions, joins, and aggregations to large datasets
- 2. Write efficient Spark SQL and PySpark transformations
- Data Quality
- 1. Develop data quarantining processes for invalid data
- 2. Apply data quality controls using Lakeflow Spark Declarative Pipelines or Auto Loader
|
| Topic 4: Data Modelling | - Dimensional Modelling
- 1. Design dimensional models for analytical workloads
- Scalable Data Models
- 1. Design and implement scalable data models using Delta Lake
- 2. Optimize data layout using Liquid Clustering
- 3. Understand Liquid Clustering versus partitioning and Z-Ordering
|
| Topic 5: Developing Code for Data Processing using Python and SQL | - Building and Testing ETL Pipelines
- 1. Compare Spark Structured Streaming and Lakeflow Spark Declarative Pipelines
- 2. Compare streaming tables and materialized views
- 3. Use APPLY CHANGES APIs for change data capture
- 4. Build production-ready batch and streaming pipelines using Lakeflow Spark Declarative Pipelines and Auto Loader
- 5. Create and automate ETL workloads using Jobs through UI, APIs, and CLI
- 6. Develop unit and integration tests for data processing code
- 7. Use control flow operators in pipeline components
- 8. Configure environments, dependencies, memory, and retry behavior
- Using Python and Tools for Development
- 1. Design and implement scalable Python project structures optimized for Databricks Asset Bundles
- 2. Manage and troubleshoot third-party library installations and dependencies
- 3. Develop User-Defined Functions using Pandas/Python UDFs
|
| Topic 6: Monitoring and Alerting | - Alerting
- 1. Configure Lakeflow Jobs notifications for job status and performance issues
- 2. Use SQL Alerts for data quality monitoring
- Monitoring
- 1. Use Query Profiler and Spark UI to monitor workloads
- 2. Use Databricks REST APIs and CLI for monitoring jobs and pipelines
- 3. Use system tables for resource, cost, audit, and workload monitoring
- 4. Use Lakeflow Spark Declarative Pipelines event logs for monitoring
|
| Topic 7: Ensuring Data Security and Compliance | - Compliance
- 1. Implement pipelines that detect and mask personally identifiable information
- 2. Develop data purging solutions according to data retention policies
- Data Security
- 1. Use ACLs to secure workspace objects and enforce least privilege
- 2. Use row filters and column masks for sensitive data
- 3. Apply anonymization and pseudonymization techniques
|
| Topic 8: Data Governance | - Metadata and Discoverability
- 1. Create and maintain descriptions and metadata for enterprise data
- Unity Catalog Permissions
- 1. Understand the Unity Catalog permission inheritance model
|
| Topic 9: Cost & Performance Optimisation | - Query Performance
- 1. Use Query Profile to identify performance bottlenecks
- 2. Identify inefficient joins and excessive data shuffling
- Delta Optimization
- 1. Understand deletion vectors and liquid clustering
- 2. Apply data skipping and file pruning techniques
- 3. Use Change Data Feed to address streaming table limitations and improve latency
- Cost Optimization
- 1. Understand how Unity Catalog managed tables reduce operational overhead
|
| Topic 10: Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Ingest Delta Lake, Parquet, ORC, Avro, JSON, CSV, XML, Text, and Binary data
- 2. Build append-only pipelines for batch and streaming data using Delta
- 3. Ingest data from message buses and cloud storage
|
>> Test Certified-Data-Engineer-Professional Online <<
Free PDF Databricks - Updated Test Certified-Data-Engineer-Professional Online
ActualTestsIT is one of the leading platforms that has been helping Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) exam candidates for many years. Over this long time period we have helped Certified-Data-Engineer-Professional exam candidates in their preparation. They got help from ActualTestsIT Databricks Certified Data Engineer Professional practice questions and easily got success in the final Certified-Data-Engineer-Professional Certification Exam. You can also trust ActualTestsIT Certified-Data-Engineer-Professional exam dumps and start preparation with complete peace of mind and satisfaction.
Databricks Certified Data Engineer Professional Sample Questions (Q85-Q90):
NEW QUESTION # 85
The data engineering team maintains the following code:
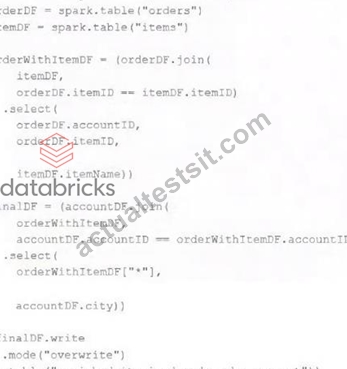
Assuming that this code produces logically correct results and the data in the source tables has been de-duplicated and validated, which statement describes what will occur when this code is executed?
- A. A batch job will update the enriched_itemized_orders_by_account table, replacing only those rows that have different values than the current version of the table, using accountID as the primary key.
- B. An incremental job will leverage information in the state store to identify unjoined rows in the source tables and write these rows to the enriched_iteinized_orders_by_account table.
- C. The enriched_itemized_orders_by_account table will be overwritten using the current valid version of data in each of the three tables referenced in the join logic.
- D. No computation will occur until enriched_itemized_orders_by_account is queried; upon query materialization, results will be calculated using the current valid version of data in each of the three tables referenced in the join logic.
- E. An incremental job will detect if new rows have been written to any of the source tables; if new rows are detected, all results will be recalculated and used to overwrite the enriched_itemized_orders_by_account table.
Answer: C
Explanation:
This is the correct answer because it describes what will occur when this code is executed. The code uses three Delta Lake tables as input sources: accounts, orders, and order_items. These tables are joined together using SQL queries to create a view called new_enriched_itemized_orders_by_account, which contains information about each order item and its associated account details. Then, the code uses write.format("delta").mode("overwrite") to overwrite a target table called enriched_itemized_orders_by_account using the data from the view. This means that every time this code is executed, it will replace all existing data in the target table with new data based on the current valid version of data in each of the three input tables.
NEW QUESTION # 86
A data pipeline uses Structured Streaming to ingest data from kafka to Delta Lake. Data is being stored in a bronze table, and includes the Kafka_generated timesamp, key, and value. Three months after the pipeline is deployed the data engineering team has noticed some latency issued during certain times of the day.
A senior data engineer updates the Delta Table's schema and ingestion logic to include the current timestamp (as recoded by Apache Spark) as well the Kafka topic and partition. The team plans to use the additional metadata fields to diagnose the transient processing delays.
Which limitation will the team face while diagnosing this problem?
- A. Updating the table schema requires a default value provided for each file added.
- B. New fields cannot be added to a production Delta table.
- C. New fields will not be computed for historic records.
- D. Spark cannot capture the topic partition fields from the kafka source.
- E. Updating the table schema will invalidate the Delta transaction log metadata.
Answer: C
Explanation:
When adding new fields to a Delta table's schema, these fields will not be retrospectively applied to historical records that were ingested before the schema change. Consequently, while the team can use the new metadata fields to investigate transient processing delays moving forward, they will be unable to apply this diagnostic approach to past data that lacks these fields.
NEW QUESTION # 87
The data engineering team is migrating an enterprise system with thousands of tables and views into the Lakehouse. They plan to implement the target architecture using a series of bronze, silver, and gold tables. Bronze tables will almost exclusively be used by production data engineering workloads, while silver tables will be used to support both data engineering and machine learning workloads. Gold tables will largely serve business intelligence and reporting purposes. While personal identifying information (PII) exists in all tiers of data, pseudonymization and anonymization rules are in place for all data at the silver and gold levels.
The organization is interested in reducing security concerns while maximizing the ability to collaborate across diverse teams.
Which statement exemplifies best practices for implementing this system?
- A. Working in the default Databricks database provides the greatest security when working with managed tables, as these will be created in the DBFS root.
- B. Isolating tables in separate databases based on data quality tiers allows for easy permissions management through database ACLs and allows physical separation of default storage locations for managed tables.
- C. Storinq all production tables in a single database provides a unified view of all data assets available throughout the Lakehouse, simplifying discoverability by granting all users view privileges on this database.
- D. Because databases on Databricks are merely a logical construct, choices around database organization do not impact security or discoverability in the Lakehouse.
- E. Because all tables must live in the same storage containers used for the database they're created in, organizations should be prepared to create between dozens and thousands of databases depending on their data isolation requirements.
Answer: B
Explanation:
This is the correct answer because it exemplifies best practices for implementing this system. By isolating tables in separate databases based on data quality tiers, such as bronze, silver, and gold, the data engineering team can achieve several benefits. First, they can easily manage permissions for different users and groups through database ACLs, which allow granting or revoking access to databases, tables, or views. Second, they can physically separate the default storage locations for managed tables in each database, which can improve performance and reduce costs. Third, they can provide a clear and consistent naming convention for the tables in each database, which can improve discoverability and usability.
NEW QUESTION # 88
A data organization has adopted Delta Sharing to securely distribute curated datasets from a Unity Catalog-enabled workspace. The data engineering team shares large Delta tables internally via Databricks-to-Databricks and externally via Open Sharing for aggregated reports. While testing, they encounter challenges related to access control, data update visibility, and shareable object types. What is a limitation of the Delta Sharing protocol or implementation when used with Databricks-to-Databricks or Open Sharing?
- A. Delta Sharing does not support Unity Catalog-enabled tables; only legacy Hive Metastore tables are shareable.
- B. Delta Sharing (both Databricks-to-Databricks and Open Sharing) allows recipients to modify the source data if they have select privileges.
- C. With Databricks-to-Databricks sharing, Unity Catalog recipients must re-ingest data manually using COPY INTO or REST APIs.
- D. With Open Sharing, recipients cannot access Volumes, Models, or notebooks -- only static Delta tables are supported.
Answer: D
Explanation:
According to Databricks' documentation, Open Sharing allows secure sharing of Delta tables to any recipient via a REST-based protocol without requiring a Databricks account. However, the Open Sharing protocol is limited to static Delta tables--it does not support sharing of Unity Catalog objects like Volumes, Machine Learning models, or notebooks. Only Databricks-to- Databricks sharing supports dynamic data sharing with update visibility and streaming reads.
Thus, the inability to share non-table objects in Open Sharing represents a known limitation of the protocol. Option A accurately reflects this constraint as described in Delta Sharing design principles and documentation.
NEW QUESTION # 89
The DevOps team has configured a production workload as a collection of notebooks scheduled to run daily using the Jobs Ul. A new data engineering hire is onboarding to the team and has requested access to one of these notebooks to review the production logic. What are the maximum notebook permissions that can be granted to the user without allowing accidental changes to production code or data?
- A. Can manage
- B. Can run
- C. Can edit
- D. Can Read
Answer: D
Explanation:
Granting a user 'Can Read' permissions on a notebook within Databricks allows them to view the notebook's content without the ability to execute or edit it. This level of permission ensures that the new team member can review the production logic for learning or auditing purposes without the risk of altering the notebook's code or affecting production data and workflows. This approach aligns with best practices for maintaining security and integrity in production environments, where strict access controls are essential to prevent unintended modifications.
NEW QUESTION # 90
......
It is known to us that the Certified-Data-Engineer-Professional exam braindumps have dominated the leading position in the global market with the decades of painstaking efforts of our experts and professors. There are many special functions about study materials to help a lot of people to reduce the heavy burdens when they are preparing for the exams. For example, the Certified-Data-Engineer-Professional study practice question from our company can help all customers to make full use of their sporadic time. Just like the old saying goes, time is our product by a good at using sporadic time person, will make achievements. If you can learn to make full use of your sporadic time to preparing for your Certified-Data-Engineer-Professional Exam, you will find that it will be very easy for you to achieve your goal on the exam. Using our study materials, your sporadic time will not be wasted, on the contrary, you will spend your all sporadic time on preparing for your Certified-Data-Engineer-Professional exam.
Certified-Data-Engineer-Professional Certified: https://www.actualtestsit.com/Databricks/Certified-Data-Engineer-Professional-exam-prep-dumps.html
- Certified-Data-Engineer-Professional Interactive Practice Exam 👪 Certified-Data-Engineer-Professional Fresh Dumps 🦁 Certified-Data-Engineer-Professional Exam Questions And Answers 🌄 Enter { www.exam4labs.com } and search for 《 Certified-Data-Engineer-Professional 》 to download for free 🦀Test Certified-Data-Engineer-Professional Result
- Certified-Data-Engineer-Professional Original Questions 📠 Reliable Certified-Data-Engineer-Professional Test Camp 🦨 Certified-Data-Engineer-Professional Fresh Dumps 👛 Open ➽ www.pdfvce.com 🢪 and search for ➥ Certified-Data-Engineer-Professional 🡄 to download exam materials for free 🔲Exam Certified-Data-Engineer-Professional Simulations
- Certified-Data-Engineer-Professional Exam Cram 🏥 Valid Certified-Data-Engineer-Professional Exam Objectives 😆 Books Certified-Data-Engineer-Professional PDF 🐊 Open ✔ www.pdfdumps.com ️✔️ enter ✔ Certified-Data-Engineer-Professional ️✔️ and obtain a free download 📤Reliable Certified-Data-Engineer-Professional Exam Labs
- Braindumps Certified-Data-Engineer-Professional Torrent 🪕 Reliable Certified-Data-Engineer-Professional Exam Practice ➿ Braindumps Certified-Data-Engineer-Professional Torrent 🥜 Search for 「 Certified-Data-Engineer-Professional 」 and obtain a free download on ✔ www.pdfvce.com ️✔️ 🐍Reliable Certified-Data-Engineer-Professional Exam Practice
- Databricks - Updated Test Certified-Data-Engineer-Professional Online ♿ Easily obtain free download of ➡ Certified-Data-Engineer-Professional ️⬅️ by searching on 「 www.verifieddumps.com 」 😅Valid Certified-Data-Engineer-Professional Exam Objectives
- Certified-Data-Engineer-Professional Exam Exercise 🦽 Valid Certified-Data-Engineer-Professional Exam Objectives 🎄 New Certified-Data-Engineer-Professional Test Testking 🦏 Download ▶ Certified-Data-Engineer-Professional ◀ for free by simply entering ⮆ www.pdfvce.com ⮄ website 💻Certified-Data-Engineer-Professional Exam Questions And Answers
- Trustable Test Certified-Data-Engineer-Professional Online - 100% Pass Certified-Data-Engineer-Professional Exam 💒 Search for ( Certified-Data-Engineer-Professional ) and download exam materials for free through ⇛ www.dumpsmaterials.com ⇚ ✔Test Certified-Data-Engineer-Professional Result
- Exam Certified-Data-Engineer-Professional Simulations 🆖 Test Certified-Data-Engineer-Professional Result 🕍 Certified-Data-Engineer-Professional Original Questions 😸 Search for ▷ Certified-Data-Engineer-Professional ◁ and obtain a free download on ▷ www.pdfvce.com ◁ 😵Books Certified-Data-Engineer-Professional PDF
- Reliable Certified-Data-Engineer-Professional Exam Practice 🍮 Certified-Data-Engineer-Professional Exam Questions And Answers 💻 Test Certified-Data-Engineer-Professional Result 🎧 Download { Certified-Data-Engineer-Professional } for free by simply searching on ( www.torrentvce.com ) 🚇Certified-Data-Engineer-Professional Exam Questions And Answers
- Databricks - Updated Test Certified-Data-Engineer-Professional Online 🥔 Search for “ Certified-Data-Engineer-Professional ” on 【 www.pdfvce.com 】 immediately to obtain a free download 🕐Certified-Data-Engineer-Professional Interactive Practice Exam
- Test Certified-Data-Engineer-Professional Result ☔ Valid Certified-Data-Engineer-Professional Exam Objectives 🥕 Braindumps Certified-Data-Engineer-Professional Torrent 🏑 Simply search for ▷ Certified-Data-Engineer-Professional ◁ for free download on { www.practicevce.com } 📕Braindumps Certified-Data-Engineer-Professional Torrent
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes