DOWNLOAD the newest Dumps4PDF DP-100 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1s4ltvGVsSadzTj8aeghcbrobQU_Dra4G
Our online test engine and the windows software of the DP-100 study materials can evaluate your exercises of the virtual exam and practice exam intelligently. Our calculation system of the DP-100 study materials is designed subtly. Our evaluation process is absolutely correct. We are strictly in accordance with the detailed grading rules of the real exam. The point of every question is set separately. Once you submit your exercises of the DP-100 Study Materials, the calculation system will soon start to work.
| Section | Objectives |
|---|---|
| Topic 1: Design and prepare a machine learning solution | - Select appropriate Azure services for machine learning workloads - Plan and configure Azure Machine Learning workspace - Manage compute and data assets |
| Topic 2: Train machine learning models | - Tune hyperparameters and evaluate models - Train models using Azure Machine Learning |
| Topic 3: Deploy and consume models | - Deploy models to endpoints - Monitor deployed models and endpoints |
| Topic 4: Explore and analyze data | - Perform exploratory data analysis - Ingest and prepare data for modeling |
| Topic 5: Optimize and manage models | - Improve model performance - Track experiments and manage model lifecycle |
The practice exams (desktop and web-based) are customizable, meaning you can set the Designing and Implementing a Data Science Solution on Azure (DP-100) questions and time according to your needs to improve your preparation for the Professional Microsoft DP-100 certification test. You can give multiple practice tests to improve yourself and even access the result of previously given tests from the history to avoid mistakes while taking the Designing and Implementing a Data Science Solution on Azure (DP-100) test. The practice tests have been made according to the latest pattern so you can practice in real Designing and Implementing a Data Science Solution on Azure (DP-100) exam environment and improve yourself daily.
NEW QUESTION # 469
You need to correct the model fit issue.
Which three actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.
Answer:
Explanation:
Explanation:
Step 1: Augment the data
Scenario: Columns in each dataset contain missing and null values. The datasets also contain many outliers.
Step 2: Add the Bayesian Linear Regression module.
Scenario: You produce a regression model to predict property prices by using the Linear Regression and Bayesian Linear Regression modules.
Step 3: Configure the regularization weight.
Regularization typically is used to avoid overfitting. For example, in L2 regularization weight, type the value to use as the weight for L2 regularization. We recommend that you use a non-zero value to avoid overfitting.
Scenario:
Model fit: The model shows signs of overfitting. You need to produce a more refined regression model that reduces the overfitting.
Incorrect Answers:
Multiclass Decision Jungle module:
Decision jungles are a recent extension to decision forests. A decision jungle consists of an ensemble of decision directed acyclic graphs (DAGs).
L-BFGS:
L-BFGS stands for "limited memory Broyden-Fletcher-Goldfarb-Shanno". It can be found in the wwo-Class Logistic Regression module, which is used to create a logistic regression model that can be used to predict two (and only two) outcomes.
References:
<https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/linear-regr ession>
NEW QUESTION # 470
You are creating a machine learning model in Python. The provided dataset contains several numerical columns and one text column.
*Biker
*Cars
*Vans
*Boats
You are building a regression model using the scikit- learn Python package.
You need to transform the text data to be compatible with the scikit-learn Python package How should you complete the code segment? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
NEW QUESTION # 471
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You have a Python script named train.py in a local folder named scripts. The script trains a regression model by using scikit-learn. The script includes code to load a training data file which is also located in the scripts folder.
You must run the script as an Azure ML experiment on a compute cluster named aml-compute.
You need to configure the run to ensure that the environment includes the required packages for model training. You have instantiated a variable named aml-compute that references the target compute cluster.
Solution: Run the following code:
Does the solution meet the goal?
Answer: A
Explanation:
The scikit-learn estimator provides a simple way of launching a scikit-learn training job on a compute target. It is implemented through the SKLearn class, which can be used to support single-node CPU training.
Example:
from azureml.train.sklearn import SKLearn
}
estimator = SKLearn(source_directory=project_folder,
compute_target=compute_target,
entry_script='train_iris.py'
)
Reference:
https://docs.microsoft.com/en-us/azure/machine-learning/how-to-train-scikit-learn
NEW QUESTION # 472
You manage an Azure Machine Learning workspace named workspace1 by using the Python SDK v2.
The default datastore of workspace1 contains a folder named sample_data. The folder structure contains the following content:
You write Python SDK v2 code to materialize the data from the files in the sample.data folder into a Pandas data frame. You need to complete the Python SDK v2 code to use the MLTaWe folder as the materialization blueprint. How should you complete the code? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Answer:
Explanation: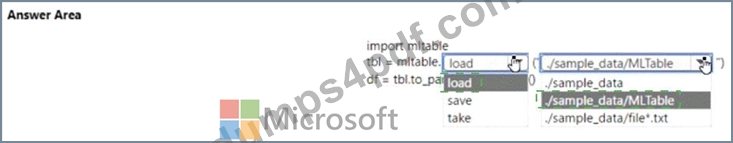
Explanation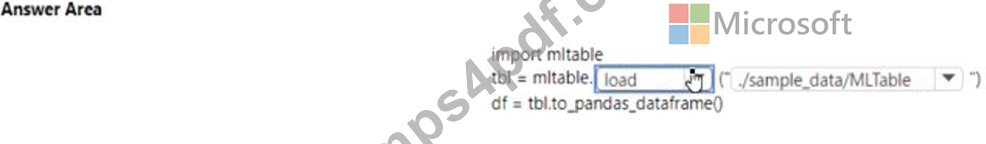
NEW QUESTION # 473
You have an Azure Machine Learning workspace
You plan to use the Azure Machine Learning SDK for Python v1 to submit a job to run a training script.
You need to complete the script to ensure that it will execute the training script.
How should you complete the script? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point
Answer:
Explanation:
NEW QUESTION # 474
......
Dumps4PDF trained experts have made sure to help the potential applicants of Designing and Implementing a Data Science Solution on Azure certification to pass their Designing and Implementing a Data Science Solution on Azure exam on the first try. Our PDF format carries real Microsoft DP-100 Exam Dumps. You can use this format of Microsoft DP-100 actual questions on your smart devices.
Practice DP-100 Exam Fee: https://www.dumps4pdf.com/DP-100-valid-braindumps.html
2026 Latest Dumps4PDF DP-100 PDF Dumps and DP-100 Exam Engine Free Share: https://drive.google.com/open?id=1s4ltvGVsSadzTj8aeghcbrobQU_Dra4G