BONUS!!! Download part of ActualPDF Databricks-Certified-Data-Engineer-Associate dumps for free: https://drive.google.com/open?id=1YYcLPDp7-RukwVWGnwMQLd5WkQXnj8bX
You will never be afraid of the Databricks-Certified-Data-Engineer-Associate exam, we believe that our Databricks-Certified-Data-Engineer-Associate preparation materials will help you change your present life. It is possible for you to start your new and meaningful life in the near future, if you can pass the Databricks-Certified-Data-Engineer-Associate exam and get the certification. So it is very important for you to prepare for the Databricks-Certified-Data-Engineer-Associate Practice Exam, you must pay more attention to the Databricks-Certified-Data-Engineer-Associate certification guide to help you. And our Databricks-Certified-Data-Engineer-Associate exam questions can give you all the help to obtain the certification.
The GAQM Databricks-Certified-Data-Engineer-Associate exam is a comprehensive test of an individual's knowledge of Databricks and its related technologies. It evaluates the ability of candidates to design, build, and maintain data pipelines using Databricks. Databricks Certified Data Engineer Associate Exam certification is ideal for data engineers, data architects, and data scientists who want to showcase their skills and knowledge in working with Databricks. Earning the certification can help individuals advance their careers and lead to better job opportunities and higher salaries.
The GAQM Databricks-Certified-Data-Engineer-Associate (Databricks Certified Data Engineer Associate) Exam is a comprehensive certification program designed to validate the skills and knowledge of data engineers in using Databricks to build and manage data pipelines, perform data analysis, and develop data-driven solutions. Databricks-Certified-Data-Engineer-Associate exam is designed for professionals who work with big data and are responsible for designing, building, and maintaining data pipelines using Databricks.
>> Databricks-Certified-Data-Engineer-Associate Exam Papers <<
It’s really a convenient way for those who are fond of paper learning. With this kind of version, you can flip through the pages at liberty and quickly finish the check-up Databricks-Certified-Data-Engineer-Associate test prep. What’s more, a sticky note can be used on your paper materials, which help your further understanding the knowledge and review what you have grasped from the notes. While you are learning with our Databricks-Certified-Data-Engineer-Associate Quiz guide, we hope to help you make out what obstacles you have actually encountered during your approach for Databricks-Certified-Data-Engineer-Associate exam torrent through our PDF version, only in this way can we help you win the Databricks-Certified-Data-Engineer-Associate certification in your first attempt.
The Databricks Databricks-Certified-Data-Engineer-Associate Exam consists of 60 multiple-choice questions and has a duration of 120 minutes. The topics covered in the exam include Databricks architecture, data ingestion, data processing, data transformation, data modeling, and data warehousing. Databricks-Certified-Data-Engineer-Associate exam is intended for data engineers, data architects, data analysts, and data scientists who have experience in working with Databricks for data engineering tasks. By obtaining this certification, candidates can demonstrate their expertise in Databricks and enhance their career prospects in the field of data engineering.
NEW QUESTION # 114
A data engineer is building a nightly batch ETL pipeline that processes very large volumes of raw JSON logs from a data lake into Delta tables for reporting. The data arrives in bulk once per day, and the pipeline takes several hours to complete. Cost efficiency is important, but performance and reliable completion of the pipeline are the highest priorities.
Which type of Databricks cluster should the data engineer configure?
Answer: B
Explanation:
For large-scale batch ETL workloads, Databricks documentation recommends using job clusters that are created specifically for a job run and terminated automatically when the job completes. A job cluster with autoscaling enabled provides the best balance of performance, reliability, and cost efficiency for long- running nightly pipelines. Autoscaling allows the cluster to dynamically add or remove worker nodes based on the workload demands, ensuring sufficient parallelism to process very large JSON datasets efficiently while avoiding overprovisioning when demand decreases. This is especially important when processing raw data into Delta tables, where shuffle-heavy transformations and writes benefit from multiple workers. Single- node clusters (option B) are not suitable for very large volumes of data and risk excessive runtimes or job failures. High-concurrency clusters (option C) are optimized for interactive and concurrent SQL queries, not long-running batch ETL jobs. Always-on all-purpose clusters (option D) increase costs unnecessarily and are intended for interactive development, not scheduled production pipelines. Databricks best practices clearly position autoscaling job clusters as the preferred solution for reliable, cost-effective batch ETL in production on Databricks.
NEW QUESTION # 115
The Delta transaction log for the 'students' tables is shown using the 'DESCRIBE HISTORY students' command. A Data Engineer needs to query the table as it existed before the UPDATE operation listed in the log.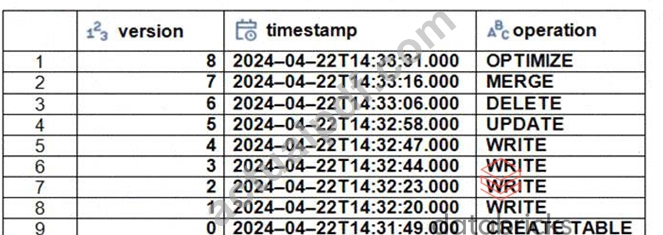
Which command should the Data Engineer use to achieve this? (Choose two.)
Answer: C,D
NEW QUESTION # 116
A data engineering team needs to ingest historical CSV files from a cloud-storage location that already contains 50,000 existing files. The team also expects new files to arrive continuously. The team wants to use Auto Loader to incrementally process both the existing files and new arrivals efficiently.
Which Auto Loader mode should the team configure for this use case?
Answer: B
NEW QUESTION # 117
A Delta table sales_fact is frequently queried with predicates on store_id and transaction_date.
Query performance has degraded because the table contains a very large number of small files.
Which command improves read performance for these query patterns?
Answer: A
Explanation:
OPTIMIZE compacts small files into larger ones, and ZORDER BY co-locates related column values in the same files so data skipping can prune more files for predicates on those columns.
VACUUM only removes unreferenced files and does not improve layout.
NEW QUESTION # 118
A dataset has been defined using Delta Live Tables and includes an expectations clause:
CONSTRAINT valid_timestamp EXPECT (timestamp > '2020-01-01') ON VIOLATION FAIL UPDATE What is the expected behavior when a batch of data containing data that violates these constraints is processed?
Answer: A
Explanation:
The expected behavior when a batch of data containing data that violates the expectation is processed is that the job will fail. This is because the expectation clause has the ON VIOLATION FAIL UPDATE option, which means that if any record in the batch does not meet the expectation, the entire batch will be rejected and the job will fail. This option is useful for enforcing strict data quality rules and preventing invalid data from entering the target dataset.
Option A is not correct, as the ON VIOLATION FAIL UPDATE option does not drop the records that violate the expectation, but fails the entire batch. To drop the records that violate the expectation and record them as invalid in the event log, the ON VIOLATION DROP RECORD option should be used.
Option C is not correct, as the ON VIOLATION FAIL UPDATE option does not drop the records that violate the expectation, but fails the entire batch. To drop the records that violate the expectation and load them into a quarantine table, the ON VIOLATION QUARANTINE RECORD option should be used.
Option D is not correct, as the ON VIOLATION FAIL UPDATE option does not add the records that violate the expectation, but fails the entire batch. To add the records that violate the expectation and record them as invalid in the event log, the ON VIOLATION LOG RECORD option should be used.
Option E is not correct, as the ON VIOLATION FAIL UPDATE option does not add the records that violate the expectation, but fails the entire batch. To add the records that violate the expectation and flag them as invalid in a field added to the target dataset, the ON VIOLATION FLAG RECORD option should be used.
Delta Live Tables Expectations
[Databricks Data Engineer Professional Exam Guide]
NEW QUESTION # 119
......
Test Databricks-Certified-Data-Engineer-Associate Simulator Free: https://www.actualpdf.com/Databricks-Certified-Data-Engineer-Associate_exam-dumps.html
P.S. Free & New Databricks-Certified-Data-Engineer-Associate dumps are available on Google Drive shared by ActualPDF: https://drive.google.com/open?id=1YYcLPDp7-RukwVWGnwMQLd5WkQXnj8bX