BONUS!!! Download part of ValidVCE ARA-C01 dumps for free: https://drive.google.com/open?id=1e60vl4qO9Jzz3VOKlqR6CI2JY3VT8Ov_
Of course, the future is full of unknowns and challenges for everyone. Even so, we all hope that we can have a bright future. Pass the ARA-C01 exam, for most people, is an ability to live the life they want, and the realization of these goals needs to be established on a good basis of having a good job. A good job requires a certain amount of competence, and the most intuitive way to measure competence is whether you get a series of the test ARA-C01 Certification and obtain enough qualifications.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Data Engineering | 25% | - Data Transformation
|
| Topic 2: Snowflake Architecture | 30% | - Storage and Compute Design
|
| Topic 3: Accounts and Security | 25% | - Governance and Compliance
|
| Topic 4: Performance Optimization | 20% | - Cost and Resource Optimization
|
>> ARA-C01 Valid Test Discount <<
ARA-C01 Guide Torrent compiled by our company is definitely will be the most sensible choice for you. In this website, you can find three different versions of our ARA-C01 guide torrent which are prepared in order to cater to the different tastes of different people from different countries in the world since we are selling our SnowPro Advanced Architect Certification test torrent in the international market. Most notably, the simulation test is available in our software version. With the simulation test, all of our customers will have an access to get accustomed to the SnowPro Advanced Architect Certification exam atmosphere and get over all of bad habits which may influence your performance in the real SnowPro Advanced Architect Certification exam.
NEW QUESTION # 162
Based on the Snowflake object hierarchy, what securable objects belong directly to a Snowflake account?
(Select THREE).
Answer: A,C,F
Explanation:
* A securable object is an entity to which access can be granted in Snowflake. Securable objects include databases, schemas, tables, views, stages, pipes, functions, procedures, sequences, tasks, streams, roles, warehouses, and shares1.
* The Snowflake object hierarchy is a logical structure that organizes the securable objects in a nested manner. The top-most container is the account, which contains all the databases, roles, and warehouses for the customer organization. Each database contains schemas, which in turn contain tables, views, stages, pipes, functions, procedures, sequences, tasks, and streams. Each role can be granted privileges on other roles or securable objects. Each warehouse can be used to execute queries on securable objects2.
* Based on the Snowflake object hierarchy, the securable objects that belong directly to a Snowflake account are databases, roles, and warehouses. These objects are created and managed at the account level, and do not depend on any other securable object. The other options are not correct because:
* Schemas belong to databases, not to accounts. A schema must be created within an existing database3.
* Tables belong to schemas, not to accounts. A table must be created within an existing schema4.
* Stages belong to schemas or tables, not to accounts. A stage must be created within an existing schema or table.
1: Overview of Access Control | Snowflake Documentation
2: Securable Objects | Snowflake Documentation
3: CREATE SCHEMA | Snowflake Documentation
4: CREATE TABLE | Snowflake Documentation
[5]: CREATE STAGE | Snowflake Documentation
NEW QUESTION # 163
Which SQL alter command will MAXIMIZE memory and compute resources for a Snowpark stored procedure when executed on the snowpark_opt_wh warehouse?



Answer: D
Explanation:
To maximize memory and compute resources for a Snowpark stored procedure, you need to set the MAX_CONCURRENCY_LEVEL parameter for the warehouse that executes the stored procedure. This parameter determines the maximum number of concurrent queries that can run on a single warehouse. By setting it to 16, you ensure that the warehouse can use all the available CPU cores and memory on a single node, which is the optimal configuration for Snowpark-optimized warehouses. This will improve the performance and efficiency of the stored procedure, as it will not have to share resources with other queries or nodes. The other options are incorrect because they either do not change the MAX_CONCURRENCY_LEVEL parameter, or they set it to a lower value than 16, which will reduce the memory and compute resources for the stored procedure. Reference:
[Snowpark-optimized Warehouses] 1
[Training Machine Learning Models with Snowpark Python] 2
[Snowflake Shorts: Snowpark Optimized Warehouses] 3
NEW QUESTION # 164
When using the COPY INTO
command with the CSV file format, how does the MATCH_BY_COLUMN_NAME parameter behave?
Answer: C
Explanation:
Comprehensive and Detailed Explanation From Exact Extract:
The MATCH_BY_COLUMN_NAME parameter in the COPY INTO
command is used to load semi-structured or structured data, such as CSV, into columns of the target table by matching column names in the data file with those in the table. For CSV files, this parameter requires specific conditions to be met, particularly the presence of a header row in the file, which is used to map columns to the target table.
According to the official Snowflake documentation, when the MATCH_BY_COLUMN_NAME parameter is used with CSV files, it is only supported in specific scenarios and requires the PARSE_HEADER file format option to be set to TRUE. This option indicates that the first row of the CSV file contains column headers, which Snowflake uses to match with the target table's column names. The matching behavior can be configured as CASE_SENSITIVE or CASE_INSENSITIVE, but the default behavior is case-sensitive unless specified otherwise.
However, there is a critical limitation when using MATCH_BY_COLUMN_NAME with CSV files: as of the latest Snowflake documentation, this feature is in Open Private Preview for CSV files and is not generally available for all accounts. When the MATCH_BY_COLUMN_NAME parameter is specified for a CSV file in an environment where this feature is not enabled, or if the PARSE_HEADER option is not set to TRUE, the COPY INTO command will return an error. This is because Snowflake cannot process the column name matching without the header parsing capability, which is not fully supported for CSV files in general availability.
The exact extract from the Snowflake documentation states:
"For loading CSV files, the MATCH_BY_COLUMN_NAME copy option is available in preview. It requires the use of the above-mentioned CSV file format option PARSE_HEADER = TRUE." Additionally, the documentation clarifies:
"Boolean that specifies whether to use the first row headers in the data files to determine column names. This file format option is applied to the following actions only: Automatically detecting column definitions by using the INFER_SCHEMA function. Loading CSV data into separate columns by using the INFER_SCHEMA function and MATCH_BY_COLUMN_NAME copy option." Furthermore, a known issue is noted:
"For CSV only, there is a known issue when the INCLUDE_METADATA copy option is used with MATCH_BY_COLUMN_NAME. Do not use this copy option when loading CSV files until the known issue is resolved." Given that the MATCH_BY_COLUMN_NAME parameter is not fully supported for CSV files in general availability and requires specific preview conditions, attempting to use it without meeting those conditions, such as PARSE_HEADER = TRUE or enabling the preview feature, results in an error. Therefore, option C is correct: The command will return an error.
Option A is incorrect because, while MATCH_BY_COLUMN_NAME expects a header in the CSV file for matching when the feature is enabled, the case-sensitive matching is only true when explicitly set to CASE_SENSITIVE. Additionally, the feature's limited availability means it is not guaranteed to work without causing an error. Option B is incorrect because the parameter is not simply ignored; it triggers an error if the conditions are not met. Option D is incorrect because Snowflake does not issue a warning for unmatched columns in this context; it fails with an error when the parameter is unsupported or misconfigured.
References:
Snowflake Documentation: COPY INTO
Snowflake Documentation: Transforming Data During a Load
Stack Overflow: COPY INTO Snowflake Table with Extra Columns
NEW QUESTION # 165
The diagram shows the process flow for Snowpipe auto-ingest with Amazon Simple Notification Service (SNS) with the following steps:
Step 1: Data files are loaded in a stage.
Step 2: An Amazon S3 event notification, published by SNS, informs Snowpipe - by way of Amazon Simple Queue Service (SQS) - that files are ready to load. Snowpipe copies the files into a queue.
Step 3: A Snowflake-provided virtual warehouse loads data from the queued files into the target table based on parameters defined in the specified pipe.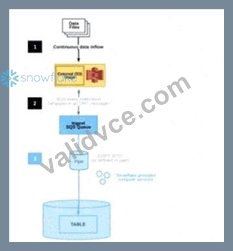
If an AWS Administrator accidentally deletes the SQS subscription to the SNS topic in Step 2, what will happen to the pipe that references the topic to receive event messages from Amazon S3?
Answer: C
Explanation:
If an AWS Administrator accidentally deletes the SQS subscription to the SNS topic in Step 2, the pipe that references the topic to receive event messages from Amazon S3 will no longer be able to receive the messages. This is because the SQS subscription is the link between the SNS topic and the Snowpipe notification channel. Without the subscription, the SNS topic will not be able to send notifications to the Snowpipe queue, and the pipe will not be triggered to load the new files. To restore the system immediately, the user needs to manually create a new SNS topic with a different name and then recreate the pipe by specifying the new SNS topic name in the pipe definition. This will create a new notification channel and a new SQS subscription for the pipe. Alternatively, the user can also recreate the SQS subscription to the existing SNS topic and then alter the pipe to use the same SNS topic name in the pipe definition. This will also restore the notification channel and the pipe functionality. References:
* Automating Snowpipe for Amazon S3
* Enabling Snowpipe Error Notifications for Amazon SNS
* HowTo: Configuration steps for Snowpipe Auto-Ingest with AWS S3 Stages
"To circumvent the 72-hour delay, you can create a SNS topic with a different name. Recreate any pipes that reference the topic using the CREATE OR REPLACE PIPE command, and specify the new topic name."
https://docs.snowflake.com/en/user-guide/data-load-snowpipe-ts#snowpipe-stops-loading-files-after-amazon- sns-topic-subscription-is-deleted
NEW QUESTION # 166
Data is being imported and stored as JSON in a VARIANT column. Query performance was fine, but most recently, poor query performance has been reported.
What could be causing this?
Answer: B
Explanation:
Data is being imported and stored as JSON in a VARIANT column. Query performance was fine, but most recently, poor query performance has been reported. This could be caused by the following factors:
* The order of the keys in the JSON was changed. Snowflake stores semi-structured data internally in a column-like structure for the most common elements, and the remainder in a leftovers-like column. The order of the keys in the JSON affects how Snowflake determines the common elements and how it optimizes the query performance. If the order of the keys in the JSON was changed, Snowflake might have to re-parse the data and re-organize the internal storage, which could result in slower query performance.
* There were variations in string lengths for the JSON values in the recent data imports. Non-native values, such as dates and timestamps, are stored as strings when loaded into a VARIANT column.
Operations on these values could be slower and also consume more space than when stored in a relational column with the corresponding data type. If there were variations in string lengths for the JSON values in the recent data imports, Snowflake might have to allocate more space and perform more conversions, which could also result in slower query performance.
The other options are not valid causes for poor query performance:
* There were JSON nulls in the recent data imports. Snowflake supports two types of null values in semi- structured data: SQL NULL and JSON null. SQL NULL means the value is missing or unknown, while JSON null means the value is explicitly set to null. Snowflake can distinguish between these two types of null values and handle them accordingly. Having JSON nulls in the recent data imports should not affect the query performance significantly.
* The recent data imports contained fewer fields than usual. Snowflake can handle semi-structured data with varying schemas and fields. Having fewer fields than usual in the recent data imports should not affect the query performance significantly, as Snowflake can still optimize the data ingestion and query execution based on the existing fields.
Considerations for Semi-structured Data Stored in VARIANT
Snowflake Architect Training
Snowflake query performance on unique element in variant column
Snowflake variant performance
NEW QUESTION # 167
......
There are other several Snowflake ARA-C01 certification exam benefits that you can gain after passing the Snowflake ARA-C01 certification exam. However, you should keep in mind that passing the SnowPro Advanced Architect Certification certification exam is not a simple and easiest task. It is a challenging job that you can make simple and successful with the complete ARA-C01 Exam Preparation.
New ARA-C01 Test Answers: https://www.validvce.com/ARA-C01-exam-collection.html
BTW, DOWNLOAD part of ValidVCE ARA-C01 dumps from Cloud Storage: https://drive.google.com/open?id=1e60vl4qO9Jzz3VOKlqR6CI2JY3VT8Ov_