Every user has rated study material positively and passed the Databricks-Certified-Data-Engineer-Professional Exam. LatestCram gives a guarantee to the customers that if they fail to pass the Databricks Certified Data Engineer Professional Exam (Databricks-Certified-Data-Engineer-Professional) certification on the very first try despite all their efforts they can claim their money back according to terms and conditions. A team of experts is working day and night in order to make the product successful day by day and provide the customers with the best experience.
| Section | Weight | Objectives |
|---|---|---|
| Monitoring and Alerting | 10% | - Monitor pipeline performance and health - Track data lineage and metrics - Set up alerts and notifications |
| Data Transformation, Cleansing, and Quality | 10% | - Apply data cleansing and validation rules - Enforce data quality standards - Implement schema evolution and management |
| Data Ingestion & Acquisition | 7% | - Handle incremental and batch data loads - Use Auto Loader and structured streaming - Ingest data from diverse sources |
| Developing Code for Data Processing using Python and SQL | 22% | - Write efficient and maintainable code - Use Databricks-specific libraries and APIs - Implement complex data processing logic |
| Ensuring Data Security and Compliance | 10% | - Secure data at rest and in transit - Ensure data privacy and compliance - Implement access control and permissions |
| Debugging and Deploying | 10% | - Troubleshoot and debug pipelines - Implement CI/CD and DevOps practices - Deploy using Asset Bundles, CLI, and APIs |
| Data Governance | 7% | - Manage data assets and metadata - Enforce data policies and standards - Use Unity Catalog for governance |
| Data Modelling | 6% | - Implement dimensional and relational models - Optimize table design and partitioning - Design Medallion Architecture |
| Cost & Performance Optimisation | 13% | - Improve query and pipeline performance - Optimize compute and storage resources - Apply cost management best practices |
| Data Sharing and Federation | 5% | - Implement Lakehouse Federation - Use Delta Sharing for secure data sharing - Manage cross-platform data access |
>> New Databricks-Certified-Data-Engineer-Professional Dumps <<
There is no doubt they are clear-cut and easy to understand to fulfill your any confusion about the exam. Our Databricks Certified Data Engineer Professional Exam exam question is applicable to all kinds of exam candidates who eager to pass the exam. Last but not the least, they help our company develop brand image as well as help a great deal of exam candidates pass the exam with passing rate over 98 percent of our Databricks-Certified-Data-Engineer-Professional real exam materials. Considering many exam candidates are in a state of anguished mood to prepare for the Databricks Certified Data Engineer Professional Exam exam, our company made three versions of Databricks-Certified-Data-Engineer-Professional Real Exam materials to offer help. All these variants due to our customer-oriented tenets. As a responsible company over ten years, we are trustworthy. In the competitive economy, this company cannot remain in the business for long.
NEW QUESTION # 113
A data organization has adopted Delta Sharing to securely distribute curated datasets from a Unity Catalog-enabled workspace. The data engineering team shares large Delta tables internally via Databricks-to-Databricks and externally via Open Sharing for aggregated reports. While testing, they encounter challenges related to access control, data update visibility, and shareable object types. What is a limitation of the Delta Sharing protocol or implementation when used with Databricks-to-Databricks or Open Sharing?
Answer: A
Explanation:
According to Databricks' documentation, Open Sharing allows secure sharing of Delta tables to any recipient via a REST-based protocol without requiring a Databricks account. However, the Open Sharing protocol is limited to static Delta tables--it does not support sharing of Unity Catalog objects like Volumes, Machine Learning models, or notebooks. Only Databricks-to- Databricks sharing supports dynamic data sharing with update visibility and streaming reads.
Thus, the inability to share non-table objects in Open Sharing represents a known limitation of the protocol. Option A accurately reflects this constraint as described in Delta Sharing design principles and documentation.
NEW QUESTION # 114
A Delta Lake table was created with the below query: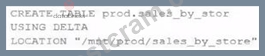
Realizing that the original query had a typographical error, the below code was executed:
ALTER TABLE prod.sales_by_stor RENAME TO prod.sales_by_store
Which result will occur after running the second command?
Answer: B
Explanation:
The query uses the CREATE TABLE USING DELTA syntax to create a Delta Lake table from an existing Parquet file stored in DBFS. The query also uses the LOCATION keyword to specify the path to the Parquet file as /mnt/finance_eda_bucket/tx_sales.parquet. By using the LOCATION keyword, the query creates an external table, which is a table that is stored outside of the default warehouse directory and whose metadata is not managed by Databricks. An external table can be created from an existing directory in a cloud storage system, such as DBFS or S3, that contains data files in a supported format, such as Parquet or CSV.
The result that will occur after running the second command is that the table reference in the metastore is updated and no data is changed. The metastore is a service that stores metadata about tables, such as their schema, location, properties, and partitions. The metastore allows users to access tables using SQL commands or Spark APIs without knowing their physical location or format. When renaming an external table using the ALTER TABLE RENAME TO command, only the table reference in the metastore is updated with the new name; no data files or directories are moved or changed in the storage system. The table will still point to the same location and use the same format as before. However, if renaming a managed table, which is a table whose metadata and data are both managed by Databricks, both the table reference in the metastore and the data files in the default warehouse directory are moved and renamed accordingly.
NEW QUESTION # 115
A data engineer is designing a system to process batch patient encounter data stored in an S3 bucket, creating a Delta table (patient_encounters) with columns encounter_id, patient_id, encounter_date, diagnosis_code, and treatment_cost. The table is queried frequently by patient_id and encounter_date, requiring fast performance. Fine-grained access controls must be enforced. The engineer wants to minimize maintenance and boost performance. How should the data engineer create the patient_encounters table?
Answer: D
Explanation:
Databricks documentation specifies that Unity Catalog managed tables are the preferred choice for secure, low-maintenance Delta Lake architectures. Managed tables provide full lifecycle management, including metadata, file storage, and access control integration with Unity Catalog.
Fine-grained permissions can be enforced at the column and row level through built-in Unity Catalog governance.
Additionally, Predictive Optimization (Auto Optimize + Auto Compaction) automatically manages file sizes, metadata pruning, and layout optimization, eliminating the need for manual maintenance such as scheduling OPTIMIZE or VACUUM.
External tables (A) require manual path management, and Hive Metastore tables (D) do not support Unity Catalog access policies. Therefore, creating a managed Unity Catalog table with predictive optimization provides both the security and performance benefits needed, making B the correct solution.
NEW QUESTION # 116
An hourly batch job is configured to ingest data files from a cloud object storage container where each batch represent all records produced by the source system in a given hour. The batch job to process these records into the Lakehouse is sufficiently delayed to ensure no late-arriving data is missed. The user_id field represents a unique key for the data, which has the following schema:
user_id BIGINT, username STRING, user_utc STRING, user_region STRING, last_login BIGINT, auto_pay BOOLEAN, last_updated BIGINT New records are all ingested into a table named account_history which maintains a full record of all data in the same schema as the source. The next table in the system is named account_current and is implemented as a Type 1 table representing the most recent value for each unique user_id.
Assuming there are millions of user accounts and tens of thousands of records processed hourly, which implementation can be used to efficiently update the described account_current table as part of each hourly batch job?
Answer: D
Explanation:
This is the correct answer because it efficiently updates the account current table with only the most recent value for each user id. The code filters records in account history using the last updated field and the most recent hour processed, which means it will only process the latest batch of data. It also filters by the max last login by user id, which means it will only keep the most recent record for each user id within that batch. Then, it writes a merge statement to update or insert the most recent value for each user id into account current, which means it will perform an upsert operation based on the user id column.
NEW QUESTION # 117
A data engineer wants to create a cluster using the Databricks CLI for a big ETL pipeline. The cluster should have five workers, one driver of type i3.xlarge, and should use the '14.3.x- scala2.12' runtime. Which command should the data engineer use?
Answer: A
Explanation:
The correct Databricks CLI command to create a new cluster is databricks clusters create. You specify the runtime with --spark-version (here '14.3.x-scala2.12'), the number of workers with -- num-workers, the node type with --node-type-id, and the cluster name with --cluster-name. This command properly initializes the cluster with the desired configuration.
NEW QUESTION # 118
......
Databricks Certified Data Engineer Professional Exam Questions are Very Beneficial for Strong Preparation. The top objective of LatestCram is to offer real Databricks Exam Databricks-Certified-Data-Engineer-Professional exam questions so that you can get success in the Databricks-Certified-Data-Engineer-Professional actual test easily. The Databricks Exam Databricks Certified Data Engineer Professional Exam valid dumps by the LatestCram are compiled by a team of experts. We have hired these Databricks-Certified-Data-Engineer-Professional Exam professionals to ensure the top quality of our product. This team works together and compiles the most probable Databricks Certified Data Engineer Professional Exam exam questions. So you can trust Databricks Exams Practice questions without any doubt.
Databricks-Certified-Data-Engineer-Professional Authorized Certification: https://www.latestcram.com/Databricks-Certified-Data-Engineer-Professional-exam-cram-questions.html