P.S. Free & New AI-500 dumps are available on Google Drive shared by RealExamFree: https://drive.google.com/open?id=1mTK5jPluz7xCp-Mr0NIOzpHdhHkW4KMU
The Microsoft AI-500 dumps are given regular update checks in case of any update. We make sure that candidates are not preparing for the Microsoft AI-500 exam from outdated and unreliable AI-500 study material. RealExamFree offers you a free demo version of the Microsoft AI-500 Dumps. This way candidates can easily check the validity and reliability of the AI-500 exam products without having to spend time.
| Section | Weight | Objectives |
|---|---|---|
| Develop multi-agent solutions in Azure | 30–35% | - Implement agents using Azure AI services
|
| Secure, govern, and deploy multi-agent solutions | 20–25% | - Apply security and compliance
|
| Architect multi-agent solutions | 15–20% | - Design workflow and tool integration
|
| Evaluate, optimize, and monitor multi-agent solutions | 20–25% | - Implement observability
|
>> Trusted AI-500 Exam Resource <<
It is seen as a challenging task to pass the AI-500 exam. Tests like these demand profound knowledge. The Microsoft AI-500 certification is absolute proof of your talent and ticket to high-paying jobs in a renowned firm. Designing and Implementing Multi-Agent AI Solutions AI-500 test every year to shortlist applicants who are eligible for the AI-500 exam certificate.
NEW QUESTION # 72
You need to modify claim Approval to prevent the prompt injection issue. Which guardrail should you use?
Answer: A
Explanation:
The malicious text is contained in an uploaded email rather than being typed directly as the user ' s prompt.
Microsoft classifies malicious instructions embedded in external or retrieved content as an indirect prompt- injection attack. Prompt Shields for documents is designed to detect those attacks in document content before the content can steer the model away from its system instructions. Prompt Shields for user prompts addresses direct attacks originating in the user ' s prompt and therefore targets the wrong attack surface here.
Groundedness evaluates whether a response is supported by context; it does not prevent an injected instruction from changing agent behavior. Task Adherence can assess whether an agent follows its task constraints, but it is not the primary control for document-borne prompt injection. Because the source of the attack is the uploaded email, the document-oriented Prompt Shields control is the technically aligned guardrail. The same configuration should be paired with auditable identity, trace, and evaluation data so reviewers can prove which principal acted, which policy was applied, and why a request was allowed or blocked. That is particularly important for production multi-agent systems with external tools.
Official Microsoft reference: Microsoft Foundry guardrails - intervention points and indirect attacks
NEW QUESTION # 73
You have a Microsoft Foundry multi-agent solution that includes a orchestrator and agents named Agent1 and Agent2. The solution has the following characteristics:
* The orchestrator routes tasks to both agents.
* The agents invoice Model Context Protocol (MCP)-hosted tools.
* Agent? sends model-generated JSON parameters directly to tool endpoints.
* The agents use a shared managed identity that has contributor access to the resource group that contains the tool-backed Azure resources.
You need to implement a guardrail strategy for tool calls. The solution must meet the following requirements:
* Prevent invalid or out-of-range tool parameters from reaching the tool endpoints.
* Scope each agent ' s permissions to its assigned tools
* Limit Agent? to refund-processing tools only.
* Log tool invocations for audit purposes.
What should you do?
Answer: C
Explanation:
The solution needs deterministic validation before model-generated tool arguments reach MCP endpoints, per- agent authorization boundaries, tool scoping, and audit logging. Validating typed payload schemas at the tool boundary prevents malformed or out-of-range arguments before execution, which is stronger than validating outputs after a tool has already run. Per-agent managed identities and scoped RBAC roles reduce lateral movement and contain the impact of a compromised agent. A per-agent tool-access policy also ensures the refund-focused agent cannot invoke unrelated tools. Finally, Azure Monitor/trace logging provides an auditable record of tool invocations. A2A capability cards describe remote-agent capabilities rather than validate tool arguments. System instructions are not an authorization boundary, and shared Contributor access leaves an excessive blast radius. Option D is therefore the only answer that satisfies all four requirements at enforceable platform boundaries. From a security and governance perspective, the control should be enforced at the narrowest platform boundary that can deterministically block or constrain the action. Relying only on prompt text is weaker because the model can still be induced to behave unexpectedly.
Official Microsoft reference: AI-500 Study Guide - tool scopes, permission boundaries, and auditing
NEW QUESTION # 74
You have a Microsoft Foundry agent that completes benefits enrollment during a single user conversation The agent collects the required enrollment fields during 15 turns. Users can correct earlier values before final submission. The current implementation sends the complete transcript with every model request.
You need to change the context accumulation strategy for the active enrollment. The solution must meet the following requirements:
* Preserve the latest value for each required enrollment field until submission.
* Bound the maximum number of tokens sent with each model request
* Preserve user corrections until submission.
* Prevent durable cross-session memory.
What should you do?
Answer: D
Explanation:
The application must preserve the latest authoritative value of each enrollment field even when the user corrects an earlier value, while also placing a firm bound on prompt size. A session-scoped enrollment-state snapshot provides deterministic structured state: each correction overwrites the previous field value. A recent- turn sliding window then preserves enough conversational context for natural interaction without resending the full 15-turn transcript. Response chaining with a fixed number of prior turns can lose an important field once it falls outside the retained history. Summarization can omit or distort corrected values, and automatic truncation likewise offers no guarantee that the latest value of every required field survives. Because the state is scoped only to the active enrollment and is not written to long-term memory, the design also avoids durable cross-session memory. Therefore A is correct. At implementation time, the same rule should be expressed through the framework or service configuration rather than left only as a natural-language convention. That makes the behavior repeatable across runs, easier to test, and less sensitive to model variability.
Official Microsoft reference: Microsoft Agent Framework - workflow state and context management
NEW QUESTION # 75
You need to recommend a Microsoft Foundry multi-agent solution that has the following domain-specific requirements:
* Agent responses must never include the names of two specific sanctioned companies.
* Agent responses must NOT expose customer account numbers
Which guardrail strategy should you include in the recommendation?
Answer: D
Explanation:
Both stated restrictions concern content that must not appear in the agent ' s final output. A custom blocklist should therefore be applied to agent output so the two sanctioned company names are detected before a response is returned. The customer-account requirement likewise belongs at the output boundary, where PII
/sensitive-data detection can identify protected identifiers in generated content. Applying the controls only to user input would not stop the model from generating the prohibited names or identifiers itself. Task Adherence focuses on whether agent behavior stays within assigned procedures and is not a substitute for explicit output filtering. Microsoft Foundry guardrails are designed to attach controls to the intervention point where the relevant risk occurs. Because the risk is disclosure in the response, option C is the configuration that places both controls at the correct boundary. The same configuration should be paired with auditable identity, trace, and evaluation data so reviewers can prove which principal acted, which policy was applied, and why a request was allowed or blocked. That is particularly important for production multi-agent systems with external tools.
Official Microsoft reference: Microsoft Foundry guardrails - intervention points
NEW QUESTION # 76
You have a Microsoft Foundry multi-agent solution that includes the following agents:
* An orchestrator agent
* A supplier worker agent that runs the APIs of external suppliers
* A finance worker agent that has confidential enterprise resource planning {ERP) access You need to implement resource access boundaries that meet the following requirements:
* Limit the blast radius if a worker agent is compromised.
* Allow each agent to access only its required downstream resources.
What should you configure? To answer, select the appropriate options in the answer area. NOTE: Each correct selection is worth one point.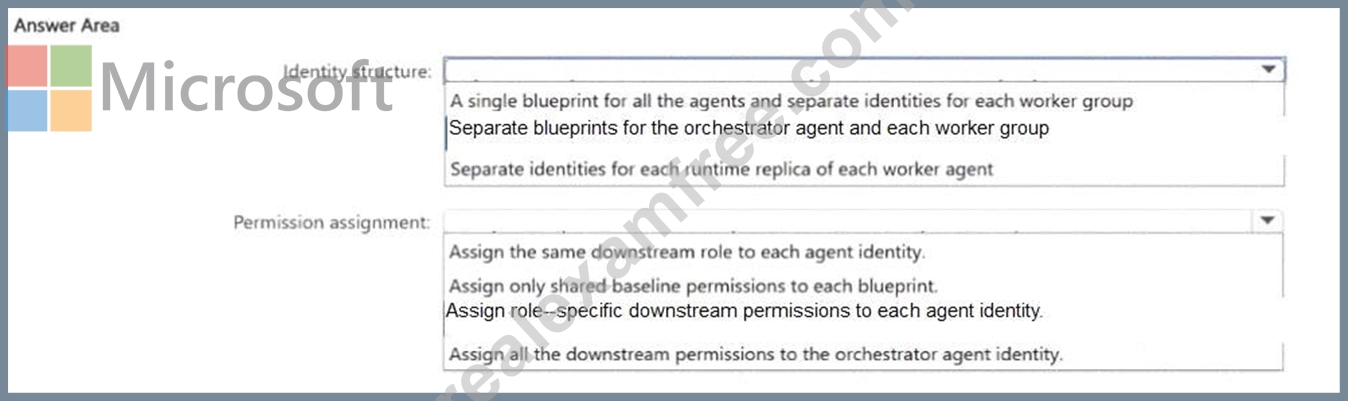
Answer:
Explanation: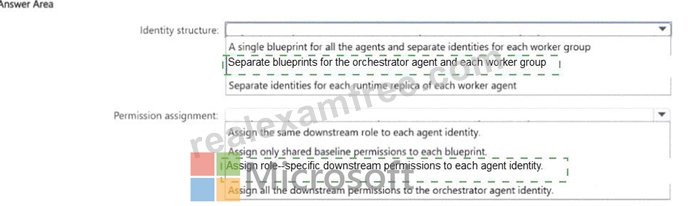
Explanation:
Identity structure: Separate blueprints for the orchestrator agent and each worker group; Permission assignment: Assign role-specific downstream permissions to each agent identity.
The supplier and finance workers operate in different trust domains: one reaches external supplier APIs while the other has confidential ERP access. Microsoft Entra Agent ID guidance recommends separating blueprint
/identity trust boundaries when compromise of one agent must not expose unrelated credentials or permissions. Each logical agent identity should then receive only the downstream roles required for its own function. This creates clear audit attribution and limits lateral movement. Giving all workers the same role or routing every privileged operation through an overly powerful orchestrator would expand the blast radius.
Creating an identity for every runtime replica is unnecessary when replicas represent the same logical agent role. The correct structure therefore separates the orchestrator and worker trust domains and assigns role- specific permissions to each identity rather than sharing a common authorization envelope. The same configuration should be paired with auditable identity, trace, and evaluation data so reviewers can prove which principal acted, which policy was applied, and why a request was allowed or blocked. That is particularly important for production multi-agent systems with external tools.
Official Microsoft reference: Microsoft Entra Agent ID - plan agent identity architecture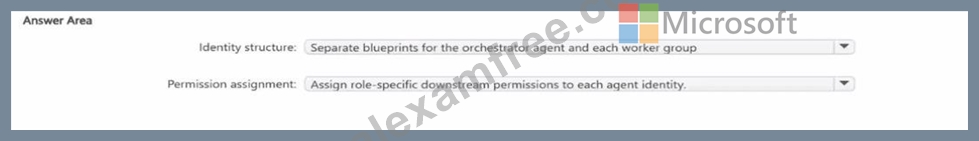
NEW QUESTION # 77
......
The latest technologies have been applied to our AI-500 actual exam as well since we are at the most leading position in this field. You can get a complete new and pleasant study experience with our AI-500 study materials. Besides, you have varied choices for there are three versions of our AI-500 practice materials. At the same time, you are bound to pass the exam and get your desired certification for the validity and accuracy of our AI-500 training guide.
New AI-500 Mock Test: https://www.realexamfree.com/AI-500-real-exam-dumps.html
P.S. Free & New AI-500 dumps are available on Google Drive shared by RealExamFree: https://drive.google.com/open?id=1mTK5jPluz7xCp-Mr0NIOzpHdhHkW4KMU