Our Databricks-Certified-Data-Engineer-Professional exam questions just focus on what is important and help you achieve your goal. With high-quality Databricks-Certified-Data-Engineer-Professional guide materials and flexible choices of learning mode, they would bring about the convenience and easiness for you. Every page is carefully arranged by our experts with clear layout and helpful knowledge to remember. In your every stage of review, our Databricks-Certified-Data-Engineer-Professional practice prep will make you satisfied.
| Section | Objectives |
|---|---|
| Data Modeling and Transformation | - Spark SQL transformations - Dimensional modeling concepts - Performance optimization techniques |
| Delta Lake and Data Management | - Time travel and versioning - Delta Lake transactions and ACID properties - Schema evolution and enforcement |
| Databricks Lakehouse Platform Architecture | - Workspace and cluster architecture - Data governance concepts (Unity Catalog basics) - Medallion architecture (Bronze, Silver, Gold) |
| Production Pipelines and Orchestration | - Error handling and recovery strategies - Databricks Workflows - Job scheduling and monitoring |
| Data Ingestion and Processing | - ETL pipeline design patterns - Structured Streaming fundamentals - Batch and streaming ingestion with Auto Loader |
>> Reliable Databricks-Certified-Data-Engineer-Professional Study Notes <<
Our Databricks Certified Data Engineer Professional Exam exam questions are curated and crafted by experts. We have put in a lot of efforts to create amazing guides for our customers. Passing Databricks-Certified-Data-Engineer-Professional can be hard, and you won’t find such exam Databricks-Certified-Data-Engineer-Professional Brain Dumps anywhere. With Databricks-Certified-Data-Engineer-Professional sample questions exam dumps, you can secure high marks in the Databricks-Certified-Data-Engineer-Professional. We provide 100% money back guarantee on exam Databricks-Certified-Data-Engineer-Professional practice exam products.
NEW QUESTION # 247
A data engineer is using Auto Loader to read incoming JSON data as it arrives. They have configured Auto Loader to quarantine invalid JSON records but notice that over time, some records are being quarantined even though they are well-formed JSON.
The code snippet is:
df = (spark.readStream
.format("cloudFiles")
.option("cloudFiles.format", "json")
.option("badRecordsPath", "/tmp/somewhere/badRecordsPath")
.schema("a int, b int")
.load("/Volumes/catalog/schema/raw_data/"))
What is the cause of the missing data?
Answer: B
Explanation:
Auto Loader quarantines records that cannot be parsed according to the specified schema, even if the JSON itself is well formed. If incoming records contain additional fields, missing fields, or incompatible data types compared to the declared schema, they are treated as invalid and routed to the bad records path.
NEW QUESTION # 248
A data engineer wants to refactor the following DLT code, which includes multiple table definitions with very similar code.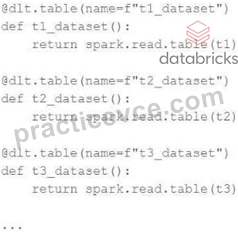
In an attempt to programmatically create these tables using a parameterized table definition, the data engineer writes the following code.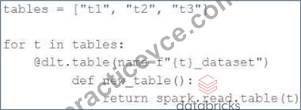
The pipeline runs an update with this refactored code, but generates a different DAG showing incorrect configuration values for these tables.
How can the data engineer fix this?
Answer: B
Explanation:
The issue with the refactored code is that it tries to use string interpolation to dynamically create table names within the dlc.table decorator, which will not correctly interpret the table names.
Instead, by using a dictionary with table names as keys and their configurations as values, the data engineer can iterate over the dictionary items and use the keys (table names) to properly configure the table settings. This way, the decorator can correctly recognize each table name, and the corresponding configuration settings can be applied appropriately.
NEW QUESTION # 249
A junior data engineer has been asked to develop a streaming data pipeline with a grouped aggregation using DataFrame df. The pipeline needs to calculate the average humidity and average temperature for each non-overlapping five-minute interval. Events are recorded once per minute per device.
Streaming DataFrame df has the following schema:
"device_id INT, event_time TIMESTAMP, temp FLOAT, humidity FLOAT"
Code block: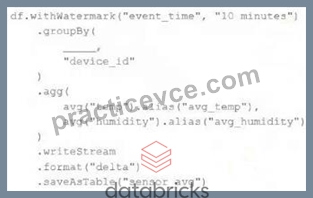
Choose the response that correctly fills in the blank within the code block to complete this task.
Answer: D
Explanation:
This is the correct answer because the window function is used to group streaming data by time intervals. The window function takes two arguments: a time column and a window duration. The window duration specifies how long each window is, and must be a multiple of 1 second. In this case, the window duration is "5 minutes", which means each window will cover a non-overlapping five- minute interval. The window function also returns a struct column with two fields: start and end, which represent the start and end time of each window. The alias function is used to rename the struct column as "time".
NEW QUESTION # 250
The data science team has requested assistance in accelerating queries on free form text from user reviews. The data is currently stored in Parquet with the below schema:
item_id INT, user_id INT, review_id INT, rating FLOAT, review STRING
The review column contains the full text of the review left by the user. Specifically, the data science team is looking to identify if any of 30 key words exist in this field.
A junior data engineer suggests converting this data to Delta Lake will improve query performance.
Which response to the junior data engineer's suggestion is correct?
Answer: B
Explanation:
Converting the data to Delta Lake may not improve query performance on free text fields with high cardinality, such as the review column. This is because Delta Lake collects statistics on the minimum and maximum values of each column, which are not very useful for filtering or skipping data on free text fields. Moreover, Delta Lake collects statistics on the first 32 columns by default, which may not include the review column if the table has more columns. Therefore, the junior data engineer's suggestion is not correct. A better approach would be to use a full-text search engine, such as Elasticsearch, to index and query the review column. Alternatively, you can use natural language processing techniques, such as tokenization, stemming, and lemmatization, to preprocess the review column and create a new column with normalized terms that can be used for filtering or skipping data.
NEW QUESTION # 251
A workspace admin has created a new catalog called finance_data and wants to delegate permission management to a finance team lead without giving them full admin rights. Which privilege should be granted to the finance team lead?
Answer: C
Explanation:
The MANAGE privilege in Unity Catalog provides the ability to grant and revoke privileges on the specified object (in this case, a catalog) without giving full administrative access or ownership.
This is the Databricks-recommended approach for delegating governance responsibilities while preserving the principle of least privilege.
By contrast, the ALL PRIVILEGES option grants excessive access (including read and write permissions), and metastore admin status provides global control over all catalogs--far exceeding the requirement. The MANAGE privilege enables the finance team lead to control access to objects within finance_data responsibly while limiting overall administrative exposure.
NEW QUESTION # 252
......
PracticeVCE have a professional IT team to do research for practice questions and answers of the Databricks Databricks-Certified-Data-Engineer-Professional exam certification exam. They provide a very effective training tools and online services for your. If you want to buy PracticeVCE products, PracticeVCE will provide you with the latest, the best quality and very detailed training materials as well as a very accurate exam practice questions and answers to be fully prepared for you to participate in the Databricks Certification Databricks-Certified-Data-Engineer-Professional Exam. Safely use the questions provided by PracticeVCE's products. Selecting the PracticeVCE is equal to be 100% passing the exam.
Databricks-Certified-Data-Engineer-Professional Mock Exam: https://www.practicevce.com/Databricks/Databricks-Certified-Data-Engineer-Professional-practice-exam-dumps.html