MLA-C01시험합격덤프최신덤프무료샘플

2026 PassTIP 최신 MLA-C01 PDF 버전 시험 문제집과 MLA-C01 시험 문제 및 답변 무료 공유: https://drive.google.com/open?id=1WZIG-_ZRuG0BNcYdZdxQZzJDdW4l0_Kt
Amazon인증 MLA-C01시험은 IT인증시험중 가장 인기있는 시험입니다. Amazon인증 MLA-C01시험패스는 모든 IT인사들의 로망입니다. PassTIP의 완벽한 Amazon인증 MLA-C01덤프로 시험준비하여 고득점으로 자격증을 따보세요.
Amazon MLA-C01 시험요강:
| 주제 | 소개 |
|---|
| 주제 1 | - ML Model Development: This section of the exam measures skills of Fraud Examiners and covers choosing and training machine learning models to solve business problems such as fraud detection. It includes selecting algorithms, using built-in or custom models, tuning parameters, and evaluating performance with standard metrics. The domain emphasizes refining models to avoid overfitting and maintaining version control to support ongoing investigations and audit trails.
|
| 주제 2 | - ML Solution Monitoring, Maintenance, and Security: This section of the exam measures skills of Fraud Examiners and assesses the ability to monitor machine learning models, manage infrastructure costs, and apply security best practices. It includes setting up model performance tracking, detecting drift, and using AWS tools for logging and alerts. Candidates are also tested on configuring access controls, auditing environments, and maintaining compliance in sensitive data environments like financial fraud detection.
|
| 주제 3 | - Data Preparation for Machine Learning (ML): This section of the exam measures skills of Forensic Data Analysts and covers collecting, storing, and preparing data for machine learning. It focuses on understanding different data formats, ingestion methods, and AWS tools used to process and transform data. Candidates are expected to clean and engineer features, ensure data integrity, and address biases or compliance issues, which are crucial for preparing high-quality datasets in fraud analysis contexts.
|
| 주제 4 | - Deployment and Orchestration of ML Workflows: This section of the exam measures skills of Forensic Data Analysts and focuses on deploying machine learning models into production environments. It covers choosing the right infrastructure, managing containers, automating scaling, and orchestrating workflows through CI
- CD pipelines. Candidates must be able to build and script environments that support consistent deployment and efficient retraining cycles in real-world fraud detection systems.
|
>> MLA-C01시험합격덤프 <<
MLA-C01 덤프자료 & MLA-C01 덤프문제 & MLA-C01 시험자료
PassTIP의 Amazon인증 MLA-C01시험덤프는 실제시험의 기출문제와 예상문제를 묶어둔 공부자료로서 시험문제커버율이 상당히 높습니다.IT업계에 계속 종사하려는 IT인사들은 부단히 유력한 자격증을 취득하고 자신의 자리를 보존해야 합니다. PassTIP의 Amazon인증 MLA-C01시험덤프로 어려운 Amazon인증 MLA-C01시험을 쉽게 패스해보세요. IT자격증 취득이 여느때보다 여느일보다 쉬워져 자격증을 많이 따는 꿈을 실현해드립니다.
최신 AWS Certified Associate MLA-C01 무료샘플문제 (Q22-Q27):
질문 # 22
A company is planning to create several ML prediction models. The training data is stored in Amazon S3. The entire dataset is more than 5 TB in size and consists of CSV, JSON, Apache Parquet, and simple text files.
The data must be processed in several consecutive steps. The steps include complex manipulations that can take hours to finish running. Some of the processing involves natural language processing (NLP) transformations. The entire process must be automated.
Which solution will meet these requirements?
- A. Use Amazon SageMaker notebooks for each data processing step. Automate the process by using Amazon EventBridge.
- B. Process data at each step by using AWS Lambda functions. Automate the process by using AWS Step Functions and Amazon EventBridge.
- C. Process data at each step by using Amazon SageMaker Data Wrangler. Automate the process by using Data Wrangler jobs.
- D. Use Amazon SageMaker Pipelines to create a pipeline of data processing steps. Automate the pipeline by using Amazon EventBridge.
정답:D
질문 # 23
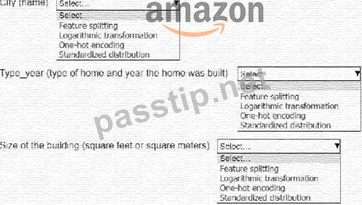
An ML engineer is working on an ML model to predict the prices of similarly sized homes. The model will base predictions on several features The ML engineer will use the following feature engineering techniques to estimate the prices of the homes:
* Feature splitting
* Logarithmic transformation
* One-hot encoding
* Standardized distribution
Select the correct feature engineering techniques for the following list of features. Each feature engineering technique should be selected one time or not at all (Select three.)
정답:
설명:
Explanation:
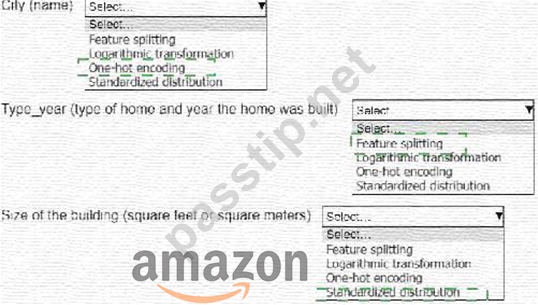
* City (name): One-hot encoding
* Type_year (type of home and year the home was built): Feature splitting
* Size of the building (square feet or square meters): Standardized distribution
* City (name): One-hot encoding
* Why? The "City" is a categorical feature (non-numeric), so one-hot encoding is used to transform it into a numeric format. This encoding creates binary columns for each unique category (e.g., cities like "New York" or "Los Angeles"), which the model can interpret.
* Type_year (type of home and year the home was built): Feature splitting
* Why? "Type_year" combines two pieces of information into one column, which could confuse the model. Feature splitting separates this column into two distinct features: "Type of home" and
"Year built," enabling the model to process each feature independently.
* Size of the building (square feet or square meters): Standardized distribution
* Why? Size is a continuous numerical variable, and standardization (scaling the feature to have a mean of 0 and a standard deviation of 1) ensures that the model treats it fairly compared to other features, avoiding bias from differences in feature scale.
By applying these feature engineering techniques, the ML engineer can ensure that the input data is correctly formatted and optimized for the model to make accurate predictions.
질문 # 24
A company is using Amazon SageMaker to develop ML models. The company stores sensitive training data in an Amazon S3 bucket. The model training must have network isolation from the internet.
Which solution will meet this requirement?
- A. Run the SageMaker training jobs in private subnets. Create a NAT gateway. Route traffic for training through the NAT gateway.
- B. Encrypt traffic to Amazon S3 by using a bucket policy that includes a value of True for the aws:SecureTransport condition key. Use default at-rest encryption for Amazon S3. Encrypt SageMaker instance storage by using server-side encryption with AWS KMS keys (SSE-KMS).
- C. Run the SageMaker training jobs in private subnets. Create an S3 gateway VPC endpoint. Route traffic for training through the S3 gateway VPC endpoint.
- D. Run the SageMaker training jobs in public subnets that have an attached security group. In the security group, use inbound rules to limit traffic from the internet. Encrypt SageMaker instance storage by using server-side encryption with AWS KMS keys (SSE-KMS).
정답:C
질문 # 25
An ML engineer has trained a neural network by using stochastic gradient descent (SGD). The neural network performs poorly on the test set. The values for training loss and validation loss remain high and show an oscillating pattern. The values decrease for a few epochs and then increase for a few epochs before repeating the same cycle.
What should the ML engineer do to improve the training process?
- A. Increase the learning rate.
- B. Increase the size of the test set.
- C. Introduce early stopping.
- D. Decrease the learning rate.
정답:D
질문 # 26
A company stores time-series data about user clicks in an Amazon S3 bucket. The raw data consists of millions of rows of user activity every day. ML engineers access the data to develop their ML models.
The ML engineers need to generate daily reports and analyze click trends over the past 3 days by using Amazon Athena. The company must retain the data for 30 days before archiving the data.
Which solution will provide the HIGHEST performance for data retrieval?
- A. Organize the time-series data into partitions by date prefix in the S3 bucket. Apply S3 Lifecycle policies to archive partitions that are older than 30 days to S3 Glacier Flexible Retrieval.
- B. Put each day's time-series data into its own S3 bucket. Use S3 Lifecycle policies to archive S3 buckets that hold data that is older than 30 days to S3 Glacier Flexible Retrieval.
- C. Create AWS Lambda functions to copy the time-series data into separate S3 buckets. Apply S3 Lifecycle policies to archive data that is older than 30 days to S3 Glacier Flexible Retrieval.
- D. Keep all the time-series data without partitioning in the S3 bucket. Manually move data that is older than 30 days to separate S3 buckets.
정답:A
설명:
Partitioning the time-series data by date prefix in the S3 bucket significantly improves query performance in Amazon Athena by reducing the amount of data that needs to be scanned during queries. This allows the ML engineers to efficiently analyze trends over specific time periods, such as the past 3 days. Applying S3 Lifecycle policies to archive partitions older than 30 days to S3 Glacier FlexibleRetrieval ensures cost- effective data retention and storage management while maintaining high performance for recent data retrieval.
질문 # 27
......
우리PassTIP에서는 각종IT시험에 관심있는분들을 위하여, 여러 가지 인증시험자료를 제공하는 사이트입니다. 우리PassTIP는 많은 분들이 IT인증시험을 응시하여 성공할수록 도와주는 사이트입니다. 우리의 파워는 아주 대단하답니다. 여러분은 우리PassTIP 사이트에서 제공하는Amazon MLA-C01관련자료의 일부분문제와답등 샘플을 무료로 다운받아 체험해봄으로 우리에 믿음이 생기게 될 것입니다.
MLA-C01퍼펙트 최신버전 자료: https://www.passtip.net/MLA-C01-pass-exam.html
- 100% 유효한 MLA-C01시험합격덤프 덤프 💦 【 www.exampassdump.com 】의 무료 다운로드➠ MLA-C01 🠰페이지가 지금 열립니다MLA-C01최신버전 시험덤프
- MLA-C01높은 통과율 시험덤프공부 🎏 MLA-C01최신버전 시험덤프 🛥 MLA-C01합격보장 가능 시험대비자료 🔐 「 www.itdumpskr.com 」웹사이트를 열고➠ MLA-C01 🠰를 검색하여 무료 다운로드MLA-C01인기덤프공부
- 최신 MLA-C01시험합격덤프 인증덤프 데모문제 다운 💃 오픈 웹 사이트( www.dumptop.com )검색[ MLA-C01 ]무료 다운로드MLA-C01유효한 인증시험덤프
- MLA-C01합격보장 가능 시험대비자료 🏓 MLA-C01인기자격증 시험대비자료 🤿 MLA-C01최고품질 예상문제모음 🟣 「 www.itdumpskr.com 」을(를) 열고{ MLA-C01 }를 검색하여 시험 자료를 무료로 다운로드하십시오MLA-C01최신시험
- MLA-C01:AWS Certified Machine Learning Engineer - Associate 시험덤프 MLA-C01응시자료 🚦 ➥ kr.fast2test.com 🡄은「 MLA-C01 」무료 다운로드를 받을 수 있는 최고의 사이트입니다MLA-C01최신버전 시험덤프공부
- 최신버전 MLA-C01시험합격덤프 퍼펙트한 덤프의 모든 문제를 기억하면 시험패스 가능 🥁 시험 자료를 무료로 다운로드하려면➠ www.itdumpskr.com 🠰을 통해▷ MLA-C01 ◁를 검색하십시오MLA-C01퍼펙트 공부
- MLA-C01최신 업데이트버전 덤프문제 🔪 MLA-C01퍼펙트 공부 🎊 MLA-C01최신버전 시험덤프공부 🥝 지금⏩ www.koreadumps.com ⏪을(를) 열고 무료 다운로드를 위해⏩ MLA-C01 ⏪를 검색하십시오MLA-C01최신버전 시험덤프
- 100% 유효한 MLA-C01시험합격덤프 덤프 🚬 무료로 쉽게 다운로드하려면{ www.itdumpskr.com }에서☀ MLA-C01 ️☀️를 검색하세요MLA-C01인기덤프공부
- MLA-C01최신 덤프문제 ⚜ MLA-C01높은 통과율 시험덤프공부 🌸 MLA-C01합격보장 가능 시험대비자료 🌕 시험 자료를 무료로 다운로드하려면【 kr.fast2test.com 】을 통해⇛ MLA-C01 ⇚를 검색하십시오MLA-C01인기덤프공부
- MLA-C01인기자격증 시험 덤프자료 👞 MLA-C01인기자격증 시험 덤프자료 🦺 MLA-C01합격보장 가능 시험대비자료 💈 《 www.itdumpskr.com 》웹사이트를 열고「 MLA-C01 」를 검색하여 무료 다운로드MLA-C01높은 통과율 시험덤프공부
- MLA-C01합격보장 가능 시험대비자료 🚲 MLA-C01최신시험 🍵 MLA-C01높은 통과율 인기덤프 🚦 ✔ www.exampassdump.com ️✔️은➽ MLA-C01 🢪무료 다운로드를 받을 수 있는 최고의 사이트입니다MLA-C01퍼펙트 공부
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
2026 PassTIP 최신 MLA-C01 PDF 버전 시험 문제집과 MLA-C01 시험 문제 및 답변 무료 공유: https://drive.google.com/open?id=1WZIG-_ZRuG0BNcYdZdxQZzJDdW4l0_Kt