Jpexamお支払いが完了すると、システムから5〜10分以内にMicrosoft電子メールが届きます。その後、高品質のAI-200試験ガイドを使用してすぐに学習できます。 誰もが時間が非常に重要であることを知っており、AI-200試験に合格するために効率的に学習したいと考えています。 AI-200の実践教材を発見したら、彼らは間違いなく学習する時間をつかむことを望むでしょう。 したがって、支払い後、Developing AI Cloud Solutions on Azure試験データベースにダウンロードすることが製品の利点です。 早急にAI-200ガイドトレントをダウンロードして使用すると、AI-200証明書を早く取得できます。
| Section | Objectives |
|---|---|
| Topic 1: Implement and monitor AI workloads | - Deploy AI models and services - Monitor performance and troubleshoot issues |
| Topic 2: Plan and manage Azure AI solutions | - Select appropriate Azure AI services - Monitor and optimize AI solutions - Plan security and compliance requirements |
| Topic 3: Implement Azure AI solutions | - Implement knowledge mining with Azure AI Search - Implement computer vision solutions - Implement generative AI solutions using Azure OpenAI - Implement natural language processing solutions |
お支払い後、最初にAI-200練習資料を受け取りたい場合があります。心配しないで。支払いが完了するまで、オンラインワーカーが教材の注文を迅速に処理します。支払いプロセス全体は数秒続きます。それに加えて、AI-200学習ガイドについて知りたいことを尋ねることができます。質問を送信すると、すぐに詳細な説明が表示されます。 AI-200学習教材の練習中に問題に遭遇した場合でも、問題の解決もお手伝いします。 AI-200ラーニングガイドでお客様の問題に対応いたします。
質問 # 143
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear on the review screen.
You are using Azure Monitor Application Insights to investigate a production API. You open the Logs blade and set the time range to Last 24 hours.
An engineer recommends the following query to count requests by result code and sort the results from most frequent to least frequent:
requests
| summarize request_count = count() by resultCode
| order by request_count desc
You need to determine whether the query returns the number of requests grouped by result code and sorted from most to least frequent.
Solution: The result codes are sorted alphabetically.
Does the solution meet the goal?
正解:A
解説:
Correct:
* The query returns one row per unique resultCode value with the number of requests in each group.
The Kusto Query Language (KQL) query uses the summarize operator, which acts as a grouping and aggregation mechanism.
summarize request_count = count() by resultCode
This groups all the individual rows in the requests table by their unique resultCode. It then counts the total number of logs within each group and places that value into a new column called request_count.
order by request_count desc: This sorts those aggregated rows so that the resultCode with the highest number of requests appears at the top.
Incorrect:
* The result codes are sorted alphabetically.
* The query lists every individual request along with its result code.
Reference:
https://learn.microsoft.com/en-us/azure/azure-monitor/reference/tables/apprequests
質問 # 144
Case Study 2 - Proseware Inc.
Background
Proseware Inc. develops AI-powered knowledge management solutions for enterprise customers.
The company is modernizing its platform to support semantic search, intelligent document retrieval, and real-time partner integrations.
The engineering team uses Python and Azure SDKs. The architecture is being redesigned to support containerized microservices, vector search workloads, and serverless backend processing.
Planned Application Architecture
Microservices are containerized by using Docker.
Code for containerized microservices and Azure Function apps is developed locally but stored in a GitHub repository.
Custom images for containerized microservices are stored in Azure Container Registry (ACR).
Base images are stored in Docker Hub. Custom images must be rebuilt automatically whenever their base images are updated.
Azure Cosmos DB for NoSQL stores documents, metadata, and vector embeddings.
Azure Functions generate vector embeddings of Azure Cosmos DB for NoSQL-hosted documents and send messages to Service Bus to trigger search index updates.
Azure Container Apps (ACA) apps host backend API services that provide semantic search across Azure Cosmos DB for NoSQL documents. API services process Service Bus messages and update search indexes.
Azure Kubernetes Service (AKS) processes batch vector embedding regeneration for existing Azure Cosmos DB for NoSQL documents (whenever the embedding model is changed).
An extranet-facing containerized webhook allows business partners to submit documents to be processed by internal AI workflows for semantic search and retrieval.
Monitoring
Telemetry generated by Azure resources is sent to Azure Monitor.
A Log Analytics workspace is used to collect ACA apps logs, AKS container logs, and Azure Functions apps logs.
Monitoring of Azure Functions is currently implemented by using Azure Application Insights SDK instrumentation.
Business Requirements
Embeddings for new or updated Azure Cosmos DB for NoSQL-hosted documents must be automatically generated.
Backend API services must scale automatically during business hours.
Cold start delay of backend APIs must be minimized.
Secrets must be stored outside of container images.
Developers must be able to correlate telemetry across Azure Functions hosts and apps.
All tracing must be implemented by using OpenTelemetry SDK instrumentation.
Development efforts must be minimized.
Technical Requirements
Container images must be built automatically and validated before code updates are merged into the main branch.
Image build automation must run inside the Azure Container Registry, eliminating dependency on local developer machines and external build services.
Dependency of image builds on local developer machines must be eliminated.
Event-driven scaling in ACA must occur based on the number of pending messages in the Azure Service Bus queue.
Azure Cosmos DB for NoSQL RU consumption must be minimized.
Vector similarity search must use embeddings stored in Azure Cosmos DB for NoSQL.
The partner-facing containerized webhook service must run on Azure App Service.
Secrets must NOT be stored in container images, source control, or application configuration directly. They must be accessed securely at runtime.
All secrets must be stored centrally in Azure Key Vault and accessed at runtime through a managed identity.
Azure App Service must supply secrets at runtime without relying on external services.
Resources and workloads must be deployed by using Bicep templates through an automated, version-controlled pipeline. Local and command-line deployments must be eliminated to ensure repeatable, auditable deployments.
Known Issues
RU consumption spikes during vector similarity queries.
Hotspot Question
You need to configure image build automation based on the technical requirements.
Which settings should you configure? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.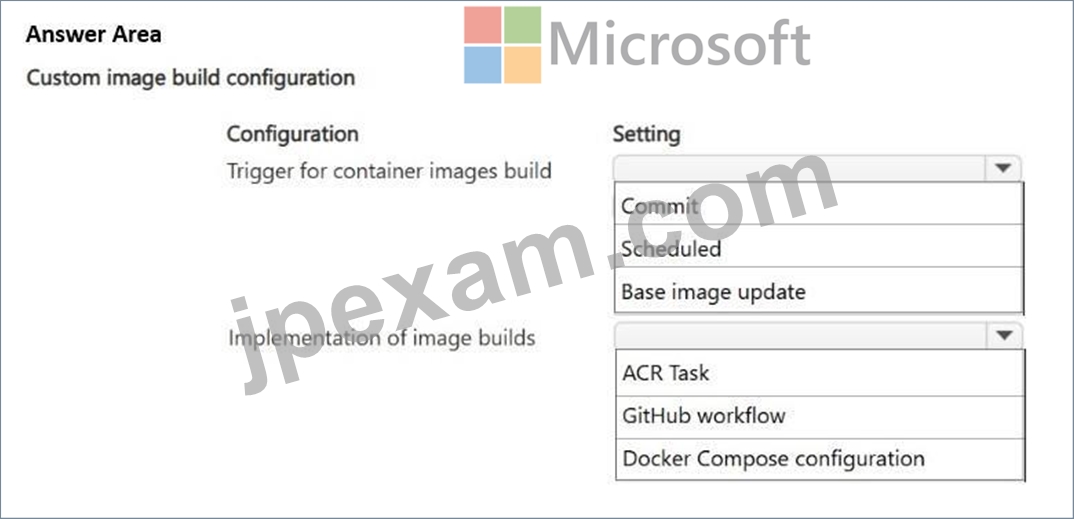
正解:
解説: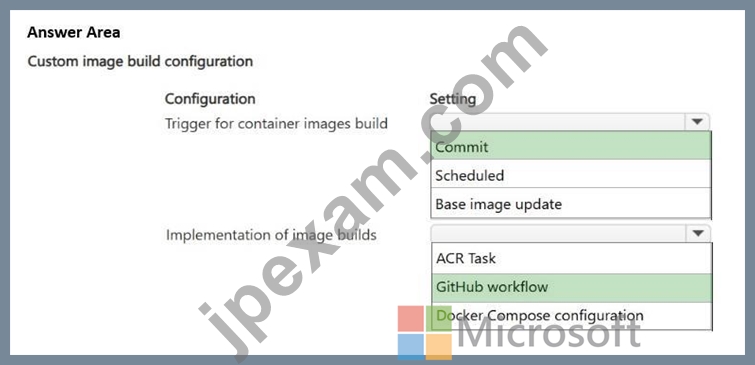
Explanation:
Scenario, Technical Requirements
Container images must be built automatically and validated before code updates are merged into the main branch.
Image build automation must run inside the Azure Container Registry, eliminating dependency on local developer machines and external build services.
Dependency of image builds on local developer machines must be eliminated.
Box 1: Commit
Use a Commit trigger for this configuration
Immediate Validation: Builds continuous integration (CI) pipelines automatically when a developer submits a pull request or pushes code.
Gatekeeper Function: Prevents unvalidated code or broken container images from merging into your main branch.
Workflow Alignment: Supports microservices development by isolating tests to the specific code updates being introduced.
Box 2: GitHub workflow
To implement automatic image builds and validation before code updates are merged into the main branch, you should use a GitHub workflow.
Branch gating: GitHub Actions can trigger specifically on pull_request events targeting the main branch, allowing you to validate code and builds before merging.
Automation control: It orchestrates the entire continuous integration (CI) pipeline, including linting, running unit tests, building Docker images, and scanning them for vulnerabilities.
Integration capacity: It can seamlessly hand off the successfully validated image to Azure Container Registry (ACR) or utilize ACR Tasks under the hood as part of the pipeline steps.
Reference:
https://docs.github.com/en/actions/tutorials/publish-packages/publish-docker-images
質問 # 145
Drag and Drop Question
You are developing a solution for a hospital to support the following use cases:
- The most recent patient status details must be retrieved even if
multiple users in different locations have updated the patient record.
- Patient health monitoring data retrieved must be the current version
or the prior version.
- After a patient is discharged and all charges have been assessed, the patient billing record contains the final charges.
You provision an Azure Cosmos DB for NoSQL database and set the default consistency level for the database account to Strong.
You set the value for Indexing Mode to Consistent.
You need to minimize latency and any impact to the availability of the solution. You must override the default consistency level at the query level to meet the required consistency guarantees for the scenarios.
Which consistency levels should you implement? To answer, drag the appropriate consistency levels to the correct requirements. Each consistency level may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.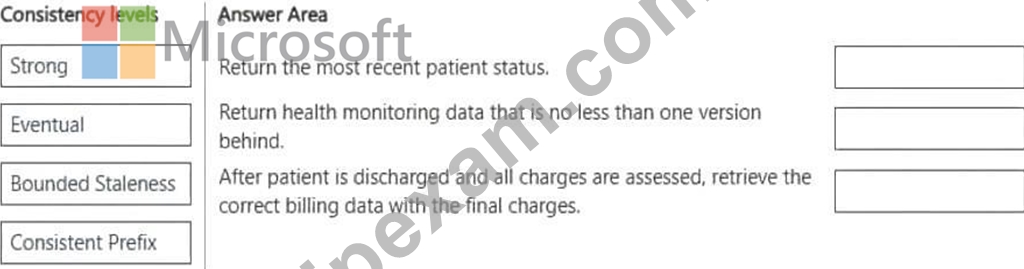
正解:
解説: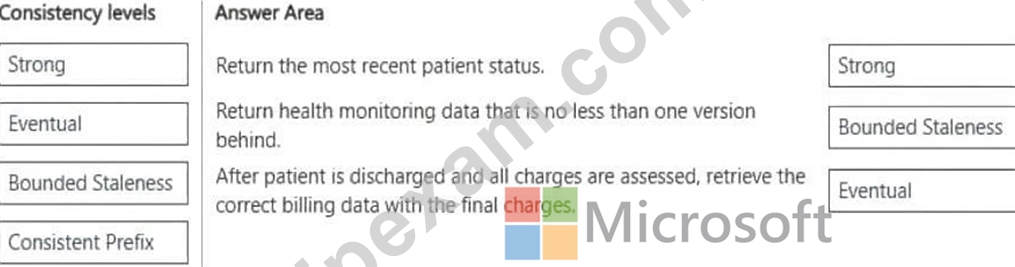
Explanation:
Box 1: Strong
Strong consistency must be used at the query level to meet this requirement.
Linearizability Guarantee: Strong consistency ensures that a read operation always returns the most recent committed version of an item.
Global Consensus: Because multiple users in different locations are updating the patient record, any reader across any region must wait for the updates to be fully committed globally before reading. This prevents any user from reading stale or out-of-order data, which is critical for patient status details.
Box 2: Bounded Staleness
To minimize latency and maximize availability while ensuring that retrieved patient health monitoring data is either the current version or the immediate prior version, you should override the consistency level at the query level to Bounded Staleness.
Version Guarantee: Bounded Staleness ensures that reads are not older than a specific time window or a configured number of versions K versions behind the latest write). Setting the version staleness to 1 (K=1 )guarantees that the data read is either the current version or the prior version.
Lower Latency: Bounded Staleness offers significantly lower latency than the account's default Strong consistency. Strong consistency requires a global majority acknowledgment before a read or write completes, increasing latency.
Higher Availability: By backing down from Strong consistency to Bounded Staleness for this query, you reduce the strict synchronization requirements, thereby minimizing impacts on availability during localized network disruptions.
Box 3: Eventual
Eventual consistency is the correct consistency level to use at the query level for this scenario.
Maximizes Performance: Eventual consistency offers the lowest latency and highest availability among all consistency levels.
Matches Scenario Needs: The billing record is final and no longer changing, so there is no risk of reading stale, in-progress updates.
Optimizes Costs: Eventual consistency queries consume half the Request Units (RUs) compared to Strong or Bounded Staleness queries.
Reference:
https://learn.microsoft.com/en-us/azure/cosmos-db/consistency-levels
質問 # 146
An application deployed to AKS depends on an internal API hosted in the same cluster. All pods are healthy and report Ready status, but requests between the services time out.
You need to determine whether the issue is related to Kubernetes service configuration or application code.
What should you do first?
正解:B
解説:
Inspect Service and Endpoints objects is the best step to start with.
The symptoms describe pods that are healthy and passing their readiness probes (meaning they are Ready), but traffic is failing to reach them and timing out. In Kubernetes, a Service routes traffic to pods by matching labels to create an Endpoints object.
Checking these objects immediately verifies if the Kubernetes network routing layer is intact.If the Endpoints object is empty or missing, the Service selector does not match the Pod labels. Traffic has nowhere to go, causing a timeout.
If the Endpoints list correctly displays the Pod IP addresses, the Kubernetes routing layer is working, shifting the blame toward the application code (e.g., misconfigured listening ports) or network policies.
Reference:
https://www.xtivia.com/blog/kubernetes-container-health-checks/
質問 # 147
Drag and Drop Question
A Python API retrieves a document from Azure Database for PostgreSQL by using a SQL statement. The API accepts the document ID from user input. The current implementation inserts the document ID directly into the SQL statement.
You need to secure the SQL statement execution by minimizing the possibility of SQL injection.
How should you modify the current implementation? To answer, move the appropriate configurations to the correct requirements. You may use each configuration once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.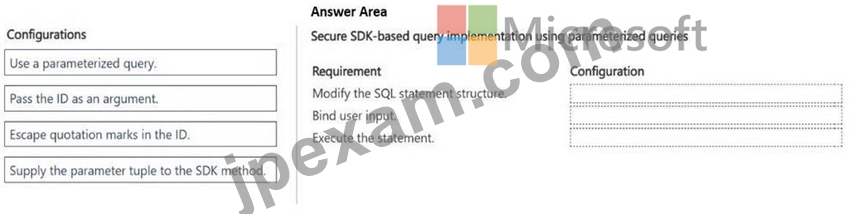
正解:
解説: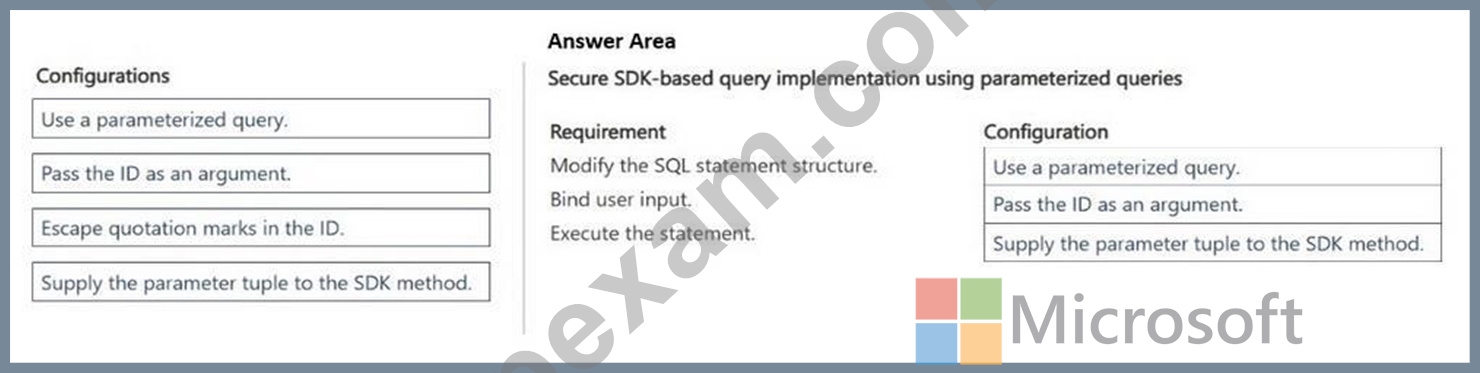
Explanation:
Box 1: Use a parameterized query
To secure your SQL statement against SQL injection, you must replace direct string insertion with parameterized queries (also known as prepared statements).
Box 2: Pass the ID as an argument
The current implementation inserts the document ID directly into the SQL statement.
Box 3: Supply the parameter tuple to the SDK method
Supply parameter tuples: Pass the user input as a separate tuple or list argument into your database driver's execution method (e.g., cursor.execute(query, (document_id,))).
Reference:
https://www.stackhawk.com/blog/finding-and-fixing-sql-injection-vulnerabilities-in-flask-python/
質問 # 148
......
JpexamのMicrosoftのAI-200試験トレーニング資料はPDF形式とソフトウェアの形式で提供します。私たちは最も新しくて、最も正確性の高いMicrosoftのAI-200試験トレーニング資料を提供します。長年の努力を通じて、JpexamのMicrosoftのAI-200認定試験の合格率が100パーセントになっていました。もし君はいささかな心配することがあるなら、あなたはうちの商品を購入する前に、Jpexamは無料でサンプルを提供することができます。
AI-200勉強ガイド: https://www.jpexam.com/AI-200_exam.html